
URL to Markdown: Website & PDF to Markdown for LLM/RAG
Pricing
from $0.75 / 1,000 page converteds
URL to Markdown: Website & PDF to Markdown for LLM/RAG
Convert web pages, sitemaps, docs sites and PDFs to clean Markdown for LLMs and RAG, in bulk. Keeps headings, code blocks and tables, adds exact token counts and ready-made RAG chunks. Automatic JavaScript rendering for dynamic sites.
Pricing
from $0.75 / 1,000 page converteds
Rating
0.0
(0)
Developer

Jason
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
Turn hundreds or thousands of web pages, PDFs, sitemaps, Google Sheets of links or whole docs sites into clean, structure-preserving Markdown in one run, ready for ChatGPT, Claude, LangChain, LlamaIndex, vector databases and RAG pipelines.
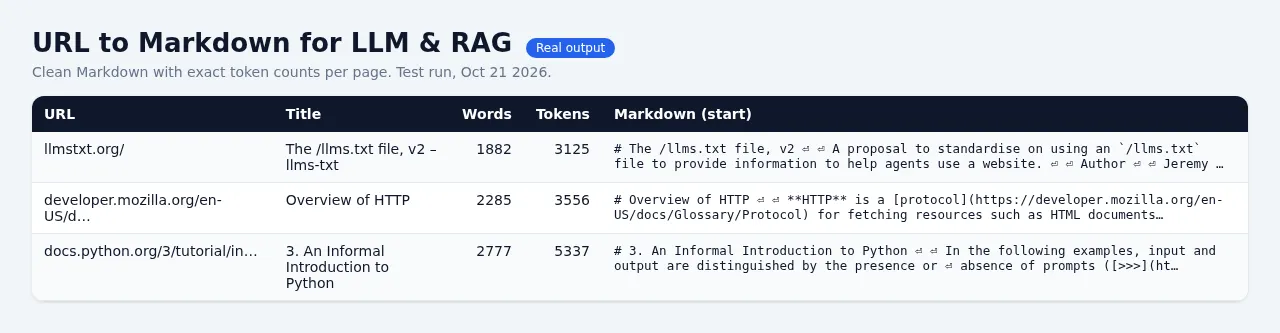
$1.10 per 1,000 pages (down to $0.75 on higher Apify plans). Failed, blocked and duplicate URLs are never charged.
- 🧹 Only the content, not the website. Menus, headers, footers, cookie banners, sidebars, "read more" cards and comment threads are removed. Headings, lists, tables, links and code are kept.
- 💻 Real code blocks. Fenced code with the language tag (
```python), indentation intact. No more code flattened into one line. - 📊 Real tables. Data tables become Markdown tables; layout tables are flattened so they don't turn into junk.
- ⚡ Fast HTTP first, browser only when needed. Pages built by JavaScript (empty app shells) are rendered automatically in a headless browser. Same price.
- 🛡️ Gets past more "403 Forbidden" pages. Refused requests are retried with a real Chrome/Safari TLS fingerprint, then in a browser, then through your proxy if you set one.
- 🔢 Exact token counts (OpenAI o200k_base tokenizer) per page and per chunk, so you can budget LLM context before you spend it.
- ✂️ RAG chunks built in. Heading-aware chunks that never exceed your token size (exact count), with overlap. Each chunk carries its heading path.
- 🕸️ Crawl a docs site or blog. Follow links 1–5 levels deep inside the same folder, host or domain, with include/exclude patterns. Or feed sitemaps.
- 📄 PDFs → text, Markdown/text files (
llms.txt,README.md) pass through unchanged. - 📥 Bring your list any way you like: paste URLs, add a sitemap, or link a TXT/CSV file or a Google Sheet.
- 📚 One combined file: every converted page also lands in
all-pages.md, ready to upload to a Custom GPT, Claude Project or NotebookLM. - 🧾 Honest errors. Every URL that failed is listed with the reason in a free
failed-urlsdataset (CSV export) and theERRORSrecord. Failures never become empty billed rows.
Head-to-head: this Actor vs the most-used Store fetcher
Same 10 real URLs, run on Oct 20, 2026 (Apify cloud, default settings for both). "Junk lines" are navigation/share/sign-in/comment-form lines left in the Markdown. "Prose kept" = how many of the competitor's real text paragraphs (150+ characters) also appear in our output.
| URL type | Competitor: tokens / junk lines | This Actor: tokens / junk lines | Prose kept | Notes |
|---|---|---|---|---|
| BBC news article | 1,776 / 14 | 1,176 / 0 | 22 of 22 | 34% fewer tokens, zero menu junk |
| Guardian long read | 5,781 / 11 | 4,295 / 2 | 30 of 30 | |
| Python docs (asyncio) | 17,266 / 45 | 13,208 / 1 | 88 of 88 | 32 code blocks fenced, language tagged where the page says it |
| Wikipedia comparison (tables) | 23,153 / 9 | 14,539 / 9 | 14 of 14 (checked by hand) | Data tables kept, nav boxes and citation markers dropped |
| JavaScript-only page (quotes.toscrape.com/js) | 30 tokens, no content | 276 tokens, all 10 quotes | n/a | Rendered automatically; competitor needs a manual wait setting |
| Blog guide with 300+ comments (CSS-Tricks) | 67,390 / 345 | 6,294 / 11 | article kept | Comment thread removed: 10x cheaper to embed |
| arXiv PDF | 18,166 | 18,211 | same | |
| GitHub repo page | 4,278 / 13 | 1,397 / 0 | README kept | Sidebar and "you signed in" banners removed |
| G2 reviews (heavy bot protection) | ✅ 12,881 | ❌ HTTP 403 | – | Needs residential proxies; not included at this price (bring your own proxy) |
| Stack Overflow (Cloudflare) | ✅ 31,592 | ❌ HTTP 403 | – | Same |
Totals: we converted 8 of 10 vs 9 of 10 (the competitor returned no content for the JavaScript page, we failed the two bot-protected sites). On the 7 pages both converted we used 57% fewer tokens (59,120 vs 137,810) for the same content, with 23 junk lines vs 437. Speed: our pages took 0.05–2.7 s each inside one batch run; the competitor took 3.8–61 s per URL, one URL per call.
Price: $1.10 per 1,000 pages vs $1.50 (27% cheaper), and a run takes thousands of URLs instead of one.
When to use the competitor instead: when your list is mostly sites with heavy bot protection (G2, Stack Overflow, Indeed...) and you don't have your own proxy.
What can I use it for?
- Feeding a chatbot or RAG app your docs, help center, blog or knowledge base (crawl it or use its sitemap).
- Building a Custom GPT / Claude Project knowledge file in one click: download
all-pages.md. - Bulk-converting research links (articles, papers, PDFs) into LLM-ready text.
- Monitoring content changes: every row has a
contentHash, so you can diff runs. - Pre-processing for summarization, translation, classification or embeddings.
How to use it
- Paste URLs into URLs, add a Sitemap URL, link a TXT/CSV/Google Sheet, or set Crawl links to follow a site's links.
- Optionally set RAG chunk size (for example 800 tokens with 100 overlap).
- Click Start, then export the dataset as JSON, CSV or Excel, download
all-pages.md, or pull it via the API, the MCP server, Make, Zapier or n8n.
Example inputs
Convert a list:
Crawl a docs section two levels deep, skipping changelogs:
Convert every URL in a Google Sheet (shared as "Anyone with the link"):
Example output (one row per page, shortened)
fetchMethod tells you how the page was fetched: http, http-impersonate (real-browser fingerprint retry), browser (JavaScript rendering) or proxy.
Other outputs of each run:
all-pages.md: every converted page in one Markdown file (key-value store).failed-urlsdataset: one row per failed URL with the reason (free, export as CSV/Excel). Its link is inOUTPUT.failedUrlsCsv.OUTPUT: counts, total tokens, fallbacks used, and the status of each URL.ERRORS: the same failures as JSON:http-error,blocked-by-site,blocked-by-robots,no-content,unsupported-type,blocked-private-network,invalid-url.
Input options
| Option | What it does | Default |
|---|---|---|
| URLs | Pages, PDFs, .md/.txt files | 3 sample pages |
| Sitemap URLs | Adds every page in the sitemap(s) | none |
| URL list file | Public TXT/CSV link or Google Sheet; any column | none |
| Max URLs | Hard cap per run (listed + sitemap + crawled pages) | 100 |
| Crawl links (depth) / scope / include / exclude | Follow links 0–5 levels; same folder, host or domain; glob or /regex/ filters | 0 (off) / same folder |
| Extraction mode | main (content only) or full (cleaned full page) | main |
| Content CSS selector / Remove elements | Override detection or strip extra blocks | none |
| Output formats | markdown, text, html | markdown |
| RAG chunk size / overlap | Heading-aware chunks in real tokens (0 = off) | off / 100 |
| Keep links / images | Keep [text](url) and  | links on, images off |
| Add list of all page links | links[] with absolute URL + anchor text | off |
| JavaScript rendering | auto (only when needed), never, always | auto |
| Retry refused pages with a real-browser fingerprint | Free 403/429 retry | on |
| Proxy for blocked pages | Apify datacenter proxy or your own proxy URLs, used only after other retries fail | off |
| Combined Markdown file / exact token counts | all-pages.md; o200k_base token counts | on / on |
| Respect robots.txt | Skip disallowed URLs | on |
| Parallel requests / per domain | Speed vs. politeness | 10 / 3 |
Pricing
Pay per page converted: $1.10 per 1,000 on the Free and Starter plans, $0.95 on Scale, $0.75 on Business and above, plus a tiny $0.00005 run start fee. JavaScript rendering, fingerprint retries, chunking, exact tokens, the combined file and crawling are all included. Failed, blocked, skipped and duplicate URLs cost nothing. Set Maximum cost per run and the Actor stops cleanly when it is reached.
Limitations
- Heavily protected sites (G2, Stack Overflow, Indeed and similar) often refuse datacenter traffic even from a real browser. They are reported as
http-error 403and not charged. Add your own residential proxy URLs under Proxy to reach them (Apify residential proxy isn't supported because its cost would exceed the page price). - robots.txt is respected by default, so some news sites (for example WSJ, Reuters) are skipped as
blocked-by-robots. Turn it off only for your own sites or with permission. - No logins or cookies. Content behind a login isn't available.
- PDF extraction reads the text layer. Scanned PDFs without text aren't OCR'd.
tokensEstimate(about 4 characters per token) is kept for older integrations;tokensis the exact count.
FAQ
Is it compatible with my existing runs? Yes. Every 1.0 input field works the same and every 1.0 output field is still there. New fields were added (tokens, fetchMethod, depth, parentUrl, modifiedDate, image, keywords).
Does JavaScript rendering cost more? No. It's the same price per page; the browser only starts when a page needs it.
How do I get one file for ChatGPT / Claude? Open the run's Storage → Key-value store → all-pages.md, or use the "All pages as one Markdown file" link on the Output tab.
Can I call it from an AI agent? Yes: through the Apify API, the Apify MCP server, or integrations like Make, Zapier and n8n.
Is it legal?
This Actor only reads publicly accessible pages, follows robots.txt by default, and doesn't collect personal data by design. Respect each website's terms and copyright when you store or republish content. If you're unsure, check with a lawyer.
Feedback
Found a page that converts badly? Open an issue with the URL, and it will be looked at quickly.


