
Eurostat Income Distribution (EU-SILC)
Pricing
from $33.50 / 1,000 income distribution records
Eurostat Income Distribution (EU-SILC)
Official Eurostat EU-SILC income distribution statistics as per-record data — national aggregates by age group and sex, verbatim from the source. No API key. Pay per record. Part of NexGen Signal — official-source data products.
Pricing
from $33.50 / 1,000 income distribution records
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
an hour ago
Last modified
Categories
Share
Official source. No API key. Pay per record.
This actor turns Eurostat's EU-SILC income distribution statistics (dataset ilc_di03) into clean, per-record data. Each run reads the figures directly from Eurostat's public JSON-stat dissemination API and delivers one record per observation — the country, the age group, the sex, the statistic, the unit, the year, and the value, verbatim from the source. These are national aggregate distribution statistics (such as mean and median income by demographic breakdown). No household- or person-level data exists in the source and none is ever constructed.
Who buys this and for what job
- Social and economic researchers comparing income distribution across EU countries and demographic groups.
- Policy and think-tank teams feeding official EU-SILC aggregates into analysis with provenance intact.
- Journalists who need the exact national figures by age group and sex behind an inequality story.
- Data engineers wanting a keyless, one-call official series for a pipeline.
The job it does: get the official income distribution (eu-silc) series as rows — reliably, with provenance, and without an account or key at the source.
Sample output
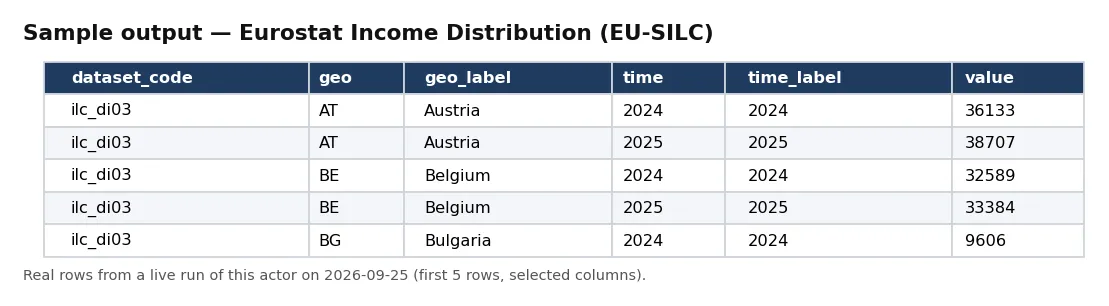
Real rows from a live run of this actor (first 5 rows, selected columns).
One full record from the same run, exactly as delivered:
Pricing
Pay per event. One event: a delivered record. Tiered by your Apify plan; the record is delivered before it is charged. No start fee, no subscription. Blocked runs and empty results cost nothing.
| Event | Free plan | Bronze | Silver | Gold / Platinum / Diamond |
|---|---|---|---|---|
income_distribution_record | $0.05 | $0.045 | $0.04 | $0.0335 |
Input
| Field | Type | Default | Description |
|---|---|---|---|
sinceTimePeriod | string | 2024 | Earliest period to return. Earlier start = more history and more records. |
maxRecords | integer | 10 | Ceiling on records delivered and billed. The default is a fast bounded sample; raise it to pull the full set. |
Both are optional; the default run is a bounded sample that finishes quickly so you can see the shape before scaling up.
Output
One JSON object per observation. Every dimension is emitted as a code and a label, both verbatim from Eurostat; a composite record_id uniquely identifies each row so no two source observations collapse together. Example record from a real run:
Every run also writes an unbilled RUN_RECEIPT to the run's key-value store: the robots check, the source URL, how many observations were present, delivered, excluded as missing or as commercial-barred geographies, and whether charged equals delivered.
Cost guidance
One income_distribution_record is billed per delivered observation, so cost = records pulled × your plan's per-record price. The full permitted set from 2024 is roughly 25,872 records — about $1,294 on the Free-plan rate, or about $867 at the Gold-tier rate. The ten-record Store example is about $0.50 (Free) or $0.34 (Gold). You control volume with sinceTimePeriod and maxRecords.
Honest limitations and caveats
- National aggregate only — by age group and sex. No individual, household, or person-level records exist in the source or are ever produced.
- Cadence: annual. Some breakdowns are suppressed or missing; those are excluded and counted, never zero-filled.
- Different statistics (mean, median) and units are distinct rows; read the fields before comparing.
- Coverage is licence-limited by design. Eurostat permits commercial reuse only for EU, EFTA, and official acceding/candidate countries; geographies outside that set are excluded at ingest and counted in the run receipt. This is a compliance choice, not a data gap.
- Missing observations are excluded, never invented; published zeros are kept as real values.
- Values, units, statuses, and dimension codes are reproduced verbatim — never rescaled, relabelled, or re-derived.
Input fields
Every input this actor accepts, read from its input schema:
| Field | Type | Default | Description |
|---|---|---|---|
sinceTimePeriod | string | "2024" | Return observations from this period onward (e.g. 2024). Earlier = more records. |
maxRecords | integer | 10 | Maximum records delivered and billed. You are billed only for records delivered. Raise to pull the full set. |
Default changed on 30 Sep 2026: if you leave maxRecords out, a run now returns up to 10 records (it was 500). Set maxRecords yourself to get more — the maximum is unchanged.
Output fields
Every field in each delivered record, read from its output schema:
| Field | Type | Meaning |
|---|---|---|
record_id | string | Composite source-native key across all dimensions. |
dataset_code | string | Eurostat dataset code. |
indicator | string | Indicator name. |
freq | string | Time frequency dimension code, verbatim. |
freq_label | string | Time frequency dimension label, verbatim. |
age | string | Age class dimension code, verbatim. |
age_label | string | Age class dimension label, verbatim. |
sex | string | Sex dimension code, verbatim. |
sex_label | string | Sex dimension label, verbatim. |
statinfo | string | Statistical information dimension code, verbatim. |
statinfo_label | string | Statistical information dimension label, verbatim. |
unit | string | Unit of measure dimension code, verbatim. |
unit_label | string | Unit of measure dimension label, verbatim. |
geo | string | Geopolitical entity (reporting) dimension code, verbatim. |
geo_label | string | Geopolitical entity (reporting) dimension label, verbatim. |
time | string | Time dimension code, verbatim. |
time_label | string | Time dimension label, verbatim. |
value | number | Observation value, verbatim (published zeros kept). |
obs_status | string | Eurostat observation status/flag when present, verbatim. |
source | string | Data source (Eurostat). |
source_dataset | string | Source dataset code. |
licence | string | Licence and reformatting notice. |
attribution | string | Required attribution string. |
caveat | string | Scope caveat (what it is and is not). |
observed_at | string | UTC retrieval timestamp. |
FAQ
How much does it cost? You pay $0.05 per income distribution record delivered to your dataset (less on higher Apify plans). Set the record limit in the input to cap what a run can cost. Records that are not delivered are never charged.
How do I get the data out? Every run saves its records to an Apify dataset. You can download it as JSON, CSV, Excel, XML or HTML from the run page, or read it through the Apify API.
Can I run it on a schedule? Yes. Use Apify Schedules to run it daily, weekly or monthly, with the same input each time.
Can I call it from my own code? Yes. Call nexgensignal/eurostat-income-distribution through the Apify API or the Apify Python and JavaScript clients, pass the same JSON input as the form, and read the dataset when the run finishes.
What happens if the source is down? The run ends with a clear status message, and nothing is charged for records that were not delivered.
The NexGen Signal family
Part of the NexGen Signal family of official-source, per-record Eurostat products. Its live siblings on the store — all official source, no API key, values verbatim, pay per record:
- Eurostat House Price Index
- Eurostat Waste Generation
- Eurostat Waste Treatment
- Eurostat Business & Consumer Confidence
Source: Eurostat. Reformatted from the Eurostat JSON-stat dissemination API; values unmodified. Third-party content and logos excluded. Data for geographies outside EU/EFTA/candidate countries is excluded in line with Eurostat's reuse terms.


