

BreezyHR Job Feed — Any Employer Board
Pricing
from $33.50 / 1,000 job records
BreezyHR Job Feed — Any Employer Board
Scrape jobs from any BreezyHR employer careers board. One structured record per public posting — title, location, type, link. No API key; pay per job.
Pricing
from $33.50 / 1,000 job records
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
🧑💻 BreezyHR Job Feed — Any Employer Board
One structured job_record per public job posting on a BreezyHR employer board. You supply a tenant (or a list of tenants); the actor pulls that employer's current public postings from {tenant}.breezy.hr/. Public, logged-out, robots-honoured.
Difference: each record carries the posting title, location, department, and employment type from the tenant's own SSR Breezy board; placeholder rows without a real title are rejected before billing.
Output is one job_record row per result; billing is pay-per-event, the value event being one job record (a $0.02 start fee per run, then $0.05 per job record).
No login, no API key and no CAPTCHA solving are involved: the source is read logged-out with an identified contact User-Agent.
📊 Sample Output
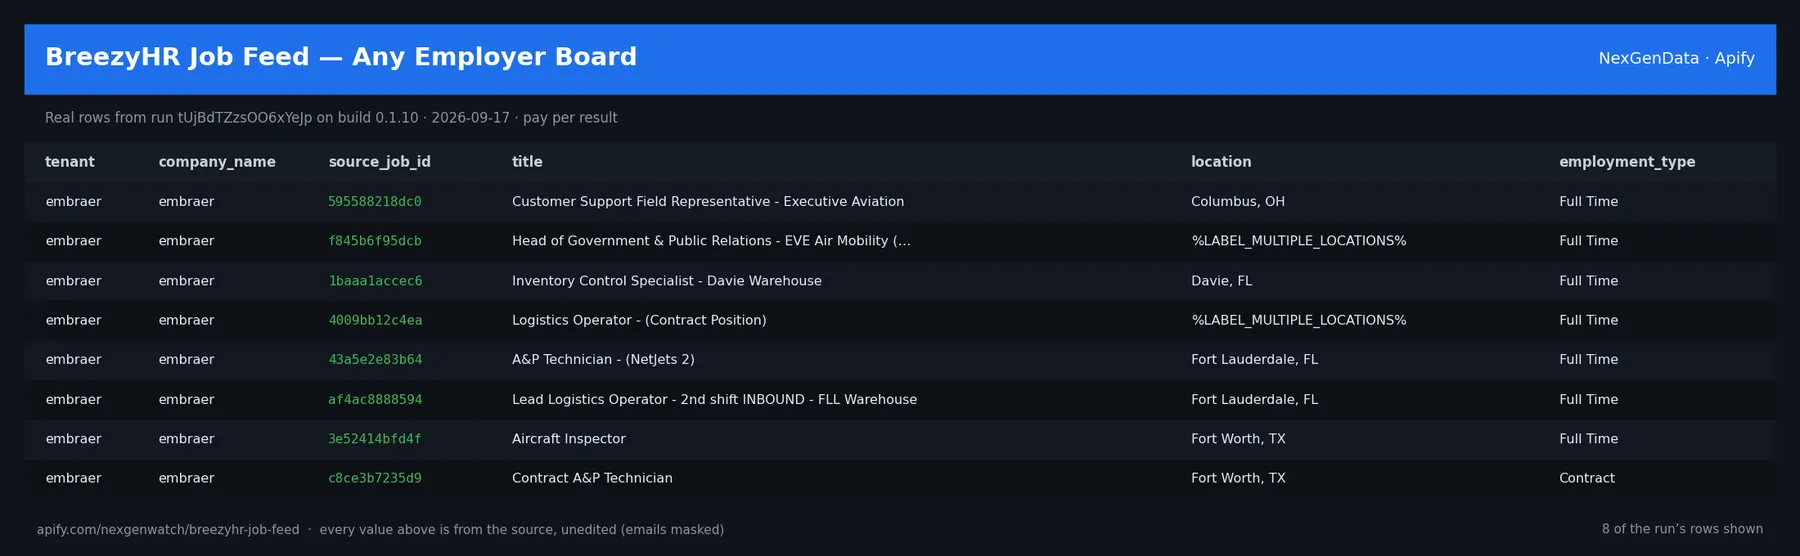
Real rows from run tUjBdTZzsOO6xYeJp on build 0.1.10 (2026-09-17), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
| tenant | company_name | source_job_id | title | location | employment_type |
|---|---|---|---|---|---|
| embraer | embraer | 595588218dc0 | Customer Support Field Representative - Executive Aviation | Columbus, OH | Full Time |
| embraer | embraer | f845b6f95dcb | Head of Government & Public Relations - EVE Air Mobility (eVTOL) | %LABEL_MULTIPLE_LOCATIONS% | Full Time |
| embraer | embraer | 1baaa1accec6 | Inventory Control Specialist - Davie Warehouse | Davie, FL | Full Time |
| embraer | embraer | 4009bb12c4ea | Logistics Operator - (Contract Position) | %LABEL_MULTIPLE_LOCATIONS% | Full Time |
| embraer | embraer | 43a5e2e83b64 | A&P Technician - (NetJets 2) | Fort Lauderdale, FL | Full Time |
| embraer | embraer | af4ac8888594 | Lead Logistics Operator - 2nd shift INBOUND - FLL Warehouse | Fort Lauderdale, FL | Full Time |
| embraer | embraer | 3e52414bfd4f | Aircraft Inspector | Fort Worth, TX | Full Time |
| embraer | embraer | c8ce3b7235d9 | Contract A&P Technician | Fort Worth, TX | Contract |
The run finished with the status message: CAPPED: delivered 20 of at least 61 unique postings (maxRecords=20). job_record billable=20 [requested_cap=20, delivered=20]
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
tenant(string/null) — e.g.embraercompany_name(string/null) — e.g.embraersource_platform(string/null) — e.g.breezysource_job_id(string/null) — e.g.595588218dc0title(string/null) — e.g.Customer Support Field Representative - Executive Aviationdepartment(string/null) — null in every sample rowlocation(string/null) — e.g.Columbus, OHcity(string/null) — null in every sample rowstate(string/null) — null in every sample rowcountry(string/null) — null in every sample rowis_remote(boolean/null) — e.g.Falseemployment_type(string/null) — e.g.Full Timeurl(string/null) — e.g.https://embraer.breezy.hr/p/595588218dc0-customer-support-field-representative-eposted_at(string/null) — null in every sample rowsource_url(string/null) — e.g.https://embraer.breezy.hr/record_type(string) — e.g.job_recordsource(string/null) — e.g.breezyhr-job-feedobserved_at(string/null) — e.g.2026-09-17T17:01:36Zterminal(string/null) — null in every sample rowplatform(string/null) — null in every sample rowtenants_requested(integer/null) — null in every sample rowtenants_ok(integer/null) — null in every sample rowtenants_blocked(integer/null) — null in every sample rowtenants_empty(integer/null) — null in every sample rowtenants_error(integer/null) — null in every sample rowraw_seen(integer/null) — null in every sample rowduplicates(integer/null) — null in every sample rowunique_found(integer/null) — null in every sample rowdelivered(integer/null) — null in every sample rowreconcile(array/null) — null in every sample rowper_tenant(array/null) — null in every sample row
What you get
One job_record per live posting, deduplicated on the source-native job id (scoped per tenant). Fields the board does not publish are honest null. A run_receipt row carries the per-tenant counts and, where the platform reports it, a delivered-vs-total reconciliation.
Every run also writes a RUN_RECEIPT record to its key-value store with the source checks it made and the counts it charged — diagnostics never land in the paid dataset.
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 20 × $0.05 job_record = $1.02 on the Free tier — every delivered row was billed.
2. A smaller, narrowed run
Caps the run at 5 rows — about $0.27 on the Free tier ($0.02 start + 5 × $0.05).
3. A full-size run
Up to 5000 rows (the schema default for maxRecords) — about $250.02 on the Free tier ($0.02 start + 5000 × $0.05) if the source has that many.
🧾 JSON sample record
One real record from run tUjBdTZzsOO6xYeJp, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent.
Terminal states. A run ends NORMAL, CAPPED (your cap was reached), PARTIAL (something was withheld and the message says what), GENUINE_EMPTY (the source was read and truly had nothing in scope) or BLOCKED (the source refused or changed shape — the run FAILS loud and bills nothing). A zero-row run is never reported as a silent success.
Charging. Each job record is charged at the moment it is pushed (job_record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
How it behaves
Each tenant board is fetched only if its robots allows. A blocked or errored board bills nothing; if every requested board is blocked the run fails loudly. Reachable boards with zero openings are an honest empty (charged nothing). maxRecords caps the count.
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
⏰ Set it on a schedule
A single run is a snapshot. The value is the feed: open the actor in Apify Console → Schedules → Create new, add this actor with the input you want, and pick a cadence:
- Daily —
0 7 * * *(07:00 UTC): catch changes within a day. - Weekly —
0 7 * * 1: a Monday digest.
Each run is independent; keep the same input on the schedule so the results stay comparable. Schedules can also POST results to a webhook (Console → Integrations).
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Job Record (job_record) | $0.05 | $0.04 | $0.04 | $0.03 |
Worked at the live Free-tier price:
- 8 job records: $0.02 start + 8 × $0.05 = $0.42
- 25 job records: $0.02 start + 25 × $0.05 = $1.27
- 5000 job records: $0.02 start + 5000 × $0.05 = $250.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
Yield on the sample run: CAPPED: delivered 20 of at least 61 unique postings (maxRecords=20). job_record billable=20 [requested_cap=20, delivered=20]. maxRecords is a hard ceiling on what is delivered and billed, never a target.
⚖️ Legal & ToS
This actor reads public data only. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How many rows can one run return?
A: Up to maxRecords (default 5000). Raise the cap for a bigger run; you pay per delivered row.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other ATS job feeds actors?
A: Same output shape and billing model; this one covers BreezyHR Job Feed — Any Employer Board. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Status says CAPPED → your cap (
maxRecords) was reached → raise it for a bigger run. - Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- ApplicantStack Job Feed — Any Employer Board — Scrape jobs from any ApplicantStack employer careers board. One structured record per public posting — title, location, link. No API key; pay per job
- BambooHR Job Feed — Any Employer Board — Scrape jobs from any BambooHR employer careers board. One structured record per public posting — title, department, location, link. No API key; pay p…
- CATS ATS Jobs Scraper — One structured jobrecord per record from the official public source, logged-out. Public, robots-honoured
- Comeet Job Feed — Any Employer Board — Scrape jobs from any Comeet employer careers board. One structured record per public posting — title, department, location, link. No API key; pay per…
- Flair Hosted Jobs — One structured jobrecord per record from the official public source, logged-out. Public, robots-honoured
- 🏢 About NexGenData — NexGen Watch is NexGenData's fleet of 256 public monitoring and lookup actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


