
Workday Jobs Scraper — Any Careers Site, Filters, Salary, Dates
Pricing
from $33.50 / 1,000 job records
Workday Jobs Scraper — Any Careers Site, Filters, Salary, Dates
Scrape every current posting from any public Workday careers site: full description, all locations, remote type, employment type, posted and closing dates, apply link and the pay range parsed from the text. Filter by title, location, keywords, remote, job family, posting age or salary first.
Pricing
from $33.50 / 1,000 job records
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
5 days ago
Last modified
Categories
Share
🧑💻 Workday Jobs Scraper — Any Workday Careers Site
Workday jobs from any Workday careers site: paste the employer's Workday careers URL and get every current posting with its full description, locations, remote type and apply link.
Scrape current job postings from any employer's public Workday career site — paste the myworkdayjobs.com or myworkdaysite.com URL — with title, full job description, every listed location, country, time type, remote type, requisition ID, posted date and apply link, plus keyword, title, location and remote filters applied before billing. Run it once and you get the current records as a dataset; put it on a schedule to keep the list current.
Export current public job postings from one or many Workday-hosted employer career sites. Paste the same Workday careers URL you would open in a browser—no tenant-code reverse engineering, login, token, or API key required.
Each delivered job_record contains the employer tenant, source requisition ID, title, location, posted date, remote indicator, and direct job URL. Records are deduplicated by Workday tenant and source requisition ID.
Narrow before you pay, and get the whole posting. filters.searchText runs Workday's own keyword search so fewer pages are read; filters.titleInclude (title contains), filters.locationInclude (any listed location or country contains — e.g. ["San Jose", "Canada"]) and filters.remoteOnly (Workday's own remote flag) are applied before a posting is counted or billed, and the run's status line says how many were read but not delivered. With includeDescriptions on (the default) each delivered posting carries its full description as plain text and HTML, every listed location, country, time type and remote type from the job page — one extra request per delivered posting, about half a second each. Turn it off for a title-and-link list.
Output is one job_record row per result; billing is pay-per-event, the value event being one job record (a $0.02 start fee per run, then $0.05 per job record).
Who buys this
- Recruiters and staffing firms tracking Workday jobs at target employers.
- Job boards and aggregators adding postings from Workday careers sites.
- Sales and labour-market analysts using Workday jobs as a hiring signal.
📊 Sample Output
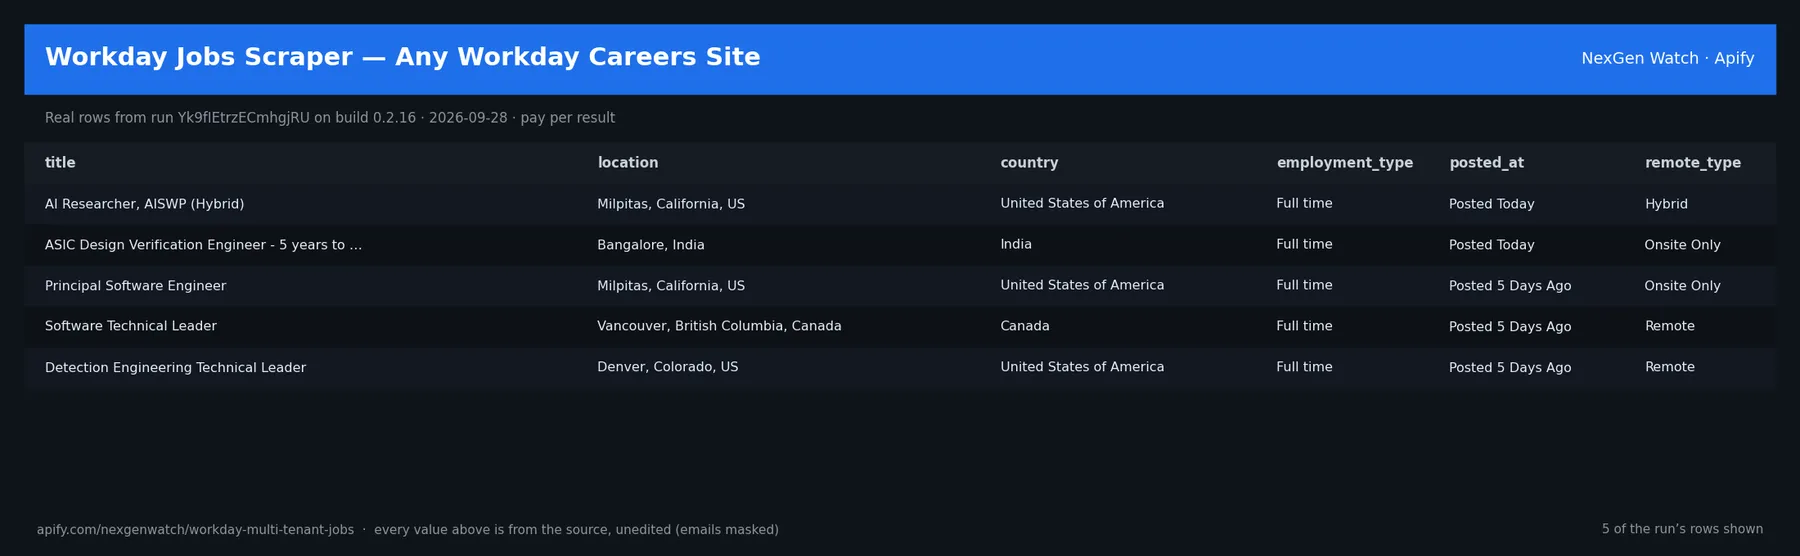
Real rows from run Yk9fIEtrzECmhgjRU on build 0.2.16 (2026-09-28), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
| title | location | country | employment_type | posted_at | remote_type |
|---|---|---|---|---|---|
| AI Researcher, AISWP (Hybrid) | Milpitas, California, US | United States of America | Full time | Posted Today | Hybrid |
| ASIC Design Verification Engineer - 5 years to 13Years - Bangalore | Bangalore, India | India | Full time | Posted Today | Onsite Only |
| Principal Software Engineer | Milpitas, California, US | United States of America | Full time | Posted 5 Days Ago | Onsite Only |
| Software Technical Leader | Vancouver, British Columbia, Canada | Canada | Full time | Posted 5 Days Ago | Remote |
| Detection Engineering Technical Leader | Denver, Colorado, US | United States of America | Full time | Posted 5 Days Ago | Remote |
The run finished with the status message: NORMAL: 5 postings across 1 tenant board(s) (0 duplicates collapsed). job_record billable=5 [requested_cap=5, delivered=5, no_filters]
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
tenant(string/null) — e.g.ciscocompany_name(string/null) — e.g.ciscosource_platform(string/null) — e.g.workdaysource_job_id(string/null) — e.g.2025643title(string/null) — e.g.AI Researcher, AISWP (Hybrid)department(string/null) — null in every sample rowlocation(string/null) — e.g.Milpitas, California, UScity(string/null) — null in every sample rowstate(string/null) — null in every sample rowcountry(string/null) — e.g.United States of Americais_remote(boolean/null) — e.g.Falseemployment_type(string/null) — e.g.Full timeurl(string/null) — e.g.https://cisco.wd5.myworkdayjobs.com/job/Milpitas-California-US/AI-Researcher--AIposted_at(string/null) — e.g.Posted Todaysource_url(string/null) — e.g.https://cisco.wd5.myworkdayjobs.com/wday/cxs/cisco/Cisco_Careers/jobsdescription_plain(string/null) — e.g.The application window is expected to close on: 10/29/2026 This is a hybrid roledescription_html(string/null) — e.g.The application window is expected to close on: 10/29/2026<p><br />This is a hybadditional_locations(array/null) — e.g.["Seattle, Washington, US"]remote_type(string/null) — e.g.Hybridposted_date(string/null) — e.g.2026-09-28detail_status(string/null) — e.g.okrecord_type(string) — e.g.job_recordsource(string/null) — e.g.workday-multi-tenant-jobsobserved_at(string/null) — e.g.2026-09-28T22:56:20Zterminal(string/null) — null in every sample rowplatform(string/null) — null in every sample rowtenants_requested(integer/null) — null in every sample rowtenants_ok(integer/null) — null in every sample rowtenants_blocked(integer/null) — null in every sample rowtenants_empty(integer/null) — null in every sample rowtenants_error(integer/null) — null in every sample rowraw_seen(integer/null) — null in every sample rowduplicates(integer/null) — null in every sample rowunique_found(integer/null) — null in every sample rowdelivered(integer/null) — null in every sample rowreconcile(array/null) — null in every sample rowper_tenant(array/null) — null in every sample row
✅ What you get
tenant(string/null) — e.g.ciscocompany_name(string/null) — e.g.ciscosource_platform(string/null) — e.g.workdaysource_job_id(string/null) — e.g.2025643title(string/null) — e.g.AI Researcher, AISWP (Hybrid)department(string/null) — null in every sample rowlocation(string/null) — e.g.Milpitas, California, UScity(string/null) — null in every sample rowstate(string/null) — null in every sample rowcountry(string/null) — e.g.United States of Americais_remote(boolean/null) — e.g.Falseemployment_type(string/null) — e.g.Full timeurl(string/null) — e.g.https://cisco.wd5.myworkdayjobs.com/job/Milpitas-California-US/AI-Researcher--AIposted_at(string/null) — e.g.Posted Todaysource_url(string/null) — e.g.https://cisco.wd5.myworkdayjobs.com/wday/cxs/cisco/Cisco_Careers/jobsdescription_plain(string/null) — e.g.The application window is expected to close on: 10/29/2026 This is a hybrid roledescription_html(string/null) — e.g.The application window is expected to close on: 10/29/2026<p><br />This is a hybadditional_locations(array/null) — e.g.["Seattle, Washington, US"]remote_type(string/null) — e.g.Hybridposted_date(string/null) — e.g.2026-09-28detail_status(string/null) — e.g.okrecord_type(string) — e.g.job_recordsource(string/null) — e.g.workday-multi-tenant-jobsobserved_at(string/null) — e.g.2026-09-28T22:53:14Zterminal(string/null) — null in every sample rowplatform(string/null) — null in every sample rowtenants_requested(integer/null) — null in every sample rowtenants_ok(integer/null) — null in every sample rowtenants_blocked(integer/null) — null in every sample rowtenants_empty(integer/null) — null in every sample rowtenants_error(integer/null) — null in every sample rowraw_seen(integer/null) — null in every sample rowduplicates(integer/null) — null in every sample rowunique_found(integer/null) — null in every sample rowdelivered(integer/null) — null in every sample rowreconcile(array/null) — null in every sample rowper_tenant(array/null) — null in every sample row
✅ What you get
tenant(string/null) — e.g.ciscocompany_name(string/null) — e.g.ciscosource_platform(string/null) — e.g.workdaysource_job_id(string/null) — e.g.2021697title(string/null) — e.g.Hardware Engineerdepartment(string/null) — null in every sample rowlocation(string/null) — e.g.San Jose, California, UScity(string/null) — null in every sample rowstate(string/null) — null in every sample rowcountry(string/null) — null in every sample rowis_remote(boolean/null) — e.g.Falseemployment_type(string/null) — null in every sample rowurl(string/null) — e.g.https://cisco.wd5.myworkdayjobs.com/job/San-Jose-California-US/Hardware-Engineerposted_at(string/null) — e.g.Posted Todaysource_url(string/null) — e.g.https://cisco.wd5.myworkdayjobs.com/wday/cxs/cisco/Cisco_Careers/jobsrecord_type(string) — e.g.job_recordsource(string/null) — e.g.workday-multi-tenant-jobsobserved_at(string/null) — e.g.2026-09-23T16:22:49Zterminal(string/null) — null in every sample rowplatform(string/null) — null in every sample rowtenants_requested(integer/null) — null in every sample rowtenants_ok(integer/null) — null in every sample rowtenants_blocked(integer/null) — null in every sample rowtenants_empty(integer/null) — null in every sample rowtenants_error(integer/null) — null in every sample rowraw_seen(integer/null) — null in every sample rowduplicates(integer/null) — null in every sample rowunique_found(integer/null) — null in every sample rowdelivered(integer/null) — null in every sample rowreconcile(array/null) — null in every sample rowper_tenant(array/null) — null in every sample row
✅ What you get
tenant(string/null) — e.g.ciscocompany_name(string/null) — e.g.ciscosource_platform(string/null) — e.g.workdaysource_job_id(string/null) — e.g.2018229title(string/null) — e.g.Principal Engineering, Hardware Project & Program Managementdepartment(string/null) — null in every sample rowlocation(string/null) — e.g.San Jose, California, UScity(string/null) — null in every sample rowstate(string/null) — null in every sample rowcountry(string/null) — null in every sample rowis_remote(boolean/null) — e.g.Falseemployment_type(string/null) — null in every sample rowurl(string/null) — e.g.https://cisco.wd5.myworkdayjobs.com/job/San-Jose-California-US/Principal-Engineeposted_at(string/null) — e.g.Posted Todaysource_url(string/null) — e.g.https://cisco.wd5.myworkdayjobs.com/wday/cxs/cisco/Cisco_Careers/jobsrecord_type(string) — e.g.job_recordsource(string/null) — e.g.workday-multi-tenant-jobsobserved_at(string/null) — e.g.2026-09-17T18:19:30Zterminal(string/null) — null in every sample rowplatform(string/null) — null in every sample rowtenants_requested(integer/null) — null in every sample rowtenants_ok(integer/null) — null in every sample rowtenants_blocked(integer/null) — null in every sample rowtenants_empty(integer/null) — null in every sample rowtenants_error(integer/null) — null in every sample rowraw_seen(integer/null) — null in every sample rowduplicates(integer/null) — null in every sample rowunique_found(integer/null) — null in every sample rowdelivered(integer/null) — null in every sample rowreconcile(array/null) — null in every sample rowper_tenant(array/null) — null in every sample row
Every run also writes a RUN_RECEIPT record to its key-value store with the source checks it made and the counts it charged — diagnostics never land in the paid dataset.
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 5 × $0.05 job_record = $0.27 on the Free tier — every delivered row was billed.
2. A full-size run
Up to 5000 rows (the schema default for maxRecords) — about $250.02 on the Free tier ($0.02 start + 5000 × $0.05) if the source has that many.
3. A filtered run
Run live on 2026-09-28 (run hzbzY6ucxtkwEBlSd): Workday's search listed 7 postings, the title filter dropped 2, 5 were delivered and billed — status line filtered_out=2 of 7 listed. filters.locationInclude and filters.remoteOnly work the same way, reading each candidate's job page before deciding.
🧾 JSON sample record
One real record from run Yk9fIEtrzECmhgjRU, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent.
Terminal states. A run ends NORMAL, CAPPED (your cap was reached), PARTIAL (something was withheld and the message says what), GENUINE_EMPTY (the source was read and truly had nothing in scope) or BLOCKED (the source refused or changed shape — the run FAILS loud and bills nothing). A zero-row run is never reported as a silent success.
Charging. Each job record is charged at the moment it is pushed (job_record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
🔧 How it works
🔧 How it works
🔧 How it works
Existing integrations
The original tenants input remains supported. Existing callers may continue sending values such as:
If both inputs are supplied, URL and legacy entries are combined and deduplicated before fetching.
Run behavior
Every run returns the employers' current public postings immediately—there is no baseline or seeding step. maxRecords is a run-wide delivery and billing cap, not a guaranteed result count.
Inputs are validated before any board request. Non-HTTPS URLs, non-Workday hosts, vanity domains that do not expose the Workday identifiers, custom ports, credentials, and malformed paths fail closed rather than guessing a tenant or endpoint.
Each resolved board's public Workday CXS endpoint is fetched only when its robots policy allows it. A blocked or errored board contributes no records and no job_record charges. If every requested board is blocked or errors, the run fails loudly instead of presenting the outage as an empty result. A reachable board with genuinely no current postings returns zero job records.
Scope
This Actor covers public myworkdayjobs.com and myworkdaysite.com career boards. It does not log in, bypass access controls, crawl employer vanity domains, open each description page, or infer fields that Workday does not provide in the public job-list response.
Who it is for
- Recruiters and sourcers monitoring openings across target employers
- Job boards and aggregators ingesting public Workday postings
- Talent-market analysts comparing hiring activity across companies
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Job Record (job_record) | $0.05 | $0.045 | $0.04 | $0.0335 |
Worked at the live Free-tier price:
- 5 job records: $0.02 start + 5 × $0.05 = $0.27
- 25 job records: $0.02 start + 25 × $0.05 = $1.27
- 5000 job records: $0.02 start + 5000 × $0.05 = $250.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
Yield on the sample run: NORMAL: 5 postings across 1 tenant board(s) (0 duplicates collapsed). job_record billable=5 [requested_cap=5, delivered=5, no_filters]. maxRecords is a hard ceiling on what is delivered and billed, never a target.
⚖️ Legal & ToS
This actor reads public data only. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How many rows can one run return?
A: Up to maxRecords (default 5000). Raise the cap for a bigger run; you pay per delivered row.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other ATS job board scrapers actors?
A: Same output shape and billing model; this one covers Workday Jobs Scraper — Any Employer Career Site. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Status says CAPPED → your cap (
maxRecords) was reached → raise it for a bigger run. - Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- Greenhouse, Lever & Ashby Jobs Scraper - 6 ATS — Scrape current job postings from any employer's Greenhouse, Lever, Ashby, Recruitee, SmartRecruiters or Personio careers board — just paste the board…
- Recruiterflow Careers Jobs Exporter — One structured job record per opening from employer career boards hosted by Recruiterflow — title, company, location, apply link. Keyless, logged-out…
- Teamtailor Jobs Scraper - Any Employer Board — Scrape job postings from any Teamtailor careers board: title, location, department, posting date and apply link. One record per result. Pay per resul…
- ApplicantStack Jobs Scraper - Any Employer Board — Scrape job postings from any ApplicantStack careers board: title, location, department, posting date and apply link. One record per result. Pay per r…
- 🏢 About NexGen Watch — NexGen Watch is a catalog of more than 300 public data actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


