
Flair Hosted Jobs Scraper
Pricing
from $33.50 / 1,000 job records
Flair Hosted Jobs Scraper
One structured jobrecord per record from the official public source, logged-out. Public, robots-honoured.
Pricing
from $33.50 / 1,000 job records
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Security
Limited permissionsShare
🧑💻 Flair Hosted Jobs Scraper
Get every open job from company career sites hosted on Flair (<company>.careers.flair.hr) as clean rows: title, location, department, employment type, seniority and salary when the employer publishes it. Give it one board or many. Each job appears once, closed roles are left out, and a board that is down is skipped and named in the run summary while the others still deliver. Built by NexGen Watch on Apify.
Pay per job: a $0.02 start fee per run, then $0.05 per job record on the Free tier. Public career pages only, read logged-out with no login, API key or CAPTCHA solving.
Who buys this
Buyers usually search for Flair jobs or Flair HR careers.
- Recruiters and staffing agencies pulling Flair jobs at target employers.
- Job boards and aggregators adding Flair HR careers as clean, deduplicated rows.
- Sales and labour-market analysts using new postings as a hiring signal.
📊 Sample Output
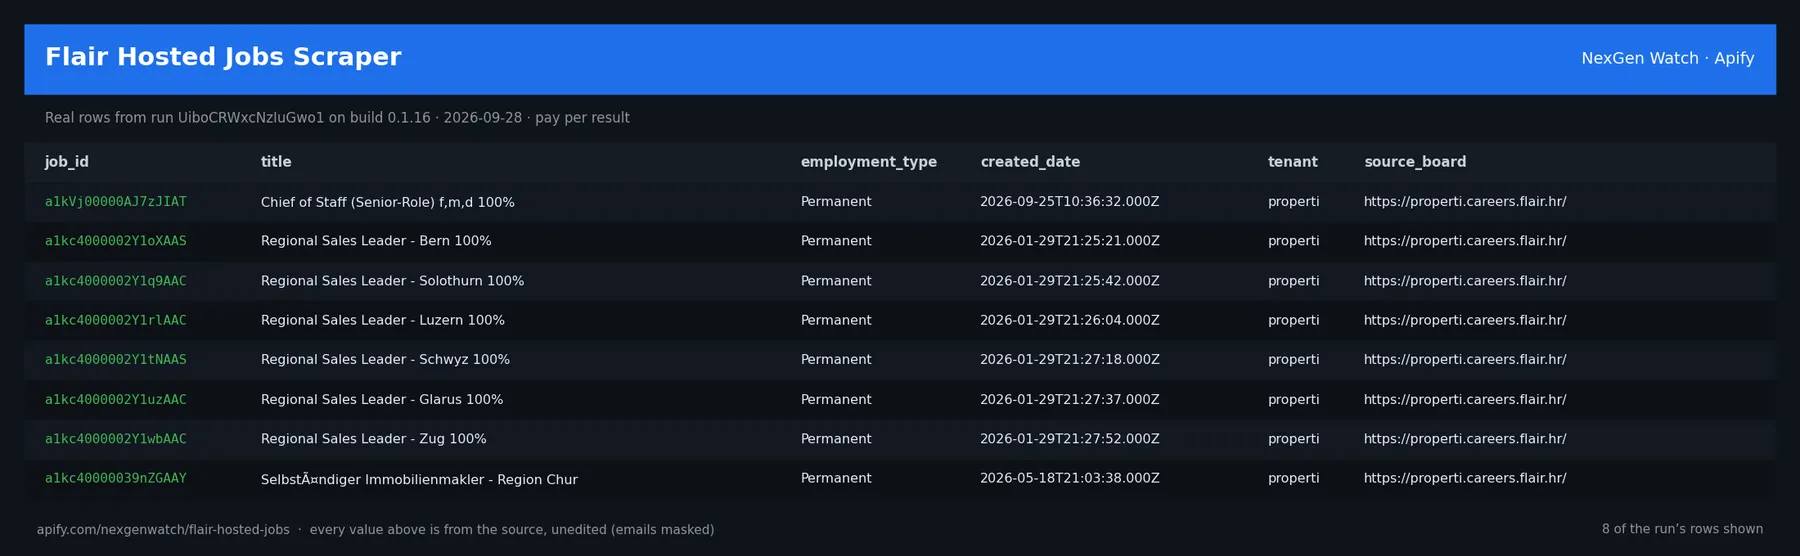
Real rows from run 1Rsw8eegAWhZsk3H6 on build 0.1.38 (2026-10-29) — the Quick start input below (the searenergy board), first 8 of 10. Salary is the range the employer published, when it published one:
| title | department | location | type | seniority | salary | posted |
|---|---|---|---|---|---|---|
| Bachelorand / Masterand (m/w/d) Projektmanagement | Execution | Hamburg, Germany | Internship/Working Stude… | Student / Trainee | EUR 700–800 per month | 2026-08-24 |
| Technischer Projektmanager (m/w/d) Instandhaltung | Execution | Hamburg, Germany | Temporary | Professional / Exp… | EUR 50,000–65,000 per year | 2026-08-27 |
| Werkstudent (m/w/d) Business Central Support | Corporate Services | Hamburg, Germany | Internship/Working Stude… | Student / Trainee | EUR 950–1,500 per month | 2026-09-07 |
| Commissioning / Site Manager (m/f/d) Offshore Substation | Freelancer | Netherlands | Contract | Professional / Exp… | EUR 17,300–18,700 per month | 2026-09-23 |
| Offshore Logistics Manager (m/f/d) | Freelancer | Łeba, Pomeranian Voivo… | Contract | Professional / Exp… | EUR 1–10,500 per month | 2026-09-29 |
| HV Electrical Inspector (m/f/d) | Freelancer | Puerto Real, Spain | Contract | Professional / Exp… | EUR 1–10,500 per month | 2026-10-01 |
| Onshore Logistics Manager (m/f/d) | Freelancer | Łeba, Pomeranian Voivo… | Contract | Professional / Exp… | EUR 1–10,500 per month | 2026-10-01 |
| Automation & Telecom Construction & Commissioning Engineer (m/… | Freelancer | Łeba, Pomeranian Voivo… | Contract | Professional / Exp… | EUR 1–10,500 per month | 2026-10-02 |
The run finished with the status message: NORMAL: 10 unique rows (0 duplicates collapsed). billable=10 (the image above is from an earlier run on another board).
✅ What you get
One flair_job row per open position (billed), plus one free run_receipt row per run.
Job rows (record_type: flair_job)
record_type(string) — e.g.flair_jobjob_id(string/null) — e.g.a2dbO000000sbKLQAYtitle(string/null) — e.g.Bachelorand / Masterand (m/w/d) Projektmanagementdepartment(string/null) — e.g.Executionemployment_type(string/null) — e.g.Internship/Working Studenttime_commitment(string/null) — e.g.Part timelocation(string/null) — e.g.Hamburg, Germanyindustry(string/null) — e.g.Engineeringseniority(string/null) — e.g.Student / Traineecategory(string/null) — e.g.Renewable Energy Project Managementcreated_date(string/null) — e.g.2026-08-24T10:51:10.000Zlanguage(string/null) — e.g.desalary(string/null) — e.g.EUR 700–800 per monthtenant(string/null) — e.g.searenergysource_board(string/null) — e.g.https://searenergy.careers.flair.hr/job_url(string/null) — e.g.https://searenergy.careers.flair.hr/position/a2dbO000000sbKLQAYsource(string/null) — e.g.flair-hosted-jobssource_url(string/null) — e.g.https://flair.careers.flair.hr/observed_at(string/null) — e.g.2026-10-29T04:57:52Zlicense(string/integer/null) — null when the board does not publish itattribution(string/integer/null) — null when the board does not publish it
The run receipt (record_type: run_receipt, not billed)
Counts for the run, and in scope the result per board — how many jobs each gave, or why it was skipped.
release_date(string/null)terminal(string/integer/null)reported_total(string/integer/null)raw_seen(string/integer/null)duplicates(string/integer/null)unique_found(string/integer/null)delivered(string/integer/null)scope(string/integer/null)note(string/integer/null)
⚙️ Sample inputs
Input fields
boards(optional, default Comma-separated Flair career-site names — the part before.careers.flair.hr(e.g.searenergy). Empty = the built-in sample of boards. A board that is down is skipped and named in the receipt.) —maxRecords(optional, default Most job rows delivered (and billed) in this run.) —searchText(optional, default Keep only rows where any field contains this text (case-insensitive), applied beforemaxRecords.) —fieldMatch(optional, default Keep rows whose named column contains a text, e.g.{"location": "Berlin"}; several columns must all match.) —userAgent(optional, default Override the identified User-Agent.) —
Examples
1. Quick start — one board (the Store example; the Sample Output above came from this)
Charged $0.02 start + 10 × $0.05 = $0.52 on the Free tier.
2. Several boards in one run
Run OHmjyy8bCa5VDAgc8 returned 40 jobs (searenergy 26, flair 10, bisedge 4); properti's own career site was down that day, so it was skipped and named in the receipt while the other boards delivered. $0.02 + 40 × $0.05 = $2.02.
3. Only the roles in one city, across boards
Run 3Sd2w58y5D11zlXM7 kept the 17 Hamburg roles out of 54 open across the four boards; only kept rows are billed: $0.02 + 17 × $0.05 = $0.87.
🧾 JSON sample record
The first row of the Quick start run:
🔧 How it works
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent. Pacing: CRAWL_DELAY=0.0.
Charging. Each job record is charged at the moment it is pushed (job_record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
How it behaves
Each comma-separated board is fetched (robots.txt allows all) and its open-positions list read from the page; if a page carries no list, the same list is read from that board's own career-site API. Only open positions are emitted, and salary is the employer's published range (min–max, currency, period) or null. A board that fails both ways is skipped and named in the run receipt; the run fails loud only when no board delivers anything. Deduped per board, bounded to maxRecords.
Source
https://{tenant}.careers.flair.hr/
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Job Record (job_record) | $0.05 | $0.045 | $0.04 | $0.0335 |
Worked at the live Free-tier price:
- 8 job records: $0.02 start + 8 × $0.05 = $0.42
- 25 job records: $0.02 start + 25 × $0.05 = $1.27
- 5000 job records: $0.02 start + 5000 × $0.05 = $250.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
Yield on the sample run: NORMAL: 10 unique rows (0 duplicates collapsed). billable=10. maxRecords is a hard ceiling on what is delivered and billed, never a target.
⚖️ Legal & ToS
This actor reads public data only. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How many rows can one run return?
A: Up to maxRecords (default 5000). Raise the cap for a bigger run; you pay per delivered row.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. To refresh it, save your input as a task and add a schedule in Apify Console (Schedules → Create new); each run returns the roles open at that moment.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other ATS job board scrapers actors?
A: Same output shape and billing model; this one covers Flair Hosted Jobs Scraper. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source (CRAWL_DELAY=0.0) and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Status says CAPPED → your cap (
maxRecords) was reached → raise it for a bigger run. - Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- BreezyHR Jobs Scraper - Any Employer Board — Scrape job postings from any BreezyHR careers board: title, location, department, posting date and apply link. One record per result. Pay per result
- CATS ATS Jobs Scraper — One structured jobrecord per record from the official public source, logged-out. Public, robots-honoured
- Comeet Jobs Scraper - Any Employer Board — Scrape job postings from any Comeet careers board: title, location, department, posting date and apply link. One record per result. Pay per result
- HireBridge Jobs Scraper — One structured jobrecord per LIVE job posting from a public, logged-out ATS board. Public, robots-honoured
- JazzHR Jobs Scraper - Any Employer Board — Scrape job postings from any JazzHR careers board: title, location, department, posting date and apply link. One record per result. Pay per result
- Jobvite Jobs Scraper - Any Employer Board — Scrape job postings from any Jobvite careers board: title, location, department, posting date and apply link. One record per result. Pay per result
- 🏢 About NexGen Watch — NexGen Watch is a catalog of more than 300 public data actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


