
GOV.UK Press Releases Scraper
Pricing
from $33.50 / 1,000 press-release records
GOV.UK Press Releases Scraper
Scrape GOV.UK press releases and announcements: department, title, summary, date and link from the official search API. One record per result. Pay per result.
Pricing
from $33.50 / 1,000 press-release records
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Security
Limited permissionsShare
📣 GOV.UK Press Releases Scraper
Scrape GOV.UK press releases and announcements: department, title, summary, date and link from the official search API. Run it once and you get the current records as a dataset; put it on a schedule to keep the list current. Built by NexGen Watch on Apify.
Output is one press_release row per result; billing is pay-per-event, the value event being one press-release record (a $0.02 start fee per run, then $0.05 per press-release record). Source: www.gov.uk.
No login, no API key and no CAPTCHA solving are involved: the source is read logged-out with an identified contact User-Agent.
Who buys this
Buyers usually search for GOV.UK news or GOV.UK press releases.
- B2B sales and account teams using GOV.UK news as a trigger signal.
- PR, comms and market-intelligence teams monitoring GOV.UK press releases.
- Investors and analysts tracking company events as they are announced.
📊 Sample Output
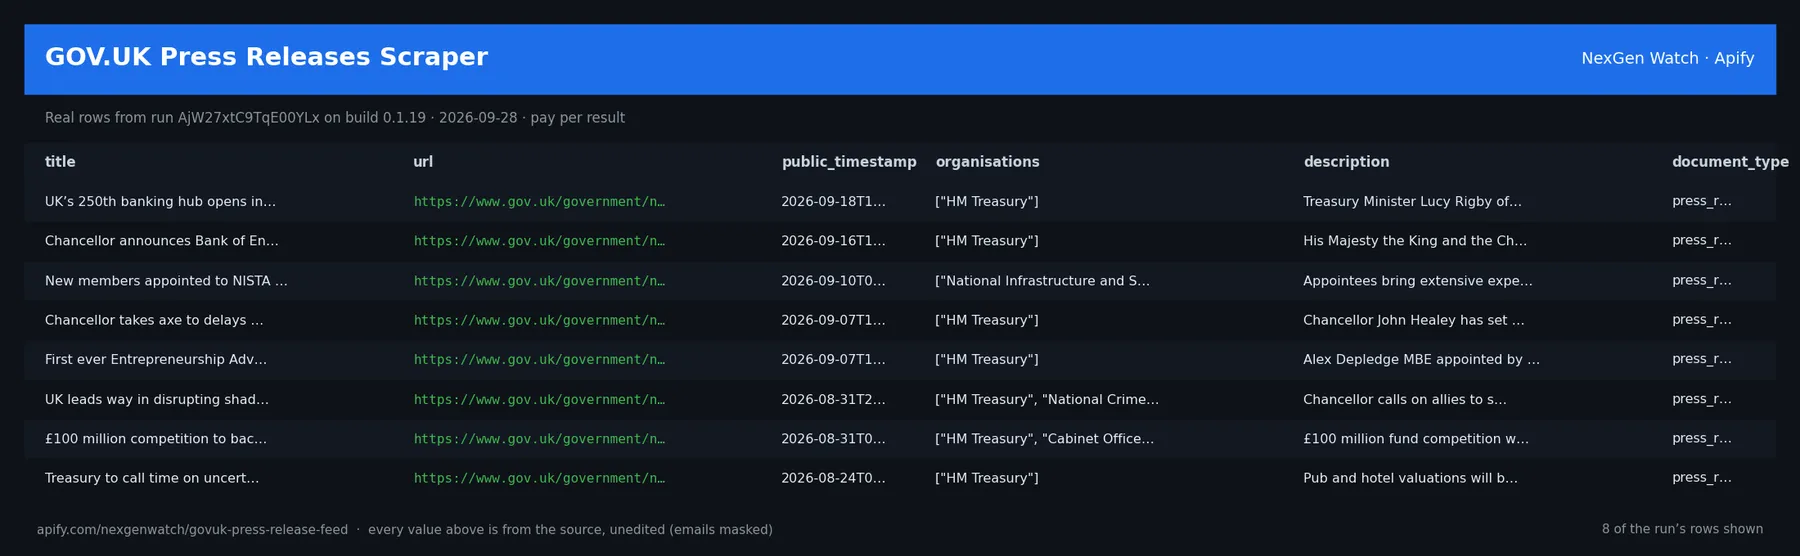
Real rows from run AjW27xtC9TqE00YLx on build 0.1.19 (2026-09-28), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
| title | url | public_timestamp | organisations | description | document_type |
|---|---|---|---|---|---|
| UK’s 250th banking hub opens in Chepstow, keeping access to cash and f | https://www.gov.uk/government/news/uks-250th-banking-hub-opens-in-chep | 2026-09-18T13:53:43Z | ["HM Treasury"] | Treasury Minister Lucy Rigby officially opens the UK's 250th banking h | press_release |
| Chancellor announces Bank of England appointments | https://www.gov.uk/government/news/chancellor-announces-bank-of-englan | 2026-09-16T14:19:00Z | ["HM Treasury"] | His Majesty the King and the Chancellor have appointed three new non-e | press_release |
| New members appointed to NISTA Expert Advisory Council | https://www.gov.uk/government/news/new-members-appointed-to-nista-expe | 2026-09-10T09:00:05Z | ["National Infrastructure and Service Transformation Authority", "HM T | Appointees bring extensive experience in infrastructure delivery, fina | press_release |
| Chancellor takes axe to delays holding back growth | https://www.gov.uk/government/news/chancellor-takes-axe-to-delays-hold | 2026-09-07T13:31:00Z | ["HM Treasury"] | Chancellor John Healey has set out his plan to drive growth in every p | press_release |
| First ever Entrepreneurship Advisor appointed to the Treasury | https://www.gov.uk/government/news/first-ever-entrepreneurship-advisor | 2026-09-07T11:42:27Z | ["HM Treasury"] | Alex Depledge MBE appointed by the Chancellor as first ever Entreprene | press_release |
| UK leads way in disrupting shadowy Russian sanctions evasion network | https://www.gov.uk/government/news/uk-leads-way-in-disrupting-shadowy- | 2026-08-31T21:58:43Z | ["HM Treasury", "National Crime Agency"] | Chancellor calls on allies to step up their pressure on Russia and set | press_release |
| £100 million competition to back British AI companies to fix public se | https://www.gov.uk/government/news/100-million-competition-to-back-bri | 2026-08-31T09:25:15Z | ["HM Treasury", "Cabinet Office"] | £100 million fund competition will help promising British AI start-ups | press_release |
| Treasury to call time on uncertainty for pubs and hotels | https://www.gov.uk/government/news/treasury-to-call-time-on-uncertaint | 2026-08-24T09:02:00Z | ["HM Treasury"] | Pub and hotel valuations will be made fairer as the government takes a | press_release |
The run finished with the status message: NORMAL: 10 press releases delivered (source reports 1020 total matches) | release-record billable=10 | release-record charged=10
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
record_type(string) — e.g.press_releasetitle(string/null) — e.g.UK’s 250th banking hub opens in Chepstow, keeping access to cash and face-to-facurl(string/null) — e.g.https://www.gov.uk/government/news/uks-250th-banking-hub-opens-in-chepstow-keepipublic_timestamp(string/null) — e.g.2026-09-18T13:53:43Zorganisations(array/null) — e.g.["HM Treasury"]description(string/null) — e.g.Treasury Minister Lucy Rigby officially opens the UK's 250th banking hub in Chepdocument_type(string/null) — e.g.press_releasesource(string/null) — e.g.https://www.gov.uk/api/search.jsonquery— e.g.{"organisations": ["hm-treasury"], "keywords": null, "count": 10}
✅ What you get
✅ What you get
✅ What you get
record_type(string) — e.g.press_releasetitle(string/null) — e.g.Chancellor announces Bank of England appointmentsurl(string/null) — e.g.https://www.gov.uk/government/news/chancellor-announces-bank-of-england-appointmpublic_timestamp(string/null) — e.g.2026-09-16T14:19:00Zorganisations(array/null) — e.g.["HM Treasury"]description(string/null) — e.g.His Majesty the King and the Chancellor have appointed three new non-executive ddocument_type(string/null) — e.g.press_releasesource(string/null) — e.g.https://www.gov.uk/api/search.jsonquery— e.g.{"organisations": ["hm-treasury"], "keywords": null, "count": 10}
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 10 × $0.05 release-record = $0.52 on the Free tier — every delivered row was billed.
This actor takes no size cap or filter beyond the input above, so the Store example is the one input to run; put it on a schedule to keep the data current.
🧾 JSON sample record
One real record from run AjW27xtC9TqE00YLx, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Source. The actor reads www.gov.uk — endpoints: https://www.gov.uk, https://www.gov.uk/api/search.json. Public pages and feeds only; nothing behind a login.
Transport. Plain HTTPS from the Apify platform, no proxy. Every request carries an identified contact User-Agent.
Terminal states. A run ends NORMAL, CAPPED (your cap was reached), PARTIAL (something was withheld and the message says what), GENUINE_EMPTY (the source was read and truly had nothing in scope) or BLOCKED (the source refused or changed shape — the run FAILS loud and bills nothing). A zero-row run is never reported as a silent success.
Charging. Each press-release record is charged at the moment it is pushed (release-record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
🔧 How it works
🔧 How it works
🔧 How it works
Source
The official GOV.UK search API, queried anonymously (no key), with a contact User-Agent.
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
⏰ Optional: run it on a schedule
A single run returns the current records. If you also want to be told what changed over time, open the actor in Apify Console → Schedules → Create new, add this actor with the input you want, and pick a cadence:
- Daily —
0 7 * * *(07:00 UTC): catch changes within a day. - Weekly —
0 7 * * 1: a Monday digest.
Each run is independent; keep the same input on the schedule so the results stay comparable. Schedules can also POST results to a webhook (Console → Integrations).
⏰ Optional: run it on a schedule
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Press-release record (release-record) | $0.05 | $0.045 | $0.04 | $0.0335 |
Worked at the live Free-tier price:
- 8 press-release records: $0.02 start + 8 × $0.05 = $0.42
- 25 press-release records: $0.02 start + 25 × $0.05 = $1.27
- 100 press-release records: $0.02 start + 100 × $0.05 = $5.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
Yield on the sample run: NORMAL: 10 press releases delivered (source reports 1020 total matches) | release-record billable=10 | release-record charged=10.
⚖️ Legal & ToS
This actor reads public, logged-out pages and feeds published by www.gov.uk. It collects only what the source publishes to any visitor, identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. The source (www.gov.uk) is read logged-out; the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other market announcement scrapers actors?
A: Same output shape and billing model; this one covers www.gov.uk. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Fewer rows than expected → the source had fewer items in scope → widen the input.
- Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- ASX Company Announcements Scraper — Scrape ASX company announcements for the tickers you name: headline, type, price-sensitive flag, date and a direct link to the announcement PDF (the…
- Bilibili Trending Videos Scraper — Scrape Bilibili trending and ranking lists: video, uploader, views, rank and rank movement. Every run returns the current records as a dataset. Optio…
- Korea DART Corporate Filings Scraper — Scrape Korean corporate filings from DART: company, report type, filing date and link. Every run returns the current records as a dataset. Optional w…
- Company Newsroom Press Releases Scraper — Scrape the press releases a company's own newsroom or investor-relations feed currently lists: publisher, headline, summary, date and link, from as m…
- SGX Financial Reports and Disclosures Scraper — Scrape SGX company financial reports and disclosure documents: company, document type, date and PDF link. Every run returns the current records as a…
- 🏢 About NexGen Watch — NexGen Watch is a catalog of more than 300 public data actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


