

Sitemap Indexability Auditor
Pricing
from $33.50 / 1,000 indexability checks
Sitemap Indexability Auditor
Audit whether the URLs in your sitemaps (or a plain URL list) are actually indexable — sitemaps are expanded (bounded nested depth + a hard URL cap) and every page URL gets one evidenced indexability verdict.
Pricing
from $33.50 / 1,000 indexability checks
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
🌐 Sitemap Indexability Auditor
Audits whether the URLs in your sitemaps (or a plain URL list) are actually indexable. Sitemaps are expanded — bounded by nested-sitemap depth and a hard URL cap — and every page URL gets one evidenced verdict.
Output is one indexability_verdict row per result; billing is pay-per-event, the value event being one indexability check (a $0.02 start fee per run, then $0.05 per indexability check).
No login, no API key and no CAPTCHA solving are involved: the source is read logged-out with an identified contact User-Agent.
📊 Sample Output
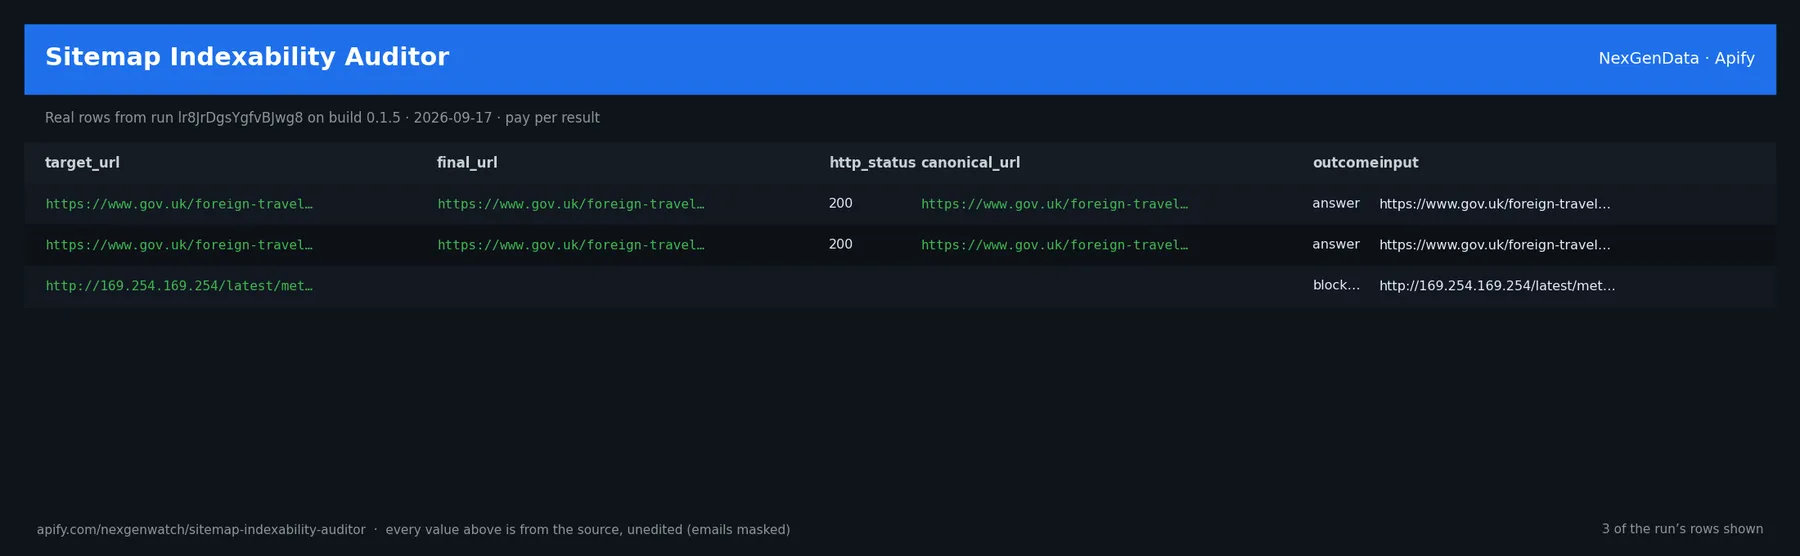
Real rows from run lr8JrDgsYgfvBJwg8 on build 0.1.5 (2026-09-17), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
The run finished with the status message: PARTIAL: 2 billable verdict(s), 1 blocked (unbilled status), 0 unreachable, 0 unparseable of 3 target(s) | indexability_check billable=2 | indexability_check charged=2
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
target_url(string/null) — e.g.https://www.gov.uk/foreign-travel-advice/francefinal_url(string/null) — e.g.https://www.gov.uk/foreign-travel-advice/francehttp_status(integer/string/null) — e.g.200robots_permission(string/null) — e.g.allowedmeta_robots(string/null) — null in every sample rowx_robots_tag(string/null) — null in every sample rowindexable(boolean/null) — e.g.Truecanonical_url(string/null) — e.g.https://www.gov.uk/foreign-travel-advice/francecanonical_conflict(boolean/null) — e.g.Falselastmod(string/null) — null in every sample rowlastmod_plausible(boolean/null) — null in every sample rowfrom_sitemap(string/null) — null in every sample rowfaults(string/null) — null in every sample rowrecord_type(string) — e.g.indexability_verdictsource(string/null) — e.g.buyer-submitted sitemaps + page URLsoutcome(string/null) — e.g.answerinput(string/null) — e.g.https://www.gov.uk/foreign-travel-advice/franceoutcome_reason(string/null) — e.g.robots.txt for http://169.254.169.254 unavailable/forbidden — cannot confirm perobserved_at(string/null) — null in every sample rowterminal(string/null) — null in every sample row
Output
One row per target. A complete evidenced verdict carries outcome: answer; blocked / unreachable / unparseable targets carry that status and are not billed.
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 2 × $0.05 indexability_check = $0.12 on the Free tier — every delivered row was billed.
2. A smaller, narrowed run
A bounded run for checking the field shape before scheduling. userAgent narrows what the source is asked for.
3. A full-size run
The same input run on a schedule; each run is billed only for what it delivers.
🧾 JSON sample record
One real record from run lr8JrDgsYgfvBJwg8, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent.
Terminal states. A run ends NORMAL, CAPPED (your cap was reached), PARTIAL (something was withheld and the message says what), GENUINE_EMPTY (the source was read and truly had nothing in scope) or BLOCKED (the source refused or changed shape — the run FAILS loud and bills nothing). A zero-row run is never reported as a silent success.
Charging. Each indexability check is charged at the moment it is pushed (indexability_check); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
What you submit
urls — sitemap urls or page urls. Sitemap URL(s) and/or page URLs. Sitemaps are expanded (bounded nested depth + capped child count) into their page URLs; each page URL gets one indexability verdict: HTTP state, robots permission, page robots directives (meta robots + X-Robots-Tag), canonical target + conflicts, and lastmod plausibility. A complete verdict bills; a target blocked by robots/SSRF/403/429/5xx or unreachable is delivered as an unbilled status.
The runtime source gate (per submitted target)
Because you choose the targets, the source contract is enforced at run time, per origin, before any page is read:
- robots.txt is fetched once per origin and honored for our crawler. No robots / 404 = permitted; a disallowed path or an unavailable robots file = BLOCKED.
- SSRF guard — every host is resolved and must be a public address. Private, loopback, link-local, reserved and cloud-metadata addresses are refused before a socket opens.
- HTTP — bounded body reads;
403/429/5xx= BLOCKED; DNS / timeout / connection faults = UNREACHABLE.
A BLOCKED or UNREACHABLE target is delivered as an unbilled status row — never a broken-site verdict, and never charged.
Why this and not a generic crawler
45-user sitemap/SEO comparators exist; this differs — a per-URL indexability VERDICT (robots+meta+canonical+lastmod evidenced), not a crawl dump.
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Indexability Check (indexability_check) | $0.05 | $0.04 | $0.04 | $0.03 |
Worked at the live Free-tier price:
- 3 indexability checks: $0.02 start + 3 × $0.05 = $0.17
- 25 indexability checks: $0.02 start + 25 × $0.05 = $1.27
- 100 indexability checks: $0.02 start + 100 × $0.05 = $5.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
Yield on the sample run: PARTIAL: 2 billable verdict(s), 1 blocked (unbilled status), 0 unreachable, 0 unparseable of 3 target(s) | indexability_check billable=2 | indexability_check charged=2.
⚖️ Legal & ToS
This actor reads public data only. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other web QA and enrichment tools actors?
A: Same output shape and billing model; this one covers Sitemap Indexability Auditor. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Fewer rows than expected → the source had fewer items in scope → widen the input.
- Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- Responsive Visual QA Matrix — Runs a headless-Chromium responsive QA pass on each URL across desktop/tablet/mobile and returns one verdict per URL: per-viewport layout metrics, a…
- 🧠 Review Sentiment Analyzer — Themes, Trends & Complaints — Turn any review set into themes, complaints, sentiment % and trends
- RSS Feed Contract Monitor — Checks a feed's health and contract: RSS/Atom/RDF shape validation, item canonicalization, a freshness score, duplicate GUID/link detection, ETag/Las…
- Social Preview Card Verifier — Verifies how a page unfurls on social platforms. Reads Open Graph and Twitter Card tags, validates each declared image for reachability, MIME and pix…
- Tech Stack Detector — Website Technology Lookup — Detect technologies used by websites across exactly 255 supported CMS, ecommerce, analytics, marketing, hosting, CDN, payment, and framework fingerpr…
- Tech Stack Enricher — Give it a list of company domains; it returns one CRM-ready record per domain describing
- 🏢 About NexGenData — NexGen Watch is NexGenData's fleet of 256 public monitoring and lookup actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


