

Recruiterflow Careers Jobs Exporter
Pricing
from $33.50 / 1,000 job records
Recruiterflow Careers Jobs Exporter
One structured job record per opening from employer career boards hosted by Recruiterflow — title, company, location, apply link. Keyless, logged-out, robots-honoured. Pay per job.
Pricing
from $33.50 / 1,000 job records
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
🧑💻 Recruiterflow Careers Jobs Exporter
One structured job_record per opening from employer career boards hosted by Recruiterflow — keyless, logged-out, robots-honored.
Difference: One normalized record per Recruiterflow hosted-board opening across one or many tenants — employer + slug identity, title, department, team, employment type, remote type, location, and the public application URL. Data is read from the board's own server-embedded window.jobsList JSON; Recruiterflow's separate KEYED external API is never called.
Output is one recruiterflow_job row per result; billing is pay-per-event, the value event being one job record (a $0.02 start fee per run, then $0.05 per job record).
No login, no API key and no CAPTCHA solving are involved: the source is read logged-out with an identified contact User-Agent.
📊 Sample Output
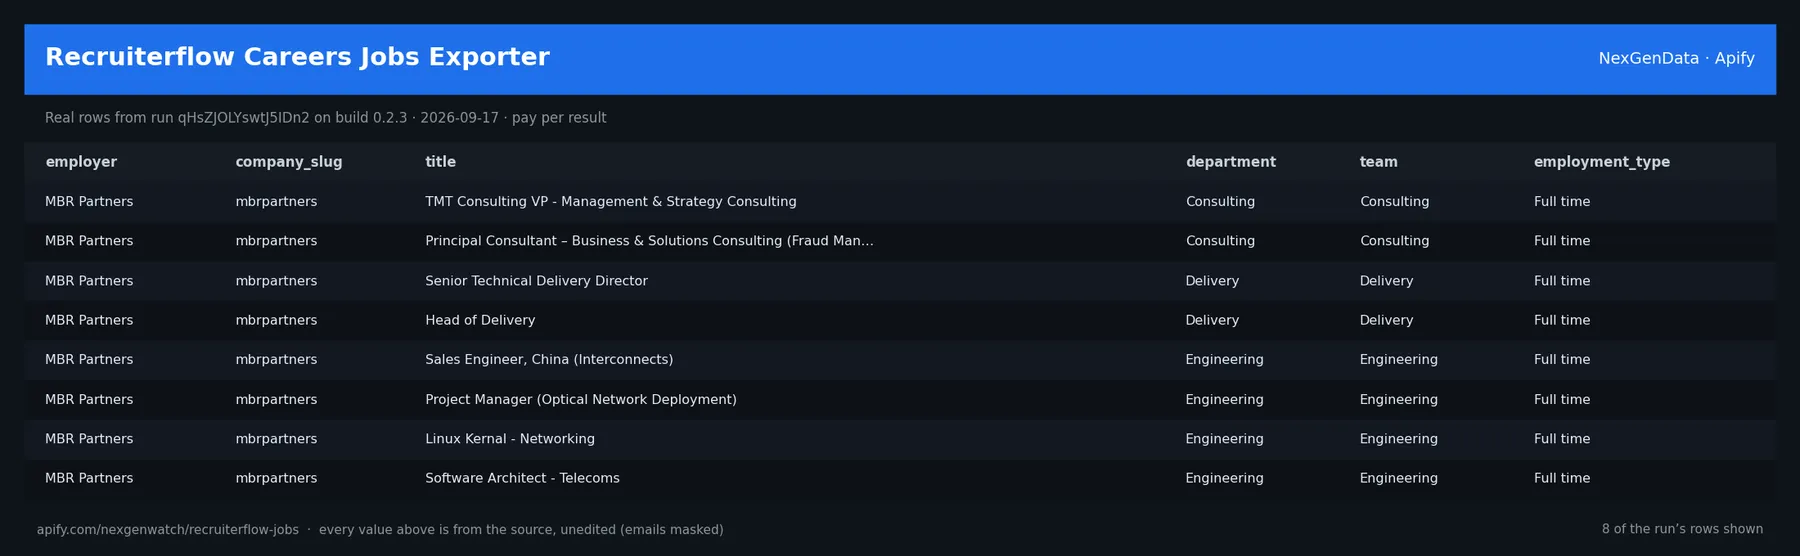
Real rows from run qHsZJOLYswtJ5IDn2 on build 0.2.3 (2026-09-17), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
| employer | company_slug | title | department | team | employment_type |
|---|---|---|---|---|---|
| MBR Partners | mbrpartners | TMT Consulting VP - Management & Strategy Consulting | Consulting | Consulting | Full time |
| MBR Partners | mbrpartners | Principal Consultant – Business & Solutions Consulting (Fraud Manageme | Consulting | Consulting | Full time |
| MBR Partners | mbrpartners | Senior Technical Delivery Director | Delivery | Delivery | Full time |
| MBR Partners | mbrpartners | Head of Delivery | Delivery | Delivery | Full time |
| MBR Partners | mbrpartners | Sales Engineer, China (Interconnects) | Engineering | Engineering | Full time |
| MBR Partners | mbrpartners | Project Manager (Optical Network Deployment) | Engineering | Engineering | Full time |
| MBR Partners | mbrpartners | Linux Kernal - Networking | Engineering | Engineering | Full time |
| MBR Partners | mbrpartners | Software Architect - Telecoms | Engineering | Engineering | Full time |
The run finished with the status message: NORMAL: 20 unique rows (0 duplicates collapsed) from None. billable=20
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
record_type(string) — e.g.recruiterflow_jobemployer(string/null) — e.g.MBR Partnerscompany_slug(string/null) — e.g.mbrpartnersjob_id(string/integer/null) — e.g.2126title(string/null) — e.g.TMT Consulting VP - Management & Strategy Consultingdepartment(string/null) — e.g.Consultingteam(string/null) — e.g.Consultingemployment_type(string/null) — e.g.Full timeremote_type(string/null) — null in every sample rowlocation(string/null) — e.g.Central Londonlocation_group(string/null) — e.g.Central Londonlast_opened(string/null) — e.g.2026-09-14T12:14:23+0000job_url(string/null) — e.g.https://recruiterflow.com/mbrpartners/jobs/2126source(string/null) — e.g.recruiterflow-jobsrelease_date(string/null) — null in every sample rowsource_url(string/null) — e.g.https://recruiterflow.com/mbrpartners/jobsobserved_at(string/null) — e.g.2026-09-17T17:47:23Zattribution(string/integer/null) — e.g.Source: employer career boards hosted by Recruiterflow (public, logged-out recruterminal(string/integer/null) — null in every sample rowreported_total(string/integer/null) — null in every sample rowraw_seen(string/integer/null) — null in every sample rowduplicates(string/integer/null) — null in every sample rowunique_found(string/integer/null) — null in every sample rowdelivered(string/integer/null) — null in every sample rowscope(string/integer/null) — null in every sample rownote(string/integer/null) — null in every sample rowlicense(string/integer/null) — null in every sample row
What you get
One job_record per opening, deduplicated on tenant slug + job id, with department and location enriched from the board's grouping keys. A RUN_RECEIPT key-value record carries the tenants read, scope, attribution, and totals.
Every run also writes a RUN_RECEIPT record to its key-value store with the source checks it made and the counts it charged — diagnostics never land in the paid dataset.
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 20 × $0.05 job_record = $1.02 on the Free tier — every delivered row was billed.
2. A smaller, narrowed run
Caps the run at 5 rows — about $0.27 on the Free tier ($0.02 start + 5 × $0.05).
3. A full-size run
Up to 5000 rows (the schema default for maxRecords) — about $250.02 on the Free tier ($0.02 start + 5000 × $0.05) if the source has that many.
🧾 JSON sample record
One real record from run qHsZJOLYswtJ5IDn2, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent. Pacing: CRAWL_DELAY=0.0.
Charging. Each job record is charged at the moment it is pushed (job_record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
How it behaves
Each board page at recruiterflow.com/{tenant}/jobs is fetched logged-out; the inline window.jobsList blob is parsed into one record per opening. robots.txt is Allow: / and explicitly permits AI/data bots. Zero-auth: if a board stops embedding jobsList (a key-gated shell), that tenant is reported empty rather than reaching for a key. Delivery is bounded to maxRecords.
Source
https://recruiterflow.com/{tenant}/jobs (inline window.jobsList; robots Allow: /)
Attribution
Source: employer career boards hosted by Recruiterflow (public, logged-out recruiterflow.com/{tenant}/jobs).
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Job record (job_record) | $0.05 | $0.04 | $0.04 | $0.03 |
Worked at the live Free-tier price:
- 8 job records: $0.02 start + 8 × $0.05 = $0.42
- 25 job records: $0.02 start + 25 × $0.05 = $1.27
- 5000 job records: $0.02 start + 5000 × $0.05 = $250.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
Yield on the sample run: NORMAL: 20 unique rows (0 duplicates collapsed) from None. billable=20. maxRecords is a hard ceiling on what is delivered and billed, never a target.
⚖️ Legal & ToS
This actor reads public data only. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How many rows can one run return?
A: Up to maxRecords (default 5000). Raise the cap for a bigger run; you pay per delivered row.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other ATS job feeds actors?
A: Same output shape and billing model; this one covers Recruiterflow Careers Jobs Exporter. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source (CRAWL_DELAY=0.0) and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Status says CAPPED → your cap (
maxRecords) was reached → raise it for a bigger run. - Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- PCRecruiter Jobs Scraper — One structured jobrecord per LIVE job posting from a public, logged-out ATS board. Public, robots-honoured
- Polymer Hosted Jobs — One structured jobrecord per record from the official public source, logged-out. Public, robots-honoured
- 🧰 ATS Hiring & Closure Delta Feed — Greenhouse, Lever, Ashby — Public ATS hiring & closure delta feed across six providers — opened/changed/closed/reopened deltas with confirmed closures, honest terminals, watch…
- Teamtailor Job Feed — Any Employer Board — Scrape jobs from any Teamtailor employer careers board. One structured record per public posting — title, department, location, link. No API key; pay…
- Workday Jobs Scraper — Any Employer Career Site — Export current job postings from public Workday career sites. Paste normal myworkdayjobs.com or myworkdaysite.com URLs and get titles, locations, req…
- 🏢 About NexGenData — NexGen Watch is NexGenData's fleet of 256 public monitoring and lookup actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.
