
YouTube Metadata Scraper: Views, Likes, Comments, Tags ($5/1K)
Pricing
from $4.00 / 1,000 video metadata
YouTube Metadata Scraper: Views, Likes, Comments, Tags ($5/1K)
$5 per 1,000 videos, failed inputs free. Full metadata for YouTube videos by ID or URL: views, likes, comments, length, publish date, description, tags, and channel.
Pricing
from $4.00 / 1,000 video metadata
Rating
0.0
(0)
Developer
Plumbline
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Features
Share
Full metadata for YouTube videos by ID or URL: views, likes, comments, length, publish date, description, tags, and channel. For analysts, agencies, and AI builders who need exact video stats.
Last verified working: 2026-11-16 (automatic live test run passed).
- Price: $5.00 per 1,000 video metadata records. No subscription; you pay only for video metadata records saved. Failed inputs are free. Try it on Apify's free plan (up to 20 video metadata records per run).
- Export: JSON, CSV, Excel, Google Sheets, or the API. Works with Make, Zapier, n8n, and AI agents (MCP).
Every run tells you plainly what worked and what did not: no silent empty runs.
What can YouTube Metadata Scraper do?
- Campaign reporting: track views, likes, and comments for a list of videos.
- Video audits: export title, description, and tags for SEO review.
What data does YouTube Metadata Scraper extract?
| Field | What it is | Example |
|---|---|---|
input | The ID or URL you submitted. | tIgIF5lve8U |
type | video or error. | video |
videoId | 11-character YouTube video id. | tIgIF5lve8U |
url | Watch URL. | https://www.youtube.com/watch?v=tIgIF5lve8U |
title | Video title. | I Just Need A Programmer | Prime Reacts |
description | Video description text. | Recorded live on twitch, GET IN https://twitch.tv/ThePrimeagen Become… |
channelName | Uploader display name. | The PrimeTime |
channelId | YouTube channel id. | UCUyeluBRhGPCW4rPe_UvBZQ |
channelUrl | https://www.youtube.com/channel/{channelId} | https://www.youtube.com/channel/UCUyeluBRhGPCW4rPe_UvBZQ |
views | View count as an integer when YouTube provided one. | 224438 |
likes | Like count when YouTube showed it. | 5658 |
commentCount | Comment count when available. | 501 |
durationSeconds | Length in seconds. | 1106 |
duration | Length as m:ss or h:mm:ss. | 18:26 |
publishedAt | Upload or publish date as returned for the video. | 20240105 |
thumbnailUrl | Largest thumbnail URL returned. | https://i.ytimg.com/vi/tIgIF5lve8U/maxresdefault.jpg |
category | YouTube category when present. | |
tags | Creator tags when present. | [programming, …] |
Examples come from a real run. Every row has every field; a value the page did not show is null, never guessed.
One row per video.
How to use YouTube Metadata Scraper
- Click Try for free (or Start) on this page.
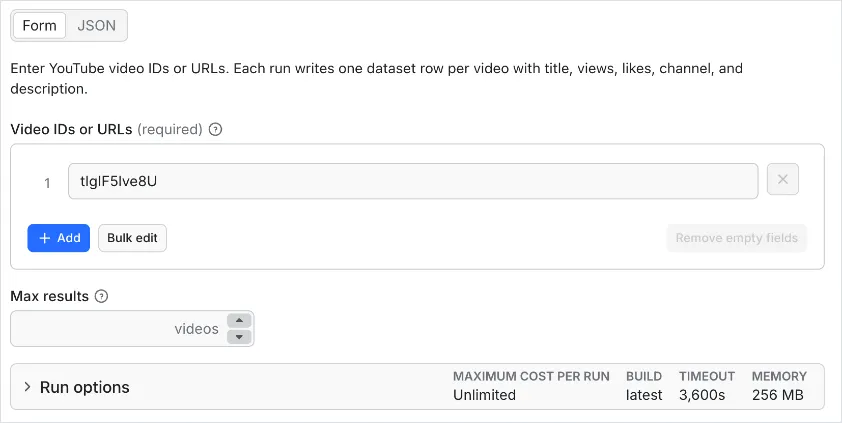
- Enter one video ID or URL per line in the first field. The form is prefilled with a working example.
- Optional: set Max results and the other options.
- Click Start. Open the Output tab, or export JSON, CSV, Excel, or HTML.
Example input
Example output
One real row from a run on 17 October 2026 (long values shortened here):
How much does YouTube Metadata Scraper cost?
Pay per result: $5.00 per 1,000 video metadata records, plus $0.001 per run start. No subscription. With Apify's Store discounts: $4.50 per 1,000 on the Silver tier, $4.00 on Gold and above.
| Event | When | Price |
|---|---|---|
| Actor start | Once per run (per GB of memory; the default 256 MB counts as one) | $0.001 |
| Video metadata | Each video metadata record saved to the dataset | $0.005 |
| Example | Rows | Cost |
|---|---|---|
| 10 videos | 10 | $0.001 + $0.05 = $0.051 |
| 100 videos | 100 | $0.001 + $0.50 = $0.501 |
| 1,000 videos | 1,000 | $0.001 + $5.00 = $5.001 |
- Retries after a bot check or a temporary error cost you nothing. You pay only for rows saved.
- An input that fails after all retries saves one error row so you can see what failed and why. Error rows are free.
- On Apify's free plan a run stops at 20 rows. Any paid Apify plan removes this limit.
- Set Max total charge per run in the run options. The Actor stops cleanly at that limit and keeps every row saved so far.
What you can count on
- Same columns on every row. Missing values are
null, so spreadsheets and databases never break. - No silent failures. An input that fails gets an error row with
errorCodeand a plain-languageerrorMessage. The other inputs keep running. - A clear run summary. The run status says how many results were saved, how many inputs failed, and why. The same numbers are saved as the
RUN_SUMMARYrecord in the run's key-value store, for automations. - Automatic retries. Bot checks and temporary errors are retried with a fresh request before an input counts as failed.
- Limits respected. Max results and your spending limit stop the run cleanly.
YouTube Metadata Scraper API for code, automations, and AI agents
API (returns the rows when the run finishes):
Python (pip install apify-client):
JavaScript (npm install apify-client):
No-code: connect the Actor in Make, Zapier, n8n, or Google Sheets through Apify's integrations, or add a webhook to get notified when a run finishes.
AI agents (MCP): add https://mcp.apify.com?tools=plumblinedata/youtube-metadata-scraper to Claude, Cursor, or any MCP client. The agent can call this Actor as a tool with the same input as above.
Limitations
- Private, deleted, and members-only videos return an error row with the reason.
- Transcripts and comment texts are not included.
FAQ
How do I get YouTube video views and likes in bulk?
Paste video IDs or URLs into Video IDs or URLs (videoIds), one per line. Each video returns views, likes, and commentCount.
How to extract YouTube video tags and descriptions
Paste the videos into Video IDs or URLs (videoIds). Each row has tags, description, category, and title.
How to track YouTube video stats for a campaign
Put the campaign videos in Video IDs or URLs (videoIds) and schedule the Actor. Compare views, likes, and commentCount per videoId between runs.
What does an error row mean?
It marks an input that failed after retries. errorCode is short (blocked, empty_result, not_available, http_404, or invalid_... for a bad ID or URL) and errorMessage says what to do. Remove error rows with a filter on type.
Can I run it on a schedule?
Yes. Create a task with your input in Apify Console, then add a schedule (for example every day at 8:00).
Is it legal to collect this data?
The Actor reads public pages that anyone can open without logging in. You are responsible for how you use the data, including copyright, personal data rules such as GDPR, and the site's terms. If you are not sure, ask a lawyer.
Related Actors
| Actor | What it does |
|---|---|
| YouTube Search Scraper | YouTube search results by keyword |
| YouTube Channel Scraper | Latest videos from any YouTube channel plus the channel profile |
Support
Found a problem or need a field? Open an issue on the Issues tab. Include the run ID and one input that shows the problem. We read every issue.


