
Backlink Keywords Scraper
Pricing
from $0.25 / 1,000 results
Backlink Keywords Scraper
Extract granular backlinks, anchor snippets, DOM positions, and on-page keyword density in one lightning-fast pass.
Pricing
from $0.25 / 1,000 results
Rating
0.0
(0)
Developer
REXREUS D.O
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
3 days ago
Last modified
Categories
Share
Backlink and Keywords Scraper
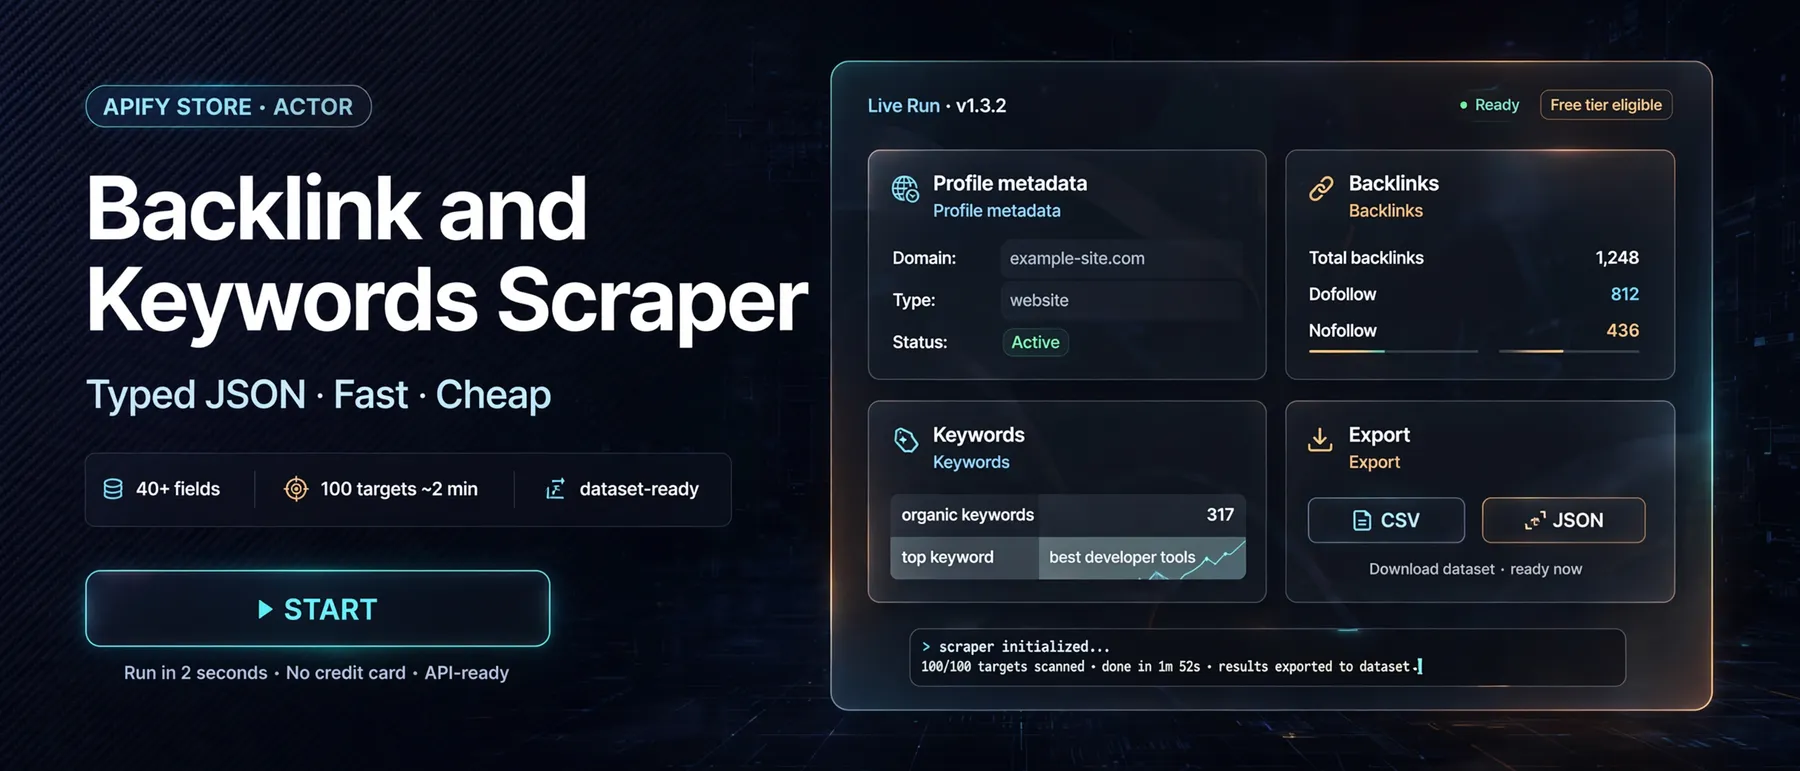
Extract granular backlinks, anchor snippets, DOM positions, and on-page keyword density in one lightning-fast pass.
Pure HTTP Cheerio · TypeScript · Memory < 128MB · 100% Flat CSV-Ready

In one line: Crawl public web domains → extract flat, CSV-ready link records with surrounding sentence context, DOM layout positioning, and 1/2/3-gram keyword densities for SEO auditors and digital PR teams.
Input Target seed URLs, crawl depth limit, max pages, and link validation toggle Output 1 flat record per link with anchor snippet, rel equity, DOM position, and top keywords Cost ~$0.25 per 1,000 links extracted (Pay-Per-Event) · < 0.01 CU per 1,000 links Speed 20–35 pages/sec on 128MB RAM (~1–2 minutes for 100 pages) Runs on Apify Console · CLI · API
Who it's for
- SEO Specialists & Auditors: Audit internal link architecture, check anchor text distribution, isolate boilerplate footer links, and verify
rel="nofollow"equity tags without desktop crawler lag. - Link Builders & Outreach Teams: Discover high-relevance editorial outlinks with surrounding sentence context snippets (±80 chars) to craft tailored guest post and broken link pitches.
- Content Strategists & Copywriters: Analyze topical keyword density (1-gram, 2-gram, 3-gram) correlated with on-page link graphs to eliminate keyword cannibalization.
- Webmasters & Site Migration Engineers: Verify all internal and external link references post-redesign with optional HTTP status checks.
What you get
- Granular Link Records: Every discovered link generates an independent row containing
sourceUrl,targetUrl,anchorText,rel, andlinkType. - Reasonable Surfer Context (±80 chars): Automatically extracts adjacent sentence context around anchor text for instant semantic relevance audit.
- DOM Layout Categorization: Identifies whether a link resides in
header,nav,content,footer, orsidebar. - On-Page Keyword Intelligence: Tokenizes clean editorial body text to compute 1-gram, 2-gram, and 3-gram frequencies, keyword densities, and top page terms.
- Spreadsheet-Ready Flat Schema: Zero nested arrays; opens seamlessly in Google Sheets, Microsoft Excel, and Airtable.
- SSRF & CSV Injection Protection: Pre-flight DNS resolution blocks private RFC 1918 subnets and cloud metadata endpoints, while formula triggers (
=, +, -, @) are auto-sanitized.
Why this Actor?
| Feature | What you get |
|---|---|
| Flat Link-Level Schema | 1 row per link; filter directly in Excel without data wrangling scripts |
| Surrounding Text Snippet | View the complete sentence containing the anchor without opening the web page |
| DOM Position Classification | Separate high-equity editorial links from boilerplate navigation and footer links |
| N-Gram Keyword Analysis | Discovers top 1, 2, and 3-word topical phrases with density percentage |
| Ultra-Low Memory (<128MB) | Consumes 90% fewer Compute Units than heavy browser-based scrapers |
| Optional Status Probe | Checks destination HTTP response codes (200, 404, 500) on demand |
How it compares
| Capability | Backlink & Keywords Scraper | Generic Link Extractors | Heavy Browser Scrapers |
|---|---|---|---|
| Engine Architecture | Pure HTTP Cheerio (<128MB) | HTTP or Puppeteer | Headless Chrome (1GB–4GB) |
| Output Granularity | Flat Link-Level (1 row/link) | Nested JSON page arrays | Unstructured Markdown / HTML |
| Surrounding Text Snippet | ✅ Yes (±80 chars) | ❌ No | ❌ No |
DOM Position (content/nav) | ✅ Yes | ⚠️ Partial | ❌ Stripped |
| N-Gram Keyword Density | ✅ Yes (1/2/3-grams) | ❌ No | ❌ No |
| Cost per 1,000 Links | $0.25 | $1.15 – $5.00 | $10.00+ in CU burn |
Where it wins: Delivers spreadsheet-ready backlink records enriched with editorial context snippets and keyword density at a fraction of competitor costs.
Where it doesn't: Does not execute client-side JavaScript or solve Cloudflare Turnstile captchas on SPA sites (public server-rendered HTML only).
Quick start
Apify Console
- Open Backlink and Keywords Scraper on Apify Store and click Start.
- Enter your seed URL (e.g.
https://crawlee.dev) in Start URLs. - Configure
maxPagesPerCrawl(e.g.20) andmaxCrawlDepth(e.g.2). - Click Start and watch results stream into Storage → Dataset.
- Click Export to download a clean, formatted CSV or Excel spreadsheet.
How it works
Input
Input Field Specifications
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
startUrls | Array | Yes | [{"url": "https://crawlee.dev"}] | List of seed URLs or domain homepages to start crawling from. |
maxPagesPerCrawl | Integer | No | 30 | Maximum number of pages to crawl before terminating (1–5000). |
maxCrawlDepth | Integer | No | 2 | Maximum click distance from seeds (0 = seed URLs only). |
crawlInternalLinks | Boolean | No | true | Follow internal links across the same domain apex. |
checkTargetStatus | Boolean | No | false | Verify destination HTTP status codes via lightweight HEAD probes. |
maxConcurrency | Integer | No | 8 | Maximum concurrent HTTP connections (1–15). |
proxyConfiguration | Object | No | { "useApifyProxy": false } | Optional proxy settings for target websites with rate limits. |
Output
Sample Dataset Record (JSON)
Dataset Field Specifications
| Field | Type | Format | Description |
|---|---|---|---|
sourceUrl | String | URI | URL of the crawled web page where the link was found. |
targetUrl | String | URI | Fully-resolved destination URL. |
anchorText | String | Text | Clickable anchor text, image alt text, or aria-label. |
surroundingSnippet | String | Text | ±80 characters of sentence context surrounding the anchor. |
rel | String | Text | Link equity attribute (dofollow, nofollow, sponsored, ugc). |
linkType | String | Text | Link category (internal, external, self-referential). |
linkPosition | String | Text | DOM container classification (header, nav, content, footer, sidebar). |
pageTitle | String | Text | HTML title tag of the source web page. |
pageTopKeywords | String | Text | Top 3 extracted topical n-grams of the page for instant sorting. |
httpStatus | Number | Integer | Target HTTP response status code (when checkTargetStatus is enabled). |
scrapedAt | String | ISO-8601 | Timestamp when the link was extracted. |
Key-Value Store: Key OUTPUT stores a run summary record containing pagesCrawled, totalLinksExtracted, and completedAt.
Cost, limits, proxy
| Metric | Specification |
|---|---|
| Memory Allocation | 128 MB – 256 MB (Default: 256 MB, Peak: ~143 MB) |
| Compute Units per 1,000 Links | cf9nQL75R04rkre2m) |
| Pricing Model | Pay-Per-Event ($0.005 init + $0.25 / 1,000 links extracted) |
| Throughput | 3–5 pages/sec (HTTP concurrency 8) |
| Proxy Recommendation | None / Datacenter for public sites; Apify Residential for strict anti-bot targets |
Recipes
1. Single-Page Link & Keyword Audit (No Deep Crawl)
2. Deep Domain Backlink Extraction (50 Pages, Depth 2)
3. Broken Outlink Audit with Status Code Verification
Troubleshooting
| Symptom | Cause | Solution |
|---|---|---|
ERR_SSRF_BLOCKED | Seed URL points to localhost or private RFC 1918 IP | Supply public internet URLs only |
| 0 links extracted | Page is client-rendered SPA without server HTML | Verify target renders server HTML or check URL path |
| Crawl finishes too quickly | maxPagesPerCrawl or maxCrawlDepth reached | Increase maxPagesPerCrawl or maxCrawlDepth |
STATUS_429_RATE_LIMITED | Target server is throttling rapid requests | Enable proxyConfiguration or lower maxConcurrency to 2 |
FAQ
Q: Can this scraper extract backlinks pointing to my website from other websites?
A: This scraper audits on-page links on the target websites you specify. To find external backlinks pointing to your domain, input prospective competitor or partner domains, and the scraper will extract all outbound links and anchor texts.
Q: How is keyword density calculated?
A: Body text is parsed, noise tags (<script>, <style>, <nav>) are stripped, and words are matched using a linear Unicode tokenizer. Stopwords are filtered, and n-grams ($n=1, 2, 3$) are scored using $(count \times n / totalWords) \times 100$.
Q: Why is this Actor so much cheaper than other link extractors?
A: It uses pure HTTP CheerioCrawler without launching headless Chrome browsers, consuming under 128MB RAM and executing in milliseconds per page.
Q: Does it work with JavaScript-rendered Single Page Applications (SPAs)?
A: No. To keep compute costs ultra-low, this Actor targets public HTML server-rendered responses. Over 90% of content and article websites render HTML server-side.
Q: Can I export directly to Microsoft Excel or Google Sheets?
A: Yes! Every record is 100% flat with zero nested arrays, designed specifically for immediate spreadsheet import.
Limitations
- Scrapes publicly available HTML/XHTML pages only. Does not bypass login walls or authentication.
- Users are responsible for complying with target website Terms of Service and applicable privacy regulations.
Run it
Open Backlink and Keywords Scraper on the Apify Console and click Start.
License
Copyright © 2026 REXREUS. Licensed under the MIT License.


