
Google Trends Scraper
Pricing
from $2.00 / 1,000 results
Google Trends Scraper
Get daily trends, interest curves, related queries & country comparisons from Google Trends — without a browser, proxy, or API key.
Pricing
from $2.00 / 1,000 results
Rating
0.0
(0)
Developer
REXREUS D.O
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
Google Trends Scraper
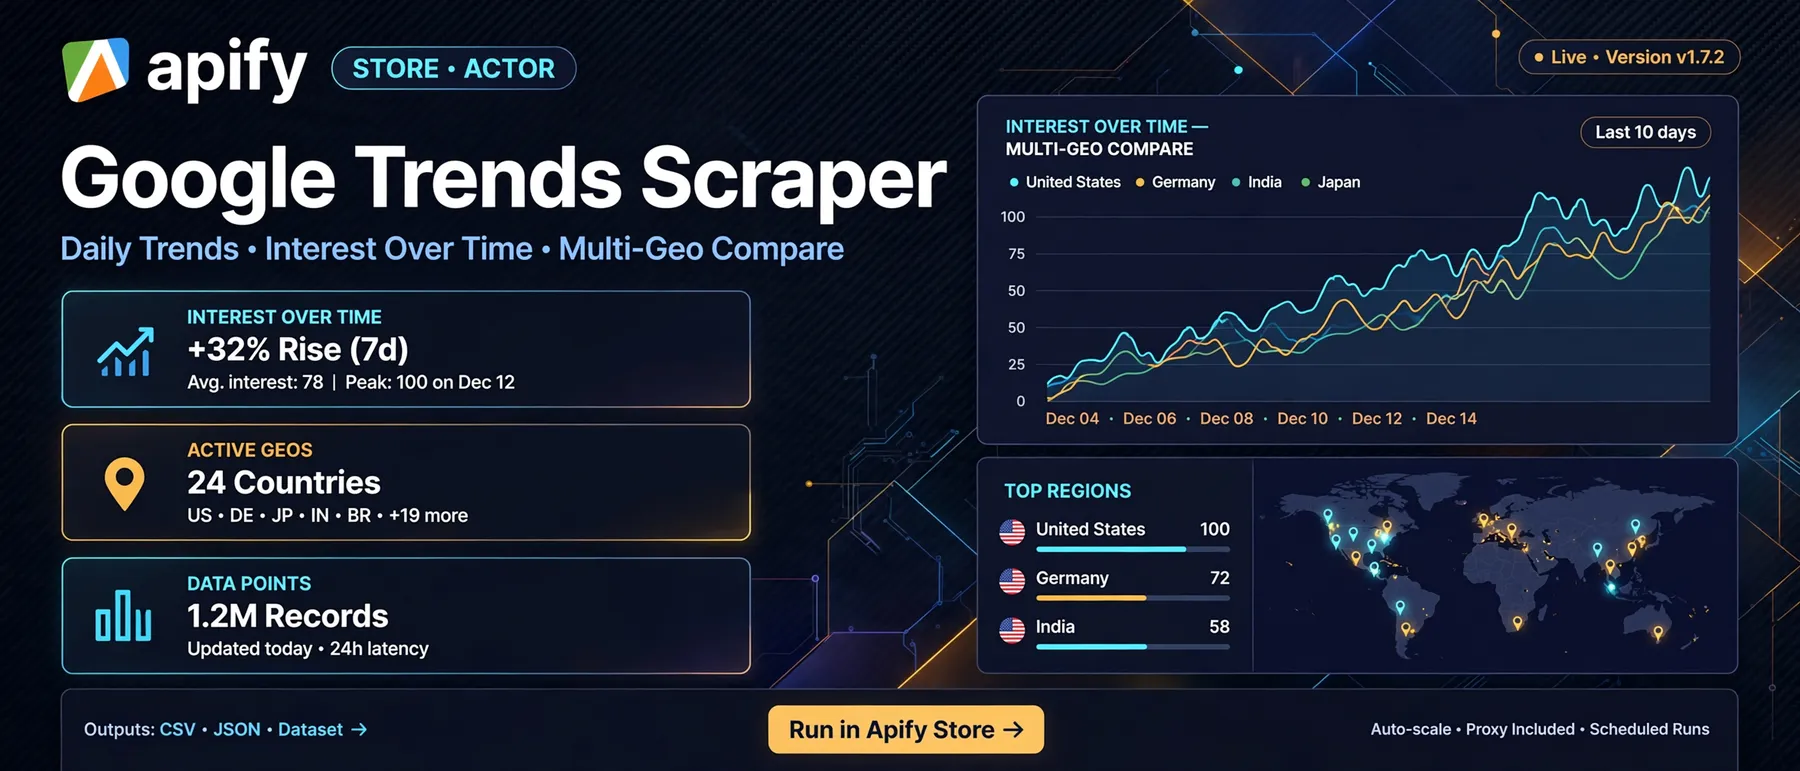
Get daily trends, interest curves, related queries & country comparisons from Google Trends — without a browser, proxy, or API key.
HTTP-only (JSONP + official RSS) · no Playwright · no cookies persisted · rate-limit aware

In one line: Scrape 5 Google Trends datasets (daily trends, interest over time, related queries, related topics, multi-geo compare) → one flat, schema-backed JSON/CSV record per trend → for content teams, SEOs, and analysts who need current trend data in minutes.
Input a mode + keywords and/or geo codes Output one clean record per trend; fields per mode (see Output) Cost ~2 HTTP requests per keyword (no browser, ~256 MB); 20 records ≈ near-zero CU Speed daily trends (2 geos) ≈ seconds; 50 keywords interest ≈ ~2–3 min (rate-limit aware) Runs on Apify Console · CLI · API
Who it's for
- Content & editorial teams — know what's trending per market before you pick a headline.
- SEO / keyword researchers — related queries & topics give a ready seed keyword list.
- Regional growth analysts — multi-geo compare shows where demand concentrates.
- News & media monitors — daily RSS trends as an automatic morning data feed.
What you get
- Daily trending searches by country — top-10 per geo from Google's official trending RSS (
source: rss), no cookie needed, near-instant. - Interest-over-time curves — per-point value (0–100) with
formattedTime,time(unix) andhasDatafor clean charting. - Related queries (Top + Rising) — volume and momentum signals per keyword.
- Related topics — entity-level trends, not just strings.
- Multi-geo comparison in ONE run — pass a country list, get region-by-region interest values in a single pass (competitors often cap at one geo per run).
- Flat, sanitized records — control chars stripped, length-capped, ready for CSV / BI / AI pipelines with zero cleanup.
Why this Actor?
| Feature | What you get |
|---|---|
| 5 modes in one Actor | daily + IOT + related + topics + geo-compare, no second tool |
| HTTP-only (JSONP/RSS) | no Chromium, no proxy, no fingerprinting → lower CU + no proxy line item |
| Request budget guard | hard cap stops runaway cost & protects against IP bans |
| Per-keyword error records | one failing keyword doesn't kill the run — an error row is logged, the rest continue |
| Auto NID cookie bootstrap | session warms once in-memory (never persisted/printed) to pass Google's token checks |
| Backoff + re-warm | 429s auto-retried 2→60s with jitter; missing-cookie 429 auto re-warms |
| Flat CSV-ready schema | mode-qualified single-record view via dataset schema |
How it compares
| Capability | This Actor | apify/google-trends-scraper | data_xplorer/google-trends-fast-scraper |
|---|---|---|---|
| Daily trends per geo | ✅ (RSS) | ❌ | ✅ (browser, 125+ countries) |
| Interest over time (batch keywords) | ✅ (up to 50) | ✅ | ⚠️ one keyword per run |
| Related queries + topics | ✅ (HTTP, always on) | ✅ (browser) | ❌ |
| Multi-geo compare in one run | ✅ | ✅ (viewedFrom proxy) | ❌ |
| No browser / no proxy | ✅ | ❌ (pageLoadTimeout, maxConcurrency) | ❌ (browser + proxy rotation) |
| Per-request pricing anchor | ~$0.001–0.002 (estimate) | $0.003/result | $0.002/result + $0.025 start |
Quick start
Apify Console
- Open the Actor and click Start.
- Accept the default (
mode: dailyTrends,geos: ["US","ID"]) or switch mode. - Results land in Storage → Dataset (JSON or CSV export).
How it works
Input
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
mode | string | ✅ | dailyTrends | dailyTrends, interestOverTime, relatedQueries, relatedTopics, multiGeoTrends (see schema enum) |
keywords | string[] | mode-dependent | — | 1–50 keywords for interest/related modes (max 50/run to stay in IP budget) |
geos | string[] | mode-dependent | ["US","ID"] daily / ["US"] others | ISO 3166-1 alpha-2, region sub-codes, or WORLD; max 50 |
timeRange | string | — | today 12-m | now 4-h · now 1-d · today 3-m · today 12-m · today 5-y |
category | integer | — | 0 | Google Trends category id; 0 = All (19 Entertainment · 21 Health · 27 Finance · 29 Food) |
maxKeywords | integer | — | 50 | Hard cap on keywords processed this run (protects IP budget) |
maxRequestCap | integer | — | 400 | Hard cap on total HTTP requests per run (budget guard) |
includeTopics | boolean | — | false | relatedQueries mode: also fetch related topics |
Output
One flat record per trend/mode in the dataset. Example (real dailyTrends run, US):
| Field | Modes | Type | Description |
|---|---|---|---|
mode | all | string | dataset name |
query | all | string | originating keyword (or geo for dailyTrends) |
geo | all | string | ISO code / WORLD |
time, formattedTime | interestOverTime | number / string | unix sec + human date |
value, formattedValue | interest / multi-geo / related | number / string | scalar value (0–100) |
hasData | all | boolean | false on empty/error rows |
rankKind, rank | relatedQueries/topics | string / number | TOP / RISING + position |
entityTitle | relatedTopics | string | entity name |
date, formattedDate | dailyTrends | string | trending date |
trendTitle, trendUrl, approxTraffic | dailyTrends | string | + official RSS link + approx traffic |
geoCode, geoName, maxValueIndex | multiGeoTrends | string / number | region compare |
link | related* | string | query/topic link |
error | any | string | present only on per-keyword failure rows |
Output schema: .actor/output_schema.json (dataset link). Dataset view: .actor/dataset_schema.json.
Cost, limits, proxy
| Item | Value |
|---|---|
| Min memory | 256 MB (max 512 MB set; actor.json) |
| Verified run (3 geo daily-trends, 30 records) | 3.55 s, 0.00099 CU, 63.4 MB peak → ~$0.0002 platform cost |
| Expected run (50-keyword interest) | ≈ 100 requests, ~2–3 min, rate-limit aware |
| Proxy | none required (datacenter IP OK for token flow; heavy runs may 429) |
| Retries | backoff 2→60s + 30% jitter; hard 429 fail-fast after 2 (per-keyword error row) |
| Cost per 1,000 results | ≈ $0.0066 platform cost (verified: 30 records / 0.00099 CU) |
Recipes
Daily trends for your markets (default)
→ Morning news/content feed, top-10 per country.
Keyword momentum (Top + Rising)
→ Seed lists for content/SEO in one run.
Multi-geo demand map
→ Where to localize / prioritize ad spend.
Troubleshooting
| Symptom | Cause | Fix |
|---|---|---|
error: RATE_LIMITED (429 missing cookie) on a keyword | session cookie stale | auto re-warm triggers once; reduce maxKeywords/pause between runs |
error: RATE_LIMITED (429 IP budget) | IP exhausted on Google's side | backoff 2–60s; wait IP reset, lower maxRequestCap |
error: EMPTY_RESULT row | valid empty (OF-8) — no data that period | legit; e.g. relatedTopics returns empty on some sessions |
| Dataset has 0 items | geo blocked / wrong geo code | verify geo is ISO alpha-2; check warm() status in log |
dailyTrends returns < 10 items | RSS top-10 is the public ceiling | by design — no category filter on RSS |
FAQ
Q: Do I need a Google account or API key? No — public JSONP/RSS endpoints, NID cookie is auto-bootstrapped in memory.
Q: Why no Playwright/Puppeteer? HTTP-only = 10–20× cheaper CU + faster; all 5 modes work over JSONP/RSS.
Q: Is daily trends data "official"? It uses Google's public trending RSS feed — same data the trends page exposes; it's top-10 with no category/volume numbers.
Q: Why did one keyword return an error record?
Rate limit or transient failure after 2 retries — the rest of the run continues; check the log + error value.
Q: Can I get historical data?
Yes — interest/related/multi-geo support today 5-y or custom ranges.
Q: What does includeTopics do?
In relatedQueries mode it also fetches related topics for the same keywords.
Limitations
- Public data only — you are responsible for Google's ToS and applicable privacy law.
- RSS daily trends: top-10, no category filter, no absolute search volumes (approx buckets only).
- Values are relative interest (0–100), not absolute search counts.
- Google may geo-block datacenter IPs; heavy runs can hit 429 → auto-retry + budget guard keeps it safe.
Run it
Open the Actor on Apify Console and click Start. Every run writes flat records to your Dataset — export JSON or CSV directly.


