
Recruitee Jobs Scraper – Job Listings by Company Career Site
Pricing
from $1.00 / 1,000 job ads
Recruitee Jobs Scraper – Job Listings by Company Career Site
Job listings from Recruitee career sites by company: title, department, locations with country, employment type, remote flag, published salary and full text, one request per company. Many companies per run, keyword and location filters, only new jobs on schedules. No login, no personal data.
Pricing
from $1.00 / 1,000 job ads
Rating
0.0
(0)
Developer
Rowcraft
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
17 hours ago
Last modified
Categories
Share
Recruitee Jobs Scraper: Job Listings from Company Career Sites
Get every published job from the Recruitee career sites of the companies you choose, as clean, flat JSON, CSV or Excel. This Recruitee jobs scraper reads Recruitee's public Careers Site API, the keyless interface Recruitee offers for showing a company's jobs on its own website, so it is fast and does not break when a careers page changes its design. One request returns a company's whole list with texts, locations and salaries; list as many companies as you like in one run.
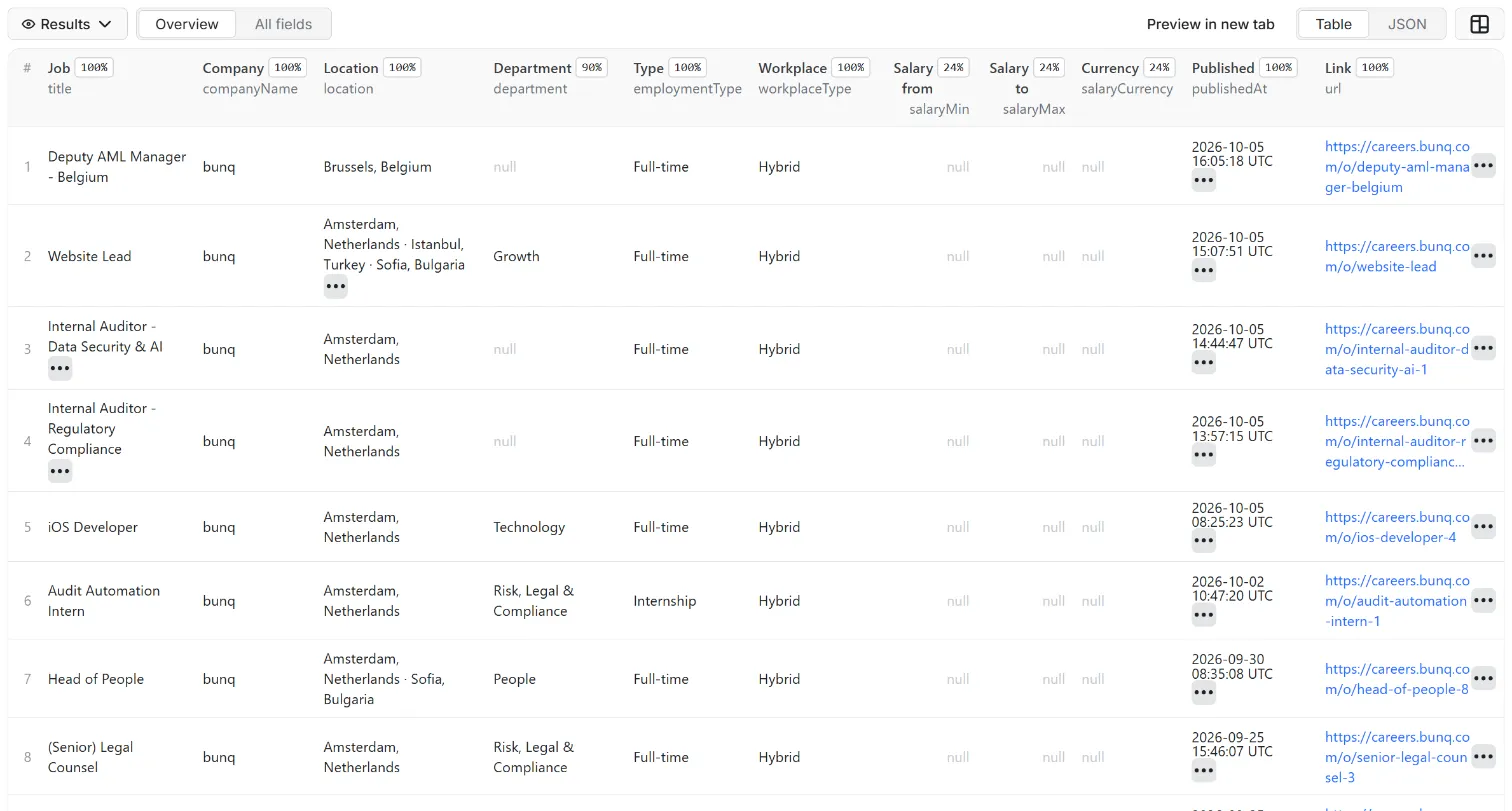
Each job comes with title, department, every location with its country code, employment and workplace type, remote flag, publication date, the published salary (minimum, maximum, currency, period) and the full ad text with the requirements as a separate column.
What you get
One row per job:
- Job:
id(recruitee:company:jobId), title, job and apply page, company name - Classification: department, employment type (full-time, part-time, internship…), workplace type (remote, hybrid, on-site), remote flag; category, experience, education, tags and hours per week in
metadatawhen the company fills them in - Location: all locations, plus country, ISO country code, region and city of the first one
- Dates: published, last updated
- Salary: minimum, maximum, currency, period and the range as text, when the company publishes it
- Text: description and requirements as plain text, optional HTML
Why this actor
- One request per company: the Careers Site API returns every published job with its text, so there are no detail requests to pay for in time.
- Salary fields straight from the API, with currency and period (per month, per year), for the companies that publish them.
- Description and requirements apart, parsed from the two texts Recruitee keeps; locations parsed into country code, region and city.
- Contact details removed from texts, a report per company and a charge cap: you pay per delivered job ad.
How to use it
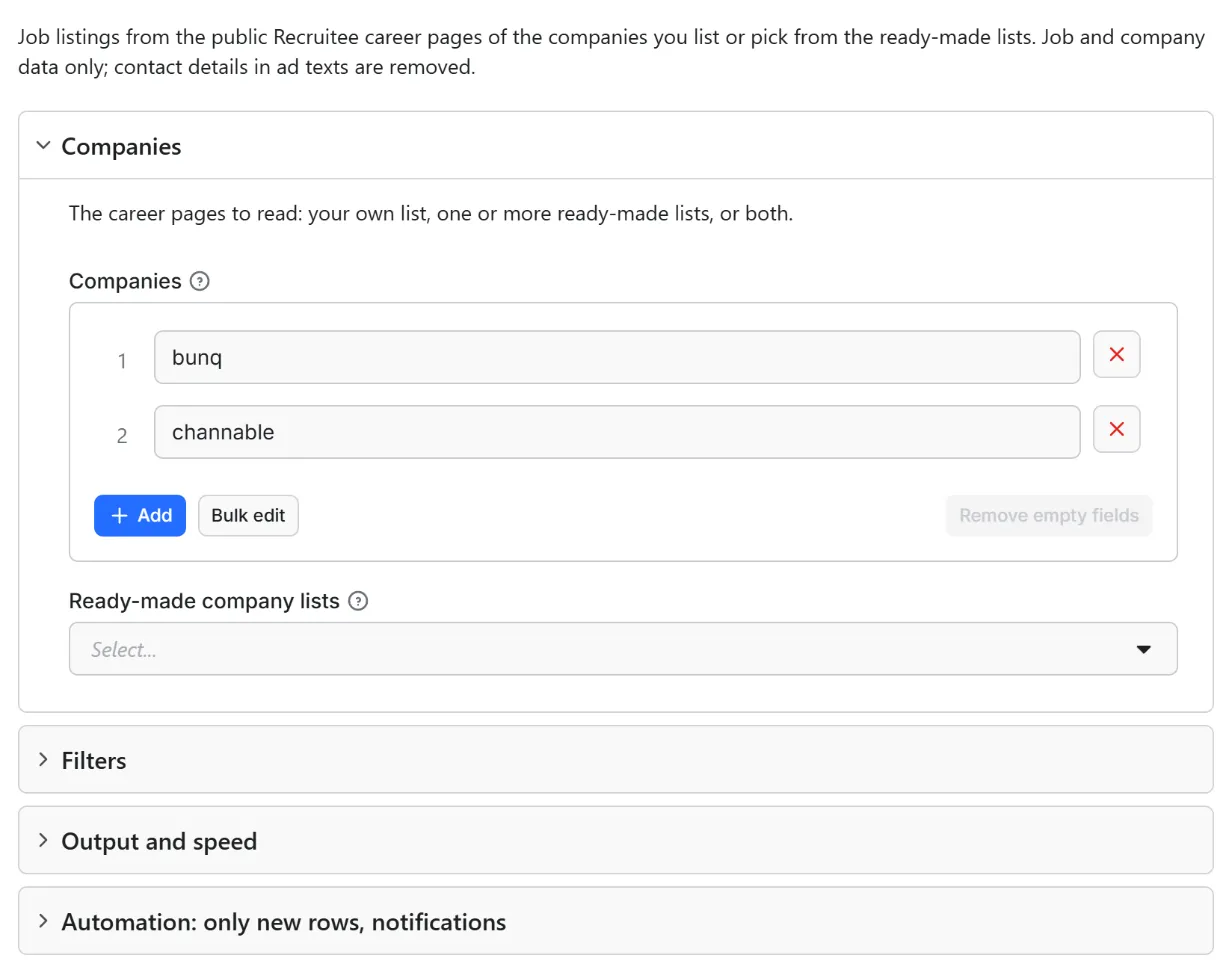
- Open the Actor and fill in Companies (the other fields are optional filters).
- Set Maximum job ads to a small number for a first try (the default is a safe start).
- Click Start. The status line shows progress; the run stops cleanly at your limit or at the charge limit you set in the run options.
- Open the Dataset tab and download JSON, CSV, Excel, XML or HTML, or send the rows to Google Sheets, Slack, Make, n8n or Zapier with the Integrations tab.
- To run it on a schedule, use Schedules in Apify Console and turn on Only new rows since the last run below: every run then costs only the new rows, and a webhook URL tells you when something new came in.
Input
| Field | What it does |
|---|---|
companies, lists | Company names (bunq), career-site addresses (channable.recruitee.com) or job links on recruitee.com (then only that job); ready-made lists picked in the form |
keywords | Match the job title; keywordsInDescription also searches the ad text |
locations | Countries, codes, regions or cities; add remote to keep remote jobs |
departments, employmentTypes, remoteOnly, withSalaryOnly, postedAfter | More filters (postedAfter: 2026-10-01, yesterday, 7 days) |
maxItems, maxItemsPerCompany, includeHtml | Limits (0 = none); HTML text |
onlyNew, stateName, notifyUrl, notifyWhenEmpty | See Automation below |
Example: jobs with a published salary in the Netherlands, from two companies, posted in the last 30 days.
Output
37 fields per row. Empty values are null, never missing, so CSV and Excel columns are stable.
| Field | Type | Example |
|---|---|---|
id | string | greenhouse:stripe:8172510 |
jobId | string | 8172510 |
ats | string | greenhouse |
company | string | stripe |
companyName | string | Stripe |
title | string | Abuse Investigator |
url | string | Job page |
applyUrl | string | Apply page |
requisitionCode | string | Requisition code |
department | string | Department (first) |
departments | array | All departments |
team | string | Team or function |
employmentType | string | Full-time |
workplaceType | string | Workplace type: Remote, Hybrid, On-site, or as written |
isRemote | boolean | False |
location | string | Dublin · Ireland |
locations | array | Locations: raw text, country, countryCode (ISO 3166-1), region, city |
country | string | Ireland |
countryCode | string | IE |
region | string | Region or state of the first location |
city | string | Dublin |
publishedAt | string | 2026-09-03T17:30:34.000Z |
updatedAt | string | Last update (when the system publishes it) |
language | string | en |
salaryMin | number | Salary from (when the employer publishes it) |
salaryMax | number | Salary to |
salaryCurrency | string | Salary currency (ISO 4217) |
salaryPeriod | string | Salary period: year, month, week, day, hour |
salaryText | string | Salary as the employer wrote it |
descriptionText | string | Full ad text as plain text, contact details removed |
requirementsText | string | Requirements as a separate text (Lever, Workable, Recruitee, Personio, when the employer separates them) |
benefitsText | string | Benefits as a separate text (Lever, Workable, Personio, when separated) |
descriptionHtml | string | HTML version of the description (only with "Include HTML") |
requirementsHtml | string | HTML version of the requirements (only with "Include HTML") |
benefitsHtml | string | HTML version of the benefits (only with "Include HTML") |
metadata | object | Other fields the employer set: custom fields, level, category, experience, hours per week, keywords |
detailsIncluded | boolean | False |
Example rows
Two real rows from a run (long texts shortened here, complete in the dataset):
Results can be downloaded as JSON, CSV, Excel, XML or HTML from the Dataset tab, or read through the Apify API.
Pricing
Pay per result. You pay for each job ad delivered to your dataset, nothing else: no subscription, no minimum, no charge for rows your filters drop or for the requests behind them.
| Your Apify plan | Price per 1,000 rows | Price per row |
|---|---|---|
| Free plan | $1.50 | $0.0015 |
| Starter plan | $1.33 | $0.00133 |
| Scale plan | $1.17 | $0.00117 |
| Business plan and above | $1.00 | $0.001 |
Example: 1,000 job ads cost $1.50 on the Free plan and $1.00 on the Business plan. The Apify platform usage of a run (compute, storage) is small for this actor — well under one cent per 1,000 rows — and is billed by Apify separately, as for every Actor.
A start event of $0.00005 is charged once per run (Apify default).
Cap your spend: set Maximum total charge in the run options. The actor stops cleanly when the cap is reached and you keep everything delivered until then. The run summary (RUN_SUMMARY in the key-value store) says why a run stopped.
Automation: only new rows, notifications, schedules
Only new rows since the last run. Turn on onlyNew and the actor remembers every job ad it delivered to you (in a key-value store named rowcraft-recruitee-jobs-scraper-state in your Apify account). The next run with the same stateName skips what you already have and you pay only for new rows. The first run delivers everything that matches. Use a different stateName for each schedule or search so they keep separate memories.
Notification when the run ends. Put a webhook address in notifyUrl and the actor sends one JSON POST with the number of new rows, links to the dataset (JSON and CSV) and the run. It works out of the box with Slack and Discord incoming webhooks (the message is in text and content), with Make, n8n and Zapier catch hooks, and with your own endpoint. By default it is sent only when there is at least one new row; notifyWhenEmpty sends it every time.
Schedules. Create a schedule in Apify Console (hourly, daily, weekly or cron) with onlyNew on. A daily schedule gives you a feed of new job ads for the price of the new rows only.
Integrations. Send the results to Make, n8n, Zapier, Google Sheets, Slack, Google Drive, Airtable or any webhooks from the Integrations tab of the Actor, with no code. Apify also offers native actions for Make, n8n and Zapier.
API, SDKs and AI agents. Every run is available through the Apify API and the official JavaScript and Python clients; the Actor can also be called by AI agents through the Apify MCP server. The example input in the API tab is a working call.
Use cases
- Job boards and aggregators: a clean feed from the Recruitee companies you follow, with salaries where published.
- Salary research: published ranges by role, department and country across many companies.
- Monitoring: only new rows tell you when a company opens a matching role.
Ready-made examples, each with the input filled in (open one and press Start, or save it as your own task):
- Get jobs at Dutch companies hiring on Recruitee
- Get jobs at German, Austrian and Swiss companies on Recruitee
- Find remote jobs at companies hiring on Recruitee
What this actor does not do
- Search all of Recruitee by keyword: you bring company names or lists, and the filters apply to them.
- Read applications, candidates, recruiters or the application form.
- Read a job from a link on the company's own domain (
careers.example.com/o/…): use the company's recruitee.com name instead. Other systems' addresses are listed as invalid. - Report closed jobs: a job that disappears is simply missing from the next run.
Limits and fair use
- One request per second by default, 250 ms at the lowest. A company is one request whatever its number of jobs: bunq had 19 published jobs and channable 10 on 10 October 2026, two requests in all.
- Keyword, location, date and salary filters run on the list; only delivered jobs are charged.
- If the site shows an anti-bot page or asks for a long pause, the actor stops and keeps what it delivered (
stoppedByProtection,stoppedByRateLimitin the run summary).
Data source
Source: the Recruitee Careers Site API (<company>.recruitee.com/api/offers/), the public, keyless interface Recruitee documents for showing a company's published jobs on its own website (API reference). The careers domains answer robots.txt with Allow: /. No login or cookie. The job ads belong to the employers; each row links to the original. Rowcraft is not affiliated with Recruitee; the name belongs to its owner.
Privacy: no personal data
Rowcraft actors are built not to collect personal data:
- The API's job mailbox address, the application-form options and the screening questions are never mapped; applicants and recruiters are not part of the API.
- E-mail addresses, phone numbers,
mailto:,tel:and personal LinkedIn links in ad texts are removed; contact-person names after a title or contact cue ("Recruiter: …") become[name removed]. Other names cannot be told from ordinary words reliably.
You are responsible for using the data in line with the law that applies to you.
Other Rowcraft actors
All Rowcraft actors read official or public sources, deliver flat rows without personal data and support only-new runs and notifications:
- Ashby Jobs Scraper – Job Postings with Salary Ranges — Job postings from Ashby job boards (jobs.ashbyhq.com) by company: title, department, team, locations with country, employment and workplace type, published salary range, full text.
- Broken Link Checker – Find 404s and Dead Links API — Pay per crawled page, not per link: crawl a site within robots.txt and check every link on each page for 404s, 5xx errors, DNS and TLS failures and redirects.
- Career Site Jobs Scraper: Greenhouse, Lever, Ashby, Workday — Job listings from the career pages of the companies you choose on Greenhouse, Lever, Ashby, Workday, Workable, Personio, Recruitee, Teamtailor and Gem, in one run and one format: title, locations, department, salary when published, full text.
- Chrome Web Store Scraper: Users, Ratings & Versions — Reads public Chrome Web Store listing pages with no login, no proxy and no personal data: users, rating, category, version, update date, permissions and company developers.
- Domain Email and DNS Checker API: MX, SPF, DMARC, Providers — Find which email provider, sending services and DNS host each domain uses, from public DNS records only.
- SIRENE France Company Scraper: SIREN, NAF, Revenue, Status — French companies from the official Recherche d'entreprises API (INSEE SIRENE + INPI): SIREN and SIRET, legal form, NAF activity, head-office address, employee band, revenue and net income, labels, creation date and VAT number.
- Gem Jobs Scraper – Job Board Listings from jobs.gem.com — Job listings from Gem job boards (jobs.gem.com) by company: title, department, offices with country, employment type, remote, hybrid or on-site, requisition ID, publication date and full ad text, from the public Gem Job Board API.
- Google Play Apps Scraper: App Details, Installs, Ratings — Public Google Play app details as flat rows: installs, rating, number of ratings, price, version, last update, minimum Android, ads and in-app purchases.
- Greenhouse Jobs Scraper – Job Listings by Company Board — Job listings from Greenhouse job boards by company: title, departments, offices, publication date, full ad text, published pay ranges.
- Himalayas Jobs Scraper: Remote Jobs API with Salaries — Remote jobs from Himalayas through its public jobs API: title, company, salary range, seniority, categories, the countries and time zones open to candidates, full description and job link.
- KRS Poland Companies Scraper: Register Data, PKD, Status — Polish companies from the official KRS register API of the Ministry of Justice: name, KRS, NIP and REGON numbers, legal form, status, address, PKD activity codes, share capital, branches and registration dates.
- LEI Records Scraper: Legal Entity Identifier Lookup API — Legal Entity Identifier (LEI) records from the Global LEI Index, read through the public GLEIF API: legal name, legal form, register number, addresses, status, renewal date and parent companies.
- Lever Jobs Scraper – Job Postings from jobs.lever.co — Job postings from Lever career pages (jobs.lever.co) by company: title, team, department, location, commitment, workplace type, salary range when published, description, requirements and benefits.
- Norway Company Register Scraper: Brønnøysund Business Data — Norwegian companies from the Central Coordinating Register for Legal Entities (Brønnøysund, NLOD open data): organisation number, legal form, industry, employees, share capital, addresses, website, VAT and bankruptcy status.
- Personio Jobs Scraper: Job Listings, Salaries, Departments — Job ads from any company's Personio careers feed: title, department, office, employment type, schedule, seniority, salary when published, keywords and the full description in the language you choose.
- Platsbanken Scraper: Sweden Jobs, Employers, Org Numbers — Every job ad on Platsbanken (Arbetsförmedlingen) from the official JobTech API: headline, employer and organisation number, occupation codes, municipality, coordinates, salary type, deadline and full text.
- Robots.txt and AI Crawler Access Checker API — Check which AI and search crawlers a website lets in: GPTBot, ClaudeBot, PerplexityBot, Google-Extended and more, read from robots.txt by the RFC 9309 rules.
- RSS Feed Finder and Reader – Blog and News Article API — Find the RSS, Atom and JSON feeds of any website and read their newest articles, from a domain name alone.
- SEO Audit Tool: Titles, Meta Tags, Headings and Links API — Audit the on-page SEO of any list of pages or websites: titles, meta descriptions, headings, canonicals, indexing, links, images and structured data, with a score and the issues found per page.
- Shopify Products Scraper: Store Catalog Export to JSON, CSV — Products from any Shopify store's public catalog: title, vendor, type, tags, description, variants with price, compare-at price, SKU and stock, images, options, store currency.
- Sitemap URL Extractor: Every Page with Last-Modified Dates — Get every page a site lists in its sitemaps, with last-modified dates, from robots.txt through sitemap indexes and .gz files.
- SSL Certificate and Security Headers Checker API — Check the TLS certificate and the HTTP security headers of every domain in one run, with an A+ to F grade and the exact issues to fix.
- Store Products Scraper – Shopify, WooCommerce, VTEX — Export the product catalogue of any Shopify, WooCommerce or VTEX store from its public catalogue endpoint: title, brand, prices, discounts, stock, categories, images and links, one row per product, the same columns on every platform.
- Structured Data Extractor: JSON-LD, Schema.org, Open Graph — Pull the schema.org JSON-LD, Microdata, RDFa and Open Graph of any page list into flat rows: types, product price, availability, ratings, organization, breadcrumbs, with validation issues.
- Teamtailor Jobs Scraper – Career Site Jobs by Company — Job listings from Teamtailor career sites by company: title, department, role, locations with city and country, remote or hybrid status, publication date and full ad text, from the official job feed.
- TED Tenders Scraper: EU Public Procurement Notices API — EU public procurement notices from TED (Tenders Electronic Daily), the official EU tenders portal, through its public Search API: title, buyer, country, CPV codes, values, deadlines, lots and document links.
- UK Companies House Scraper: Company Search & Profiles API — UK companies from the official Companies House API with your free key: search by name, status, type, SIC code, date or location, or look up company numbers.
- UK Tenders Scraper: Find a Tender + Contracts Finder API — UK public procurement notices from Find a Tender and Contracts Finder, the official UK government portals, through their open OCDS APIs: title, buyer, region, CPV codes, values, deadlines, notice type and links.
- Bulk URL Status and Redirect Chain Checker API — Check the status code, redirect chain, canonical and indexing signals of every URL in a list, with the final destination and a loop flag.
- VTEX Products Scraper – Public Catalog Export — Export the catalogue of any VTEX store (Auchan, Chedraui and thousands of retailers in Europe and Latin America) from its public search endpoint: title, brand, EAN, prices, list prices, stock, categories, specifications and images, one row per product.
- Website Tech Stack Detector – Technology Lookup API — Find the technologies behind a list of websites: CMS, e-commerce platform, analytics, tag managers, ad pixels, consent tools, chat, CDN and payments, from one polite home-page request per domain.
- WooCommerce Products Scraper – Store API Export — Export every product of a WooCommerce store through its public Store API: title, SKU, prices and sale prices, stock, categories, tags, attributes, ratings, images and links, one row per product.
- Workable Jobs Scraper: Job Listings from Career Pages — Job listings from any company's Workable career page: title, department, location, remote or on-site, employment type, description, requirements, benefits and salary when published.
- Workday Jobs Scraper – Jobs from myworkdayjobs.com Sites — Job listings from Workday career sites (myworkdayjobs.com) by company: title, locations, country, posting date, time type, requisition ID and the full description.
FAQ
How do I find a company's name on Recruitee? Open its careers page: if the address is bunq.recruitee.com, the name is bunq. Many companies show the same jobs on their own domain (careers.bunq.com); the name still comes from the recruitee.com address, which the "powered by Recruitee" link or the apply page usually reveals. A job link on recruitee.com (<company>.recruitee.com/o/<job>) reads only that job.
Why is the salary empty on a job? The company did not publish one; Recruitee returns the salary only when the employer fills in the range. Only jobs with a published salary keeps just the jobs that have one. A range of 0 to 0 is treated as not published.
Are the requirements separate from the description? Yes. Recruitee keeps two texts, and the actor delivers both as plain text (descriptionText, requirementsText) and optionally as HTML.
How do I get only new jobs on a schedule? Turn on onlyNew, give each schedule its own stateName and add a schedule in Apify Console. The actor remembers every job id, so an edited ad is not delivered or charged again.
How fast is it, and are there limits? One request per company and one request per second, no proxies; a hundred companies take under two minutes.
Can I read many companies without typing them? Yes. Pick one or more Ready-made company lists in the input form (Europe, the Netherlands, remote jobs, every Recruitee company we know…) and the actor reads the Recruitee companies in them. The lists hold companies we found on the public Careers Site API, named as on their own career site; sizes are shown in the form.
What happens when a company name is wrong? The COVERAGE record and the run summary give each company a status: ok, empty (no published jobs, or the job of a job link has closed: its id is listed in missingJobLinks), not_found, failed (with the reason) or not_reached (the run stopped before it). A company that left Recruitee answers not_found.
What are remote, hybrid and on-site? Recruitee lets the company flag each job; the actor delivers the flag as workplaceType and isRemote, and remoteOnly keeps remote jobs. A job without a flag has workplaceType empty.
How much does it cost? $1.50 per 1,000 job ads on the Free plan, less on paid plans (see Pricing). You pay only for rows delivered to your dataset; set a maximum total charge in the run options to cap a run.
How do I get the results into Slack, Google Sheets, Make, n8n or Zapier? Use the Integrations tab of the Actor for the data, and the notifyUrl field for a message when a run ends (Slack and Discord webhooks work directly; catch hooks of Make, n8n and Zapier too).
Can I call it from code or from an AI agent? Yes: through the Apify API, the JavaScript and Python clients, and the Apify MCP server. The API tab shows a working example with the input of this Actor.
Is it legal to use this data? The actor reads the official API described in the Data source section and delivers company and job data without personal data. The licence of the source is described above. How you use the data is your responsibility under the law that applies to you.
Does it collect personal data? No. Contact persons, e-mails and phone numbers are removed and fields about people are never requested. See the Privacy section.
The run finished with 0 rows. Did I pay? No: with no rows delivered nothing is charged apart from the start event. Check the run summary (RUN_SUMMARY) for warnings, widen the filters, or run with Only new rows off if everything matching was already delivered to you.
Support and reviews
Problems, missing fields, questions: open an issue on the Issues tab of this Actor. We answer within one working day and fix confirmed bugs in the next release; the changelog lists every change.
If this Actor saved you time, a short review on its page helps other users find it and helps us keep improving it.


