
Career Site Jobs Scraper: Greenhouse, Lever, Ashby, Workday
Pricing
from $2.00 / 1,000 job ads
Career Site Jobs Scraper: Greenhouse, Lever, Ashby, Workday
Jobs from the career pages of the companies you choose: give a name or website and the actor finds the system (Greenhouse, Lever, Ashby, Workday, Workable, Personio, Recruitee, Teamtailor, Gem). One format: title, locations, department, salary when published, full text. No personal data.
Pricing
from $2.00 / 1,000 job ads
Rating
0.0
(0)
Developer
Rowcraft
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Security
Limited permissionsShare
Career Site Jobs Scraper: Greenhouse, Lever, Ashby, Workday and More
Get open jobs from the career pages of the companies you choose, on nine systems in one run: Greenhouse, Lever, Ashby, Workday, Workable, Personio, Recruitee, Teamtailor and Gem. This career site jobs scraper reads each system's public job API, the data the careers page itself loads, so it is fast and does not break when a page design changes. Every job comes back in one flat row shape as JSON, CSV or Excel.
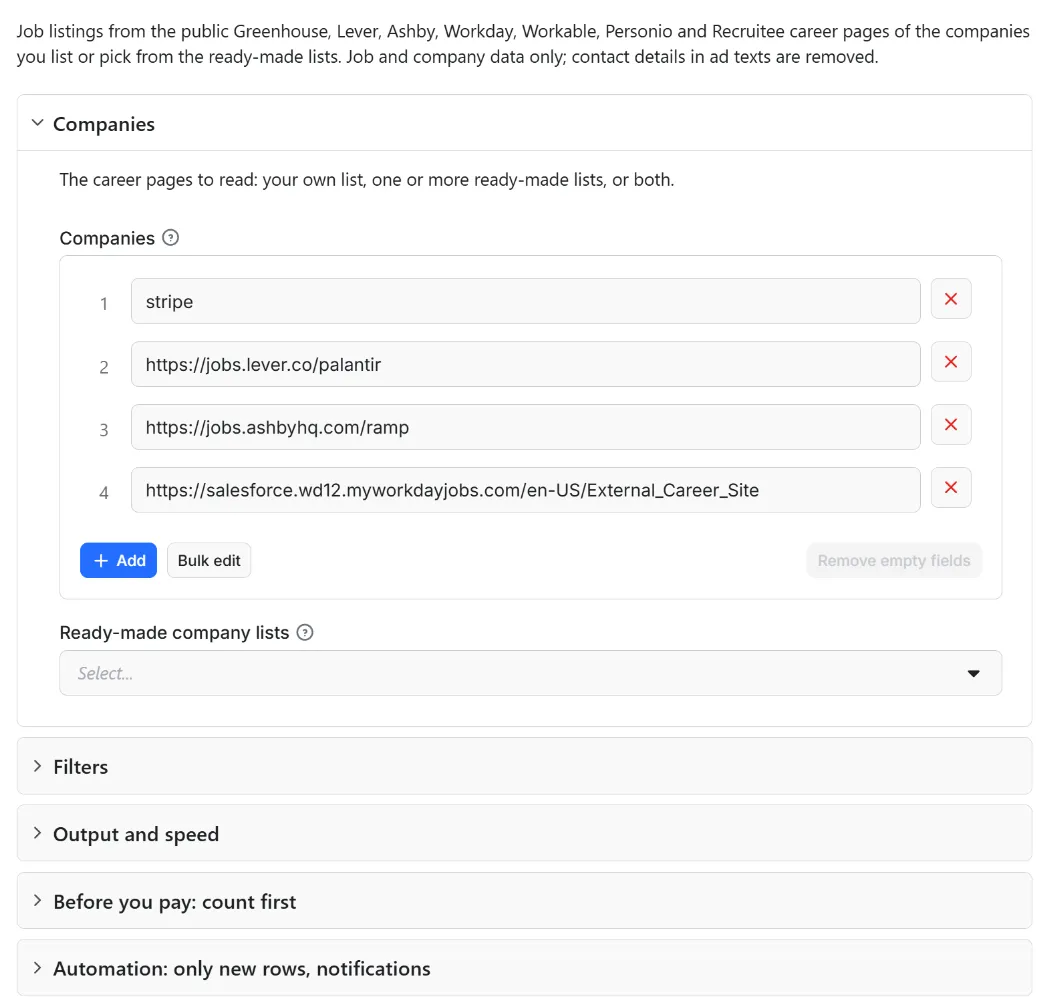
Type company names, company websites (notion.so) or career-page addresses, or pick a ready-made company list, filter the jobs and schedule the run to get only new ones. You do not need to know which system a company uses: the actor finds it.
What you get
Price: $3.00 per 1,000 job ads on the Free plan, $2.00 on the Business plan, paid per row delivered; the $5 monthly credit of a free Apify account covers about 1,600 job ads. Details in Pricing below.
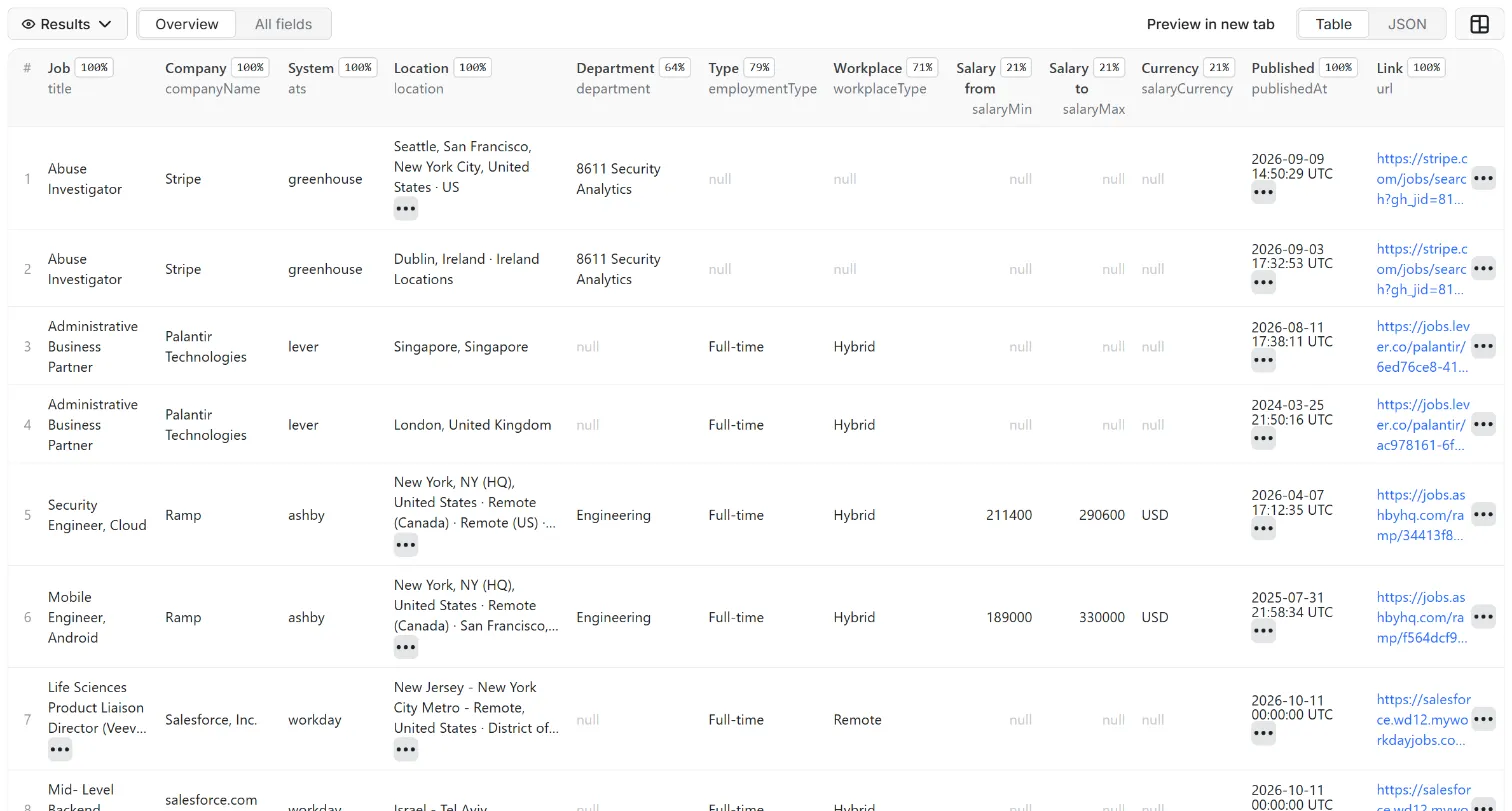
One row per job, the same columns for every system:
- Job:
id(system:company:jobId), title, company name, job and apply page, requisition code - Place: all locations, plus country, ISO country code, region and city of the first one
- Classification: department, team, employment type (Full-time, Part-time, Contract, Internship, Temporary, Apprenticeship), workplace type (Remote, Hybrid, On-site)
- Salary: minimum, maximum, currency, period and text, only when the employer publishes a range
- Texts and dates: published and updated dates, description as plain text, requirements and benefits separately where the employer does
Why this actor
- One shape for nine systems: the same columns, employment and workplace values and ISO country codes.
- Ready-made company lists by country (Europe first), remote jobs and industry, refreshed with every release.
- Count before you pay: Count only shows how many jobs match and what they would be charged; nothing is delivered.
- Contact details removed, a report per company and a charge cap: you pay per delivered job ad.
How to use it
- Open the Actor and fill in Companies (the other fields are optional filters).
- Set Maximum job ads to a small number for a first try (the default is a safe start).
- Optional: tick Count only and start once. You get the number of matching rows and the estimated cost, for free (only the start event is charged). Untick it to get the data.
- Click Start. The status line shows progress; the run stops cleanly at your limit or at the charge limit you set in the run options.
- Open the Dataset tab and download JSON, CSV, Excel, XML or HTML, or send the rows to Google Sheets, Slack, Make, n8n or Zapier with the Integrations tab.
- To run it on a schedule, use Schedules in Apify Console and turn on Only new rows since the last run below: every run then costs only the new rows, and a webhook URL tells you when something new came in.
Input
Quick start. This input is ready to run (it is also the example in the API tab):
One real row it returns (long texts shortened here):
| Field | What it does |
|---|---|
companies, lists | Names, addresses or job links, one per line; ready-made lists picked in the form |
keywords | Match the job title; keywordsInDescription also searches the ad text |
locations | Countries, codes, regions or cities; add remote to keep remote jobs |
departments, employmentTypes, remoteOnly, withSalaryOnly, postedAfter | More filters (postedAfter: 2026-10-01, yesterday, 7 days) |
includeDetails, includeHtml, maxItems, maxItemsPerCompany | Details (default on), HTML texts, limits (0 = none) |
countOnly, onlyNew, stateName, notifyUrl, notifyWhenEmpty | Count only (deliver nothing); see Automation below |
Company references: a name (stripe, or as written: Hugging Face, Stripe, Inc.), the company's own website (notion.so, https://www.figma.com/careers), a career-page address (https://jobs.lever.co/palantir, bunq.recruitee.com, deezer.teamtailor.com, https://jobs.gem.com/linktree) or, for Workday, the full site address.
- Website: the actor reads up to four public pages of the site (the address you gave, the home page, then the career pages it links to) and follows the link to the career system it finds there. Each page is read only if the site's robots.txt allows it; a site behind an anti-bot page is skipped, never worked around, and the name is tried instead.
- Name: tried on every system except Workday, first as one word (
huggingface), then with hyphens (hugging-face); legal suffixes such as Inc., Ltd or GmbH are dropped. The first board that answers is used. - The
COVERAGErecord says how each company was found (matchedBy:websiteorname) and, for a website, the page the link was on (detectedFrom). Two inputs that lead to the same board, such asstripeandstripe.com, are read once.
Example: engineering jobs in Germany or remote, from four systems, posted in the last two weeks.
Output
37 fields per row. Empty values are null, never missing, so CSV and Excel columns are stable.
| Field | Type | Example |
|---|---|---|
id | string | greenhouse:stripe:8172510 |
jobId | string | 8172510 |
ats | string | greenhouse |
company | string | stripe |
companyName | string | Stripe |
title | string | Abuse Investigator |
url | string | Job page |
applyUrl | string | Apply page |
requisitionCode | string | Requisition code |
department | string | Department (first) |
departments | array | All departments |
team | string | Team or function |
employmentType | string | Full-time |
workplaceType | string | Workplace type: Remote, Hybrid, On-site, or as written |
isRemote | boolean | False |
location | string | Dublin · Ireland |
locations | array | Locations: raw text, country, countryCode (ISO 3166-1), region, city |
country | string | Ireland |
countryCode | string | IE |
region | string | Region or state of the first location |
city | string | Dublin |
publishedAt | string | 2026-09-03T17:30:34.000Z |
updatedAt | string | Last update (when the system publishes it) |
language | string | en |
salaryMin | number | Salary from (when the employer publishes it) |
salaryMax | number | Salary to |
salaryCurrency | string | Salary currency (ISO 4217) |
salaryPeriod | string | Salary period: year, month, week, day, hour |
salaryText | string | Salary as the employer wrote it |
descriptionText | string | Full ad text as plain text, contact details removed |
requirementsText | string | Requirements as a separate text (Lever, Workable, Recruitee, Personio, when the employer separates them) |
benefitsText | string | Benefits as a separate text (Lever, Workable, Personio, when separated) |
descriptionHtml | string | HTML version of the description (only with "Include HTML") |
requirementsHtml | string | HTML version of the requirements (only with "Include HTML") |
benefitsHtml | string | HTML version of the benefits (only with "Include HTML") |
metadata | object | Other fields the employer set: custom fields, level, category, experience, hours per week, keywords |
detailsIncluded | boolean | False |
Example rows
Two real rows from a run (long texts shortened here, complete in the dataset):
Results can be downloaded as JSON, CSV, Excel, XML or HTML from the Dataset tab, or read through the Apify API.
Pricing
Pay per result. You pay for each job ad delivered to your dataset, nothing else: no subscription, no minimum, no charge for rows your filters drop or for the requests behind them.
| Your Apify plan | Price per 1,000 rows | Price per row |
|---|---|---|
| Free plan | $3.00 | $0.003 |
| Starter plan | $2.67 | $0.00267 |
| Scale plan | $2.33 | $0.00233 |
| Business plan and above | $2.00 | $0.002 |
Example: 1,000 job ads cost $3.00 on the Free plan and $2.00 on the Business plan. Platform usage of the run (compute, storage) is included in that price and is not billed to you separately (pay per event: the actor covers it).
A start event of $0.00005 is charged once per run (Apify default).
Cap your spend: set Maximum total charge in the run options. The actor stops cleanly when the cap is reached and you keep everything delivered until then. The run summary (RUN_SUMMARY in the key-value store) says why a run stopped.
Check before you pay: turn on Count only to see how many rows match and what they would cost at your tier. That run delivers nothing and costs only the start event.
Automation: only new rows, notifications, schedules
Only new rows since the last run. Turn on onlyNew and the actor remembers every job ad it delivered to you (in a key-value store named rowcraft-career-site-jobs-scraper-state in your Apify account). The next run with the same stateName skips what you already have and you pay only for new rows. The first run delivers everything that matches. Use a different stateName for each schedule or search so they keep separate memories.
Notification when the run ends. Put a webhook address in notifyUrl and the actor sends one JSON POST with the number of new rows, links to the dataset (JSON and CSV) and the run. It works out of the box with Slack and Discord incoming webhooks (the message is in text and content), with Make, n8n and Zapier catch hooks, and with your own endpoint. By default it is sent only when there is at least one new row; notifyWhenEmpty sends it every time.
Schedules. Create a schedule in Apify Console (hourly, daily, weekly or cron) with onlyNew on. A daily schedule gives you a feed of new job ads for the price of the new rows only.
Integrations. Send the results to Make, n8n, Zapier, Google Sheets, Slack, Google Drive, Airtable or any webhooks from the Integrations tab of the Actor, with no code. Apify also offers native actions for Make, n8n and Zapier.
API, SDKs and AI agents. Every run is available through the Apify API and the official JavaScript and Python clients; the Actor can also be called by AI agents through the Apify MCP server. The example input in the API tab is a working call.
Count only. countOnly returns the number of matching job ads and the estimated cost without delivering anything, so you can size a job before paying for it.
Use with AI agents (MCP). Add the Apify MCP server to Claude, Cursor, VS Code or any MCP client and the agent can run this Actor as a tool:
Call it from a shell or any language. One request runs the Actor with the input below and returns the rows as JSON:
Python (pip install apify-client):
JavaScript / Node.js (npm install apify-client):
Use cases
- Job boards and aggregators: one feed from every company you follow.
- Recruiting and sales intelligence: who is hiring, for which roles, where.
- Monitoring: only new rows tell you when a competitor opens a role.
Ready-made examples, each with the input filled in (open one and press Start, or save it as your own task):
- Find remote software engineering jobs at tech companies
- Get jobs in Romania from company career sites
- Track new jobs posted in Europe in the last 24 hours
What this actor does not do
- Search all career sites by keyword: you bring companies or lists, and the filters apply to them.
- Find a Workday site from a company name.
- Read applications, candidates or recruiter contacts, log in, use proxies or solve CAPTCHAs.
- Report closed jobs: a job that disappears is simply missing from the next run.
Limits and fair use
- One request per second by default, 250 ms at the lowest. Lever, Ashby, Recruitee, Personio, Teamtailor and Gem need about one request per company (Teamtailor one per 100 jobs); Greenhouse, Workday and Workable add one per job with details on. Stripe's Greenhouse board had 729 jobs on 10 October 2026 (about 12 minutes); Salesforce's Workday site had 1,537 (about 27 minutes, under two without details).
- Keyword, location and date filters run before the detail requests; only delivered jobs are charged.
- Workday sites are read up to 5,000 jobs per run.
- If a site shows an anti-bot page or asks for a long pause, the actor stops and keeps what it delivered (
stoppedByProtection,stoppedByRateLimitin the run summary).
Data source
Each system is read through the public interface it offers for showing a company's jobs, or the one its career page calls. No login, key or cookie, and no path that a robots.txt excludes. Each row links to the original ad. Rowcraft is not affiliated with Greenhouse, Lever, Ashby, Workday, Workable, Personio, Recruitee, Teamtailor or Gem; the names belong to their owners.
Privacy: no personal data
Rowcraft actors are built not to collect personal data:
- Only job and company fields are read; recruiter, hiring-manager and candidate fields never are.
- E-mail addresses, phone numbers,
mailto:,tel:and personal LinkedIn links in ad texts are removed; contact-person names after a title or contact cue ("Recruiter: …") become[name removed]. Other names cannot be told from ordinary words reliably.
You are responsible for using the data in line with the law that applies to you.
Other Rowcraft actors
Related Rowcraft actors. All of them read official or public sources, deliver flat rows without private contact details and support only-new runs and notifications; the full list is on the Rowcraft profile:
- Ashby Jobs Scraper – Job Postings with Salary Ranges — Job postings from Ashby job boards (jobs.ashbyhq.com) by company: title, department, team, locations with country, employment and workplace type, published salary range, full text.
- Gem Jobs Scraper – Job Board Listings from jobs.gem.com — Job listings from Gem job boards (jobs.gem.com) by company: title, department, offices with country, employment type, remote, hybrid or on-site, requisition ID, publication date and full ad text, from the public Gem Job Board API.
- Greenhouse Jobs Scraper by Company — Job listings from Greenhouse job boards by company: title, departments, offices, publication date, full ad text, published pay ranges.
- Himalayas Jobs Scraper: Remote Jobs API with Salaries — Remote jobs from Himalayas through its public jobs API: title, company, salary range, seniority, categories, the countries and time zones open to candidates, full description and job link.
- Lever Jobs Scraper for Any Company — Job postings from Lever career pages (jobs.lever.co) by company: title, team, department, location, commitment, workplace type, salary range when published, description, requirements and benefits.
- Personio Jobs Scraper: Job Listings, Salaries, Departments — Job ads from any company's Personio careers feed: title, department, office, employment type, schedule, seniority, salary when published, keywords and the full description in the language you choose.
FAQ
Can I just give the company's website? Yes: notion.so or https://www.figma.com/careers works. The actor reads a few public pages of the site, finds the link to Greenhouse, Lever, Ashby, Workday, Workable, Personio, Recruitee, Teamtailor or Gem and reads that board. When the site has its own job pages with no such link, or blocks automated visits, it tries the company name instead, and the COVERAGE note says so: check that the company name in the rows is the one you meant.
How do I find a company's reference? Usually you do not need to: give the name or the website. To pin a board, open the careers page and copy the address of the page that lists its jobs. A job link on the system's own domain, such as jobs.lever.co/<company>/<id>, reads only that job (a Workday job link with one request instead of the whole list). A job page on a company's own domain, for example a stripe.com page, cannot be read from its link: use the company's name on its system.
Why does Workday need the site address? A site is identified by tenant, data center (wd1 to wd12) and site name, which a company name does not hold. Copy the address of the career page; en-US and anything after the site name are ignored. A bare name is listed as invalid.
Which companies are in the lists? Companies we checked on the public APIs of Greenhouse, Lever, Ashby, Personio and Recruitee, each with open jobs and named after their own career page. Sizes are shown in the form. Add locations to keep one country; add Workday, Workable, Teamtailor and Gem companies yourself.
What does Count only do? It reads the same pages and writes the number of matching jobs, and what delivering them would be charged, into the run summary. Switch details off for a fast count.
Does it return salaries? When the employer publishes a range: salaryMin, salaryMax, salaryCurrency, salaryPeriod, salaryText. Greenhouse and Workable need details on; Workday, Teamtailor and Gem have no pay fields.
How do I get only new jobs on a schedule? Turn on onlyNew, give each schedule its own stateName and add a schedule in Apify Console. The actor remembers every job id, so an edited ad is not delivered or charged again.
How fast is it, and are there limits? One request per second, no proxies; see Limits. Boards without detail requests take seconds.
What happens when a company name is wrong? The COVERAGE record and the run summary give each company a status: ok, empty (no open jobs, or the job of a job link has closed: its id is listed in missingJobLinks), not_found (with the board names tried and, for a website, why it gave no link), duplicate (same board as an earlier input), failed (with the reason) or not_reached (the run stopped before it). A company that moved to another system often leaves an empty board behind.
How much does it cost? $3.00 per 1,000 job ads on the Free plan, less on paid plans (see Pricing). You pay only for rows delivered to your dataset; set a maximum total charge in the run options to cap a run.
How do I get the results into Slack, Google Sheets, Make, n8n or Zapier? Use the Integrations tab of the Actor for the data, and the notifyUrl field for a message when a run ends (Slack and Discord webhooks work directly; catch hooks of Make, n8n and Zapier too).
Can I call it from code or from an AI agent? Yes: through the Apify API, the JavaScript and Python clients, and the Apify MCP server. The API tab shows a working example with the input of this Actor.
Is it legal to use this data? The actor reads the official API described in the Data source section and delivers company and job data without personal data. The licence of the source is described above. How you use the data is your responsibility under the law that applies to you.
Does it collect personal data? No. Contact persons, e-mails and phone numbers are removed and fields about people are never requested. See the Privacy section.
The run finished with 0 rows. Did I pay? No: with no rows delivered nothing is charged apart from the start event. Check the run summary (RUN_SUMMARY) for warnings, widen the filters, or run with Only new rows off if everything matching was already delivered to you.
Support and reviews
Problems, missing fields, questions: open an issue on the Issues tab of this Actor. We answer within one working day and fix confirmed bugs in the next release; the changelog lists every change.
If this Actor saved you time, a short review on its page helps other users find it and helps us keep improving it.


