
Taobao Scraper | Products, Prices and Sellers
Pricing
from $3.82 / 1,000 products
Taobao Scraper | Products, Prices and Sellers
Taobao scraper for Taobao and Tmall: get best-selling products by keyword or product link with price, original price, shop, seller credit level and service scores, shipping location, images and the latest buyer review. No login needed. Export JSON, CSV or Excel for sourcing and price tracking.
Pricing
from $3.82 / 1,000 products
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
Taobao 淘宝 Scraper
Turn Taobao and Tmall into a table: the best-selling products of any keyword, or any product you paste, with price, shop, seller scores, shipping location and the latest buyer review on every row. 40 fully detailed products in under 30 seconds, no Taobao account needed.
How it works
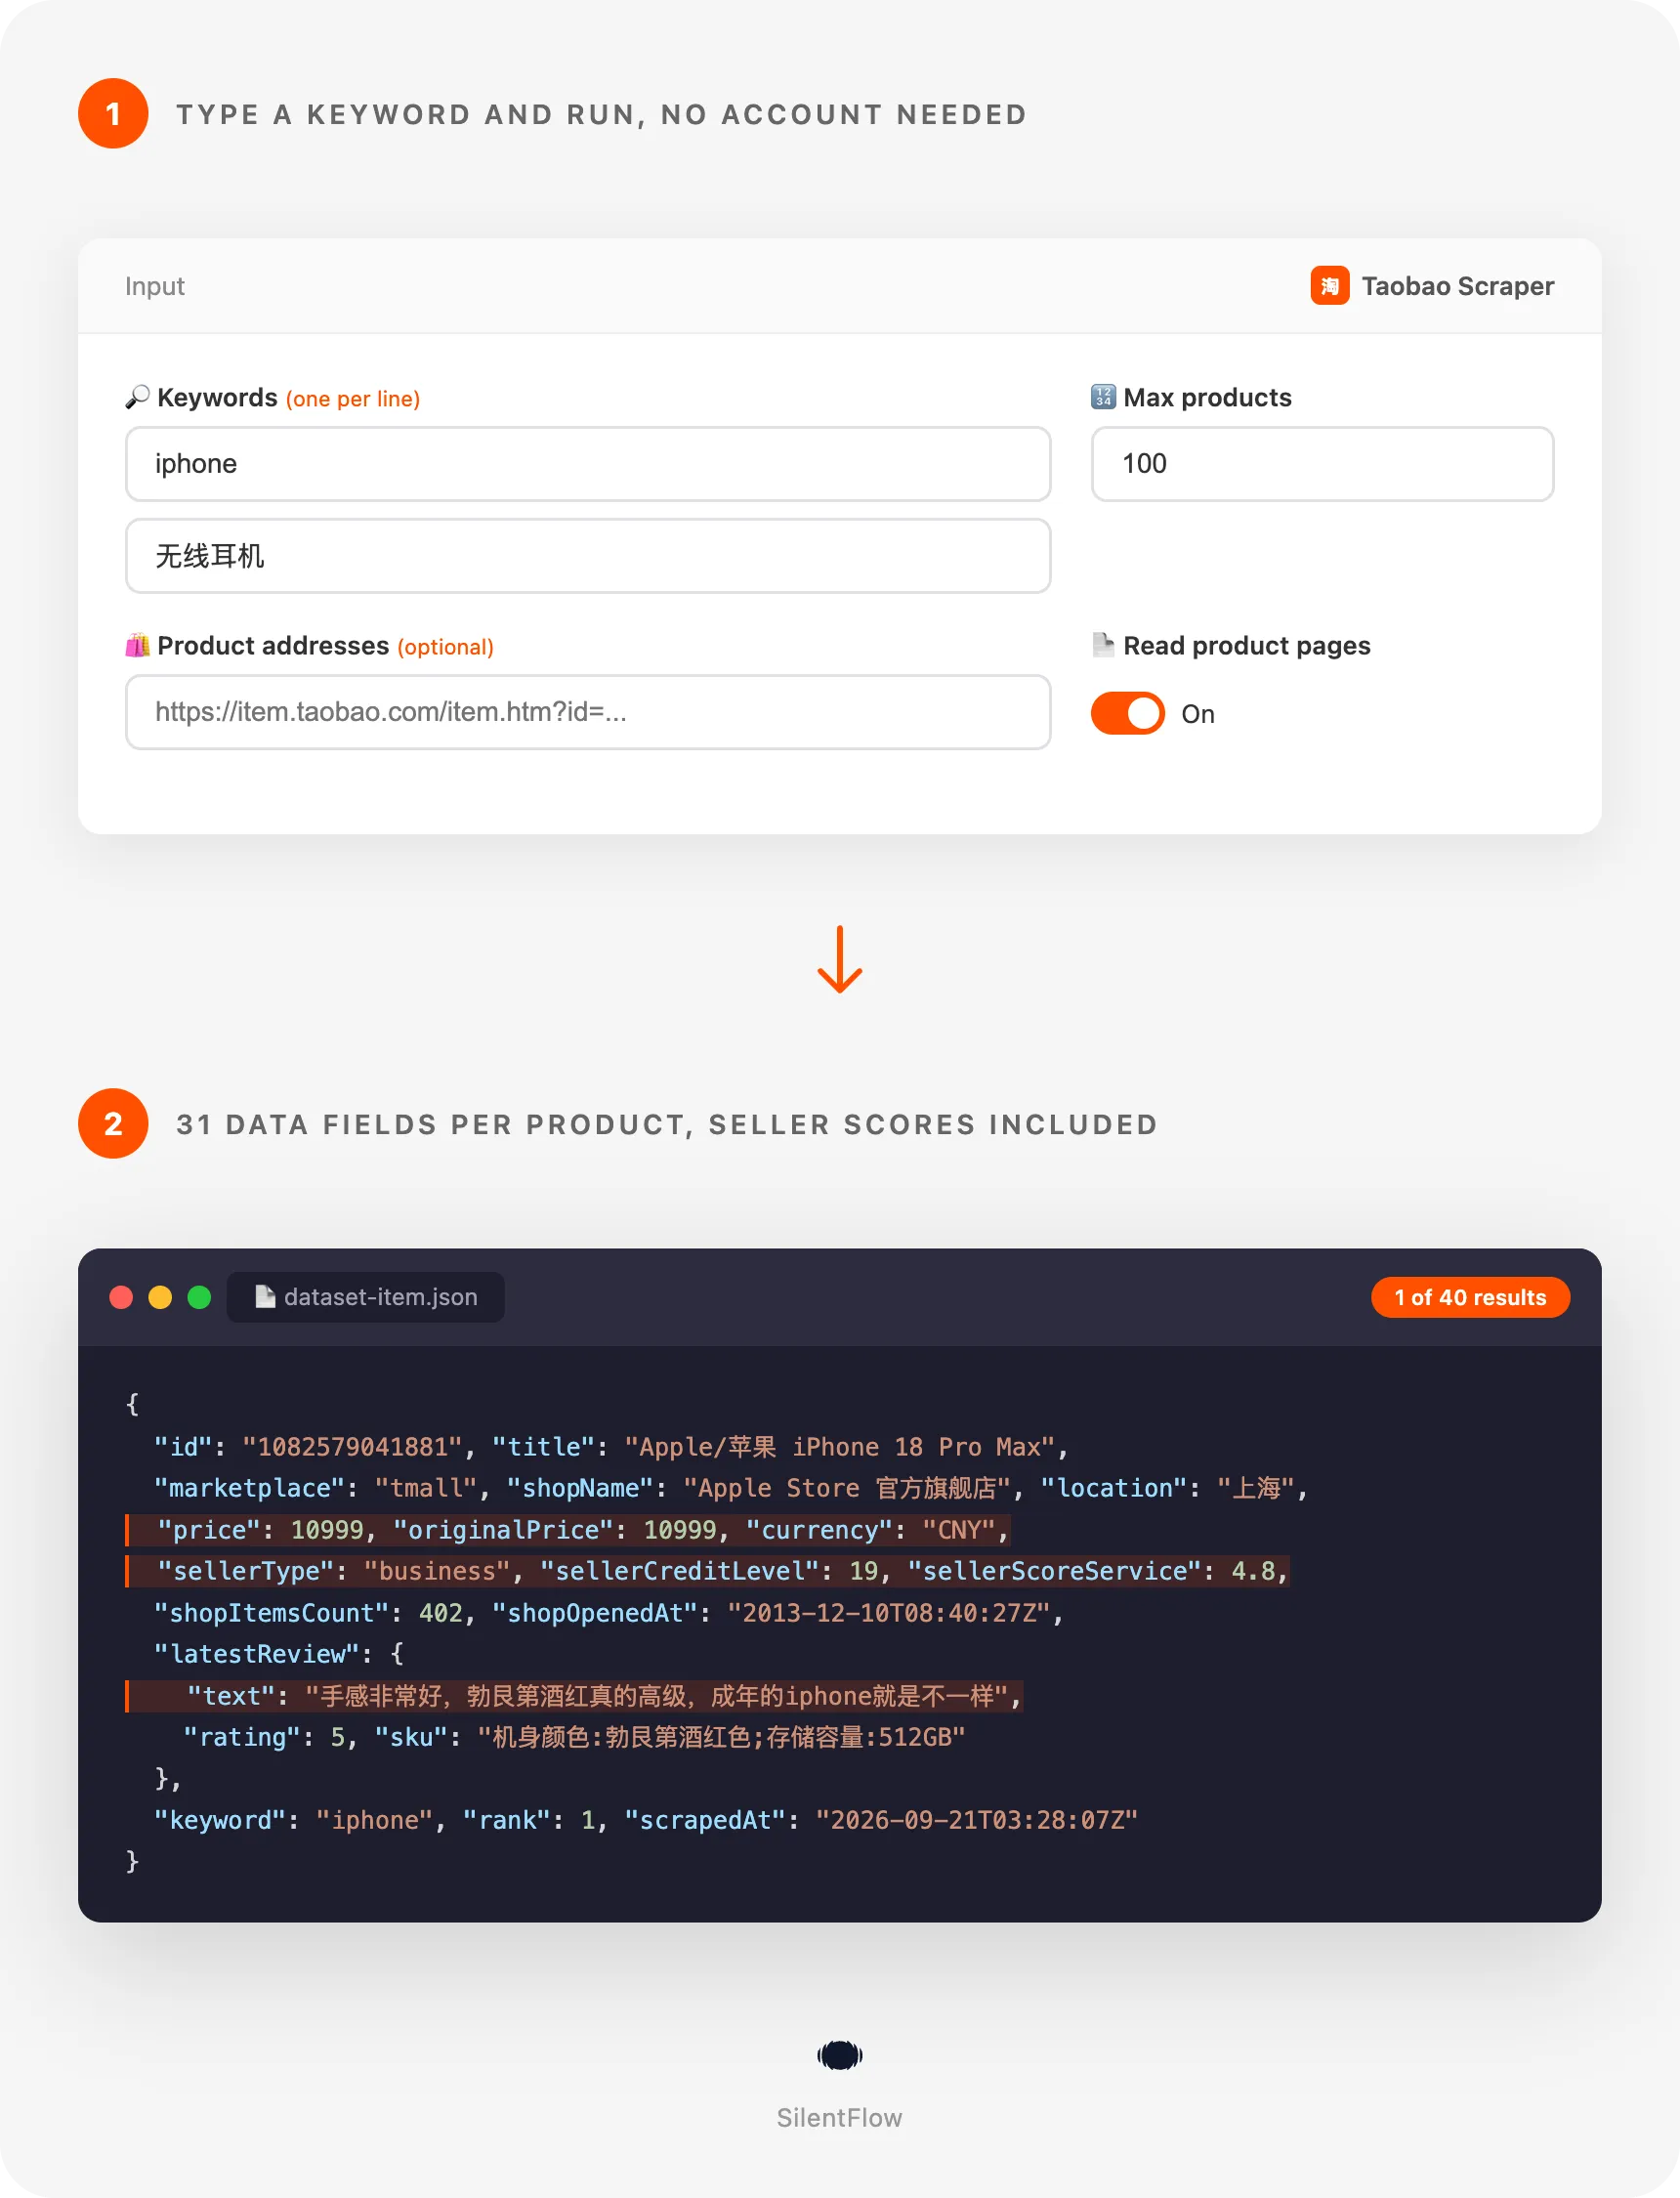
- You type keywords or paste product addresses. Chinese keywords match best (
无线耳机,机械键盘), brand names work in English (iphone,nike). Product addresses from item.taobao.com, detail.tmall.com or a bare item id go in a second field. - Each keyword returns its 20 best sellers. The same products a shopper on Taobao sees first, with the product page of each one read for the seller, the location and the reviews.
- One row comes back per product. 31 fields: identity, price and original price in yuan, shop and seller with credit level and three service scores, category, shipping location, images, the latest review with its rating and SKU, the keyword and the rank. Ready for a spreadsheet, a database or an AI pipeline.
✨ Why teams choose this over other Taobao scrapers
Copying prices from Taobao tabs into a spreadsheet? Running a scraper that asks for your account before it shows a single product? Getting seller data as "300+" strings you cannot sort?
- 🔓 No account, no login, no API key. Type a keyword and run. The scraper reads the public pages Taobao publishes to search engines, so there is nothing to log into and nothing to renew.
- 🏆 Best sellers, not random hits. A keyword returns the 20 products Taobao ranks first by sales, the ones that actually move. Two keywords give you a market snapshot in one run.
- 🏪 Seller scores on every row. Credit level, description, service and logistics scores, item count and the year the shop opened, plus whether the seller is a business (Tmall) or an individual (Taobao). Other scrapers make you run a second operation for this.
- 💬 The latest review, with rating and SKU. See what the last buyer said, which variant they bought and when, next to the price. Individual sellers also come with good and bad review counts and the positive rate.
- 🔢 Numbers you can sort. Prices are numbers in yuan with the currency in its own field, review counts are integers, dates are RFC 3339 in UTC, ids are stable strings. No
"1.5万+"to clean. - ⚡ Fast and predictable. 40 detailed products in 26 seconds, 45 listing rows in 8 seconds. One keyword costs one page, one product one page, so you know the size of a run before you start it.
🎯 What you can do with Taobao data
| Team | What they build |
|---|---|
| Sourcing | Compare the 20 best-selling suppliers of a product with their credit level, service scores and shipping province before contacting any of them |
| Pricing | Track the price and original price of competing listings every morning and alert on drops of more than 10 percent |
| Cross-border sellers | Spot which products a Chinese keyword sells most and at what price before listing them on Amazon, Shopee or Lazada |
| Market research | Map a category by shop type, location and price band across dozens of keywords in one run |
| Brand protection | Find who sells your brand on Taobao and Tmall, at what price, with which seller scores, and keep the list current |
| Purchasing agents | Give clients a live table of best sellers with images, prices and shop names instead of screenshots |
| Data and AI | Feed product rows with the latest review and SKU into an LLM to summarise what buyers praise or complain about |
📥 Input parameters
| Field | Type | Default | Description |
|---|---|---|---|
keywords | array | ["iphone", "无线耳机"] | What to search, one keyword per line. Each keyword returns its 20 best-selling products. |
productUrls | array | Single products to read: a product address (https://item.taobao.com/item.htm?id=1082579041881, https://detail.tmall.com/item.htm?id=...) or a numeric item id. | |
maxItems | integer | 100 | How many rows to save for the whole run. Products read by address count too. |
includeDetails | boolean | true | Read the product page of every product for the marketplace, seller scores, location, original price and latest review. Turn off for a faster listing. |
debugMode | boolean | false | Adds detailed lines to the run log. |
Keywords and product addresses can be combined in one run. A product already returned by a keyword is not read twice.
📊 Output data
One row per product. A row found by keyword:
A row read by product address, from an individual seller on Taobao:
Facts worth knowing before you build on the output:
idandurlare permanent. The product address opens the full product page on Taobao or Tmall.titleis the full listing title for rows found by keyword. For rows read by address, Taobao's product page shortens the title to about ten characters (富士二手拍立得min...), and that short title is what the row carries.priceis the current price in yuan;originalPriceis the price before promotion when the page shows one. A product with several variants shows the price of the default one.reviewsGoodCount,reviewsBadCountandreviewsGoodPercentare given by the pages of individual sellers (Taobao). Tmall product pages do not show them, so they arenullthere. Counts are lower bounds: Taobao writes700+and1万+, saved as700and10000.- Image URLs point to Taobao's image CDN and stay valid for months.
- All dates are RFC 3339 in UTC. Taobao writes them in Beijing time; the conversion is done for you.
- A field the source does not give is
null, never an empty string.
🗂️ Data fields
31 fields per product, plus 5 inside latestReview.
| Group | Fields |
|---|---|
| Identity | id, url, title |
| Content | marketplace (tmall or taobao), categoryId, categoryPath, isFreeShipping |
| Seller | shopId, shopName, shopUrl, sellerId, sellerType (business or individual), sellerCreditLevel, sellerScoreDescription, sellerScoreService, sellerScoreLogistics, shopItemsCount, shopOpenedAt |
| Measures | price, originalPrice, currency, reviewsGoodCount, reviewsBadCount, reviewsGoodPercent |
| Latest review | latestReview.text, latestReview.rating (1 to 5), latestReview.sku, latestReview.publishedAt, latestReview.images |
| Place | location (province or city the product ships from) |
| Media | imageUrl, images |
| Meta | keyword, rank (position in the keyword's best sellers, 1 to 20), scrapedAt |
With includeDetails off, the row keeps id, url, title, categoryId, isFreeShipping, shopId, shopName, price, originalPrice, currency, imageUrl, images, keyword, rank and scrapedAt; the other fields are null.
🚀 Examples
Get the best-selling wireless earbuds
Compare iPhone listings across three generations
Read the products you already track, by address
Build a fast price list without product pages
Map a whole category in one run
Mix a keyword and a watch list
🤖 Copy to your AI assistant
Paste this block into Claude, ChatGPT or Cursor to give it full context about this scraper:
💻 Integrations
Build a supplier shortlist ranked by seller scores
Alert on price drops for a watch list
Export the best sellers of a category to CSV
📈 Performance
| Run | Rows | Time |
|---|---|---|
| Two keywords with product pages (the default input) | 40 | 26 s |
| Three keywords, listing only | 45 | 8 s |
| Three product addresses | 3 | 11 s |
| Eight keywords with product pages | 160 | about 2 min |
A keyword costs one page read; a product page costs one more, read four at a time. Rows are saved keyword by keyword, so a run you stop early keeps what it has read.
💾 Data export
Results are available on the run's dataset page as JSON, CSV, Excel, XML, RSS and HTML table. The Products view shows title, price, shop, location, marketplace, keyword and URL; the Sellers view shows the seller columns.
Pull them programmatically:
💡 Tips for best results
- Search in Chinese.
无线耳机returns earbuds;wireless earbudsreturns what Taobao matches to those Latin words, which is often less relevant. Brand names (iphone,nike,sony) work as they are. - Use several keywords to widen a market. Each keyword gives its own 20 best sellers.
iphone 15,iphone 16andiphone 16 proreturn three different top-20 lists, not the same one three times. - Turn
includeDetailsoff for pure price lists. The listing alone gives title, price, shop and image in a fifth of the time. Switch it on when you need the seller scores, the location or the latest review. - Filter on
sellerTypeand the scores.businessis a Tmall flagship or brand store;individualis a Taobao C2C shop. A service score of 4.8 or above with hundreds of items is a reliable supplier signal. - Watch products by address for daily tracking. Paste the
urlvalues of the rows you care about intoproductUrlsand schedule the run. Each address costs one page and returns the current price, original price and latest review.
❓ FAQ
What does this scraper extract? Products from Taobao and Tmall: title, price and original price in yuan, shop and seller with credit level and service scores, category, shipping location, images and the latest buyer review. Rows come from keyword searches or from product addresses you paste.
Do I need a Taobao account? No. The scraper reads the public product pages Taobao publishes to search engines. No login, no account, no API key.
How many products does a keyword return? 20, the best sellers Taobao ranks first for that keyword. Taobao shows this public listing on one page only; use several keywords to cover a market, and product addresses to read specific items beyond the top 20.
Can I sort or filter by price?
Not on Taobao's side: the public listing is fixed to the best-selling order. Filter the rows after the run on price, sellerType, location or the scores; every one of them is a sortable number or a plain string.
Why is the title short on rows read by address?
Taobao's product page cuts the title to about ten characters (富士二手拍立得min...) and shows the full one only in the keyword listing. A product found by keyword keeps its full title; a product read by address carries the short one.
Why are the review counts null on some rows? Product pages of individual sellers (Taobao) show good and bad review counts and the positive rate. Product pages of business sellers (Tmall) show only the latest review. The latest review is on both.
How fresh is the data?
Live. Every run reads Taobao at that moment; nothing is cached. The scrapedAt field on each row says exactly when.
Can I scrape several keywords and addresses in one run?
Yes. Keywords are read first, then addresses. A product that appears twice is saved once, and maxItems caps the whole run.
What is the difference between Taobao and Tmall?
Both belong to Alibaba and share the same search. Tmall hosts brand and business stores (marketplace: "tmall", sellerType: "business"); Taobao hosts individual and small sellers (marketplace: "taobao", sellerType: "individual"). The scraper returns both and tells you which is which.
Are image and product URLs permanent? Product URLs are permanent. Image URLs point to Taobao's image CDN and stay valid for months. Shop URLs open the seller's mobile storefront.
Does it read variants, stock or the description? No. The public page shows the default variant's price, the seller, the location and the latest review, and that is what the row carries. Variant tables and stock are not part of the public page.
What happens when a product address is wrong? The product is skipped with a note in the log and the run continues. A run that finds nothing says why on its status: product not found, invalid input or no product matched.
⚖️ Legal
This Actor extracts publicly available data from Taobao and Tmall. It does not bypass any login, paywall or CAPTCHA. Users are responsible for complying with Taobao's terms of service and applicable data protection laws (GDPR, CCPA and PIPL where relevant). The output can contain personal data (shop names of individual sellers, review text); handle it accordingly. The data returned is informational; verify prices and seller information before relying on them for purchasing decisions.
🔗 Related scrapers
- 1688 Wholesale Scraper: wholesale prices and suppliers from 1688, Alibaba's domestic B2B marketplace.
- RedNote Scraper: trending posts and categories from RedNote (Xiaohongshu).
- Douyin Scraper: videos and profiles from Douyin, China's TikTok.
- Weibo Scraper: the posts of any public Weibo profile.
📬 Support
Need something this scraper does not do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing details live on the Monetization tab of the actor page
Response time: usually under 24 hours.
Check out our other scrapers: silentflow on Apify


