
Goodreads Scraper & Series Read-Through
Pricing
from $5.00 / 1,000 series
Goodreads Scraper & Series Read-Through
Goodreads scraper for book series: every book's ratings and average, read-through from book 1 to the last, the biggest drop-off and new ratings per day. Benchmark series against a Listopia list or an author's series. $5 per 1,000 series, $3 per 1,000 books.
Pricing
from $5.00 / 1,000 series
Rating
0.0
(0)
Developer
Steadywren
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Security
Limited permissionsShare
Goodreads book series data for indie and KDP authors, publishers, agents and book marketers: every main book's ratings and average, the read-through from book 1 to the last, the biggest drop-off and new ratings per day between runs - does book 1 sell the series? $5 per 1,000 series.
What you get
- One row per series: name, author, Goodreads' own "primary works" count, main books in reading order with
ratings, average rating, publication year and pages, extras (prequels, novellas, companion books) and upcoming
books. Clean typed fields: numbers as numbers,
nullwhen Goodreads has no value. - Series read-through funnel: ratings of every main book as a share of book 1 (
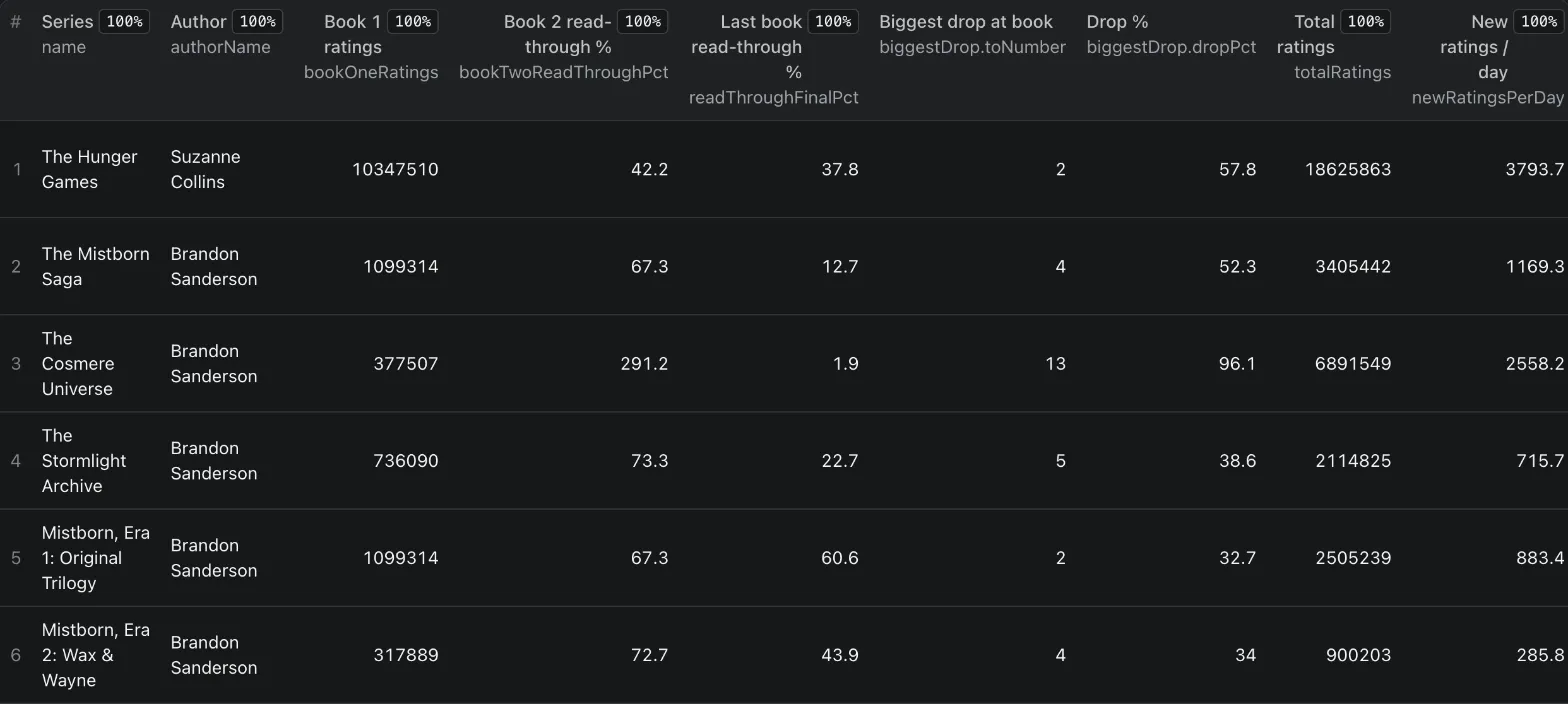
readThroughPct), the book 2 read-through, the read-through to the last book and the biggest drop-off (which step loses the most readers). Prequels (#0), novellas (#0.5, #2.5), box sets, translated split editions and announced "Untitled" books are kept out of the funnel, so a prequel or a box set is never the base. - Rating velocity: the Actor remembers ratings per book between runs. Schedule it daily or weekly and every result shows new ratings per day per book and for the whole series: follow a launch, compare it with the earlier books.
- Listopia benchmark: give a Goodreads Listopia list ("Best Cozy Mystery Series", "Best Fantasy Series") and every series named on it comes back with its full funnel, its best rank on the list and its percentile among the list's series: "is a 44% book 2 read-through good for cozy mysteries?" in one run. The free lists dataset shows per list: books read, standalones, series books, matched books, series found, books not checked because of Max series, and the series books that could not be matched (title, author).
- Author portfolio (free authors dataset): give an author and get one summary row - numbered series, total ratings, median book 2 read-through, the best and the weakest series, the newest series and its new ratings per day, and how much of the author's ratings the top series carries.
- Run benchmark: give 5 or more series, or one author with all their series, and each result gets its
percentile among the other series of the run (book 2 read-through and final read-through) and how many series it
was compared with. With fewer than 5 series
benchmarkisnull. - Optional books dataset: one row per main book, ready for a spreadsheet.
Sample output
Series
From a run on 2026-11-04 (trimmed):
velocity is null on the first run of a series. From the next run (at least an hour later) it holds
previousScrapedAt, daysSincePrevious, newRatings, newRatingsPerDay, perBook (new ratings and new ratings
per day of every main book) and newBooks (main books that were not there in the previous run).
newRatingsPerDay and bookTwoReadThroughPercentile repeat the two most used numbers as plain columns for
spreadsheets and the table view.
Series from a Listopia list
A series found on a list carries the list (run on 2026-11-05, "Best Cozy Mystery Series", Hannah Swensen):
How much does it cost?
$5 per 1,000 series. Example: 10 series plus the books dataset with their 124 books = 10 x $0.005 + 124 x $0.003 = about $0.42 (our test run, 2026-11-05). Without the books dataset, 100 series = $0.50.
- $0.003 per book in the optional books dataset ($3 per 1,000 books).
- The lists and authors datasets are free. Series found on an author page that have no numbered books are skipped and not charged; series read only to check a list book and not confirmed are not saved and not charged.
- No Actor start fee. Platform compute is included.
- Max series caps your cost.
How to use
- Paste Goodreads series URLs or ids into Series, author URLs into Authors, or Listopia list URLs into Listopia lists.
- Set Max series (and Add a books dataset if you want one row per book).
- Click Start, then download JSON, CSV or Excel from the Output tab.
Main filters: series, authors, Listopia lists, pages per list, max series.
Use it for:
- Indie / KDP authors: does book 1 sell the series? Where do readers leave? Compare your series with the others in your genre or with an author you model yourself on.
- Publishers and agents: screen a series before an acquisition or a translation deal.
- Book marketers and ad buyers: track a launch day by day; see which series keep their readers.
Use with AI assistants (MCP)
Connect this Actor to Claude, ChatGPT or any MCP client: https://mcp.apify.com?tools=steadywren/goodreads-series-scraper
Try:
- "How many readers of The Hunger Games continue to book 2 and to the last book on Goodreads?"
- "Take the Goodreads list Best Cozy Mystery Series and show me the series with the best book 2 read-through."
How it compares
Checked against the Store descriptions of 12 Goodreads Actors in Apify Store on 2026-11-03.
| This Actor | Other Goodreads scrapers in Apify Store | |
|---|---|---|
| Series read-through funnel (ratings of book N / book 1, drop-off point) | yes | no |
| Rating velocity (new ratings per day per book between runs) | yes | no |
| Listopia benchmark (percentile among the list's series) | yes | no |
| Author portfolio summary of all series | yes | no |
| Price | $5 per 1,000 series, $3 per 1,000 books (optional) | $1.50 to $3 per 1,000 results (where listed) |
Monitor daily
Keep Track changes between runs on (default) and schedule the Actor daily or weekly (Console -> Schedules) for
the same series, authors or lists. From the second run (at least an hour after the first), every series shows
velocity: new ratings per day per book and for the series, and newBooks when a main book appears. Rating
history is kept in the named key-value store goodreads-series-history of your account (up to 60 snapshots per
series).
FAQ
Is it legal? The Actor collects publicly available data only, without login and without personal data of private individuals. Check the site's terms for your use case. It reads only pages Goodreads' robots.txt allows (every URL is checked before it is requested): no reviews, no reader data; author names are those of published authors.
What if Goodreads changes or a run fails? The run fails with a clear error instead of returning empty results
(when it saves 0 series without a reason, e.g. a site change), and you are not charged for results it did not
deliver. A series page that does not look like a series page fails the request instead of returning an empty row.
Series that do not exist give a green run and are listed in seriesNotFound. Each run's summary (series and books
saved, retries and failures per category, series not found, skipped series without numbered books, input series
left out by Max series) is in the Storage tab -> Key-value store -> RUN_SUMMARY. A migrated run keeps the series it
already read.
Do I need proxies? Are there limits? Apify Proxy is used by default. At most 3 pages in parallel and about one request per second, to be polite to Goodreads. One request per series page (one per 100 works for bigger series); a list page (100 books) takes 40-200 requests - the list, the authors' series lists (up to 3 pages each) and the series pages - about 1-3 minutes. Max series counts all inputs together (first come, list candidates count too); it defaults to 100 when a list is given, because one list page names about 90 series.
How fresh is the data? Live at run time: ratings counts as Goodreads shows them on the series pages.
Why are some list books missing from the results? Standalone books (no "(Series, #N)" in the title) are
skipped. A series book is matched through its author's series list and confirmed on the series page (the book is in
the series, or the series has a main book with that number) - never guessed. On three lists checked on 2026-11-05,
94% of series books were matched; the rest (omnibus editions, authors with hundreds of series) are listed in the
lists dataset as unmatched. Books not checked because Max series was reached are counted in
skippedByMaxSeries.
Why are there no reviews and no search? Goodreads' robots.txt does not allow automated access to review pages, search or book "work" pages, and this Actor respects that. It reads only series pages, authors' series lists and Listopia lists; book pages are never requested. Give series, authors or lists by URL or id.
Is read-through the same as sales? No. It is a proxy: Goodreads ratings are cumulative, summed over all editions of a book, and only some readers rate. It is the best public signal of how many readers continue, and it is comparable between series because every series is measured the same way.
Why can book 2 have more ratings than book 1? Some series are numbered in story order, not publication order (The Chronicles of Narnia: book 2 is The Lion, the Witch and the Wardrobe), or a later book was a bigger hit. The Actor keeps Goodreads' numbering and shows the number as it is (over 100%). "Universe" series that collect several series of one author (e.g. The Cosmere Universe) behave the same way; compare their sub-series instead. The author portfolio picks the best and weakest series only among series with a book 2 read-through up to 100% and book 2 published before this year.
Why is the last book so low? A book published a few months ago has had less time to collect ratings. Check
publicationYear, and use velocity to follow it.
Which books count as main books? Entries Goodreads lists as "Book 1", "Book 2", ... up to its own "N primary
works" count. Prequels and novellas (#0, #0.5, #2.5), unnumbered companion books, box sets, omnibus editions,
translated split volumes and announced "Untitled" books are left out of the funnel (extras / upcoming). When a
series page has no main "Book 1" (it exists only as split parts), book 1 ratings, book 2 read-through and final
read-through stay empty instead of using another book as the base (per-book readThroughPct is then relative to the
lowest-numbered main book).
More from Steadywren
- Substack Scraper & Newsletter Revenue Estimate - Substack leaderboards with paid tiers, prices and an estimated revenue range per newsletter.
- Google News Scraper & AI Company Signals - news for any company or topic with AI event type, sentiment and momentum.
- Startup Funding Rounds Scraper - Global News - funding rounds from news worldwide with amount in USD, round, investors and sources.
- All Steadywren Actors - small tools, steady results. Custom builds: steadywren.com.
Input reference
| Field | Type | Default | Description |
|---|---|---|---|
series | array | Harry Potter (https://www.goodreads.com/series/45175-harry-potter) | Goodreads series URLs or ids, e.g. https://www.goodreads.com/series/45175-harry-potter or 45175. One result per series: every main book's ratings and average, read-through from book 1, the biggest drop-off. |
authors | array | - | Goodreads author URLs or ids, e.g. https://www.goodreads.com/author/show/38550.Brandon_Sanderson. Every series of the author is read (up to Max series); series without numbered books (translated split editions, box sets) are skipped and not charged. |
lists | array | - | Goodreads Listopia list URLs or ids, e.g. https://www.goodreads.com/list/show/3810.Best_Cozy_Mystery_Series. Every series book on the list is matched to its series (through the author's series list, confirmed on the series page), and each series gets its percentile among the list's series. Standalone books are skipped. |
maxListPages | integer | 1 | List pages read per list (100 books each), 1-5. |
maxSeries | integer | 20 (100 with lists) | Stop after reading this many series pages (all inputs together). You are charged per series result, so this also caps the cost. Default 20, or 100 when a list is given (one list page names ~90 series). |
includeBooks | boolean | false | Also save one row per main book (ratings, average, read-through, new ratings per day) to the run's 'books' dataset. Charged per book. |
trackChanges | boolean | true | Remember ratings counts per book, so the next run of the same series shows new ratings per day per book and for the series. Schedule the Actor (e.g. daily or weekly) to follow a launch. |
authorSummary | boolean | true | One summary row per input author in the run's 'authors' dataset (free): numbered series, total ratings, median book 2 read-through, best and weakest series, newest series and its new ratings per day. |
maxConcurrency | integer | 2 | Pages fetched in parallel (1-3). Kept low on purpose to be polite to Goodreads (about one request per second). |
proxyConfiguration | object | Apify Proxy | Proxy servers used for the requests. |
Search keywords: goodreads scraper, goodreads, book series, goodreads ratings, goodreads list scraper, listopia


