

Reddit Brand Sentiment Scraper | Complaints & Reviews
Pricing
from $0.079 / quick sentiment report
Reddit Brand Sentiment Scraper | Complaints & Reviews
Extract brand sentiment, complaints, and alternatives from Reddit discussions. Enter any brand name, get structured analysis with real quotes and source URLs. Competitive mode compares multiple brands side by side. Full markdown report for LLM pipelines.
Pricing
from $0.079 / quick sentiment report
Rating
0.0
(0)
Developer

Zen Studio
Maintained by CommunityActor stats
1
Bookmarked
8
Total users
0
Monthly active users
7 days ago
Last modified
Categories
Share
Reddit Brand Sentiment Analyzer | What People Really Think (2026)
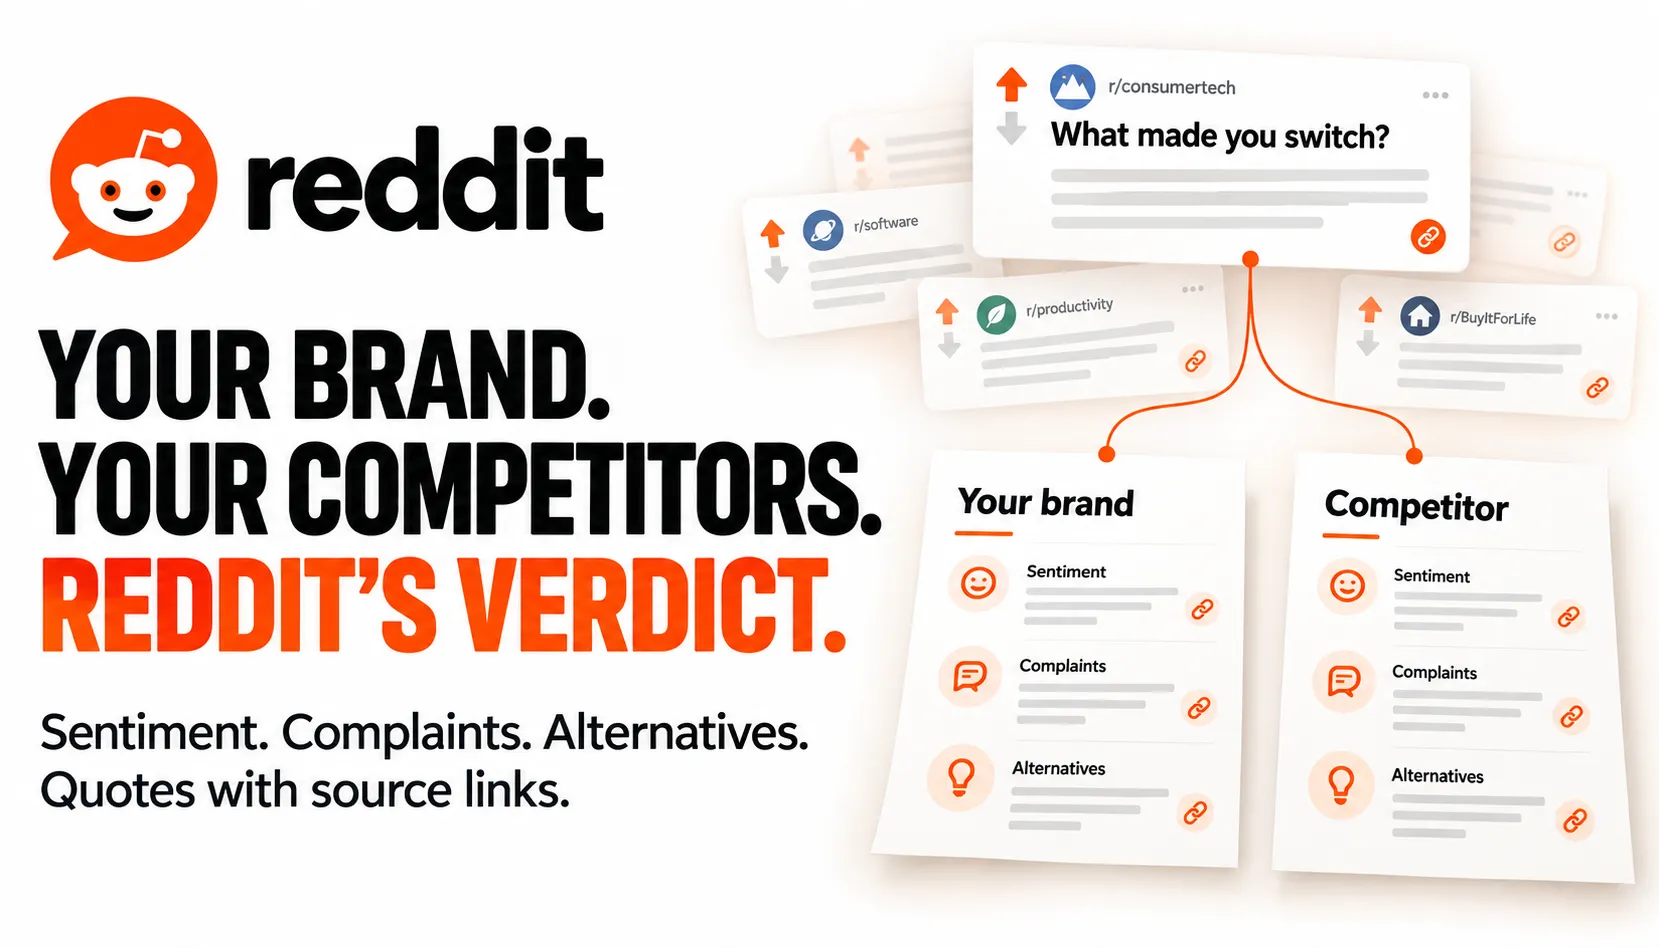
From Zen Studio, creators of G2 Reviews and Capterra Reviews, with 50,000+ combined runs across those two actors.
Why choose this Reddit brand analyzer?
- Compare brands on the same three questions. Full reports cover how people feel, what frustrates them, and which alternatives they recommend. Add competitors to get a separate report for each, making differences and switching reasons easier to compare.
- Follow the quotes back to Reddit. Get supporting quotes with subreddit attribution and source links, plus cited posts and the communities discussing each brand. Use the AI-summarized findings to spot themes, then inspect the original discussions.
- Use the report immediately. Export structured JSON with
sentiment,complaints,alternativesandallQuotes, alongside a combined Markdown report for briefs, dashboards and further analysis. Duplicate quotes and communities are consolidated within each brand report.
Compare your brand with a competitor
Open actor input, paste this example and replace the brand names with yours. Full mode includes all three sections. Each competitor is charged as a separate brand analysis, so this example requests two analyses. Remove competitors for a single-brand report.
Choose depth: "quick" for sentiment only. The output is a sourced narrative analysis, not a numeric sentiment score; the available discussions and quotes depend on the brand's Reddit presence. Export JSON to retain the nested brand reports, or use the included Markdown report.
| Zen Studio · Reviews & Brand Research | ||||
 Brand Sentiment You are here |  Reddit Reviews Software opinions |  G2 Reviews Pros & cons |  Capterra Buyer reviews |  TrustRadius Enterprise reviews |
Copy to your AI assistant
Copy this block into ChatGPT, Claude, Cursor, or any LLM to start building with this data.
How to Analyze Brand Sentiment on Reddit
Single brand
Quick snapshot (faster, cheaper)
Competitive analysis
Input Parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
brand | string | required | Brand, product, or company to analyze |
competitors | string[] | — | Competitors for side-by-side comparison |
depth | select | full | quick (1 angle, ~15s) or full (3 angles, ~30-60s) |
What Data Can You Extract About a Brand?
Every report includes:
- Sentiment — AI-synthesized summary of how Reddit discusses the brand, with supporting quotes
- Complaints — most common frustrations and criticisms, sourced from real discussions
- Alternatives — what people recommend instead and why they switch
- Quotes — deduplicated across all angles, each with subreddit attribution and direct URL
- Communities — subreddits where the brand is discussed
- Source posts — cited Reddit threads with metadata
- Markdown report — combined narrative ready for LLM consumption
Output Example
In competitive mode, the output includes a competitors object with a full report per competitor:
Advanced Usage
Competitive research pipeline
Run multiple competitors to map the competitive landscape. Each brand gets the same full analysis.
The alternatives angle for each brand naturally cross-references the others. If people switch from Slack to Discord, that shows up in Slack's alternatives section.
Scheduled brand monitoring
Schedule this actor to run weekly or monthly. Each run produces a timestamped report. Compare reports over time to track sentiment shifts after product launches, pricing changes, or PR incidents.
Use quick mode for scheduled runs to keep costs down ($0.10 vs $0.25 per brand).
Feed into LLM pipelines
The markdown field is a complete narrative report ready for GPT, Claude, or any LLM. Use it as context for generating executive summaries, blog posts, or investor briefings.
Customer discovery for founders
Find out what people complain about in your space. The complaints and alternatives angles reveal pain points and unmet needs.
Pricing — Pay Per Event (PPE)
| Depth | Per brand | What you get |
|---|---|---|
| Quick snapshot | $0.10 | 1 angle (sentiment only), ~15 seconds |
| Full report | $0.25 | 3 angles (sentiment + complaints + alternatives), ~30-60 seconds |
Each brand counts as one event. Competitors are charged separately at the same rate.
| Scenario | Cost |
|---|---|
| Single brand, quick | $0.10 |
| Single brand, full | $0.25 |
| Brand + 2 competitors, full | $0.75 |
| Brand + 4 competitors, quick | $0.50 |
What Brands Work?
Tested across 14 brands in different categories. Works for any brand, product, or company discussed on Reddit.
| Category | Example | Quotes found |
|---|---|---|
| SaaS | Notion, Linear, Monday.com | 28-79 |
| Consumer | Tesla, SHEIN, Temu | 36-45 |
| Fintech | Robinhood | 42 |
| B2B | Datadog | 37 |
| DTC | Huel, Oatly | 40 |
| Dev Tools | Raycast, Cursor | 36-39 |
| VPN | NordVPN | 35 |
| Niche SaaS | GorillaDesk (pest control) | 32 |
| Medical | Cala (wearable) | 32 |
Niche brands with limited Reddit presence still produce useful reports. GorillaDesk returned 32 quotes from r/PestControlIndustry.
How It Works
- Identify — resolves brand name to its canonical form, detects generic names (e.g. "Linear", "Monday") to avoid confusion with common words
- Analyze — fires 3 parallel queries to Reddit's AI synthesis engine, each targeting a different angle (sentiment, complaints, alternatives)
- Merge — deduplicates quotes and communities across angles, builds a unified report with combined markdown
Full mode takes 30-60 seconds. Quick mode takes 15-20 seconds.
FAQ
What brands work? Any brand, product, or company discussed on Reddit. Works across all categories: SaaS, consumer products, fintech, health, automotive, dev tools.
What if a brand has a generic name like "Linear" or "Monday"? The actor automatically detects generic names and adds context to prevent confusion. "Linear" returns results about the project management tool, not linear algebra.
How fresh is the data? Every run queries Reddit live. There is no cache. Results reflect current discussions.
What's the difference between quick and full mode? Quick runs 1 angle (sentiment only), full runs 3 (sentiment + complaints + alternatives). Both cost the same per brand, but quick is faster.
How does competitive mode work?
Add competitor names to the competitors field. Each competitor gets the same full analysis. The alternatives angle for each brand naturally references the others, revealing switching patterns.
Can I schedule recurring runs? Yes. Use Apify's built-in scheduler to run weekly or monthly. Compare timestamped reports to track sentiment shifts over time.
What if there are no Reddit discussions about my brand? You'll get a report with empty or minimal data. The actor only returns what Reddit actually contains.
How are quotes selected? Quotes are extracted from Reddit's AI-synthesized answers, which pull from thousands of discussions. Each quote includes the source subreddit and a direct URL to the original comment.
Can I use this for content marketing? Yes. The quotes and pain points make excellent source material for blog posts, social media, and thought leadership content. Every quote has attribution.
Support
- Bugs: Issues tab
- Features: Issues tab
Legal Compliance
Extracts publicly available data from Reddit. Users must comply with Reddit's terms of service and applicable data protection regulations (GDPR, CCPA).
Structured brand intelligence from Reddit. Real quotes, real communities, real sentiment.


