
Company Contact Route Planner
Pricing
from $7.00 / 1,000 contact routes
Company Contact Route Planner
Route company contact datasets to sales, support, press or partnerships. Select exact role mailboxes and label general, phone and contact-page fallbacks with source evidence for each contact route.

Company Contact Route Planner — turn a company-contact dataset into an explicit departmental routing table
Feed it an existing company-contact dataset and get back one explicit contact route per company per department — sales, support, press, partnerships, general — built from exact role-mailbox matching, with the matched evidence shown, never a claim of deliverability.
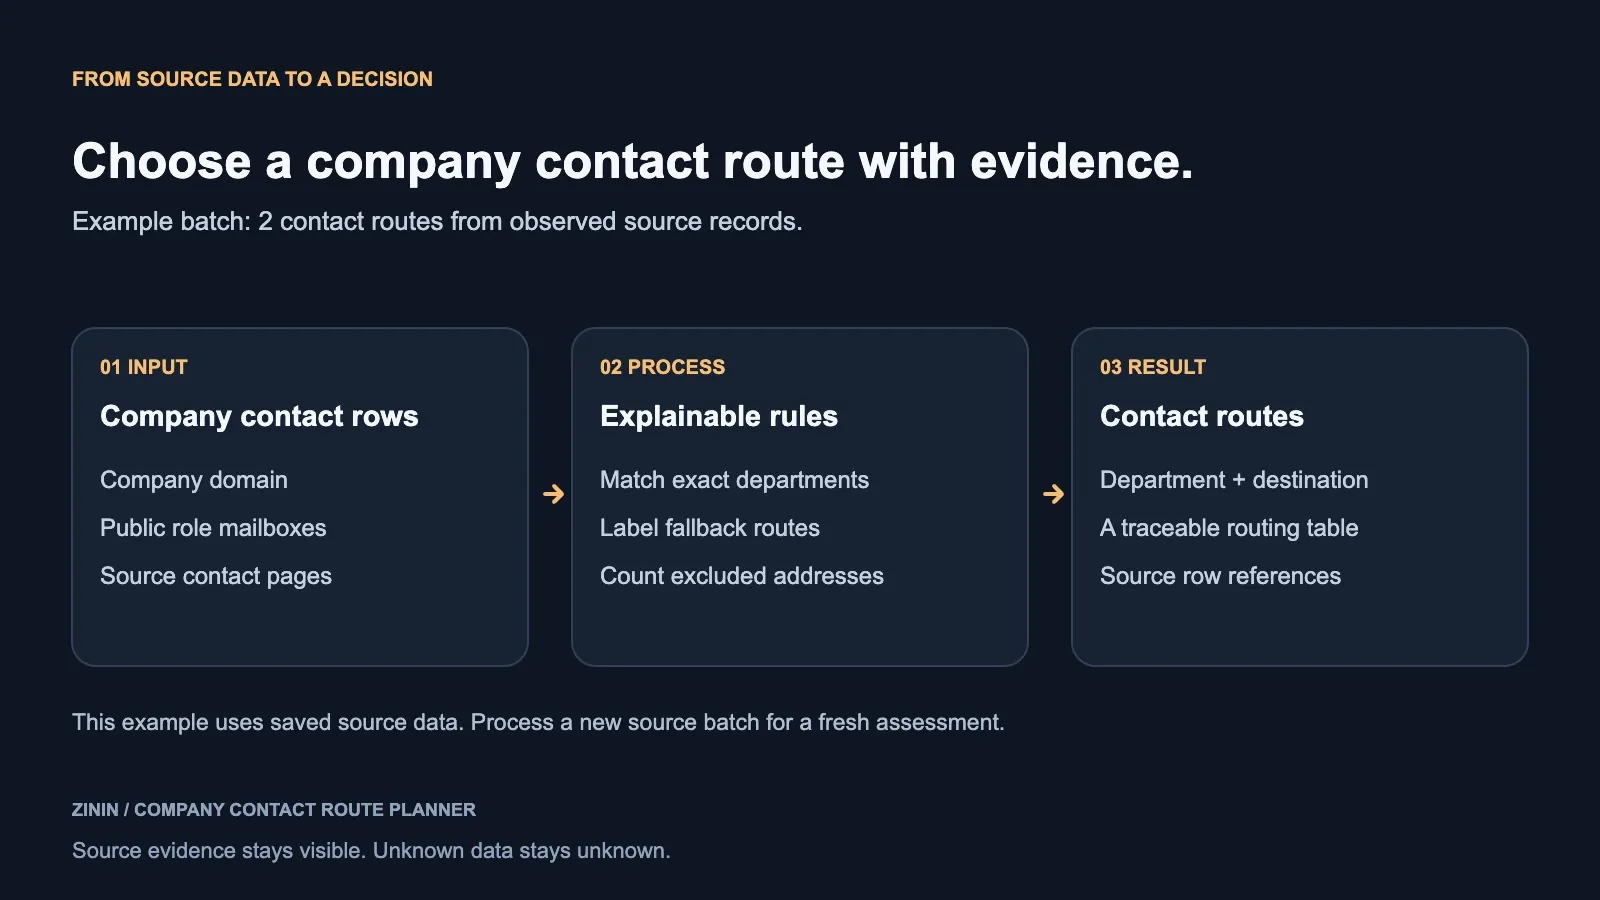
This Actor does not scrape websites, Google Maps, or any other source. It reads a company-contact dataset you already have — most naturally from Website Contact Scraper or a compatible Google-Maps-with-contact-details dataset — and turns it into an auditable routing table: which mailbox to use for which department, with the exact rule that produced it, or an honest "no usable route" record when nothing qualifies. Every route names its email or fallback, source row, and exact or fallback match. Use it for RevOps routing; it does not check deliverability or permission to contact anyone.
What you get
For each distinct company domain and requested departmental purpose, you get one route record containing:
domain— the company's canonicalized hostname (protocol, path, port, and a leadingwww.stripped; exactly one trailing DNS root dot removed), andtargetPurpose— which of five fixed departments this route is for (sales,support,press,partnerships,general).routeType,routeValue, andconfidence— the kind of route found (an exact role mailbox, a generic fallback mailbox, a phone-research fallback, or a contact-page-research fallback), the actual value to use, and a disclosed confidence label (highfor an exact role match,mediumfor a generic fallback,lowfor a phone/page research fallback) — never a probability of commercial success.action—use_routewhen a real mailbox was found (role or generic fallback), ormanual_researchwhen only a phone number or a contact page URL is available and a person still needs to do the outreach research themselves.alternateRoutes— up to 10 other departments' role mailboxes at the same company, so you can see what else is available without a second run.- Exclusion counts —
excludedNonRoleEmailCountcounts distinct own-domain non-role addresses fromemails;excludedThirdPartyEmailCountcounts valid distinct foreign addresses fromthirdPartyEmails. Foreign addresses inemailsare ignored without entering either count. Excluded address strings are not emitted. evidence— the literal matched value, which rule matched it, and the exact source row index it came from, for full auditability of every route.- Free diagnostics identify failed source rows, invalid domains and missing routes. The initial list combines business diagnostics and source-read notices; only its first 200 entries are written. Later result-size and result/budget-cap notices can increase the total free row count.
What this Actor explicitly is not: it performs no MX/SMTP/deliverability checks, computes no generic "hotness" or lead score, and never re-scrapes a website — it only reads the contact data your source dataset already collected. A delivered route is a disclosed routing decision from that data, never a promise the mailbox is monitored or that the address will accept mail.
Who uses it
- RevOps and sales-ops teams who already run a company-contact scrape and need to route each company's raw address list to the right internal queue — sales, support, press, or partnerships — without eyeballing every domain's inbox list by hand.
- Outbound SDR/BDR teams who want an exact
sales@-style mailbox when one exists, and an honestmanual_researchflag (a phone number or contact page to check by hand) when it doesn't, instead of guessing at a genericinfo@address. - PR and partnerships teams working from the same contact dataset who need their own department's route without re-running a separate scrape.
- Data-quality and CRM-hygiene teams who want a repeatable, auditable, dictionary-based routing step (not an opaque LLM guess) they can insert into an existing pipeline and explain exactly why a company routed the way it did.
It is not a scraper: point it at an existing company-contact Dataset from an upstream Actor producing the row shape in Input contract, most naturally Website Contact Scraper (users30d=7, successfulRuns30d=59 at last capture) or Google Maps with Contact Details (users30d=3240, successfulRuns30d=72898). This Actor never starts either one, and never fetches a page from the open web.
How to run
- Console (fastest for a one-off run). Open the Actor, go to Input, and either paste your contact rows into Source records (inline) or fill in Source Dataset with the Dataset ID from your contact-extraction run. Leave everything else at default and hit Start.
- From an existing company-contact Dataset. Put a Dataset ID from a contact-extractor run into
datasetId. The Dataset is read with your own run's permissions — private sources require an authorized resource selection or integration; there is no elevated access beyond the run token. - Chained after an upstream contact-extractor Actor via Integrations. Add this Actor as an "Actor/task run" integration on your upstream Actor. Apify's Integrations UI auto-populates the payload with
{{resource.defaultDatasetId}}; map that value into this Actor'sdatasetIdfield explicitly (see Integration recipes) for aREADgrant underLIMITED_PERMISSIONS— a bare Dataset ID string or webhook payload reference alone does not grant access. - Via the API. Call
POST /v2/acts/Cae9iduRC0BFptpvP/runs(orrun-sync-get-dataset-itemsfor a synchronous call) with a JSON body containingdatasetId(oritems) and, for a hard spending ceiling, the run optionmaxTotalChargeUsd. - Choose your departments. Set
targetPurposesto any subset ofsales,support,press,partnerships,general(1–5 values); omit it to get all five per company. - Read the results. One row per matched domain+purpose lands in the run's default Dataset. A matching
OUTPUT/SUMMARYrecord in the Key-value store reports routes delivered, free diagnostics, and whether a cap ended the run early.
Every run is independent processing — see Operating guide for exactly what that means for re-running against the same batch.
Pricing
Pay-per-event, one event type: result-found ("Contact route" in the platform's pricing UI) — one delivered contact route (one domain+purpose pair). There is no start fee, and every free diagnostic (a missing domain, a source-reported failure, a "no route available" record, a budget stop, an empty batch) requests no charge event at all.
| Tier | Price per contact route | Discount |
|---|---|---|
| Free (default) | $0.01 | — |
| Bronze | $0.009 | 10% |
| Silver | $0.008 | 20% |
| Gold | $0.007 | 30% |
| Platinum | $0.007 | 30% |
| Diamond | $0.007 | 30% |
These are Apify's platform-wide account pricing tiers — not a volume schedule this Actor invents — assigned automatically based on your account's own usage; you don't select one. The pricing noun throughout this listing is contact route: one delivered domain+purpose routing decision, never billed per raw input row or per email address seen. A company requesting routes for three departments in one run produces (and is billed for) three separate contact-route rows, one per department.
A note on the evidence in this README: every output example below comes from the product owner's own verification runs against this Actor's accepted build — cost to the owner, not sales or customer revenue.
Set the platform's own Max total charge (USD) run option to cap total spend for a single run. If testing the zero-paid path via a raw API call rather than the Console, do not rely on a literal maxTotalChargeUsd: 0 — use a small positive value below every current tier's price (e.g. $0.005, below Gold/Platinum/Diamond's $0.007); see Evidence and boundaries for a real recorded run demonstrating exactly this.
Input contract
| Field | Type | Default | Notes |
|---|---|---|---|
items | array (JSON editor), max 1000 entries | prefilled real example | Inline source records. Ignored if datasetId, runId, or a resolvable payload.resource is also given. |
datasetId | string (Dataset picker, READ) | — | Dataset ID from a company-contact extraction run. Read with your own run's permissions. Overrides inline items. |
runId | string, max 64 chars | — | An Actor run ID to read instead of a Dataset ID directly; its default Dataset is resolved automatically, using your own run's own permissions — no elevated access, no upstream Actor started. |
payload | object (JSON editor) | — | Optional ACTOR.RUN.SUCCEEDED-shaped payload carrying resource.defaultDatasetId/resource.id from an upstream run. The resource picker on datasetId is the recommended way to grant private-Dataset access; a bare payload reference does not itself grant access. |
maxInputRows | integer | 100 | Hard cap on source records examined before grouping (1–1000). Bounded to 4 MiB total and 64 KiB per row regardless of this value. |
maxResults | integer | 10 | Maximum number of useful contact-route results this run can deliver (1–1000), independent of the platform's Max total charge run option. |
targetPurposes | array (select), 1–5 of sales|support|press|partnerships|general | all five | Which departments to build a route for. Given but empty, given with more than 5 entries, or given with a value outside the five departments is rejected as invalid input, not silently corrected to the full set. |
Source precedence, exactly: an explicit datasetId or payload.resource.defaultDatasetId (they must agree if both are present) beats a runId or payload.resource.id, which beats inline items. A dataset/run source is never merged with inline rows. A malformed or conflicting reference is rejected as invalid input, never silently downgraded to the inline example. Private-Dataset READ access is conditional on the resource picker or an authorized Integrations mapping — a bare Dataset ID string, or a webhook payload's resource.defaultDatasetId value alone, does not grant access to data you aren't already permitted to read.
Accepted row fields (any subset present is used; nothing here is strictly required except enough to identify a domain — see Evidence and boundaries for what happens with less):
| Field | Accepted as | Role |
|---|---|---|
domain, input, website | string | Company identity, in that priority order. Canonicalized to a bare hostname: protocol/path/port stripped, a leading www. stripped, exactly one trailing DNS root dot removed, then validated as a syntactically real DNS hostname (1–63-character alphanumeric-with-internal-hyphens labels, at least two labels). An authority-trick input like https://real.com@evil.com/ resolves to its true parsed hostname (evil.com), never the attacker-controlled userinfo segment. |
emails | array of strings or {value|email|address} objects | Scanned in full (the shared 64 KiB per-row cap already bounds this). Only addresses whose domain exactly matches the row's own company domain are used for routing — sub.example.com is never treated as the same target as example.com. |
thirdPartyEmails | array of strings or {value|email|address} objects | Same validation; addresses whose domain differs from the company's own are counted toward excludedThirdPartyEmailCount, never used for routing. |
phones | array of strings or {value} objects | Up to 10 per row; each must be 6–18 digits after stripping formatting characters, ≤50 characters raw. Used only as a last-resort manual_research route when no email route exists. |
sourcePages (array of strings) / sourcePageUrls (array of {sourceUrl}/{sourcePath}) | string/object | Candidate page URLs. A candidate qualifies as the domain's contact page only if it resolves (relative to the row's own domain) to that exact domain, uses http/https, carries no embedded userinfo, and its path contains an exact /contact/, /contact-us/, /about/, or /about-us/ segment — /contacted and /aboutness do not match. Used only as the last-resort manual_research route when no email or phone route exists. |
found, error, errors, failed, status | Explicit found:false, failed:true or failed/error/timed-out/aborted status is always a free source failure. Only soft error/errors warnings may remain usable with found:true AND partial:true. |
Hard read bounds, always enforced regardless of maxInputRows: at most 1000 source rows, at most 4 MiB of total source JSON per run, at most 64 KiB per individual row (an oversized row is dropped and disclosed). This Actor reads only the fixed https://api.apify.com origin with your run's own token — it never fetches an arbitrary URL and never starts an upstream Actor.
Output examples
Every example below is a real record from an actual accepted run of this Actor's build 0.1.3 (Actor ID Cae9iduRC0BFptpvP, build 5KhSjd9QO5SVPBiGa), reproduced exactly — measured values, IDs, and timestamps are not hand-edited. All source dates come from the underlying checkedAt field in the contact dataset (2026-09-22T05:45:22.120Z); the runs themselves were processed on 2026-09-23, roughly a day later — a saved snapshot, never a live re-check.
1. First useful route — a full, real dataset row
This run requested the full default set of five departments against the Actor's own real inline prefill row (the same real apify.com contact record also available via the public example Dataset E2ltQnmLuOBDVVbMD, which a separate, narrower targetPurposes: ["sales", "general"] run against that Dataset independently confirmed produces exactly 2 routes for this single company — the scope the two diagrams on this page illustrate).
Actor input (the Actor's own real default prefill row):
First Dataset output row (of five delivered from this run):
hello@apify.com is the mailbox supplied by the saved public Apify company-contact example — it is a role-dictionary hit under the general department because hello is one of that department's exact local-part keywords. The remaining four results in this run are all generic_fallback_mailbox routes (partnerships, press, sales, support), each routing to the same hello@apify.com with confidence: "medium" and alternateRoutes: [{ "purpose": "general", "email": "hello@apify.com" }], because this single-mailbox company has no dedicated role address for any department except general.
2. Derived partial-flag control — same real values, an explicit incompleteness flag injected
This is not a demonstration of removed columns or of actual upstream data incompleteness. It is the identical real apify.com row and the identical real hello@apify.com mailbox as example 1, with the source row's own partial field deliberately set to true (instead of false) to exercise this Actor's disclosed-incompleteness path under a controlled, known input. Every underlying value — the domain, the email, the source page URLs — is identical and real; only the incompleteness flag itself is a deliberate test control, not an observed condition from any actual scrape.
Actor input (identical to example 1's row, except "partial": true):
Resulting general route (businessPartial: true, partial: true — otherwise identical to example 1's general route):
Notice the route itself — mailbox, confidence, evidence — is unchanged from example 1; only businessPartial/partial flip to true because the source row disclosed its own incompleteness. This is exactly what a real upstream source marking a genuinely partial scrape would produce; the fixture control simply demonstrates the mechanism does not silently drop the disclosure.
3. Below-price run — free budget_stopped diagnostic, no partial charge
This run was started with the platform run option maxTotalChargeUsd: 0.005 — below every pricing tier's per-route price (even Gold/Platinum/Diamond's $0.007). The Actor never reads the source batch, delivers zero paid routes, and writes this one free diagnostic. See Evidence and boundaries for what the literal value 0 does instead via a raw API call, which is different from this.
4. Empty batch — free no_results diagnostic
Actor input:
Dataset output:
An empty or entirely-unusable batch is a free diagnostic, never a silent zero-row success and never a charge.
Field dictionary
Per-route result fields:
| Field | Type | Meaning |
|---|---|---|
entityId | string | `"domain: |
found | boolean | true on every billed route; false on every free diagnostic. |
status | string | role_mailbox_matched, generic_fallback_mailbox, phone_research_route, contact_page_research_route on a route; a diagnostic reason (invalid_row, source_row_failed, missing_domain, no_matching_route, invalid_input, budget_stopped, no_results, max_results_reached, result_dropped_oversized, source_rows_dropped, partial_source, source_unavailable) on a free row. |
domain | string | The canonicalized company hostname (see Input contract). |
targetPurpose | string | One of sales, support, press, partnerships, general. |
routeType | string | role_mailbox (exact departmental match), generic_fallback_mailbox (no dedicated mailbox, but a general one exists), phone_research_route (phone number only), or contact_page_research_route (contact/about page URL only). |
routeValue | string | The mailbox address, phone number, or contact-page URL to use, matching routeType. |
confidence | string | high (exact role mailbox), medium (generic fallback), or low (phone/page research fallback) — a disclosed rule-based label, never a probability. |
action | string | use_route for an email route; manual_research for a phone or contact-page fallback, signaling a person still needs to do the outreach research. |
alternateRoutes | array | Up to 10 { purpose, email } entries for this company's OTHER departments that have their own dedicated role mailbox. |
excludedNonRoleEmailCount | number | Exact count (not a raw array length) of own-domain addresses matching no departmental keyword — counted, never listed as strings. |
excludedThirdPartyEmailCount | number | Distinct valid foreign addresses in thirdPartyEmails; foreign addresses in emails are ignored, not counted. No excluded strings are emitted. |
excludedThirdPartyEmailCountIsLowerBound | boolean | true only if a defensive per-row scan ceiling was actually hit (not the normal case, since the 64 KiB row cap already bounds array size) — then the count above is a lower bound, not exact. |
observedAt | string (ISO 8601) or null | The latest valid source checkedAt across every accepted row for this domain, computed before the 50-row sourceRowIndexes display cap and shared identically by every purpose result for that domain. A source capture time, never this Actor's own processing time — null when no accepted row carried a parseable checkedAt. |
sourceObservationWindow | object | { earliest, latest, validCount, totalRowCount } — the raw checkedAt strings spanning every accepted row for this domain (never re-derived from milliseconds, so a timezone offset or sub-millisecond fraction survives unchanged), validCount of rows with a calendar-valid checkedAt, and totalRowCount of every accepted row for this domain, including rows with a missing or invalid checkedAt. |
evidence | array | Up to 12 entries, each { field, value, rule, sourceRowIndex }. |
sourceRowCount / sourceRowIndexes | number / array | True count and (capped at 50) list of original source rows contributing to this company's data. |
businessPartial / partial | boolean | businessPartial is this module's own signal (source disclosed partial: true, over 50 contributing rows, or a lower-confidence phone/page fallback). partial also folds in run-level source incompleteness — check partial if you only check one flag. |
sourceCoverage | object | Run-level: { complete, reason, droppedOversized } — whether the source read itself hit a cap. |
sourceDatasetId, sourceRunId, suppliedSourceRunId, sourceRunIdVerified | string/null, boolean/null | Where the batch came from; sourceRunId is set only when independently verified against the Dataset. |
processedAt | string (ISO 8601) | When this Actor processed the row. Never a claim about when the contact data was originally collected — see checkedAt/observedAt in your own source rows for that. |
reason / error | string | Present on free diagnostic rows only. |
mode | string | Source selection mode on invalid_input or source_unavailable diagnostics; unavailable sources fail the run. |
count | number | Source/oversized-result rows represented by a diagnostic notice. |
delivered, totalUseful | number | Confirmed deliveries and useful candidates on a result/budget-cap notice. |
Exact role-mailbox dictionary (case-insensitive, exact local-part match only — no substring guessing: "salesforce" never matches "sales"):
| Department | Exact local-parts |
|---|---|
sales | sales, sales-team, salesteam, biz, bizdev |
support | support, help, helpdesk, customerservice, care |
press | press, media, pr, communications |
partnerships | partnerships, partner, partners, alliances |
general | info, hello, contact, office, admin |
Complete runtime OUTPUT/SUMMARY field table (the Key-value store record under both the OUTPUT and SUMMARY keys — identical payload, two conventional key names):
| Field | Meaning |
|---|---|
schemaVersion | This product's output schema version string ("1.0"). |
product | "company-contact-route-planner". |
outcome | delivered, budget_stopped, max_results_reached, no_results, diagnostic, or failed. |
errorCode | A short internal code on a non-nominal outcome (e.g. SOURCE_UNAVAILABLE, ALGORITHM_FAILED), or null. |
fatalFailure | true only when outcome === "failed". |
deliveryUncertain | A Dataset-write or charge acknowledgment is uncertain, including FREE_WRITE_FAILED; raw rows can exceed confirmed counters. |
replayBlocked | true when this run refused to bill further because its own event counters didn't match its expected state, to avoid a duplicate charge. |
requested | The number of source rows actually read for this run. |
usefulResults | Results found after oversized-row filtering, before any budget/maxResults cap was applied. |
delivered | Paid, confirmed routes actually written. |
paid | Confirmed result-found charge events (from the platform's own event counters, cross-checked against delivered). |
free | Acknowledged free rows written, including notices outside the initial 200-entry diagnostic list. |
failed | Useful results dropped for exceeding the 64 KiB per-row output limit (rare; distinct from a diagnostic). |
sourcePartial / sourcePartialReason | Whether the source READ itself was incomplete, and why (e.g. max_input_rows_reached, total_byte_cap_reached, oversized_rows_dropped). |
sourceDroppedOversized | Count of source rows dropped for exceeding 64 KiB before ever reaching the routing logic. |
budgetStopped | true if the run's charge limit was reached before all useful routes could be delivered. |
resultsCapped | true if maxResults was reached before all useful routes could be delivered. |
businessPartialResults | Partial transform results counted before size, budget and result-cap filtering; not a delivered-result count. |
oversizedDiagnosticsDropped | Diagnostic rows dropped for exceeding 64 KiB (rare). |
diagnosticsTruncated | The initial list of business diagnostics plus source-read notices exceeded 200. Later result-size/cap notices are outside this limit. |
partialOverall | true if ANY of the above incompleteness signals fired — the single field to check if you only check one. |
budgetMode | unlimited, finite, or local_no_charging (running outside the platform, e.g. locally). |
maxTotalChargeUsd | The effective run charge cap this run actually enforced, or null when unlimited/local. |
replaySafety | A fixed disclosure string: re-running is new processing with no cross-run deduplication. |
businessSummary | The product module's own summary object: { rowsProcessed, resultsCount, diagnosticsCount, uniqueDomains, purposesRequested, routeTypeCounts, observedAt, sourceObservationWindow, sourceDatasetId, sourceRunId }. businessSummary.observedAt stays permanently null — it is a legacy field derived from the runtime's own context.observedAt, which is always null in production. businessSummary.sourceObservationWindow ({ earliest, latest, validCount }) is the field that actually carries real batch-wide capture-time data, mirroring each result's own window for the whole run. |
processedAt | ISO 8601 timestamp of this OUTPUT/SUMMARY write. |
Evidence and boundaries
Hostname canonicalization strips exactly one trailing DNS root dot. A source domain/input/website value has its protocol, path, port, and a leading www. stripped, then exactly one trailing . removed — example.com. canonicalizes to example.com, but example.com.. is rejected outright, since the remaining dot leaves an empty label that fails DNS-label validation. Independently verified against a 10,000-character path: the path is irrelevant, and the valid x.example hostname underneath it is still extracted correctly.
Contact-page matching requires an exact path segment, never a substring. Only /contact/, /contact-us/, /about/, or /about-us/ as a full path segment qualify — /contacted and /aboutness never match, and only a URL resolving to the row's own company domain (no cross-domain redirect trick, no embedded userinfo) is ever accepted.
Routes use source-supplied own-domain role mailboxes. Exact dictionary matching does not establish whether a mailbox is public, monitored or deliverable. Own-domain non-role addresses from emails are counted but not listed. Foreign addresses in thirdPartyEmails are deduplicated and counted; foreign addresses in emails are ignored without increasing that count. Use only contact data you may lawfully process.
Exact match beats fallback beats manual-research beats no route — never conflated. role_mailbox means a dedicated mailbox exists for exactly this department. generic_fallback_mailbox means no dedicated mailbox for this department, but a general mailbox exists (confidence: medium, still action: use_route). phone_research_route/contact_page_research_route mean no email route at all, only a phone or page (confidence: low, action: manual_research — a person still does the outreach). no_matching_route is a free diagnostic: an honest "unknown," never a fabricated address.
A late, high-priority address always wins, regardless of array position. An exact sales@ address placed after 999 personal-looking addresses is still correctly matched — the module scans the entire accepted array for every row, with no early-stop optimization that could let position bias the outcome.
Malformed addresses and URL-shaped domains are rejected before they can count toward anything. A malformed dot-atom local-part and an email domain that is actually a URL (path, port, query, fragment, credentials, or whitespace) are both rejected outright, whether for routing or for the exclusion counters.
Bounded, disclosed caps, applied only to display, never to the underlying decision: evidence capped at 12 entries per route (usually exactly one, since only the winning rule is recorded); alternateRoutes capped at 10; phones read up to 10 per row; sourceRowIndexes capped at 50 per route (sourceRowCount is the true total); bounded text fields capped at 300 characters, with the truncation ellipsis counted inside that limit. The first 200 entries of the business-diagnostic plus source-notice list are written. businessSummary.diagnosticsCount counts business diagnostics only; diagnosticsTruncated covers the combined initial list. Later result-size/cap notices are additional — verified against a 1,000-row batch (999 synthetic source-failure rows plus 1 real row): 200 diagnostics were written free, one further max_results_reached diagnostic followed a maxResults: 1 cap (201 free rows total), diagnosticsCount: 999, diagnosticsTruncated: true, and the one delivered paid route was still the correct real general match at sourceRowIndex: 999.
Budget behavior — read this before relying on a specific maxTotalChargeUsd value via the API. A positive maxTotalChargeUsd below the price of one route correctly delivers zero paid routes and one free budget_stopped diagnostic (output example 3, at $0.005 against a $0.007 floor tier). This Actor's billing layer corrects a known SDK quirk where a raw run option of literal 0 is otherwise reported back as unlimited — but that correction applies only to what this Actor's own runtime reads internally, not to how an uncorrected API caller's own tooling might interpret a literal 0 it set. When testing the zero-paid path via a direct API call, inspect the run's actual, effective options.maxTotalChargeUsd after it starts, and prefer a small positive value below every applicable tier's price (as in example 3) for certainty.
observedAt/sourceObservationWindow are computed per domain, before the display cap, and read only checkedAt. Every purpose result for a domain shares the exact same observation window, because one domain bucket backs every one of its purpose results — a domain requesting all five departments gets five identical observedAt/sourceObservationWindow values, not five independent measurements. The window is built from every accepted row for that domain before the 50-row sourceRowIndexes display cap, so sourceObservationWindow.totalRowCount can legitimately exceed the number of indexes actually listed in sourceRowIndexes. Only the exact row.checkedAt field is read; a row lacking it contributes nothing to the window (an honest null/lower validCount), never inferred from another field, the run's own processing time, or "now".
Delivery is not transactional, and a FAILED run does not mean "nothing happened." Each route is written to the Dataset and then charged as two separate steps; a run failing between them can leave an effectively free, unconfirmed write with no automatic retry — no cross-run exactly-once guarantee. usefulResults reflects routes found before budget/result-cap application; failed reflects oversized-row drops (over 64 KiB); paid/delivered reflect only confirmed, charged deliveries. If pricing, charge-limit, or event-counter state can't be verified mid-run, the run finalizes FAILED with a safe explanation — fatalFailure/deliveryUncertain/partialOverall tell you which applies. Inspect the original run's Dataset and OUTPUT/SUMMARY record before a manual retry — a blind retry after an ambiguous outcome can duplicate paid routes.
Decision routing
status: role_mailbox_matched,action: use_route,confidence: high— the strongest outcome: a dedicated departmental mailbox exists at this company. Use it directly.status: generic_fallback_mailbox,action: use_route,confidence: medium— no dedicated mailbox for this department, but ageneralmailbox exists. Usable, but checkalternateRoutesfirst in case a sibling department has its own dedicated address.status: phone_research_routeorcontact_page_research_route,action: manual_research,confidence: low— no email route exists.routeValuegives a phone number or a verified contact/about page URL, but outreach is left to a person — this Actor does not call, message, or contact anyone.businessPartial: true/partial: true— either the source disclosed incompleteness for this domain, more than 50 source rows contributed (a display cap only, not data loss), or the route is a lower-confidence phone/page fallback. Worth a second glance.- Free diagnostic rows (
found: false) — never a routing decision.missing_domainmeans the row couldn't be interpreted;no_matching_routemeans the domain was read but had no role mailbox, fallback, phone, or contact page for the requested department — an honest "nothing to route," not a system failure;budget_stopped/max_results_reachedmean a run-level cap was hit.
Commercial playbooks
Departmental inbox triage. Run with targetPurposes set to just your team's department (e.g. ["sales"]) and route straight into that team's CRM queue — every row already carries the evidence for why it routed that way.
Cross-department handoff from one shared dataset. A single upstream extraction run can feed multiple downstream runs of this Actor, one per department, each producing its own routing table from the same source data — no need to re-scrape per team.
Escalating manual-research accounts. Filter delivered routes to action: manual_research to build a worklist for accounts where no dedicated or fallback mailbox exists.
Data-quality triage on your own pipeline. A company with a high excludedNonRoleEmailCount relative to its total email count suggests your upstream extractor surfaces personal-looking addresses rather than departmental ones.
Repeatable batch cadence. Every route carries its own dataset/run provenance separately from processedAt, so successive batches can be compared on routeTypeCounts trends over time.
Integration recipes
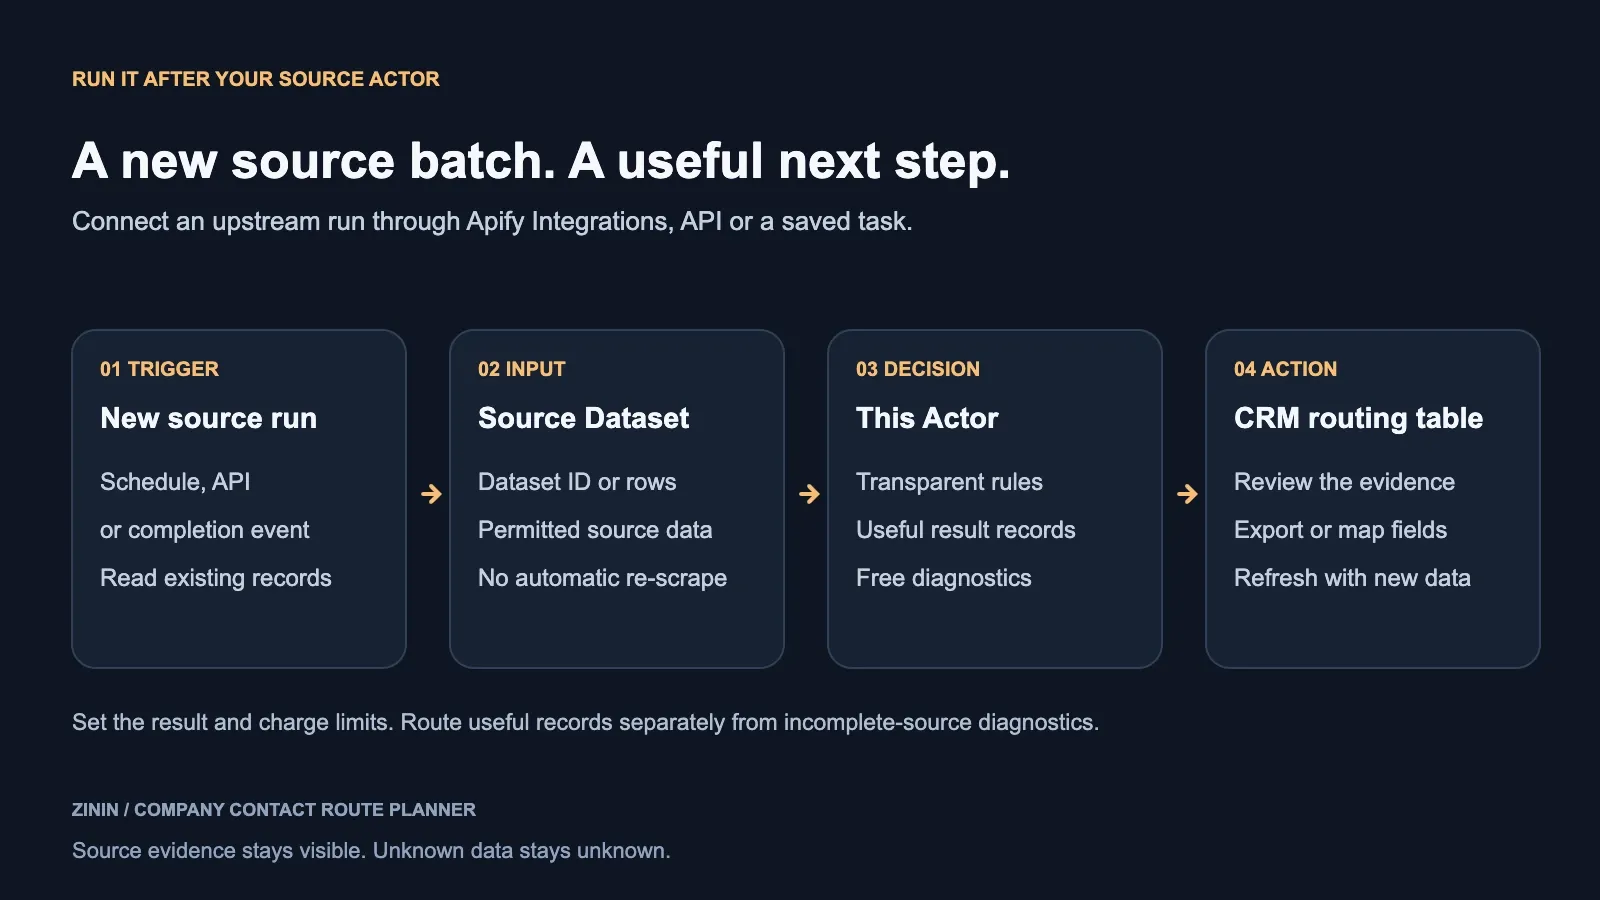
This Actor's ID is Cae9iduRC0BFptpvP. A natural upstream source is Website Contact Scraper (Actor ID CHnXcdLMha9GvwRh5); a Google-Maps-with-contact-details-shaped source works identically. The recipes below describe how to configure each mechanism — not a claim any specific trigger is currently installed. A saved public example is available in the Tasks tab.
1. Console-native chaining (no code). On your contact-extractor Actor's run page, open Integrations, add an "Actor/task run" action targeting this Actor, and let the Integrations UI populate the payload with {{resource.defaultDatasetId}}. Map that value explicitly into this Actor's datasetId field — not the generic payload pass-through alone — to request scoped READ access under LIMITED_PERMISSIONS; authorization remains conditional on the resource picker or integration. Documented at docs.apify.com/integrations/actors.
2. Direct webhook (POST /v2/webhooks), full recipe. Configure a webhook on your upstream contact-extractor Actor for the ACTOR.RUN.SUCCEEDED event, scoped to that specific Actor via its condition.actorId, targeting this Actor's run-creation endpoint:
Submit this to POST https://api.apify.com/v2/webhooks with your own Authorization: Bearer <APIFY_TOKEN> header. The {{APIFY_TOKEN}} placeholder inside headersTemplate is never a literal token embedded in the template — it is filled in from your own secrets-provisioning store at the moment the webhook is registered. doNotRetry: true avoids a duplicate-charge risk from an automatic webhook retry. datasetId is set explicitly alongside payload.resource.defaultDatasetId — the resource picker or an authorized integration can request scoped READ access; a raw datasetId or payload.resource reference alone does not grant it. A positive maxTotalChargeUsd on the request URL caps this chained run's spend; per Evidence and boundaries, avoid the literal value 0 here.
3. API-level integration outside webhooks. Per docs.apify.com/integrations/actors/integrating-actors-via-api, the same isApifyIntegration/shouldInterpolateStrings/string-encoded payloadTemplate shape from recipe 2 applies to any integration definition your own tooling submits against this Actor's ID.
4. Export / CRM-adjacent mapping. Every run's Dataset supports the platform's standard export formats (CSV, Excel, JSON) via the Console or GET /v2/datasets/{datasetId}/items?format=csv. Map domain, targetPurpose, routeType, routeValue, action, and alternateRoutes into a CRM import.
5. Generic automation tools (n8n, Zapier, Make). Use each tool's generic Apify/HTTP node to call run-sync-get-dataset-items on this Actor's ID with a JSON body containing datasetId and your chosen targetPurposes/maxResults — a plain authenticated HTTPS POST, no native integration support required.
Public searchability as an integration target does not imply a recommended-placement partnership with any upstream Actor — per docs.apify.com/integrations/actors/integration-ready-actors, that requires a separate request this Actor has not made. No outreach to any third party was performed to produce this README.
Operating guide
- Confirm your source batch shape first. Spot-check a few rows against Input contract — specifically that each has a
domain/input/websitefield. A batch missing domain data will produce mostlymissing_domaindiagnostics. - Pick your departments deliberately.
targetPurposesdirectly controls how many billable routes a single company can produce (up to 5) — narrow it to just the department(s) your team needs if routing at scale. - Start with a small
maxResultson a new source. SetmaxResultslow (e.g. 5) to confirm output matches your expectations before committing to a full batch. - Set
maxTotalChargeUsddeliberately, and check the effective value after the run starts. Use the platform run option, not an Actor input field. Calling the API directly and want zero paid routes guaranteed? Use a small positive value below $0.007 rather than literal0— see Evidence and boundaries. - Read the
OUTPUT/SUMMARYKey-value store record, not just the Dataset row count. It reportsrequested/delivered/paid/free/failed, whetherbudgetStopped/resultsCappedended the run early,diagnosticsTruncated, andsourceCoverage-level completeness. - If a run finalizes
FAILED, inspect before retrying. Check that run's Dataset andOUTPUTrecord for what was actually delivered and charged before deciding whether to re-run — a blind retry can duplicate already-successful paid routes. - Re-running is always new billing. There is no dedup key across runs. Treat "run again" as "process (and pay for) this batch again," reserved for a genuinely new or updated batch, not a routine safety retry.
FAQ
Does this Actor scrape websites or Google Maps itself? No. It only reads an existing company-contact batch you or an upstream Actor already collected, and never fetches a page from the open web or starts another Actor.
Can I use a source other than Website Contact Scraper? Yes — any source producing rows with the fields in Input contract works identically, including a compatible Google-Maps-with-contact-details dataset.
Does a delivered route mean the mailbox will actually accept mail, or that I have permission to contact it? No. No MX/SMTP/deliverability checks are performed and no claim of permission to contact anyone is made. A route is a disclosed routing decision based on the source data's own contents, nothing more.
Why did my sales department route to the same address as general? Because no dedicated sales@-style mailbox exists at that company — the module fell back to the general department's own role mailbox (status: generic_fallback_mailbox, confidence: medium). Check alternateRoutes for a sibling department with its own dedicated mailbox.
What happens if a company has no email, no phone, and no contact page for a department? A free no_matching_route diagnostic — an honest "nothing to route," not a system failure or a fabricated address.
Are excluded addresses shown? No. Own-domain non-role addresses in emails are counted; foreign addresses are counted only from thirdPartyEmails, and foreign values in emails are ignored. Excluded strings are never output.
Can I set a hard spending cap for a run? Yes, via the platform's Max total charge (USD) run option. See Pricing and Evidence and boundaries for the literal-0 caveat via a raw API call.
Does re-running the same batch avoid double-billing? No. Every run is independent processing with no cross-run deduplication.
What does a FAILED run mean? Failure can occur during initialization, source access, transformation, pricing checks, storage, charging or summary persistence — it does not prove zero rows were written. Inspect the Dataset and event counters before retrying.
Is the "partial-columns" style example a demonstration of missing upstream data? No — see output example 2. It reuses the exact same real values as the healthy example, with only the source row's own partial flag set to true as a controlled test of the disclosed-incompleteness path.
Why can diagnostic counts differ? Only the first 200 business diagnostics plus source-read notices enter the initial write loop. businessSummary.diagnosticsCount counts business diagnostics, diagnosticsTruncated flags the combined-list cap, and later result-size/cap notices can raise total free above 200.
Why does excludedThirdPartyEmailCount sometimes look larger than 50? Because it is an exact count of the full scanned array, not the display-capped sourceRowIndexes list — the two caps are independent.
Sources and rights
This Actor reads only Datasets and runs your own Apify account token already has permission to read; it never uses another user's credentials and never starts an upstream Actor on your behalf. The public prefilled example is a curated, non-sensitive real snapshot of Apify's own public company-contact page (sourceActorId CHnXcdLMha9GvwRh5, sourceRunId fTQG832SGP7sB6hWk, sourceDatasetId Gt7XpREftdsw0Ebz7), observed 2026-09-22, reused with its original timestamp and field values unchanged — a saved example, not a live re-check, containing only allowlisted public fields with no reviewer identities. All output values in this README are copied verbatim from real runs of this Actor's accepted build; none are illustrative or invented, and these verification runs were the product owner's own cost, not customer sales or revenue evidence.
Related tools
Related tools for adjacent workflows in B2B lead generation and data enrichment.
| Actor | What it does |
|---|---|
| Company Lookup — Website & GLEIF Evidence | Pair it in the B2B lead generation and data enrichment workflow: Turn domains, company names, or exact LEIs into evidence-linked website and GLEIF observations with... |
| Lead List Cleaner - Dedupe, DNS & Email Hygiene | Pair it in the B2B lead generation and data enrichment workflow: Normalize mixed lead rows, deduplicate domains and emails, check DNS/MX evidence, score retained leads,... |
| Website Contact Scraper — Public Emails & Phones | Pair it in the B2B lead generation and data enrichment workflow: Find public company-site emails, phones, and social profiles with page-level evidence, best-contact... |


