
Teamtailor Scraper [Only $1/1K💰] | Jobs | ATS Careers Data
Pricing
from $0.90 / 1,000 results
Teamtailor Scraper [Only $1/1K💰] | Jobs | ATS Careers Data
Extract job postings from any Teamtailor career site — Polestar, Savills, Huel and thousands more. Get titles, full descriptions, locations, dates and company data as structured JSON for job boards, hiring-signal monitoring and EU recruitment research. No API key, no login.
Pricing
from $0.90 / 1,000 results
Rating
0.0
(0)
Developer
Ahmed Jasarevic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
19 days ago
Last modified
Categories
Features
Share
Teamtailor Scraper
Teamtailor Scraper extracts job postings from any Teamtailor career site — the applicant tracking system used by thousands of employers, from Polestar and Oatly to Doctors Without Borders, Arsenal FC and Huawei. It reads the keyless public jobs.json feed that every Teamtailor career site exposes and returns structured rows — title, URL, publish date, full HTML description, locations and the raw schema.org JobPosting — with no API key, no login and no browser.
Built for job boards, ATS aggregators, HR-tech teams, recruitment agencies and hiring-data analytics.
Monitor Teamtailor Career Sites and Build Job Databases
- Job posting monitoring and hiring-signal tracking — schedule daily runs to detect new openings at specific Teamtailor employers (e.g. Polestar, Savills, Huel).
- Building ATS job databases — collect open roles from Teamtailor career sites into one structured dataset.
- Niche job boards and aggregators — power a vertical job board (Nordic tech, EU startups, nonprofits) with normalized postings.
- Recruiting and talent sourcing — find which companies are hiring for a given role, skill or location.
- Job market and labour-market research — analyse hiring trends across Europe and beyond using structured location and date data.
- Multi-ATS recruitment pipelines — drop Teamtailor postings into the same pipeline as Greenhouse, Lever, Workable or Recruitee jobs.
How It Works
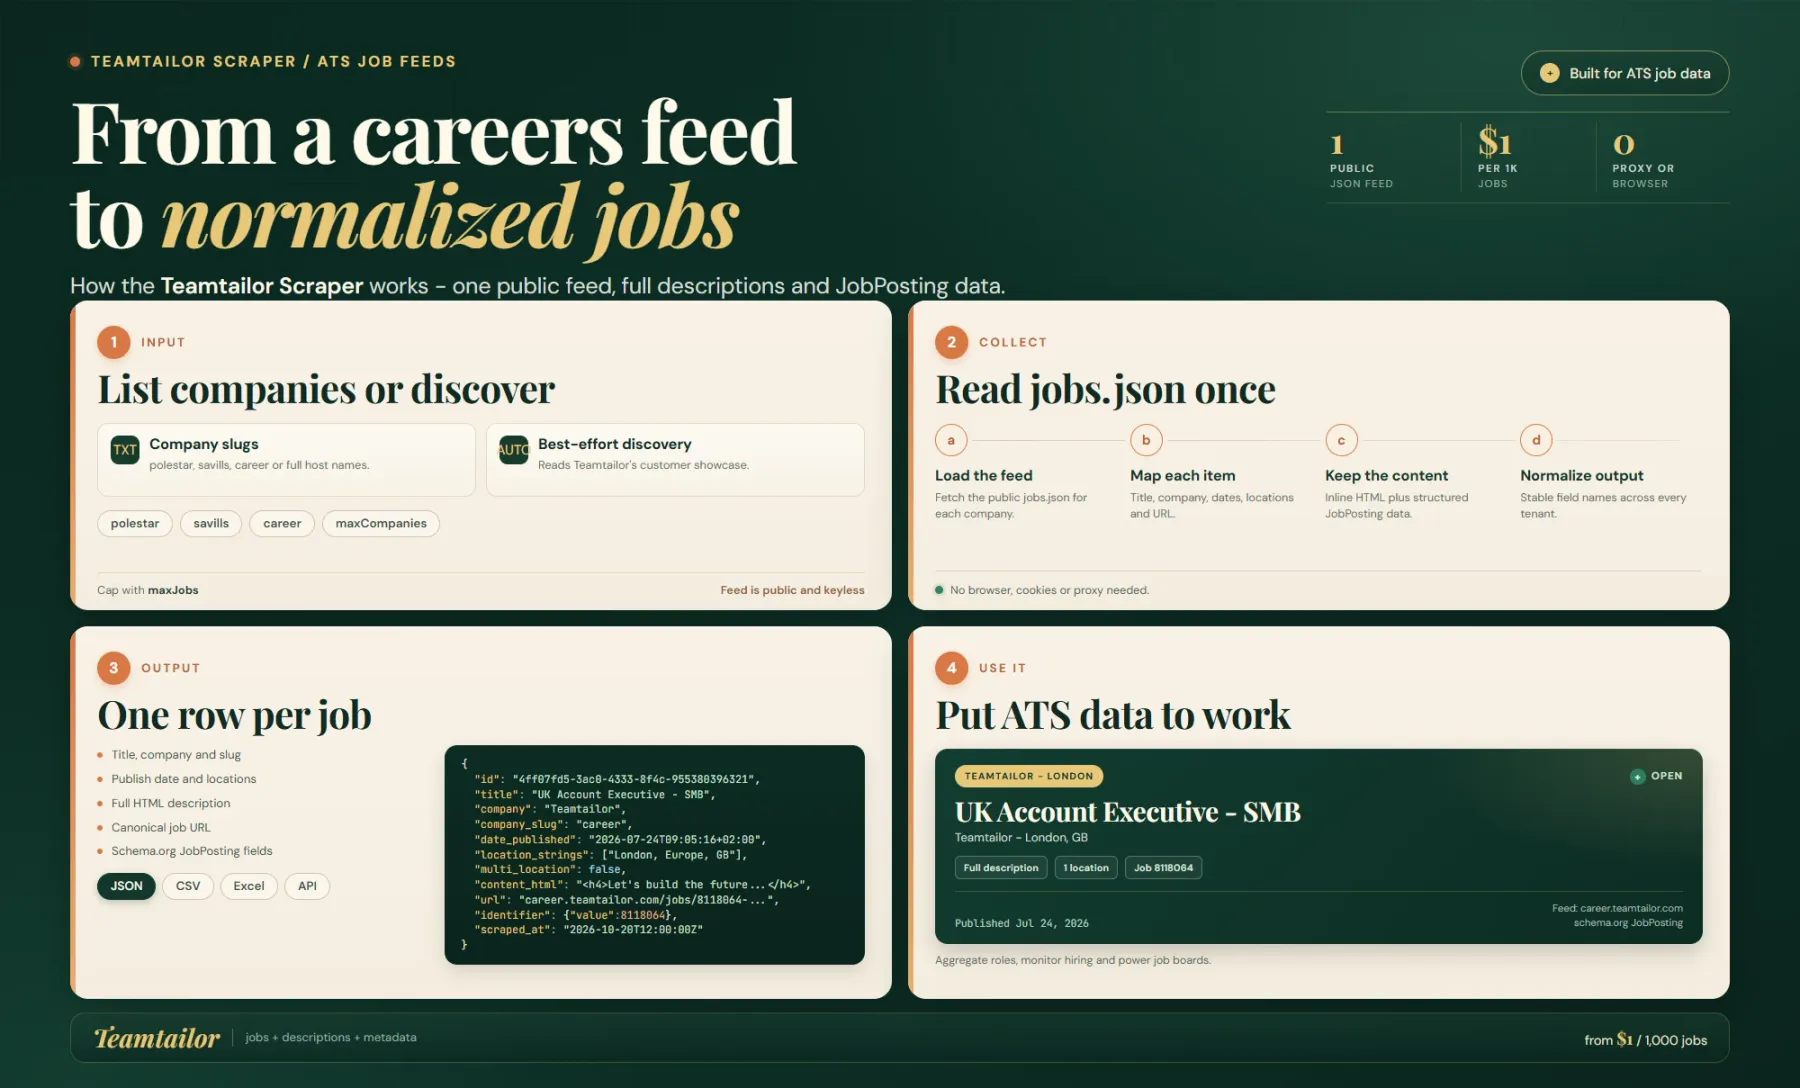
Every Teamtailor career site publishes a JSON Feed 1.1 document at /jobs.json. The Actor reads each item's inline content_html and embedded schema.org JobPosting object, so no second request per job is needed. Company discovery from the public showcase is available as a best-effort option.
Each row covers one job with its UUID, title, company, publish dates, locations, full HTML description, identifier, feed URL and raw JobPosting object.
The actor requests the public JSON Feed 1.1 document that every Teamtailor career site publishes:
It parses each entry in the feed's items array. Every item already contains the full job description in content_html and an embedded schema.org JobPosting object under _jobposting, with jobLocation (an array, so multi-location roles are represented natively) and hiringOrganization. Because the description is inline, no second request per job is needed.
The crawl is plain HTTP (CheerioCrawler) — no browser, no cookies, no login. The feed is served without bot protection, so no proxy is required.
Company discovery. Teamtailor publishes no public directory of customers, so the actor accepts an explicit list of companies in the companies input. As a convenience it can also discover companies: it reads Teamtailor's public customer showcase page, slugifies each customer name and probes its /jobs.json feed. Discovery is best-effort — it only resolves companies whose showcase name maps to their Teamtailor subdomain (in a test run, 12 of 24 showcase customers resolved). For complete coverage, supply your own companies list.
Volume note. Teamtailor returns up to 100 open jobs per feed page and adds a next_url when a company has more. This actor collects the jobs returned by each company's feed page.
Input Parameters
| Field | Type | Required | Default | Notes |
|---|---|---|---|---|
companies | string[] | No | ["career","polestar","savills"] | Career sites to scrape. Each entry can be a subdomain slug ("polestar"), a bare host ("polestar.teamtailor.com") or a full URL ("https://polestar.teamtailor.com/jobs.json"). Leave empty to auto-discover companies. |
discoverCompanies | boolean | No | false | Also discover companies from Teamtailor's public customer showcase page. Enabled automatically when companies is empty. |
maxCompanies | integer | No | 50 | Maximum number of company career sites to scrape in one run. |
maxJobs | integer | No | 1000 | Maximum number of job postings saved to the dataset. Free (non-paying) users are capped at 10 jobs. |
proxy | object (proxy) | No | Apify Proxy off | Standard Apify proxy configuration. Not required — the feed is public and keyless. |
Output Fields
| Field | Type | Description |
|---|---|---|
id | string | Teamtailor job UUID |
title | string | Job title |
url | string | Public job posting URL |
date_published | string | Feed publish date (ISO 8601) |
date_posted | string | schema.org datePosted |
valid_through | string or null | schema.org validThrough when present |
content_html | string or null | Full HTML job description |
company | string or null | Hiring organization name |
company_slug | string or null | Teamtailor subdomain slug |
company_career_site | string or null | Company career-site URL (hiringOrganization.sameAs) |
job_location | array | Normalized schema.org PostalAddress objects |
location_strings | string[] | Human-readable locations, e.g. ["London, GB"] |
multi_location | boolean | True when the job has more than one location |
location_count | integer | Number of locations |
employment_type | string or null | schema.org employmentType (usually absent in the public feed) |
identifier | object or null | schema.org PropertyValue identifier |
schema_org | object or null | The raw schema.org JobPosting object |
feed_url | string or null | Source feed URL |
scraped_at | string | Extraction timestamp (ISO 8601) |
Example Input
To let the actor find companies for you instead:
Example Output
Integrations & Automation
- Apify API — start a run programmatically and read results from the default dataset; every run also exposes the dataset as JSON, CSV or Excel.
- Webhooks — get notified when a run finishes and push new postings into your own systems.
- Zapier / Make / n8n — connect the actor through Apify's no-code integrations to write results to Google Sheets, Airtable, a database or a Slack channel.
- Scheduling — for hiring-signal monitoring, run the actor daily against your target companies and diff by
idto surface new openings; run it weekly for slower trend tracking.
Related Actors
- Career Site Job Listing API — one schema across dozens of ATS platforms (Teamtailor, Greenhouse, Lever, Workday, Ashby and more); use it when you need many ATS sources in a single run.
- LinkedIn Jobs Scraper — the broadest jobs source in the Store; pair it with Teamtailor data to cover both aggregators and first-party career sites.
- BambooHR Scraper — BambooHR-hosted job boards, the same structured job schema for a different ATS.
- Welcome to the Jungle Scraper — European tech job listings from Welcome to the Jungle.
- Apna Scraper — India blue-collar job listings and salary data.
Frequently Asked Questions
Why use this actor instead of the official Teamtailor API?
The official Teamtailor API is a JSON:API at api.teamtailor.com (regional stacks api.na.teamtailor.com and api.au.teamtailor.com). It requires a per-tenant API key generated in Settings → Integrations → API keys by a Company Admin, with Public, Internal or Admin scope — there is no aggregator key that spans multiple companies. This actor instead reads the keyless public jobs.json feed that each career site publishes, so you can collect jobs from any number of companies without a key and without admin access to their accounts. Use the official API when you own or administer a single Teamtailor account and need write access or non-public data; use this actor for read-only, cross-company public hiring data.
What are alternatives to this actor or to the Teamtailor jobs feed?
- Other Teamtailor scrapers in the Apify Store — several cover the same public feed; compare on price-per-result, description handling and location parsing.
- Multi-ATS actors — e.g. Career Site Job Listing API, which normalizes Teamtailor alongside Greenhouse, Lever, Workable and Recruitee in one schema.
- The official Teamtailor API — best when you administer a single account and need non-public fields.
- Rolling your own — fetch
https://<company>.teamtailor.com/jobs.jsonand follownext_urlyourself; you then own the parser, HTML stripping and location flattening.
How do I scrape Teamtailor job postings?
Pass the company's Teamtailor slug (e.g. polestar, savills) in the companies input and run the actor. Each run returns one row per open job with the description and locations already parsed — no API key, no browser.
Does Teamtailor have a public API or a jobs feed?
Teamtailor has an authenticated official API (per-account key required) and, separately, a public JSON feed at /<company>.teamtailor.com/jobs.json for every career site. This actor uses the public feed.
How can I get all jobs from a Teamtailor career site as JSON?
Run the actor with that company's slug; download the dataset as JSON, CSV or Excel from the Apify Console, or read it over the Apify API. Each item includes content_html (the full description) plus the raw schema_org object.
How do I monitor new job openings at a company that uses Teamtailor?
Schedule the actor to run daily against the companies you track, then compare runs by id to detect postings that appeared since the previous run.
What's the best way to build a job board from Teamtailor career sites?
Run the actor across your target companies (or enable discovery), then map the output fields — title, company, location_strings, url, date_published and content_html — into your board's schema. The dataset's overview view already surfaces title, company, location_strings, date_published and url.
For AI Agents & LLM Apps
Purpose: return one row per open job posting from Teamtailor-hosted career sites (title, URL, publish date, full HTML description, normalized locations, raw schema.org JobPosting).
Minimal working input:
Discovery variant (no company list needed):
Output fields: id, title, url, date_published, date_posted, valid_through, content_html, company, company_slug, company_career_site, job_location, location_strings, multi_location, location_count, employment_type, identifier, schema_org, feed_url, scraped_at.
Behaviors an agent should know:
- If
companiesis empty, company discovery is enabled automatically — the actor reads Teamtailor's public showcase page and probes candidate feeds. maxJobscaps the dataset size. Free (non-paying) runs are hard-capped at 10 jobs, regardless ofmaxJobs; only paying runs reach the configuredmaxJobs.maxCompaniescaps how many explicitly provided feeds are scheduled; discovery adds further feed requests on top, bounded by an internal request cap (maxCompanies + 5, hard ceiling 500).proxydefaults to off; the feed is public and no proxy is required.employment_typeandvalid_throughare frequentlynull— the public feed usually omitsemploymentTypeandvalidThrough.- The actor reads the jobs returned by each company's feed page (Teamtailor returns up to 100 open jobs per page).
Billing: pay-per-result — $1 per 1,000 dataset items ($0.001 each), plus a small per-run start fee. Budget from the expected number of job rows.
Legal & Compliance Disclaimer
This actor is an independent tool and is not affiliated with, endorsed by or sponsored by Teamtailor.
It accesses only the publicly available jobs.json feed that Teamtailor career sites publish; it does not log in, bypass authentication, solve CAPTCHAs or access non-public data.
Job data is published for public consumption, but you are responsible for ensuring your use complies with Teamtailor's and each career site's terms of service and with applicable data-protection law (including GDPR where EU personal data is involved).
Job descriptions may contain recruiter or company contact details. Do not use such data for unsolicited commercial outreach in violation of applicable law (e.g. CAN-SPAM, GDPR, TCPA).
SEO Keywords
teamtailor scraper, teamtailor jobs scraper, teamtailor job scraper api, teamtailor jobs.json feed, scrape teamtailor jobs, teamtailor api alternative, teamtailor career site scraper, teamtailor ats scraping, ats job scraper, job posting scraper, job board data, careers page scraper, jobs feed scraper, hiring data api, recruitment data scraping, job market data, extract job postings, jobs to json, jobs to csv, greenhouse lever workable jobs scraper, nordic jobs data, eu jobs data, polestar jobs, savills careers, hiring signal monitoring


