
YouTube Transcript Scraper | Text + Timestamps, Any Language
Pricing
from $2.80 / 1,000 video results
YouTube Transcript Scraper | Text + Timestamps, Any Language
Get the transcript of any YouTube video as clean text and timestamped lines: manual captions or auto-generated ones, in the language you choose, plus title, channel, length and views. Paste video URLs or IDs, including Shorts. You only pay for videos that have a transcript.

YouTube Transcript Scraper: text and timestamps, any language
Turn YouTube videos into text. Paste video URLs or IDs and get each video's transcript as clean full text and as timestamped lines, together with the title, channel, length and view count. It reads captions written by the uploader and YouTube's auto-generated captions, in the language you prefer.
By default you only pay for videos that have a transcript. Videos without captions, private or deleted videos are reported in the log and not charged. If you turn on "Also return videos without a transcript", those videos are added to the results as rows of their own and are charged like any other result.
Pay per result · No login, no API key · Public data only · Tested daily · LLM-ready JSON for AI agents (MCP)
🛠️ What does YouTube Transcript Scraper do?
- 📝 Clean full text and timestamped lines for every video, with title, channel, length and view count.
- 🌐 Any language. Reads captions written by the uploader and YouTube's auto-generated captions, in the language you prefer.
- 💸 By default you pay only for videos that have a transcript. Videos without captions, private or deleted videos are not charged.
- 🛡️ Built to get through blocking. Requests go out with a real browser fingerprint through rotating proxies, and a blocked request is retried from a fresh IP. A result that could not be completed is never charged.
What people use it for
- AI and RAG pipelines. Feed video content into LLMs, summarizers, vector stores and agents.
- Content repurposing. Turn talks, podcasts and tutorials into articles, newsletters and social posts.
- Research and analysis. Search and analyze what was said across hundreds of videos.
- SEO. Mine competitors' videos for topics, keywords and questions.
- Subtitles and translation workflows. Get timestamped lines ready to convert to SRT or VTT.
📊 What data can you extract?
Every result is one JSON object (one row in CSV or Excel) with these fields:
| Field | Meaning |
|---|---|
videoId, url | The video |
title, channel, channelId, lengthSeconds, viewCount | Basic video details |
isLiveContent | true for a live stream or the recording of one |
transcript | The whole transcript as one text |
segments | Every caption line with its start time and duration in seconds (when timestamps are on) |
wordCount | Number of words in the transcript |
language, languageName | The language of the returned transcript |
isAutoGenerated | true when the captions were generated by YouTube's speech recognition, false when the uploader provided them |
availableLanguages | Every caption language the video has |
hasTranscript, unavailableReason | Only relevant when you turn on "Also return videos without a transcript": why a video has none |
🚀 How to use YouTube Transcript Scraper
- Create a free Apify account and open this Actor.
- Add your videos, one per line: full URLs,
youtu.belinks, Shorts links, embed links or plain video IDs. - Set your preferred languages in order, for example
en,es. The first language the video has is used. - Decide whether to use another language when none of yours exist, and whether you need timestamped lines.
- Run it and download the results as JSON, CSV or Excel, or connect them through the API.
📥 Input example (JSON)
📤 Sample output (JSON)
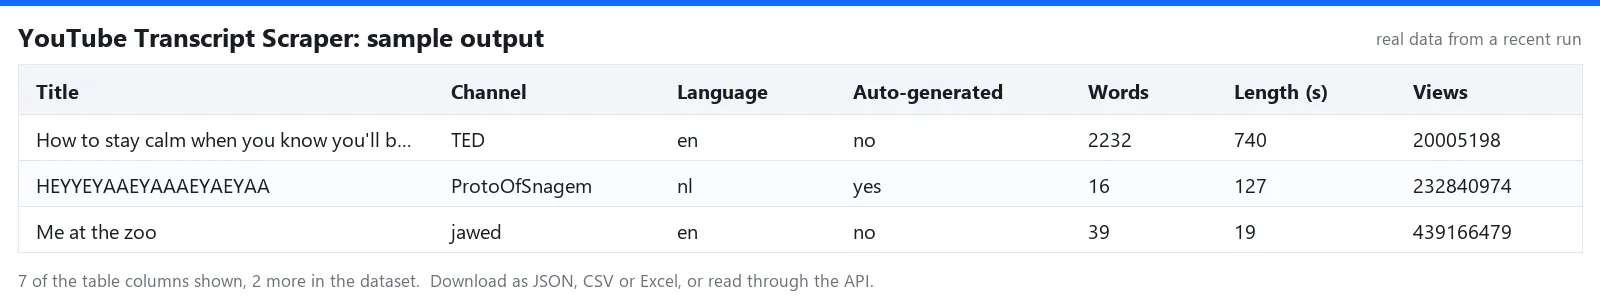
One result per video. The lists are shortened here.
🤖 Use it with AI agents, MCP and the API
The output is clean JSON with stable field names, ready for LLM pipelines, RAG and agent tools without extra parsing.
- AI agents and MCP (Claude, ChatGPT, Cursor and others). Add the Apify MCP server with this Actor as a tool:
https://mcp.apify.com?tools=akatra/youtube-transcript-scraper. The agent can then run it and read the results by itself. - API. Start a run and get the results in a single call:
- No-code tools and SDKs. Works with Make, n8n, Zapier and LangChain through Apify's integrations, and with the Apify clients for Python and JavaScript. Schedule it and send the results to a webhook, Google Sheets or your own database.
💰 Pricing: pay per result
You pay per result. By default a result is a video with a transcript; with "Also return videos without a transcript" on, every video you submit becomes a result. Nothing is charged for empty runs beyond a tiny start fee. See the price on the Pricing tab. The price is the same for a one-minute Short and a three-hour podcast. There is no subscription or rental fee. New to Apify? The free plan includes $5 of platform credit every month, enough for about 1,200 videos with this Actor, and no credit card is needed.
🚦 Run status and error messages
Every run ends with a plain status message, so automated workflows (API, Make, n8n, AI agents) can tell what happened without reading the log:
| Situation | What you get |
|---|---|
| Finished normally | Saved N videos. |
| No video has a transcript | The run succeeds with No transcripts saved. The videos have no captions in the requested languages, or are unavailable. You pay only the start fee. |
| Some videos have no transcript | N videos have no transcript and were not charged. (With 'Also return videos without a transcript' on, they are returned and charged.) |
| YouTube kept blocking some videos | Skipped N videos whose details stayed blocked (not charged). |
| Missing or unsupported input | The run fails at once and the log names the field to fix. Nothing is scraped. |
| Your maximum charge is reached | Stops cleanly with Stopped at your maximum charge limit. Everything saved so far stays in the dataset. |
ℹ️ Good to know
- Captions written by the uploader are preferred over auto-generated ones in the same language. A request for
enalso accepts regional variants such asen-USoren-GB. Different scripts are never mixed up:zh-Hansdoes not returnzh-Hant. - One run handles up to 20,000 videos. Start another run for more.
- Videos with no captions at all cannot be transcribed by this scraper; it reads YouTube's captions and does not run speech recognition itself.
- Private, deleted and age-restricted videos, and live streams that are still running, have no transcript available without logging in.
- A video that stays blocked after all retries is skipped and not charged. The run's status message tells you how many were skipped, so you can run them again.
- If you set a maximum charge for a run, the scraper stops as soon as that limit is reached.
- Turn off timestamped lines when you only need the text: results get several times smaller.
- No personal data beyond the public channel name is collected.
📝 Changelog
- 2026-10-02 README restructured: data table, API and MCP examples, run status messages.
- 2026-10-02 Better language matching (writing system, manual captions first) and clearer reasons for unavailable videos, after an independent audit.
- 2026-10-02 First release: full text and timestamped lines, any language, videos without a transcript not charged.
⚖️ Legal and privacy
This scraper is an independent tool and is not affiliated with, endorsed by, or sponsored by YouTube or Google. "YouTube" is a trademark of its owner and is used here only to show which website the tool works with. Videos and their transcripts belong to their creators. Use the data in line with the laws that apply to you and the source site's terms.
The source site's name and logo are trademarks of their owner and appear here only to identify the website this tool works with. The Actor reads only pages that are public without logging in. How you store and use the data is your responsibility: follow the laws that apply to you, such as GDPR and CCPA.
🔗 More scrapers from Akatra
- Indeed Jobs Scraper: 💼 job ads from Indeed in 30 countries, with yearly salary and only-new mode.
- Google News Scraper: 📰 news by keyword or topic in 50 editions, with the real article URLs.
- Google Trends Scraper: 📈 interest over time, by region, and rising related queries.
- Google Ads Transparency Scraper: 🔎 every ad a company runs on Google, with regions and dates.
💬 Support
Found a bug or need a field that is missing? Open an issue on the Issues tab and we usually reply within a day.


