
LinkedIn Jobs Scraper | $0.9/1K | No Login (Real-Time)
Pricing
from $0.90 / 1,000 job extracteds
LinkedIn Jobs Scraper | $0.9/1K | No Login (Real-Time)
Collect public LinkedIn job listings and organize available salary, work-mode, seniority, skills, benefits, freshness, application, and company hiring signals. Filter by role, location, experience, type, age, or remote preference. JSON and CSV export. $0.9/1K successful jobs.
Pricing
from $0.90 / 1,000 job extracteds
Rating
0.0
(0)
Developer
Apivault Labs
Maintained by CommunityActor stats
0
Bookmarked
37
Total users
4
Monthly active users
18 hours ago
Last modified
Categories
Share
LinkedIn Jobs Scraper -- Recruitment Intelligence
Automate it in n8n
Install
n8n-nodes-apivault-linkedin-jobsand import the ready-to-use hiring signal workflow. Add your Apify API credential, replace the sample keyword and location, and run it.
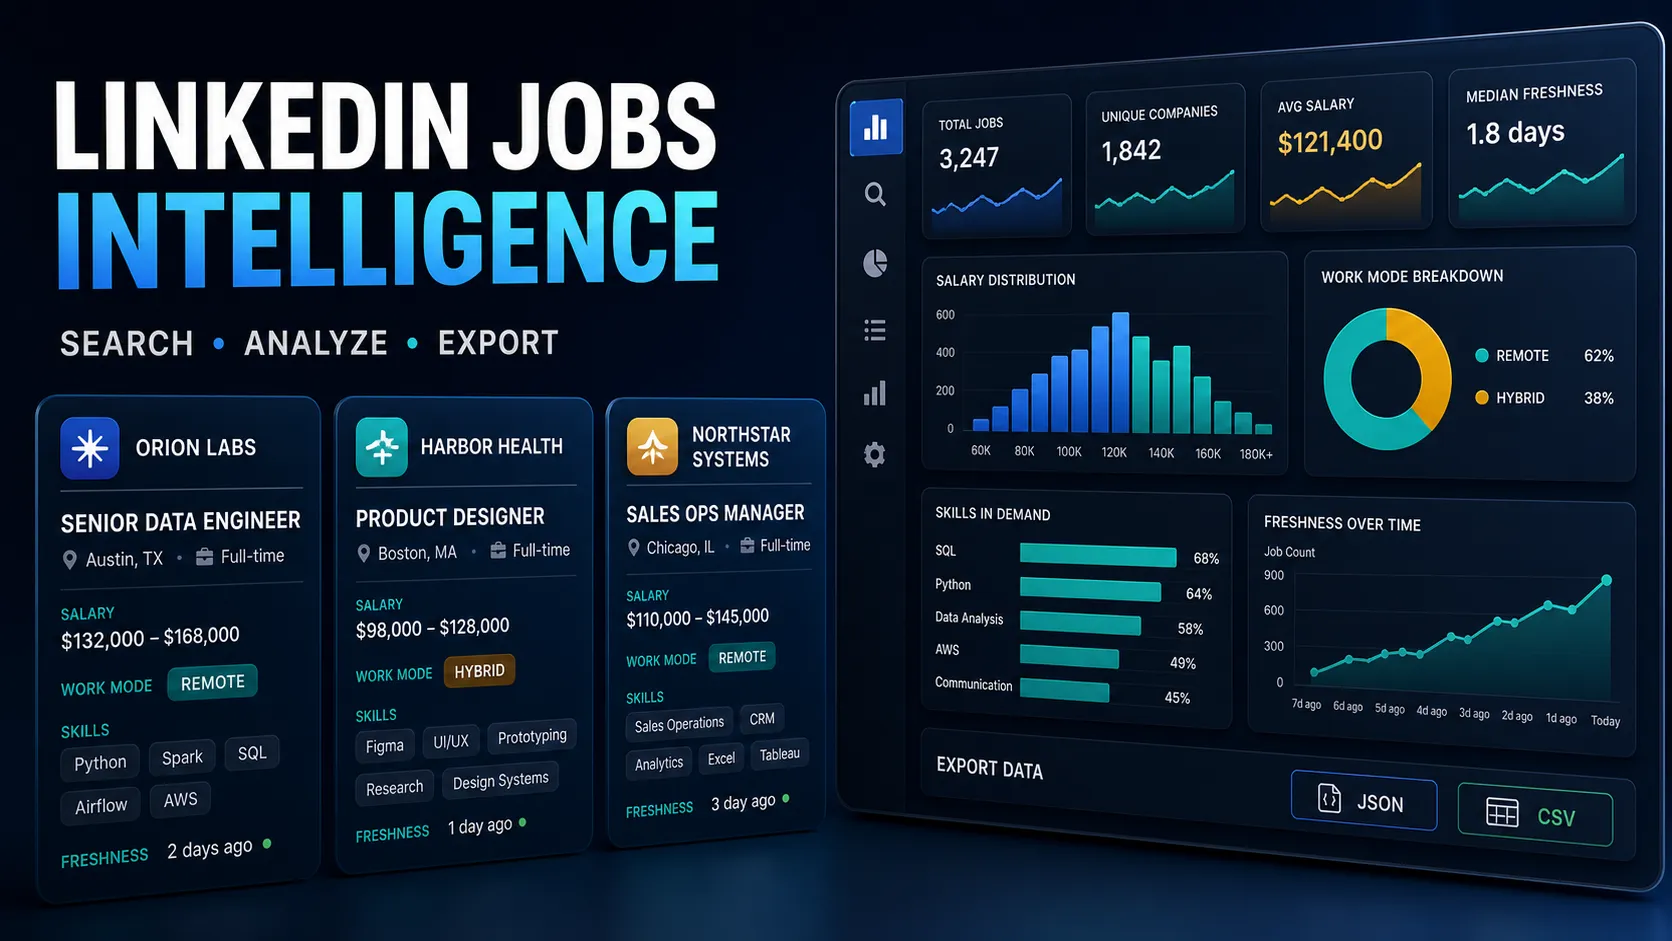

Collect public LinkedIn job listings and turn them into structured hiring-market data.
Search by role and location, apply common job filters, compare companies, and organize available salary, work-mode, seniority, skill, benefits, freshness, and application signals in one dataset.
Built for job-market research, recruitment operations, compensation analysis, workforce planning, and responsible HR-tech prospecting.
What you can do
- Search job listings by keywords and location.
- Filter by experience level, employment type, posting age, or remote preference.
- Collect available descriptions, salary details, application links, company information, and posting dates.
- Normalize fields for easier comparison across listings.
- Extract job-related skills, benefits mentions, seniority, and work-mode signals.
- Compare hiring activity by company and job category.
- Export results through Apify as JSON, CSV, Excel, XML, or RSS.
- Save optional summary, top-company, and top-job research records.
Fields vary by listing, market, language, and time. Missing source data is not fabricated.
Quick start
MCP and AI-agent usage
The input is organized as a numbered workflow: choose the source, define the
search, cap the result count, add filters, select enrichment, and choose an
output preset. For a first tool call, use workflow: "auto", maxResults: 25,
and outputPreset: "compact" or "recruiting".
compactkeeps the core role, company, location, compensation, application, and canonical URL fields to reduce tokens.recruitingadds skills, seniority, benefits, applicant, and hiring-signal fields for normal research.fullreturns every available field and preserves the legacy JSON shape.
Every completed run writes SUMMARY; skipped inputs and diagnostics are stored
in ERRORS instead of being mixed into the paid jobs Dataset. API integrations
that omit the new workflow, maxResults, and outputPreset fields retain the
legacy behavior.
Search from a LinkedIn URL
Instead of keywords, paste one or more LinkedIn jobs search URLs (open linkedin.com/jobs/search in an incognito window, apply filters, copy the full URL from the address bar). When urls is provided it replaces the keyword search; results from multiple URLs are merged and deduplicated.
URL filters that still work are used as-is: date posted (f_TPR), company (f_C), Easy Apply (f_AL), and under 10 applicants (f_EA). Since August 2026, LinkedIn's AI-powered search no longer supports the old experience-level, job-type, and workplace URL filters -- those selections are converted into natural-language terms and appended to the search keywords instead (for example f_WT=2 becomes the term "remote").
Remote roles posted recently
Salary-focused market research
Data you can collect
| Category | Example fields |
|---|---|
| Job | jobTitle, companyName, location, jobType, description |
| Links | jobUrl, jobCanonicalUrl, applyUrl, companyLinkedinUrl |
| Timing | postedDate, postedAtIso, postedAtTimestamp, daysSincePosted, freshness_tier, expireAt |
| Compensation | salaryRaw, salaryMinUsd, salaryMaxUsd, salaryMedianUsd, salaryCurrency |
| Work details | workMode, workplaceTypes, workRemoteAllowed, seniority_normalized, yearsExperienceMin, educationRequired |
| Skills and benefits | skillsRequired, softSkills, certifications, benefit mention flags |
| Application | applyMethod, applicantsCount, visaSponsorship, insights |
| Job poster | jobPosterName, jobPosterTitle, jobPosterPhoto, jobPosterProfileUrl (when LinkedIn shows the hiring team) |
| Company details | companyWebsite, companyEmployeesCount, companyDescription, companyIndustry (with includeCompanyDetails) |
| Company research | companySizeRaw, companyFundingSignal, company hiring count |
| Research signals | recruiterScore, recruiterTier, freshness and hiring-urgency indicators |
Example output
This example is fictional. Company, role, values, and URLs are illustrative.
Always open the source listing to verify current salary, location, availability, requirements, and application instructions.
Optional listing depth
deepFetchAll requests additional available detail for every collected job, such as fuller descriptions, salary information, seniority, application method, applicant count, and industry fields. Disable it for a lighter discovery run.
deepFetchTopN can limit deeper collection to a smaller set of companies when you only need detailed records for shortlisted opportunities.
Additional fields are availability-dependent and may be absent even when deeper collection is enabled.
Understanding normalized fields
Salary
Salary values can be normalized into USD and annualized for easier comparison. Keep salaryRaw and salaryCurrency for context. Exchange rates, pay periods, bonuses, equity, local taxes, and ambiguous listing text can affect comparability.
Work mode and seniority
workMode and seniority_normalized are text-based classifications. Treat unknown as a valid result and verify hybrid schedules or seniority expectations in the original listing.
Skills, benefits, sponsorship, and education
These fields summarize terms mentioned in job text. A mention does not guarantee that a benefit is offered, a visa will be sponsored, or a qualification is mandatory. Read the complete listing before making decisions.
Company hiring signal
recruiterScore is an optional 0-100 prioritization aid for company hiring-market research. It summarizes available listing signals such as freshness, activity, compensation disclosure, role characteristics, and job-text depth.
It is not a candidate score and must not be used to rank people or make automated employment decisions. It also does not guarantee that a company is buying recruitment software or actively responding to vendors.
DEI and pay-transparency indicators
Optional fields can identify relevant phrases and salary disclosures in listing text. These are screening signals only:
- They do not establish a company's actual workplace practices or values.
- They do not determine legal compliance.
- Laws and coverage rules vary by jurisdiction, employer, role, date, and listing context.
- Review the original posting and obtain qualified legal guidance for compliance work.
Filters
Filter before saving results with:
minRecruiterScoreonlyWithSalaryonlyRemotededuplicateCompanieseasyApplyandunder10Applicants(still supported by LinkedIn search)- posting-age filter (
postedWithin) - experience level, employment type, and remote preference -- these are merged into the search keywords, because LinkedIn removed the corresponding search filters in 2026
Filters rely on the corresponding field being available or successfully classified.
Optional company details
When includeCompanyDetails is enabled (default), the Actor fetches the public LinkedIn company page of each unique company (up to 25 per run) and adds companyWebsite, companyEmployeesCount, companyDescription, and companyIndustry when available. Company pages can refuse guest traffic, so these fields may be absent; the phase is skipped automatically when the run's time budget is nearly exhausted.
Aggregate research records
When writeSummary is enabled, the run's Key-Value Store can include:
SUMMARY-- counts, salary statistics, work-mode mix, and common skills.TOP_HIRING_COMPANIES-- companies with multiple observed listings.TOP_JOBS-- jobs prioritized by the optional company hiring signal.
These records summarize only the collected run, not the entire employment market.
Pricing
The active price is $0.0009 per successful job result:
| Successful jobs | Result charge |
|---|---|
| 1 | $0.0009 |
| 100 | $0.09 |
| 1,000 | $0.90 |
| 10,000 | $9.00 |
A small Actor Start charge and Apify platform usage may also apply according to the pricing displayed before each run. Filtered or unsuccessful records are not billed as successful job-result events.
Common use cases
- Track demand for roles and skills by market.
- Compare public salary ranges and work-mode trends.
- Build a source list for recruiting operations or job-alert workflows.
- Monitor hiring activity across selected companies.
- Prepare structured research for ATS, HR-tech, or workforce-planning teams.
- Create spreadsheet or BI datasets from public job listings.
FAQ
Do I need a LinkedIn account?
No account is required for the public job-listing workflow supported by this Actor.
Is every field guaranteed?
No. Listing templates and available fields vary. Some jobs omit salary, applicant counts, descriptions, company details, or application links.
How many jobs will a page return?
The number varies by query, location, filters, current availability, and deduplication. maxPages limits the search effort, not a guaranteed result count.
Does it work outside the United States?
Core listing fields can work across markets. Some text classifications are more reliable in English, and salary normalization should be independently checked.
Can the data be used for hiring decisions?
Use the Actor for job and market research. Do not use inferred fields or company-level research scores as the sole basis for decisions affecting applicants or employees.
Related Actors
Support
Open an issue on the Actor page with a non-sensitive sample input and run ID. Remove account credentials, candidate information, and private company data before sharing diagnostics.
LinkedIn is a trademark of LinkedIn Corporation. This Actor is an independent tool and is not affiliated with or endorsed by LinkedIn.


