
Google Sheets Sync: Import, Export & Upsert Datasets
Pricing
from $0.08 / 1,000 row writtens
Google Sheets Sync: Import, Export & Upsert Datasets
Export any Apify dataset or actor run to Google Sheets, or import a sheet into a dataset: append, replace, upsert by key or mirror sync, retried through Google's rate limits. Runs after any actor as an integration. Share the sheet once; no Google sign-in. $0.10 per 1,000 rows.
Pricing
from $0.08 / 1,000 row writtens
Rating
0.0
(0)
Developer
CleanPull
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Features
Share
This Google Sheets sync sends any Apify dataset to Google Sheets, or reads a sheet into a dataset, in every way you need it: append, replace, upsert by key (update rows in place, add new ones), or mirror sync (also remove rows that are gone). Runs wait out Google's rate limits instead of failing, read datasets of any size page by page, and write 30,000 rows in under 10 seconds. Share the spreadsheet once with our address; no Google sign-in, nothing expires. Run it after any actor as an integration, on a schedule or through the API.
How to export a dataset to Google Sheets
- Share your spreadsheet with our service account as Editor, once (see Set up in 30 seconds below).
- Open Google Sheets Sync on Apify and paste the spreadsheet's URL into Spreadsheet; name a Tab (created if missing).
- Choose the data: a Dataset id, a Run, an Actor (its last successful run), a Task (its last successful run), a URL (JSON or CSV) or Raw data.
- Pick a Mode: append, replace, upsert or sync. For upsert and sync, list the Key fields (upsert, sync, incremental) that identify a row, such as
skuorurl. - Start the run. Open the Sheets written view to read each Sheet, Tab, Mode and the rows Added, Updated, Removed and Unchanged. To keep the sheet updated, add Google Sheets Sync as an integration on the actor or task whose results you want (see Sheets export after any actor below).
What the Google Sheets sync gives you
- "Put every run's results in my sheet." Run it after any actor through Apify integrations; the finished run's dataset is written automatically.
- "Keep one row per product and update its price." Upsert by
sku: changed cells are updated in place, new products added, nothing duplicated. Columns you added by hand are left alone. - "Mirror this dataset exactly." Sync adds, updates, and deletes, moves or marks rows that are gone.
- "A new tab every day," or "one tab per country."
- "Use my sheet as the input of another actor." Read mode turns a tab into a dataset with typed numbers, booleans and dates.
- "Only send rows I haven't sent before."
Google Sheets setup
Set up in 30 seconds
- Open your spreadsheet → Share → add
cleanpull-sheets-1@cleanpull-sheets.iam.gserviceaccount.comas Editor (untick "Notify people"). - Paste the spreadsheet's URL into Spreadsheet and choose what to write.
The first run links the spreadsheet to your Apify account with a small hidden tab (_cleanpull, holding only your Apify user id). Runs from other Apify accounts are then refused, so your spreadsheet's URL alone is never enough to write to it.
For heavy use, also share with cleanpull-sheets-2@… and cleanpull-sheets-3@… (same domain) to triple the throughput. Prefer your own credentials? Paste your own service account key, or OAuth client and refresh token, in the optional fields; nothing is then shared with us.
Sync modes
| Mode | What it does |
|---|---|
append | Adds rows below the existing data; new fields become new columns at the end |
replace | Clears the tab and writes the data |
upsert | Matches rows by keyFields; updates only the cells that changed, adds new keys |
sync | Upsert, and rows whose key is gone are deleted, moved to a removed tab, or marked with removedAt |
read | The tab's rows into the dataset (and the OUTPUT record); header row → field names, values typed |
modify | Cleans up the tab's own rows (dedupe, columns) in place; backs the tab up first, never clears a tab it can't fully rewrite |
backup / restore | Saves a tab's values and formulas to the actor's store; restores them by key |
clear | Empties the tab |
Google Sheets sync input
| Field | Key | What it does |
|---|---|---|
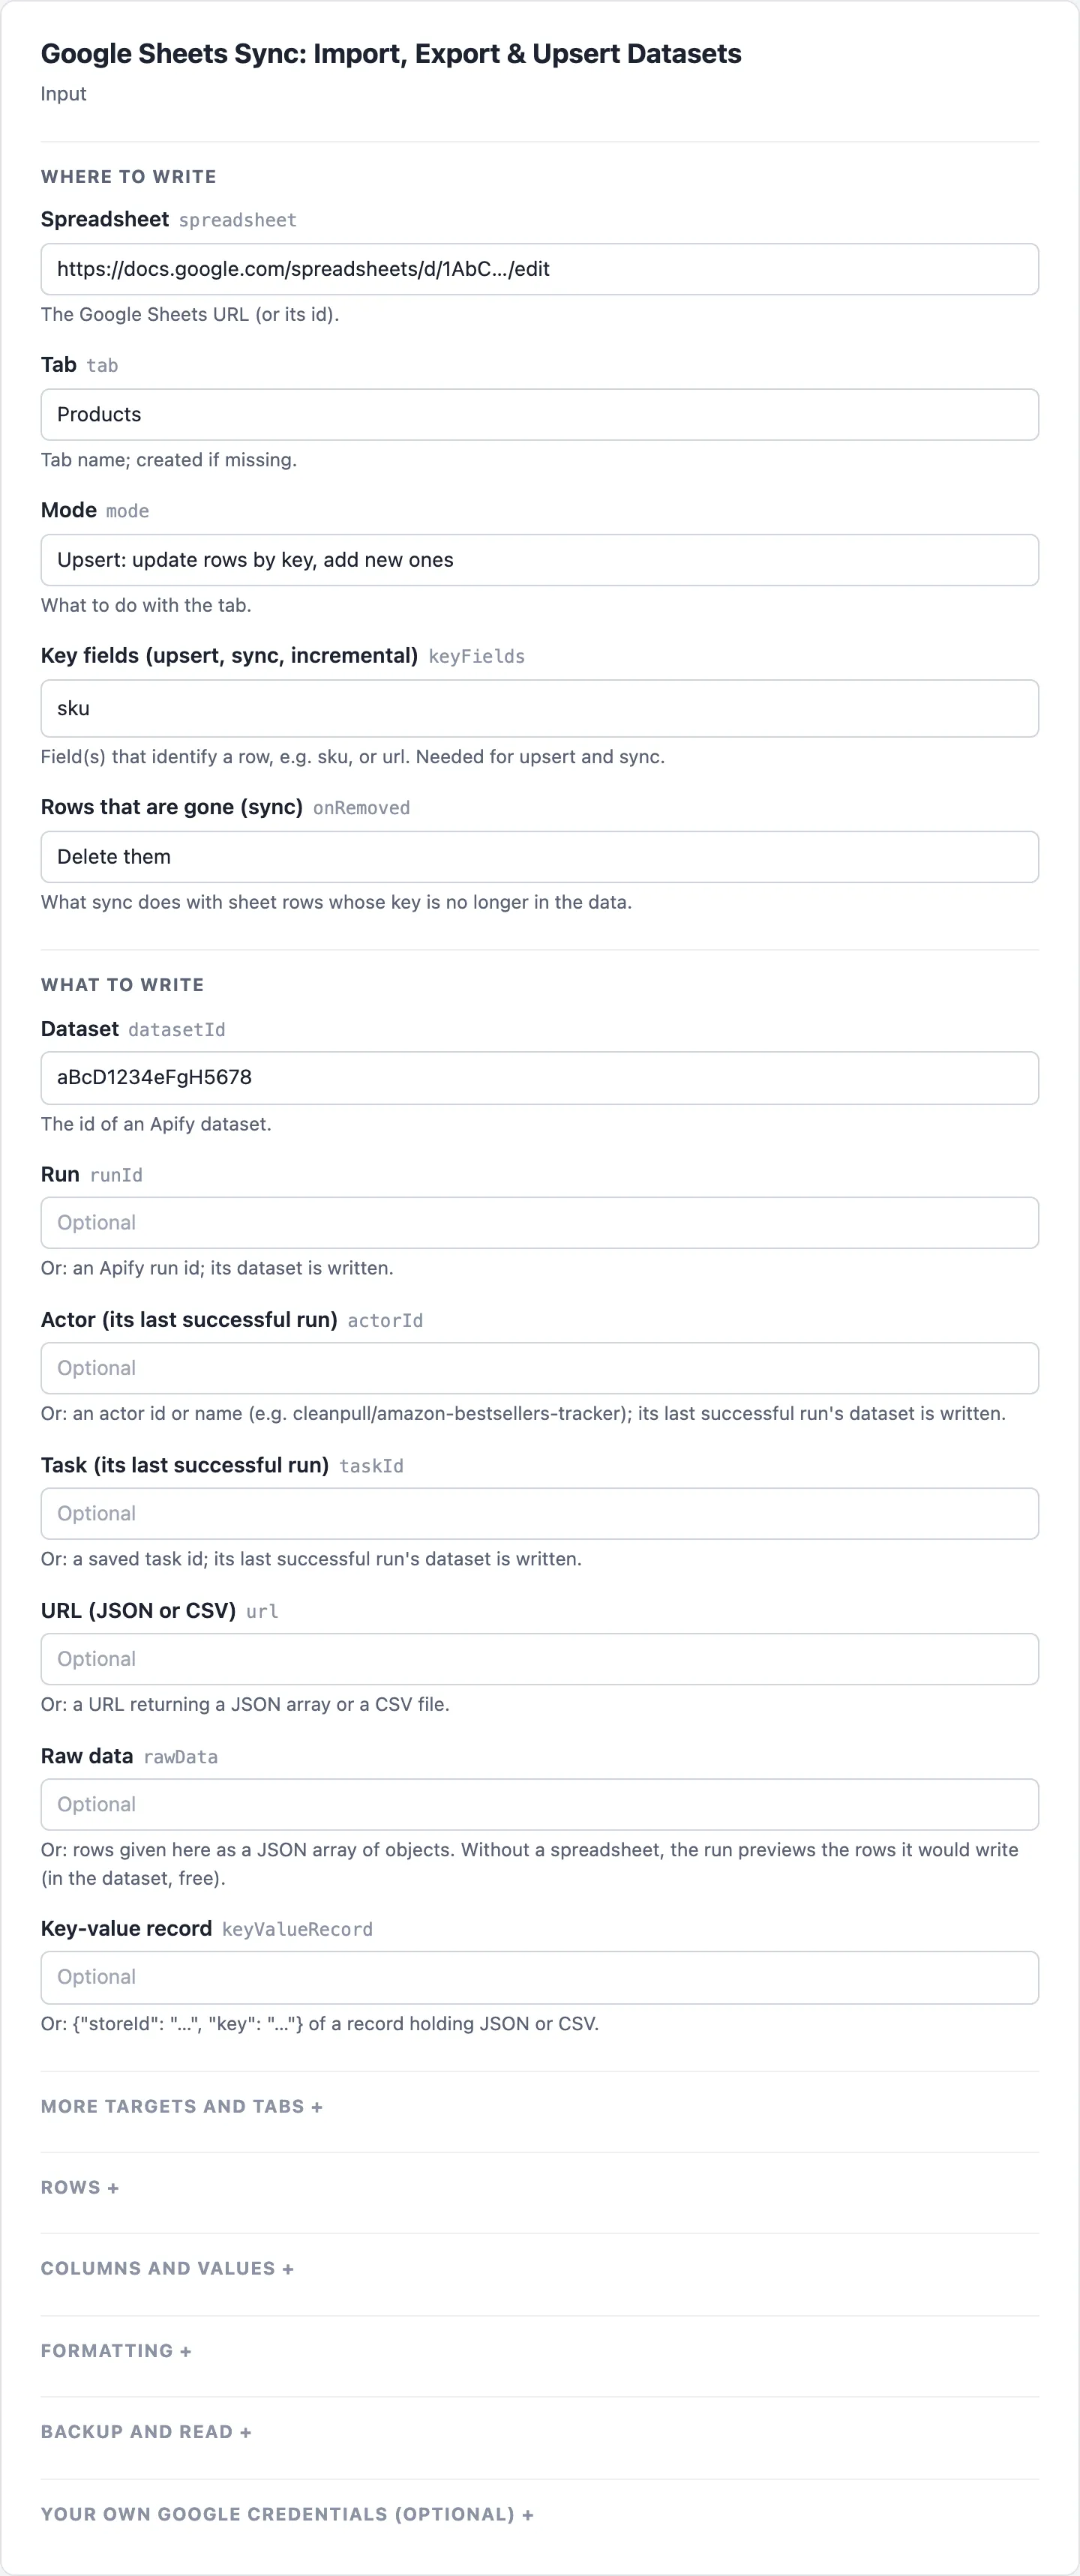
| Spreadsheet | spreadsheet | The sheet URL or id; a URL with #gid= targets that tab. Empty: a free preview of the rows a run would write |
| Tab | tab | Tab name, created if missing; {date}, {datetime}, {runId}, {value} placeholders |
| Mode | mode | See Sync modes (append by default) |
| Key fields (upsert, sync, incremental) | keyFields | Field(s) that identify a row, such as sku or url; needed for upsert and sync |
| Rows that are gone (sync) | onRemoved | Delete (the default), move to a removed tab, or mark with removedAt |
| Dataset, Run, Actor (its last successful run), Task (its last successful run), URL (JSON or CSV), Raw data, Key-value record | datasetId, runId, actorId, taskId, url, rawData, keyValueRecord | The data: a dataset, a run, an actor's or task's last successful run, a JSON or CSV URL, rows in the input, or a stored record |
| More targets | targets | Several spreadsheet / tab / mode sets in one run |
| Split into tabs by field | splitByField | One tab per value of a field |
| Only rows not sent before, Remove duplicates, Maximum items, Skip items | incremental, dedupe, limit, offset | Only rows not sent before; remove duplicates; how many |
| Columns | columns | Choose, order and rename columns (price: Price (USD)) |
| Columns first | columnsOrder | Fields to put first, in this order, when the actor creates the header; every other field follows |
| Nested fields as columns, Nested field separator, Lists, List separator | flatten, flattenSeparator, arrays, arraySeparator | Nested fields as columns (joined with "." by default); lists joined or kept as JSON |
| Add a syncedAt column | addSyncedAt | A timestamp column with the run's time |
| Values, Formula columns | valueInput, formulaColumns | Store values as given, or let Google type them (with formula columns for =IMAGE() and =HYPERLINK()) |
| Freeze the header row, Bold header, Fit column widths | freezeHeader, boldHeader, autoResize | Formatting, on by default |
| Back up before replacing or syncing, Backup to restore | createBackup, backupKey | Back up before replace or sync; restore a backup |
| Header row (read), Public sheet (read without sharing) | headerRow, publicSheet | Read: the header row; read a published sheet without sharing |
| Your service account key (optional), OAuth client id (optional), OAuth client secret, OAuth refresh token | serviceAccountJson, oauthClientId, oauthClientSecret, oauthRefreshToken | Optional: your own Google credentials |
| History store | stateStoreName | Optional. A key-value store in your account where the actor keeps the rows already written (for Only rows not sent before) and its backups. Empty: its own store, "cleanpull-sheets-sync". Pick one when you run it with a scoped API token |
Example inputs
Upsert a dataset of products into the Products tab by sku:
Read a tab into a dataset:
Sheets export after any actor
In the actor or task whose results you want in Sheets: Integrations → Connect Actor or Task → Google Sheets Sync, with this input:
Every time that actor finishes, its results land in your sheet.
Existing Sheets inputs
Inputs, tasks and integrations you already use for Sheets imports keep working: paste the same input and run.
- Keys it understands:
spreadsheetId,datasetId,rawData(objects, or a table with the header row first),limit,offset;deduplicateByField,deduplicateByEquality,columnsOrder,range(its tab is used),createBackup,publicSpreadsheet;- the modes
append,replace,modify,readandload backup(restores the latest backup of the tab).
- Your sheets keep their layout: with those inputs, nested fields keep
hobbies/0style column names, andreadalso saves the rows as theOUTPUTrecord. - No Google sign-in: share the spreadsheet with this actor's address as Editor, once. There are no tokens to expire and nothing to reconnect.
- Good to know:
transformFunctionis not run, because custom code is not executed. Use dedupe, columns, columnsOrder and limit instead.- Dedupe removes duplicates among the rows being sent. To skip rows already in the sheet, use
upsertwithkeyFields. - Rows always start at the tab's first column and row.
columnsOrderapplies when the header is created; an existing header keeps its order.
Google Sheets sync output
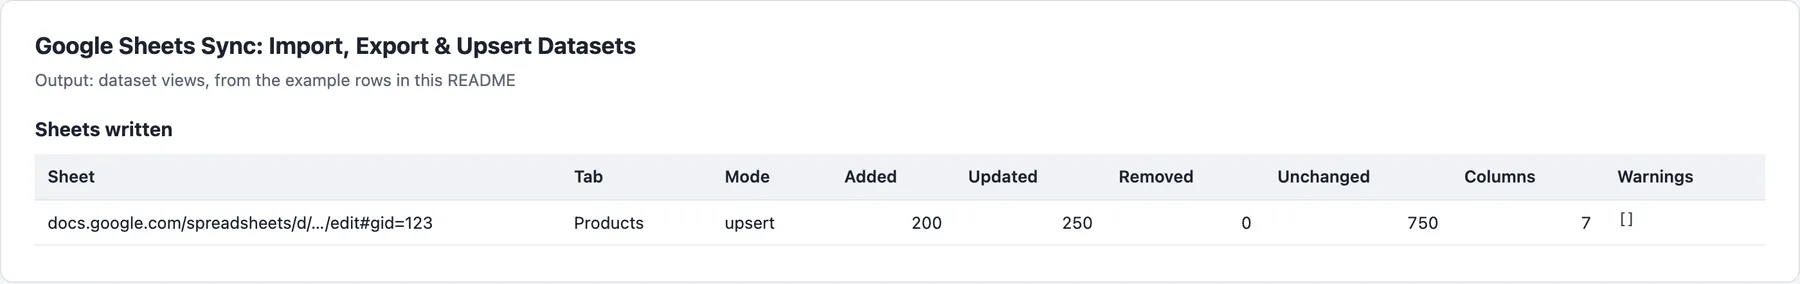
One record per spreadsheet target, in the Sheets written view. In read mode, the dataset holds the sheet's rows. RUN_SUMMARY in the key-value store gives the outcome (COMPLETE, PARTIAL, EMPTY, PREVIEW, FAILED), rows written and read, requests, retries after rate limits, and charges.
Example rows
Illustrative: the target row of the first example input above, for a dataset of 1,200 products of which 250 changed and 200 were new:
A target that could not be written has its reason in error and its kind in errorKind; a backup's key is in backupKey.
Rows and billing
| Row | Billed |
|---|---|
target (one per spreadsheet target) | Not per row: the rows it added, updated or removed are |
| Read mode: a sheet row in the dataset | One row read |
preview: true (no spreadsheet) | Free |
unreadable (a missing source, with why) | Free |
Google Sheets sync reliability
Measured on a live spreadsheet:
| Run | Result |
|---|---|
| Append 30,000 rows × 8 columns | 8.7 s, 12 requests |
| Upsert 1,200 rows (250 changed, 200 new) | 5.6 s; 750 unchanged rows untouched and free |
| Sync with mark (29,000 rows gone) | 10.2 s |
| Read 30,200 rows back | 1.0 s |
| 90 writes at once against Google's per-minute limit | All 90 succeed: the run waits and retries |
How:
- Few large writes (about 1.5 MB each, under Google's recommended 2 MB), paced under Google's per-minute limit.
- Retries with exponential backoff that honour Google's Retry-After. A write that is not safe to repeat is never retried blind: after a server error, an append is checked against the sheet before anything is sent again, so rows are never doubled, and a row deletion stops the sync (which is safe to run again).
- Datasets read in pages, so any size works.
- Progress kept per tab across platform restarts, so a resumed run continues where it stopped.
- Access checked before writing, with the exact address to share with.
- Scraped text that looks like a formula stays text.
- Cells over Google's 50,000-character limit are cut and counted.
Pricing
| Event | Free and Bronze | Silver | Gold |
|---|---|---|---|
| Row written (added, updated or removed) | $0.10 | $0.09 | $0.08 |
| Row read (read mode) | $0.05 | $0.045 | $0.04 |
Per 1,000 rows. Unchanged rows in upsert and sync are free; modify rewrites, and is charged for, every row it keeps. backup, restore and clear write no billed rows. Each run also has a $0.00005 start fee. A daily sync of 2,000 rows costs $0.20 on the Free and Bronze plans for its first run, which writes every row; after that, only the rows added, updated or removed are charged: a day with 100 changed rows costs $0.01, about $0.30 a month.
Limits
- Google's cell limit counts the whole spreadsheet. When it is reached, the run fills the sheet to the limit, stops cleanly and says so. Write the rest to a new spreadsheet (another target), or use replace or sync so the sheet keeps its size.
- Our service accounts cannot create new spreadsheets (Google gives service accounts no storage): create the sheet, then share it.
- Upsert and sync read the tab once to compare, so very large tabs (over about 500,000 rows) take longer.
- Formatting is limited to the header row and column widths; number formats come from Google when values are typed.
- "Only rows not sent before" works with append (upsert already skips unchanged rows, for free). Sync takes the whole dataset: no limit or skip, since rows left out would be removed.
- Rows without a key value are skipped in upsert and sync (they cannot be matched); rows in the sheet without a key are left as they are.
- The spending limit is respected before each write: a run that reaches it writes what fits, is charged for exactly that, and stops.
- Try it without a spreadsheet (preview): a run with no spreadsheet writes nothing and charges nothing: the dataset shows the rows it would write (up to 100, marked
preview: true), from your data or, with nothing filled in, four example rows. Add your spreadsheet's URL to write them. Your data is only ever written to the spreadsheet you name. - Nothing found: when the data or the sheet is not there (a missing run or record, a sheet not shared with us, a missing tab or backup), the run still succeeds and says why: a free
recordType: "unreadable"row for a missing source, or the target row'serroranderrorKind; nothing is charged. The run fails only when every target ended with an error, nothing was written or read, and at least one error is not one of these misses (an unexpected error from Google). When only some targets end with an error, the outcome isPARTIALand the run succeeds. A run near its time limit stops starting targets and ends with what it wrote.
FAQ
How much does it cost to export a dataset to Google Sheets?
$0.0001 per row written on the Free and Bronze plans: 1,000 rows are $0.10, 30,000 rows $3. In upsert and sync, only rows added, updated or removed are charged, so a daily sync of 2,000 rows costs $0.20 on its first run and then $0.01 on a day with 100 changed rows. Reading a sheet into a dataset is $0.00005 per row. A preview (no spreadsheet), backup, restore and clear write no billed rows; each run also has the $0.00005 start fee, and higher Apify plans pay less (see Pricing above).
How often should I sync a dataset to Google Sheets?
As often as the data changes: add it as an integration on the actor or task, so every finished run is written (see Sheets export after any actor above). With upsert or sync, a run where nothing changed writes nothing and costs only the start fee; with append, turn on Only rows not sent before so repeated rows are skipped.
What is the difference between append, upsert and sync?
Append adds every row below the existing data. Upsert matches rows by Key fields (upsert, sync, incremental), updates only the cells that changed and adds new keys, so each product has one row. Sync is upsert plus rows that are gone: Rows that are gone (sync) deletes them, moves them to a removed tab or marks them with removedAt. Replace clears the tab and writes the data.
Why are some rows not in my sheet?
- No key: rows without a key value are skipped in upsert and sync.
- Sent before: with Only rows not sent before, rows already written to the tab are skipped.
- Duplicates or limits: Remove duplicates, Maximum items and Skip items leave rows out on purpose.
- Cell limit: Google's cell limit counts the whole spreadsheet; the run fills it to the limit and says so.
- Spending limit: the run writes what fits and stops, with a warning on the target row.
- Not shared or no spreadsheet: a sheet not shared with our address has the reason in the target row's
error; with no Spreadsheet, the run only previews.
Do I need to sign in to Google?
No. Share the spreadsheet once with cleanpull-sheets-1@cleanpull-sheets.iam.gserviceaccount.com as Editor; there are no tokens to expire. The first run links the sheet to your Apify account through a hidden _cleanpull tab, so runs from other accounts are refused. To use your own Google account instead, fill Your service account key (optional) or the OAuth fields; they are secret inputs.
Can I use Google Sheets sync through the API?
Yes. Start runs through the Apify API or an API client with the same input as the form; inputs that use spreadsheetId and the related keys work unchanged. Read the Sheets written view, the sheet's rows (read mode, also in the OUTPUT record) or RUN_SUMMARY with the outcome, rows written and read, retries and charges.
Does it work with Make, Zapier or Claude?
Yes. It runs after any Apify actor or task as an integration, and Make, Zapier and n8n can start it through Apify's connectors. From Claude, the MarketMage plugin sends the results of a run or a watchlist to a Google Sheet in a chat: append, replace, or keep a sheet in sync by a key such as SKU or URL.
Is my spreadsheet data safe?
The actor writes only to the spreadsheet and tabs you name, and a run with no spreadsheet writes nothing. A shared sheet is linked to your Apify account, so its URL alone is never enough for another account to write to it. Your own service account key and OAuth fields are secret inputs. How you use the data, and following the laws and terms that apply to you, is your responsibility. This is not legal advice.
Related actors
Other CleanPull actors for monitoring:
- Alerts Sender: send results to email, Slack, Discord, Teams or a webhook.
- Watch Digest: one scheduled digest of price, stock, rank and review changes.
- Shopify Scraper: every product and variant from any Shopify store, with stock and sales estimates.
Use it from Claude
The MarketMage plugin runs these actors from a Claude chat.
Found it useful? A rating on the Store helps others find it.
Changelog
- 0.1.x, reliability (2026-10-24): no spreadsheet means a free preview of the rows a run would write (the empty-input example is now previewed too, no longer written to the demo spreadsheet); a missing source, an unshared sheet or a missing tab ends SUCCEEDED with the reason instead of FAILED; runs stop starting targets before their time limit. Prices unchanged.
- 0.1.7 (October 2026): existing Sheets inputs work unchanged (
spreadsheetIdand related keys, more modes, table-format raw data,hobbies/0columns,OUTPUTon read); newmodifymode,columnsOrderandflattenSeparator. - 0.1.6 (October 2026): an empty input runs an example on the demo spreadsheet instead of failing.
- 0.1 (October 2026): append, replace, upsert, sync, read, backup, restore and clear; datasets of any size; integration payloads; several targets; tabs per field value and per date; only-new rows; pacing, retries and resume; service-account sharing with per-user linking; your own service account or OAuth.


