
Reddit Scraper: Posts, Comments & Subreddits (No login)
Pricing
from $1.25 / 1,000 reddit posts
Reddit Scraper: Posts, Comments & Subreddits (No login)
Scrape Reddit posts and comments from subreddits, search, post URLs and user profiles. No login, no API key. Real score and comment count, clean text, parent IDs for comment threads. Free not-found and error rows.
Pricing
from $1.25 / 1,000 reddit posts
Rating
0.0
(0)
Developer

Cliqto Media
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
2 days ago
Last modified
Categories
Share
Scrape public Reddit posts and comments from subreddits, Reddit search, post URLs and user profiles. You get one row per post or comment with its real score, comment count, clean text, author, links and thread IDs. No login and no Reddit API key.
The smallest run reads the 10 newest posts of one subreddit (for example apify) in a few seconds and costs about $0.035.
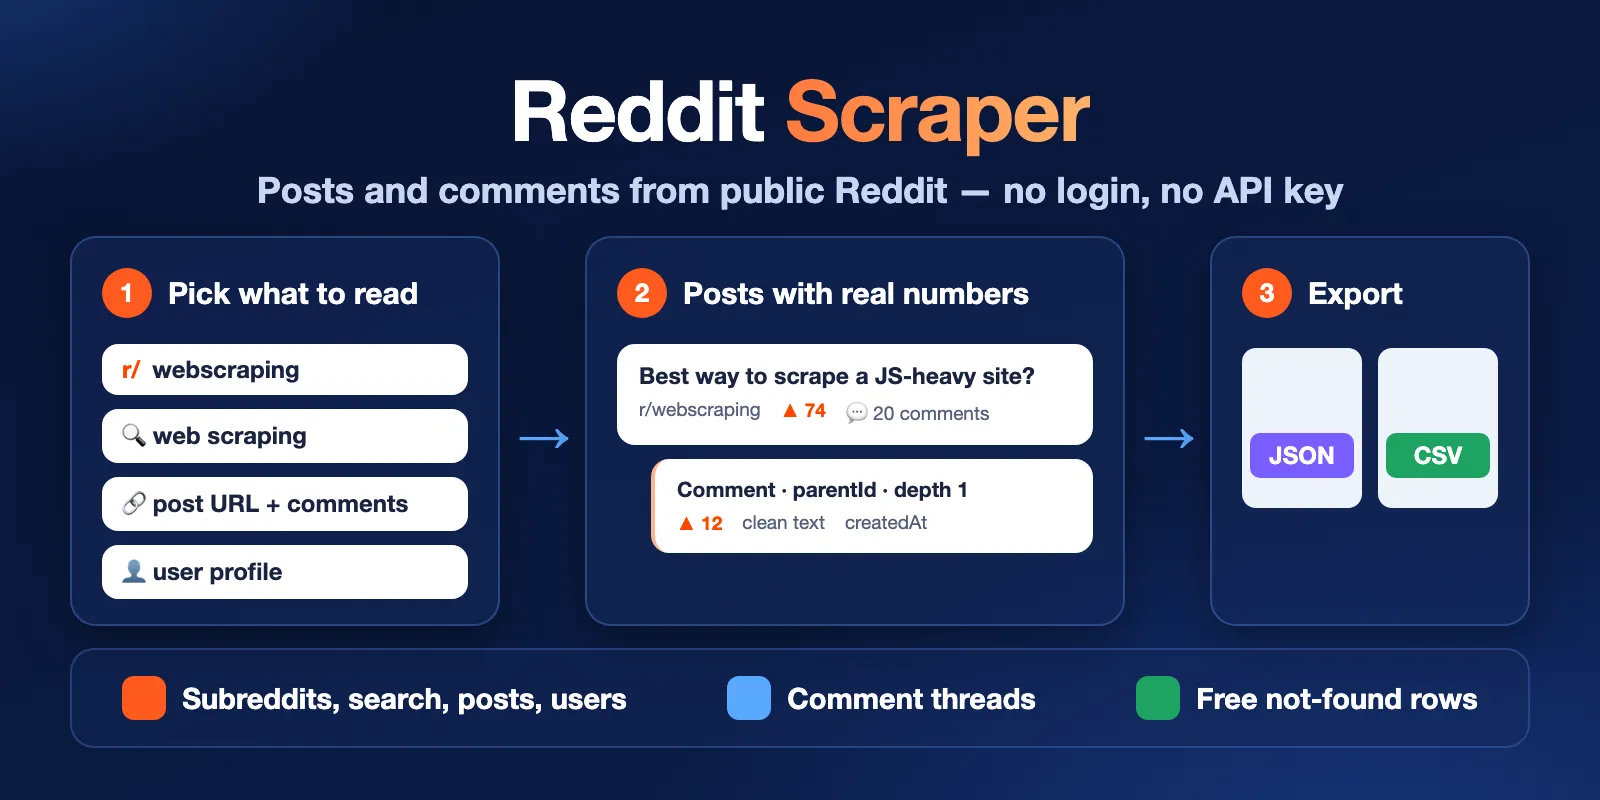
Table of contents
- What it does
- Quick start
- Use cases
- Input
- Output
- Pricing and limits
- API, export and integrations
- Troubleshooting
- FAQ
- Support
What it does
The Actor reads public pages of Reddit and saves posts and comments to a Dataset. Choose one mode:
subreddit— posts from one or more subreddits (new, hot, top or rising);search— posts that match keywords, across all public subreddits;post— single posts by URL or ID, usually with their comments;user— posts submitted by a user.
In every mode you can also add comments for each post (maxCommentsPerPost). Each comment keeps parentId and depth, so you can rebuild the reply tree.
Targets that do not exist, are empty or cannot be read get a free status row. You always see what happened to each subreddit, query, post or user.
Good fit
- Watch what people say about a brand, product or topic in a subreddit or in search.
- Collect posts and comment threads for market research or a text dataset (AI, RAG, sentiment).
- Export the posts of known users or a list of posts to a spreadsheet.
Not a fit / limits
- Only public content. No login, no private, banned or quarantined subreddits, no private messages.
- In
usermode only the user's posts are collected, not their comments. - Reddit itself shows at most about 1,000 posts per listing or search, so one target returns up to about 970–995 posts.
- This is not the official Reddit API. Reddit can change its pages; the Actor reports missing text or score in the run summary when that happens.
Quick start
- Open the Input tab.
- Keep Mode =
Posts from subredditsand type a subreddit in Subreddits, for exampleapify. - Keep Max posts per target = 10 and Max comments per post = 0 (the prefill).
- Click Start.
- Open the Output tab and check
title,scoreandnumCommentsof the first rows.
Expected result: 10 newest posts of r/apify, one row each, in about 5 seconds.
Use cases
| Buyer job | Input path | Output entity | Key fields | Next step |
|---|---|---|---|---|
| Brand or topic monitoring | mode: search, searchQueries, sort: new | post | title, text, subreddit, score, createdAt | schedule the run, export CSV |
| Community research | mode: subreddit, subreddits, sort: top, timeFilter: month | post + comment | score, numComments, text, parentId | spreadsheet or BI tool |
| Discussion analysis | mode: post, postUrls, maxCommentsPerPost | post + comment | text, depth, parentId, score | sentiment or AI pipeline |
| Author research | mode: user, usernames | post | subreddit, title, score, createdAt | spreadsheet |
Input
Input fields
| Field | Plain name | Type | Required | Default / prefill | Allowed values | Effect |
|---|---|---|---|---|---|---|
mode | Mode | string | yes | subreddit | subreddit, search, post, user | What to read; only the list for this mode is used |
subreddits | Subreddits | string[] | for subreddit | prefill ["apify"] | up to 50; apify, r/apify or a subreddit URL | Subreddits to read |
searchQueries | Search queries | string[] | for search | — | up to 50 keywords or phrases | Searches across all public subreddits |
postUrls | Post URLs | string[] | for post | — | up to 50 post URLs or IDs (1x64f49, t3_1x64f49, redd.it/1x64f49) | One post row per URL, plus comments |
usernames | Usernames | string[] | for user | — | up to 50; spez, u/spez or a profile URL | Posts submitted by each user |
maxPosts | Max posts per target | integer | no | 10 | 1–1000 | Posts for each subreddit, query or user (not used in post mode) |
maxCommentsPerPost | Max comments per post | integer | no | 0 | 0–500 | 0 = posts only; otherwise comments with replies for each post |
sort | Post sort | string | no | new | new, hot, top, rising, relevance, comments | Order of posts |
timeFilter | Time range | string | no | all | hour, day, week, month, year, all | Time range for top sort and for search |
commentSort | Comment sort | string | no | top | top, new, best, controversial, old | Order of comments |
proxy | Proxy | object | no | Apify Proxy, RESIDENTIAL, US | proxy editor | Reddit blocks datacenter IPs; keep the default |
The same post given twice (for example as an ID and as a URL) is saved once. Share links (reddit.com/r/.../s/...) are not supported: open them in a browser and copy the full post URL.
Interacting settings
| When | Setting | Effective behavior |
|---|---|---|
mode: subreddit | sort | new, hot, top, rising; another value falls back to the nearest one (shown in the run summary) |
mode: search | sort | relevance, new, top, comments |
mode: user | sort | new, hot, top |
sort: top or mode: search | timeFilter | Limits posts to the chosen time range; other sorts ignore it |
mode: post | maxCommentsPerPost | Set it above 0 to get comments; maxPosts is ignored |
commentSort: new | maxCommentsPerPost | Reddit may end a "new" comment list early; the run adds a warning. Use top for long threads |
Input examples
Newest posts of a subreddit (prefill)
Expected output: 10 post rows with title, text, score, numComments, upvoteRatio, postType. Cost on the free plan: $0.035.
Search with top posts of the month
Expected output: 15 post rows from different subreddits with subreddit, title, text and score.
One post with its comments
Expected output: 1 post row and up to 100 comment rows with parentId, depth, score and text.
Output
Each row has type: post, comment or status. The Output tab has four views: All rows, Post columns, Comment columns and Status columns.
Output fields
| Field | Meaning | Type | Can be empty? |
|---|---|---|---|
type | post, comment or status | string | no |
id | Reddit ID: t3_... for posts, t1_... for comments | string | no (status rows: absent) |
postId | t3_ ID of the post (for a comment: its post) | string | no (status rows: absent) |
parentId | Comments: t3_ post ID for a top-level comment, t1_ comment ID for a reply | string | null on posts |
depth | Comments: 0 = top level, 1 = reply, … | integer | null on posts |
subreddit | Subreddit name without r/ | string | rarely null |
title | Post title (on comments: title of their post) | string | rarely null |
text | Post body or comment text, plain text, HTML entities decoded | string | null for link, image and video posts without a body |
author | Username | string | null for deleted or removed authors |
authorId | t2_ ID of the post author (posts only) | string | null on comments |
score | Upvotes minus downvotes, as Reddit shows it | integer | null when Reddit hides it or the comment is deleted |
upvoteRatio | Share of upvotes, 0–1 (posts) | number | null in search and post modes |
numComments | Number of comments on the post | integer | null on comments |
url | Link to the post or comment on reddit.com | string | null for some deleted comments |
linkUrl | Link, image, video or gallery URL of the post | string | null for text posts |
postType | text, link, image, video, gallery, … | string | null in search and post modes |
createdAt | Creation time, ISO 8601 UTC | string | rarely null |
status | Status rows: not_found, no_results or error | string | status rows only |
message | Status rows: what happened, in plain words | string | status rows only |
errorCode | Status rows: INVALID_INPUT, SOURCE_BLOCKED, … | string | null for not_found and no_results |
mode | Mode of the run | string | no |
input | Your subreddit, query, post URL or username as given | string | no |
source | Always Reddit | string | no |
fetchedAt | Time the row was read, ISO 8601 UTC | string | no |
null means Reddit did not show the value. It is never replaced with 0: a deleted comment has score: null, not 0.
Output entities and surfaces
| Situation | Where | Result shape | What to do |
|---|---|---|---|
| Normal post or comment | Dataset | type: post / type: comment | Export or filter by type |
| Subreddit or post does not exist | Dataset | free status: not_found row | Check the spelling |
| Empty listing or search; user with no posts or no such user | Dataset | free status: no_results row | Try another sort or timeFilter; check the username |
| Invalid input or source failure | Dataset | free status: error row with errorCode | Read message; fix input or retry later |
| Whole run | Key-value store RUN_SUMMARY | status, reason, counts, targets, warnings | Check which targets returned data |
RUN_SUMMARY.status is complete when all targets were read and partial when the run stopped early: your charge limit was reached (CHARGE_LIMIT, run still SUCCEEDED), the run timeout was near, or Reddit failed after some rows were saved. Saved rows stay in the Dataset in every case.
Output example
Post from the prefill run (trimmed text):
Comment row (post mode):
Status row:
Moving from another Reddit scraper
Field names differ from some other Reddit Actors, so this is not a drop-in replacement. Common mapping: body → text, username → author, communityName → subreddit, upVotes → score, dataType → type, scrapedAt → fetchedAt. There is no html field: text is already plain text.
Pricing and limits
Pricing unit
You pay per event (pay-per-event). Apify platform usage (compute and proxy) is included in these prices.
| Event | Free | Bronze | Silver | Gold and higher |
|---|---|---|---|---|
Run start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Post row (post) | $0.0015 | $0.0014 | $0.0013 | $0.00125 |
Comment row (comment) | $0.0008 | $0.00075 | $0.0007 | $0.00065 |
statusrows (not_found,no_results,error) are free.- A run that finds nothing pays only the run start, $0.02.
- The start event is charged once per run up to 1 GB of memory. The Actor picks 256–1024 MB itself; if you set 2048 MB, the start is charged twice.
- Set Maximum cost per run in run options to cap spending. When the cap is reached, the run stops, keeps the saved rows and ends as SUCCEEDED with
partialinRUN_SUMMARY.
Cost examples (Free plan prices)
| Scenario | Input scope | Rows | Charge | Measured time |
|---|---|---|---|---|
| Prefill | 1 subreddit, 10 posts | 10 posts | $0.035 | ~4 s |
| Search | 3 queries × 10 posts | 30 posts | $0.065 | ~20 s |
| Community research | 200 posts + comments | 200 posts + 1,297 comments | $1.36 | ~85 s |
| Nothing found | 6 searches with no matches | 0 (status rows) | $0.02 | ~5 s |
Limits
- Up to 50 subreddits, queries, posts or users per run; up to 1,000 posts per target and 500 comments per post.
- Reddit shows at most about 1,000 posts per listing or search (970–995 in our tests); the run summary warns when it lists fewer than
maxPosts. - Large searches can take several minutes. The default run timeout is 1 hour; the Actor stops 20 seconds before the timeout and keeps all saved rows.
API, export and integrations
- Export: download the Dataset as JSON, CSV, Excel, XML or HTML from the Output tab, or export one view (Post columns, Comment columns, Status columns).
- API: start the Actor with the Apify API or the Apify JavaScript/Python client and read Dataset items; check
RUN_SUMMARYin the default Key-value store. - Scheduling: create a Task with your input and a schedule in Apify Console, for example a daily
searchwithsort: new. - Webhooks / no-code: use Apify integrations (Make, Zapier, n8n, webhooks) to send new rows to another tool.
Use with AI agents (MCP)
- MCP server with only this Actor:
https://mcp.apify.com?tools=cliqtomedia/reddit-scraper - Smallest useful input:
{"mode": "subreddit", "subreddits": ["apify"], "maxPosts": 10, "maxCommentsPerPost": 0} - Key output fields:
type(post, comment or status),title,text,score,numComments,url. - The prefill run takes about 4 seconds and costs $0.035 on the Free plan. Keep
maxPostssmall (10–50) for answers in under a minute; search is slower than subreddit mode.
Troubleshooting
A subreddit returns a not_found row
Symptom: no posts, one status: not_found row.
Likely reason: the subreddit does not exist, is banned or private, or the name has a typo.
Action: open https://www.reddit.com/r/<name>/ in a browser and check the name.
A user returns a no_results row
Reddit shows the same empty page for an account without posts, a suspended account and a name that does not exist. So in user mode all three give status: no_results, not not_found.
Action: open https://www.reddit.com/user/<name>/submitted/ in a browser and check the name.
Fewer posts than maxPosts
Symptom: for example 11 posts when you asked for 30.
Likely reason: Reddit shows only these posts for the chosen sort and timeFilter (for example top of a quiet week). RUN_SUMMARY.warnings says so.
Action: choose a longer timeFilter or sort: new.
Fewer comments than maxCommentsPerPost
Likely reason: the post has fewer comments, or commentSort: new was used — Reddit ends that list early. RUN_SUMMARY.counts.commentsCutShort shows it.
Action: use commentSort: top.
error row with SOURCE_BLOCKED
Likely reason: Reddit refused every proxy session for this target, or the content needs a login. Action: keep the default residential proxy and retry later. Content behind a login is not collected.
Search results change between runs
Reddit's relevance order can change from page to page and from run to run. Use sort: new or sort: top when you need stable results.
FAQ
Do I need a Reddit account or API key?
No. The Actor reads public pages without login, cookies or an API key.
Why are upvoteRatio and postType empty in search?
Reddit does not show them on search results and single post pages. They are filled in subreddit and user modes.
Do I pay for empty results?
You pay the run start ($0.02). Rows for missing, empty or invalid targets are free.
Is the data fresh?
Yes. Each row is read at run time; fetchedAt shows when. Scores and comment counts change on Reddit after that.
How does it read Reddit, and is it allowed?
The Actor reads only pages that anyone can open without an account. It uses a browser-like HTTP client and Apify residential proxies. It does not log in, does not use your cookies and does not solve CAPTCHAs or browser challenges; if Reddit asks for a login or shows a challenge, that target gets an error row.
Reddit's User Agreement does not allow scraping without Reddit's written consent. Check whether your use is permitted. You are responsible for how you use the data, including personal data rules such as GDPR.
Support
For bugs, questions or feature requests, open an issue on the Issues tab of this Actor. Include the run ID, the mode and the error text. Do not post tokens, cookies or private data.


