
Remote Jobs Aggregator - RemoteOK, WWR & Himalayas, No login
Pricing
Pay per event
Remote Jobs Aggregator - RemoteOK, WWR & Himalayas, No login
Remote job listings from Remote OK, We Work Remotely and Himalayas in one deduplicated dataset. Filter by keyword, category, region and date, get salary only when the board publishes it, and fetch only new jobs on scheduled runs. No login or API key for the boards.
Pricing
Pay per event
Rating
0.0
(0)
Developer
Cliqto Media
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
5 days ago
Last modified
Categories
Share
Remote Jobs Aggregator collects remote job listings from Remote OK, We Work Remotely and Himalayas and returns them as one dataset. The same job posted on two boards becomes one row. You can filter by keyword, category, location, date and salary, and on scheduled runs you can get only the jobs you have not seen before. You do not need a login or an API key for any of the boards.
Use it to build a remote job feed, a job alert or a salary dataset. The smallest run is one keyword: python, last 7 days, 50 jobs takes about 20 seconds and costs about $0.09.
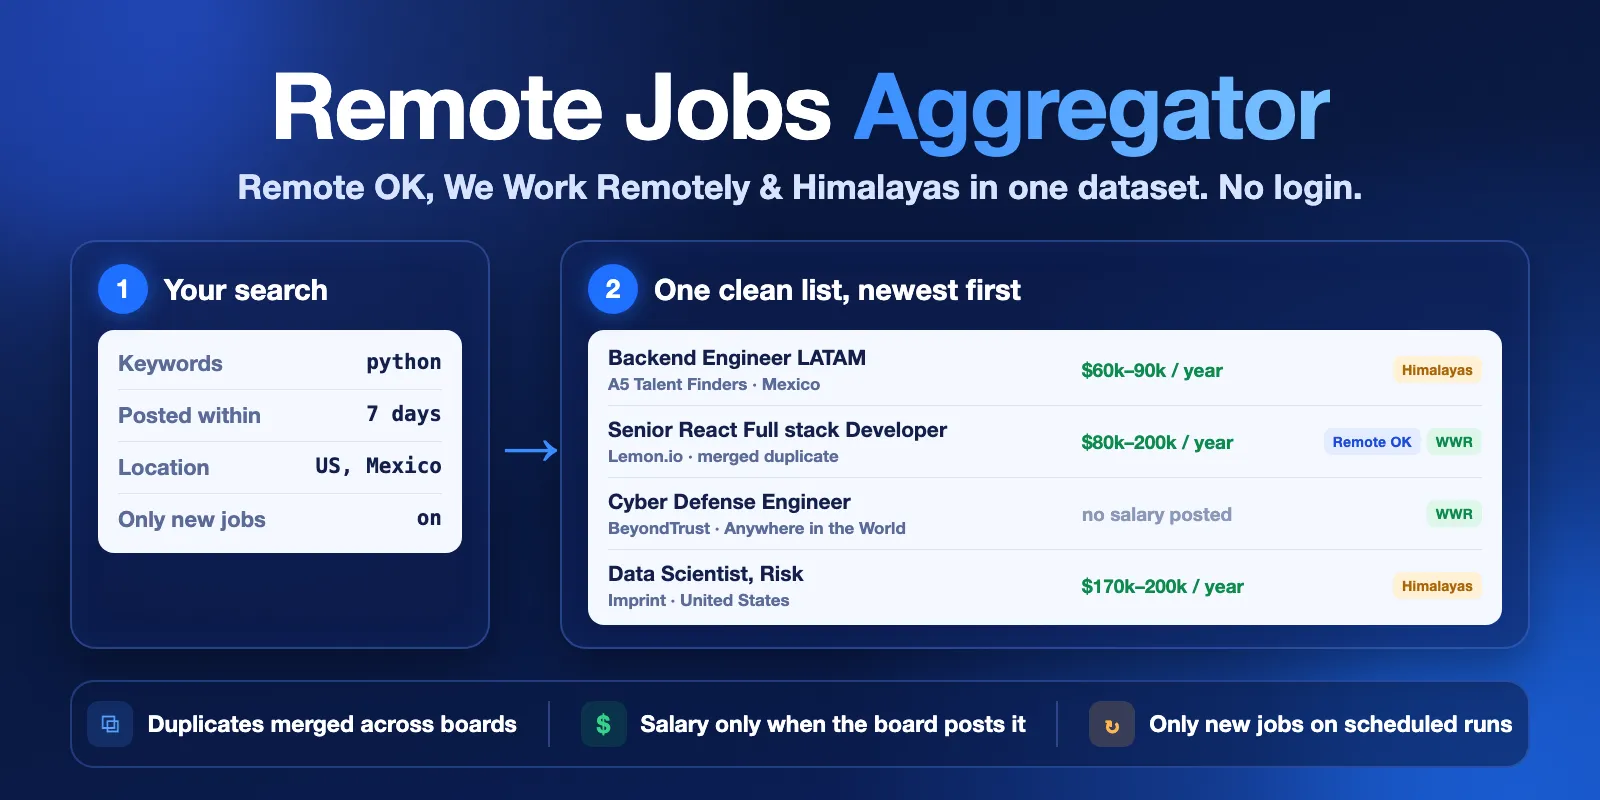
Table of contents
- What it does
- Quick start
- Input
- Output
- Pricing
- Use cases
- Scheduled runs and job alerts
- API, export and integrations
- Limits
- Source terms you must follow
- Troubleshooting
- FAQ
- Related Actors
- Support
What it does
For each run the Actor:
- Reads the public job feeds of the boards you choose: the Remote OK public API, the We Work Remotely RSS feeds and the Himalayas public API. When you add keywords, Himalayas is searched with them; the other two boards are read in full and filtered.
- Keeps jobs that match your filters: keywords, exclude keywords, categories, allowed locations, posting date and "salary only".
- Merges the same job found on several boards into one row (same company and title, or the same link). The other boards are listed in
alsoFoundOn. - Writes the newest jobs first, up to Max jobs (
maxItems). - With Only new jobs (
onlyNew), remembers which jobs it returned and skips them next time.
Each row has the job link on the board, the company, location, salary, tags, posting date and an optional description. The salary fields are filled only when the board publishes a salary. The Actor never estimates a salary.
Good fit
- A daily or hourly remote job alert for one stack or role, without duplicates from three boards.
- A dataset of remote jobs with published salary ranges for research or a newsletter.
- A job board or Slack/Telegram feed that needs clean, structured rows with links back to the source board.
Not a fit / limits
- Only these three boards. It does not read LinkedIn, Indeed, company career sites or boards that need a login.
- It does not apply to jobs and does not collect data about candidates.
- One run returns at most about 1,000 unique jobs, because that is what the three public feeds offer (see Limits).
- Board data can be incomplete: some jobs have no salary, no location or no company website. Those fields are
null.
Quick start
- Open the Input tab.
- The form already has Keywords (
keywords) =python, Posted within (days) (postedWithinDays) = 7 and Max jobs (maxItems) = 50. Change the keyword if you like. - Keep the other settings at their defaults: all three boards, description as plain text.
- Click Start.
- Open the Output tab. The Jobs view shows title, company, location, salary and the board.
Expected result: up to 50 Python remote jobs from the last 7 days from all three boards, newest first, in about 20 seconds. In our test runs 14–30% of rows had a published salary.
Input
All fields are optional. An empty input returns up to 100 jobs from the last 30 days from all three boards.
Input fields
| Field | Plain name | Type | Default / prefill | Allowed values | Effect |
|---|---|---|---|---|---|
keywords | Keywords | array of strings | default empty; prefill ["python"] | up to 20, each up to 60 characters | Keep jobs that contain any of these words in title, tags, company or description. Whole words: python also matches pythonista, developer matches developers, but java does not match javascript. Also used as the Himalayas search query. |
postedWithinDays | Posted within (days) | integer | default 30; prefill 7 | 1–90 | Keep jobs posted in the last N days. Jobs without a posting date are dropped. |
maxItems | Max jobs | integer | default 100; prefill 50 | 1–2000 | Upper limit of rows written and charged, after filters and duplicate merging. |
sources | Job boards | array | all three | remoteok, weworkremotely, himalayas | Which boards to read. |
excludeKeywords | Exclude keywords | array of strings | empty | up to 20 | Drop jobs whose title, tags or company contain any of these words, e.g. senior. The description is not checked. |
searchInDescription | Match keywords in description too | boolean | true | true / false | Off: keywords match only title, tags and company (fewer, stricter results). |
categories | Categories | array | all | programming, design, devops, product, sales-marketing, customer-support, management-finance, data, other | Keep only these categories. The category comes from the board or, if the board has none, from the job title. |
locationsAllowed | Allowed locations | array of strings | any | up to 20, e.g. USA, UK, Europe, LATAM, APAC, Germany | Keep jobs open to these countries or regions. Worldwide jobs always pass. Jobs with an unknown location are dropped. |
salaryOnly | Only jobs with a salary | boolean | false | true / false | Keep only jobs where the board publishes a salary. We Work Remotely never publishes one, so it is skipped. |
includeDescription | Description format | string | text | text, html, both, none | Plain text (up to 20,000 characters), HTML (up to 50,000), both or none. |
onlyNew | Only new jobs | boolean | false | true / false | Skip jobs returned in earlier runs with the same stateKey. |
stateKey | State key | string | default | 1–40 letters, digits or dashes | Separate memory for onlyNew, e.g. one key per saved search. |
maxPagesPerSource | Max pages per board | integer | 10 | 1–25 | Page limit for Himalayas (about 20 jobs per page). Higher finds older jobs but takes longer. |
Interacting settings
| When | Input A | Input B | Effective behavior |
|---|---|---|---|
| Many keywords | keywords | maxPagesPerSource | Himalayas gets 2 × maxPagesPerSource search pages in total, shared between the keywords (at least 1 page each). With 20 keywords, each keyword searches 1 page. |
| Keyword and exclude word both match | keywords | excludeKeywords | Exclude wins. Exclude keywords check only title, tags and company. |
| Location filter and worldwide job | locationsAllowed | job isWorldwide = true | The job passes any location filter. |
| Scheduled alerts | onlyNew | stateKey | Each stateKey has its own memory. Only rows that were written are remembered, so a job cut by maxItems can appear next time. Memory is kept for 120 days. |
Input examples
Python jobs from the last week (the form prefill)
Expected behavior: about 20 seconds, 50 rows from all three boards, newest first. Expected output: rows like the output example below. Cost: about $0.091 (one start plus 50 jobs on the Free plan).
Daily alert: new React jobs open to Europe, no senior roles
Expected behavior: the first run returns all matching jobs; the next runs return only jobs not returned before for react-europe.
Cost: you pay only for the new rows plus the start event.
Output
Each job is one row in the default Dataset. The run summary is in the Key-value store record RUN_SUMMARY.
Output example
One row from the prefill run (python, 7 days, 50 jobs). Shortened: the description fields are left out; all other fields are shown. Lemon.io posted the same job on Remote OK and We Work Remotely; it is one row with the second board in alsoFoundOn. Remote OK does not publish a location for this job, so the location fields are null.
Output fields
| Field | Meaning | Type | Can be empty? | Example |
|---|---|---|---|---|
source | Board this row comes from | string | no | himalayas |
sourceJobId | Job id on that board | string | no | a5-talent-finders/backend-engineer-latam-6204533411 |
url | Job page on the board | string | no | https://himalayas.app/companies/… |
applyUrl | Direct apply link | string | yes, when the board has none | |
title | Job title | string | no | Backend Engineer LATAM |
company | Company name | string | rarely | A5 Talent Finders |
companyUrl, companyLogo | Company website or board page, logo URL | string | yes | |
location | Location as the board writes it | string | yes | Mexico, Anywhere in the World |
regions | Countries or regions the job is open to | array | empty when unknown or worldwide | ["Mexico"] |
isWorldwide | Open worldwide? | boolean | null when the board does not say | false |
remoteType | remote, hybrid or onsite | string | no | remote |
employmentType | full_time, part_time, contract, internship, temporary, other | string | yes | full_time |
category | Normalized category | string | no | programming |
seniority | Seniority as the board publishes it | string | yes | mid-level |
salaryMin, salaryMax | Salary range as published | number | null when not published | 60000, 90000 |
salaryCurrency | ISO currency | string | null when no salary | USD |
salaryPeriod | year, month, week, day or hour | string | null when no salary | year |
tags | Tags or skills from the board | array | can be empty | ["Python Developer", …] |
postedAt | Posting time, ISO 8601 UTC | string | no | 2026-10-12T22:59:30.000Z |
expiresAt | Expiry time | string | yes | |
descriptionText, descriptionHtml | Description, depending on includeDescription | string | yes | |
alsoFoundOn | Other boards with the same job | array of {source, url} | empty when only one board | |
attribution | Source credit you must show | string | no | Job via Remote OK — https://remoteok.com |
dedupKey | Cross-board identity of the job | string | no | `a5 talent finders |
fetchedAt | When this run fetched the job | string | no |
Output views and run status
| Situation | Where to look | What you see | What to do |
|---|---|---|---|
| Normal run | Output tab → Jobs, Salaries or Details view | One row per job | Export or use the API |
| No job matches the filters | Dataset is empty; RUN_SUMMARY.status = SUCCEEDED | counts.filteredOut shows which filter removed the jobs | Widen the date, remove a filter or a keyword |
| One board failed | Rows from the other boards; RUN_SUMMARY.status = PARTIAL | sources.<board>.status and error | Run again later; the rows you got are valid |
| All boards failed | Run status Failed; RUN_SUMMARY.status = ERROR | Error code per board | Run again later or open an issue |
| Invalid input | Run status Failed with the field name in the message | No rows | Fix the field named in the message |
RUN_SUMMARY also shows per-board counts, how many duplicates were merged, how many jobs onlyNew skipped and why the run stopped (stoppedBy).
Coming from another remote jobs Actor
The fields are not a drop-in copy of other job Actors. A simple mapping is usually enough: companyName → company, postedDate → postedAt, salary.min/max/currency/unit → salaryMin/salaryMax/salaryCurrency/salaryPeriod, companyWebsite → companyUrl, validThrough → expiresAt, applicantCountries → regions, jobLevel → seniority, employmentType list → one employmentType value, categories → category plus tags.
Pricing
Pricing unit
You pay per event:
| Event | When | Free | Bronze | Silver | Gold |
|---|---|---|---|---|---|
| Actor start | once per run | $0.006 | $0.006 | $0.006 | $0.006 |
| Job result | per row written to the Dataset | $0.0017 | $0.0016 | $0.0015 | $0.0014 |
Platform usage (compute) is included. You pay for written rows only: jobs removed by filters, merged duplicates and jobs skipped by onlyNew are not charged. A run that finds no matching job costs only the start event, $0.006. A run with invalid input also costs only the start event.
If you set a maximum total charge for the run, the Actor stops writing rows before it would go over it and says so in RUN_SUMMARY.warnings.
Cost examples (Free plan)
| Scenario | Input | Rows | Cost |
|---|---|---|---|
| Prefill | python, 7 days, 50 jobs | 50 | about $0.091 |
| Scheduled alert, quiet day | onlyNew, no new jobs | 0 | $0.006 |
| Medium | no keywords, 30 days, 500 jobs | 500 | about $0.86 |
| Everything | no keywords, 90 days, maxItems 2000, maxPagesPerSource 25 | about 930 | about $1.58 |
Use cases
| Buyer job | Input path | Output entity | Key fields | Next step |
|---|---|---|---|---|
| Job alert for one stack | keywords, onlyNew = true, a schedule | Only new remote jobs | title, company, url, postedAt | Webhook to Slack, email or a sheet |
| Salary research | categories, salaryOnly = true, postedWithinDays = 90 | Jobs with published salary | salaryMin, salaryMax, salaryCurrency, salaryPeriod | Export CSV or Excel |
| Remote job feed for a region | locationsAllowed = ["Europe"] | Jobs open to Europe or worldwide | location, regions, isWorldwide | API into your site |
| Market overview | no keywords, maxItems = 2000, postedWithinDays = 90 | All jobs the three feeds offer | category, tags, company, source | Dataset export |
Scheduled runs and job alerts
- Save your input as a task, with
onlyNew= true and astateKeyfor this search, for examplereact-europe. - Add a schedule to the task in Apify Console, for example every day.
- Each run returns only jobs not returned before for this
stateKey. A quiet day costs only the start event ($0.006). - To send the new rows somewhere, add a webhook or an integration (Slack, email, Google Sheets, Zapier, Make, n8n).
The memory is stored in your named key-value store remote-jobs-aggregator-state and keeps a job for 120 days. Use a new stateKey to start again.
API, export and integrations
- API: start a run with
POST https://api.apify.com/v2/acts/cliqtomedia~remote-jobs-aggregator/runs, your Apify API token and the input JSON. Read rows from the run's default Dataset. - Export: JSON, CSV, Excel, XML or RSS from the Output tab or the Dataset API.
- Scheduling: see Scheduled runs and job alerts.
- Webhooks / no-code: add a webhook on "Run succeeded" to send new rows to Zapier, Make, n8n, Slack or your own endpoint.
Use with AI agents (MCP)
- MCP server URL with only this Actor:
https://mcp.apify.com?tools=cliqtomedia/remote-jobs-aggregator. - Smallest useful input:
{"keywords": ["python"], "postedWithinDays": 7, "maxItems": 50}. - Key output fields:
title,company,url(job page),salaryMin/salaryMax/salaryCurrency(nullwhen not published),postedAt,source. - A typical run takes about 20 seconds and costs about $0.09 for 50 jobs.
maxItemsis the main cost control; one run returns at most about 1,000 jobs.
Limits
- About 1,000 unique jobs per run at most. The Remote OK feed has its ~100 newest jobs, the We Work Remotely feeds about 400, and Himalayas up to 25 pages of about 20 jobs. A run with no keywords, 90 days and
maxPagesPerSource25 returned 927 jobs in about one minute. - Himalayas depth per keyword. With a popular keyword and the default 10 pages, Himalayas returns about 180 of its newest matching jobs (for
pythonthat was the last ~16 hours). For more, raisemaxPagesPerSourceto 25 or run without keywords and filter afterwards. - Remote OK and We Work Remotely are read in full, then filtered, so keywords do not make them deeper.
- Requests to each board are spaced (about one per second). All boards share one time limit: 120 seconds, or the run timeout minus 15 seconds if that is shorter. A run timeout under 30 seconds fails with
TIMEOUT_TOO_SHORT. - Memory is fixed at 256 MB. A typical run takes 15–70 seconds.
Partial and failed runs
- If one board fails, you still get rows from the other boards, and
RUN_SUMMARY.statusisPARTIAL. You pay only for the rows written. - If all boards fail, the run fails with status
ERRORand no rows. You pay only the start event. - A run that is aborted keeps the rows already written;
RUN_SUMMARY.statusisCANCELLED.
Source terms you must follow
The jobs belong to the boards and the companies that posted them. When you show or republish rows:
- Remote OK (API terms): link back to the job on Remote OK (
url) and mention Remote OK as the source. Do not use the Remote OK logo. Theattributionfield has the text. - Himalayas (API terms): link back to the job on Himalayas (
url) and mention Himalayas as the source. Do not submit Himalayas jobs to Jooble, Neuvoo, Google Jobs or LinkedIn Jobs. - We Work Remotely (RSS feed terms): link back to the job on We Work Remotely (
url).
The Actor does not collect personal data about candidates. Job descriptions can include a recruiter's name or email; handle them under your local privacy rules.
Troubleshooting
The run succeeded but the Dataset is empty
Likely reason: the filters removed every job.
Check: RUN_SUMMARY.counts.filteredOut shows how many jobs each filter removed (date, keywords, excluded, category, location, salary).
Action: raise postedWithinDays, remove a filter or add another keyword.
Fewer Himalayas jobs than expected
Likely reason: the page limit. RUN_SUMMARY.sources.himalayas.notes says stopped at the page limit.
Action: raise maxPagesPerSource (up to 25) or use fewer keywords.
Status is PARTIAL
Likely reason: one board did not answer or changed its feed.
Check: RUN_SUMMARY.sources.<board>.error.
Action: the rows you got are valid. Run again later. If it keeps failing, open an issue with the run ID.
onlyNew returns nothing
Likely reason: no new jobs since the last run with the same stateKey, or the new jobs did not match the filters.
Action: this is normal for a quiet period. To start over, use a new stateKey.
FAQ
Do I need a login or API key for the boards?
No. The Actor uses only public feeds of the three boards. You need only your Apify account (and an Apify API token if you start runs through the API).
Why is the salary empty for many jobs?
Many companies do not publish a salary. The Actor copies the salary only when the board publishes it and never guesses one. Use salaryOnly to keep only jobs with a salary.
How fresh are the jobs?
Each run reads the boards at that moment. postedAt is the posting time from the board, fetchedAt is when the run read it. A closed job can still be in a feed until the board removes it.
How are duplicates found?
Two jobs are the same when the company and title match after normalization (case, punctuation, "Inc"/"Ltd" and similar removed), or when the link is the same. The row with the most details is kept; the other boards are listed in alsoFoundOn.
Can I add another board?
Not in this Actor. Boards that need a login or forbid reuse are not supported. For company career pages, see the Related Actors below.
Related Actors
- Wellfound Jobs Scraper — startup jobs from Wellfound.
- Greenhouse Jobs Scraper & Monitor — all open jobs of a company that hires with Greenhouse.
- Lever Job Scraper — company job boards hosted on Lever.
- Ashby Jobs Scraper — company job boards hosted on Ashby.
Support
Open an issue in the Issues tab of this Actor. Include the run ID, your input (without private data) and the RUN_SUMMARY.status and message. Do not post tokens or personal data.


