
Reddit Scraper: Subreddit Posts and Comments
Pricing
from $1.05 / 1,000 posts
Reddit Scraper: Subreddit Posts and Comments
Scrape Reddit data from any public subreddit, post link or search, no login or Reddit API key needed: posts with title, text, score, flair, link and time, plus comments and replies as a Reddit comments scraper. Filter by date, score, flair or type, or run a subreddit monitor for new posts.
Pricing
from $1.05 / 1,000 posts
Rating
0.0
(0)
Developer
Kaleidoscope Labs
Maintained by CommunityActor stats
2
Bookmarked
5
Total users
4
Monthly active users
an hour ago
Last modified
Categories
Features
Share
What does Reddit Scraper do? Subreddit scraper and subreddit monitor
Scrape Reddit posts and comments from any public subreddit, post link or Reddit search, logged out, no Reddit API key needed: a subreddit scraper, a Reddit comments scraper and a subreddit monitor in one Actor.
Public subreddits, post links or searches go in; one record per post comes out, with its title, text, score, upvote ratio, comment count, flair, link, creation time and author, in hot, new, top, rising or best order, and, when you ask for them, one record per comment and reply in Reddit's own order. $1.50 per 1,000 posts and $1.50 per 1,000 comments on Apify's free plan, less on paid plans; a monitor's check is $0.002 per subreddit.
Filter posts by date, type, score, flair or whether they take comments, or run it as a subreddit monitor that stores only the posts new since its last run. Each post and each comment is one dataset item and one charged event. Run it from Apify Console, call it through the API, schedule it, or let an AI agent call it.
What data can you extract from Reddit?
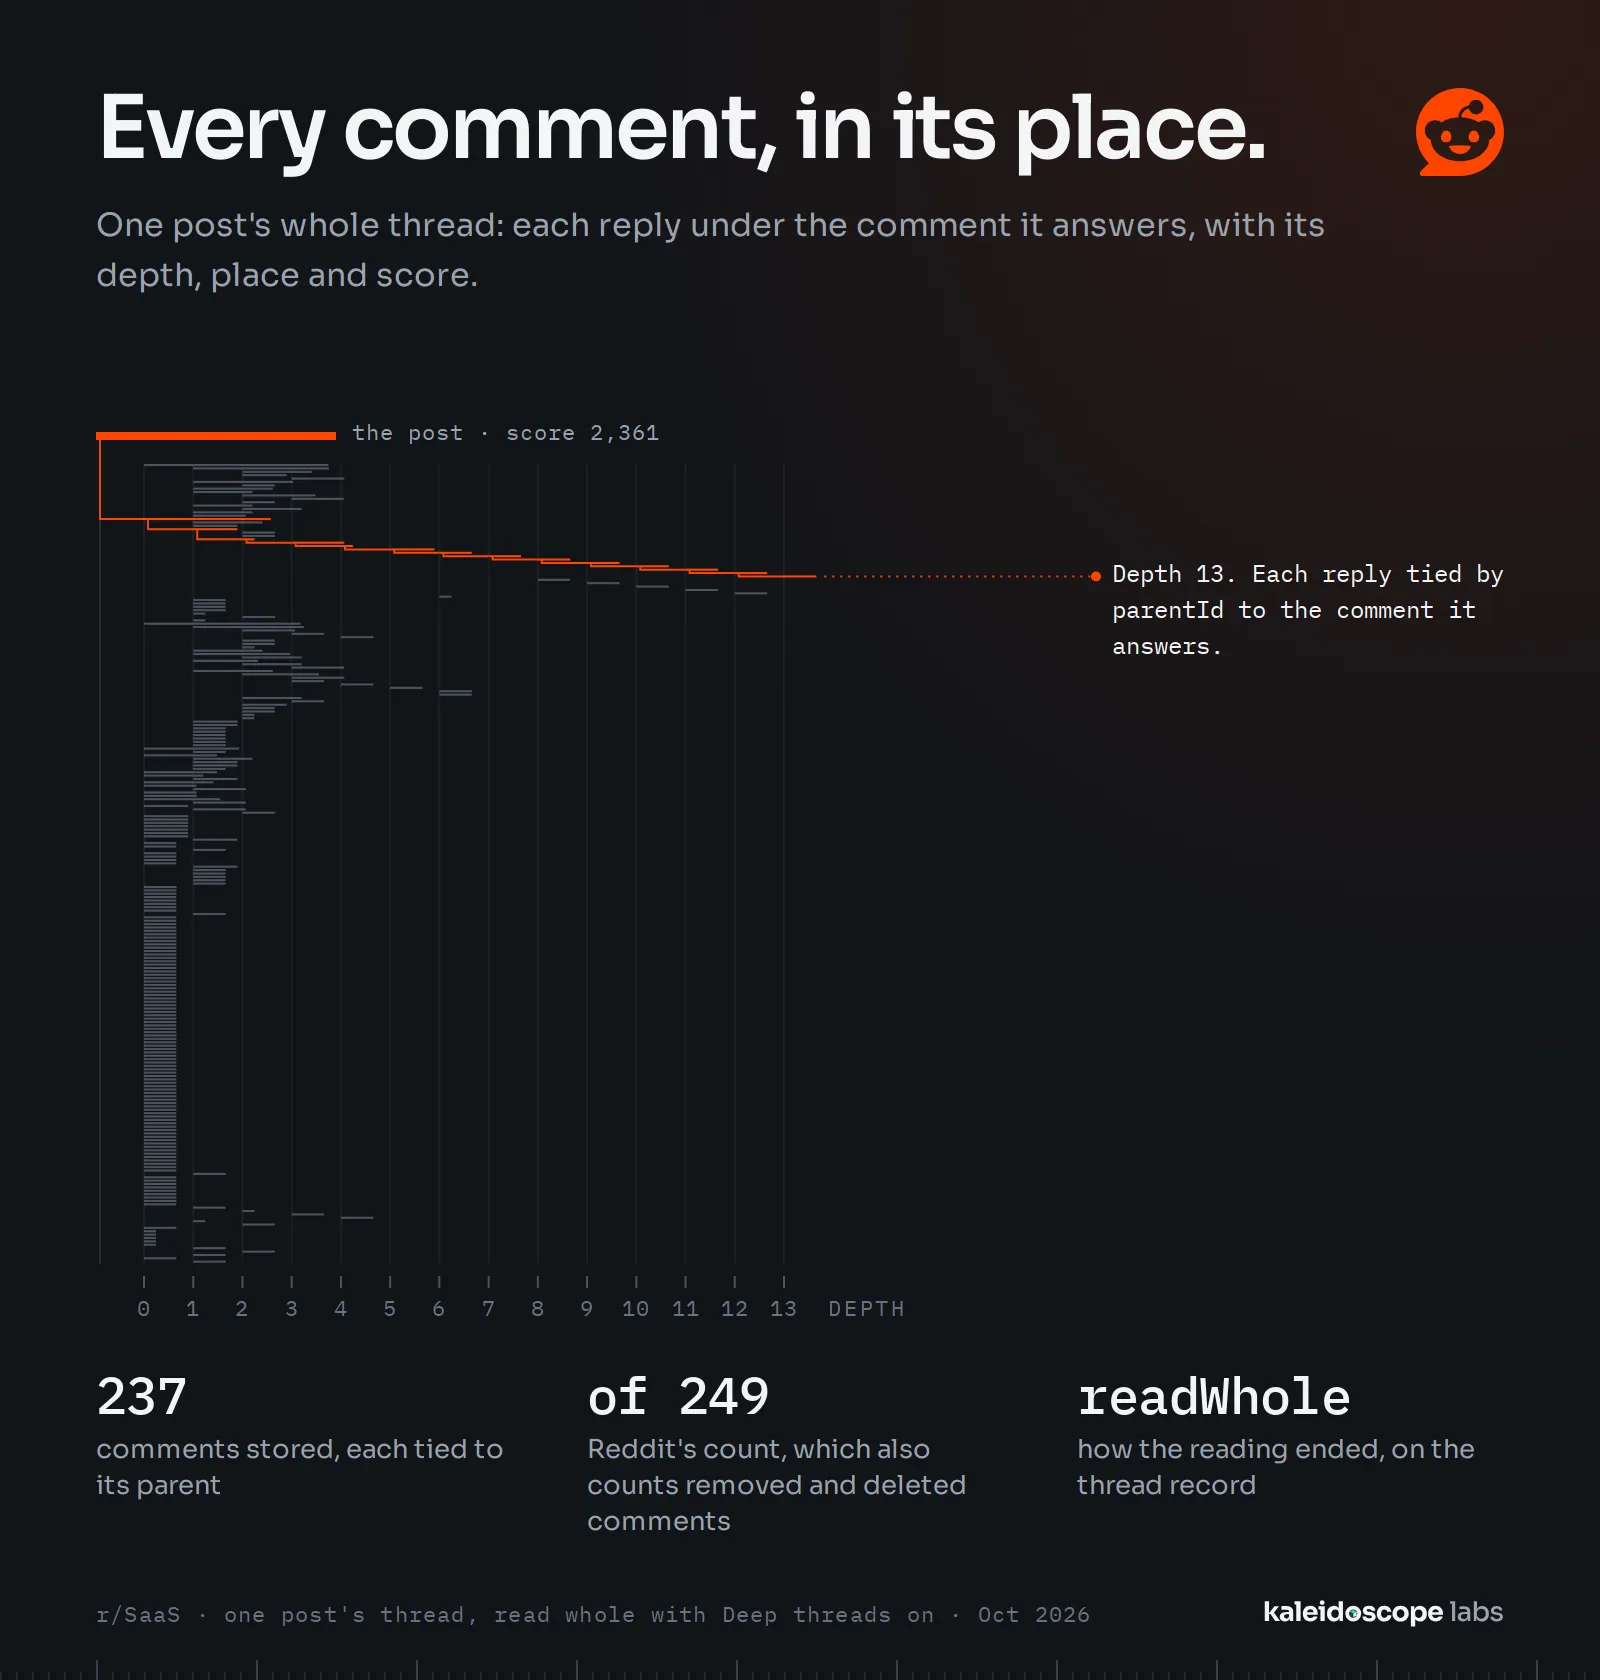
A run stores up to three kinds of record in one dataset: posts, and with Comments on, comments and one thread record per post whose comments were read. They are told apart by recordType (filter on it); the Post, Comment and Thread columns views each pick one kind's columns. The output schema lists every field.
| Record | Main fields |
|---|---|
| Post | id, url, subreddit, title, body, postType, link, images, video, flair, score, upvoteRatio, commentCount, createdAt, nsfw, stickied, locked, query, sort, rank |
| Comment | id, url, postId, parentId (the post or comment it answers), depth, position, body, authorFlair, score, createdAt, editedAt, isSubmitter, deleted |
| Thread (not charged) | postId, commentsStored, commentCount (Reddit's count), ended (why the reading stopped: readWhole, limit, depth, dateWindow and others) |
Posts and comments also carry author and authorId (Author names on, the default), scrapedAt, and missing: what the record lacks and why, such as author notRequested with Author names off, or a field Reddit's page did not give. Reddit's commentCount also counts comments it no longer shows, so a thread read whole stores fewer; its thread record says how many.
How to use Reddit Scraper
- Open Reddit Scraper in Apify Console.
- Enter subreddits or post links in Subreddits or posts, or Reddit searches in Searches, and choose the order, the period and the posts per subreddit.
- Narrow the posts under Filters if you need: posted after or before a day, post types, a minimum score, flairs, only posts open for comments.
- Turn Comments on to get each post's comments, and set how many per post, their order and the reply depth.
- For a schedule, name a Monitor: each run then stores only the posts new since the monitor's last run.
- Turn Author names off if you do not need who wrote each post and comment.
- Start the run, then download the dataset as JSON, CSV, Excel, XML or HTML, or read it through the API.
How much does it cost to scrape Reddit posts and comments?
Reddit Scraper is priced per event, with no usage fees on top:
| Event | Price | When |
|---|---|---|
post | $0.0015 | Each post stored |
comment | $0.0015 | Each comment stored (Comments on) |
check | $0.002 | Each subreddit a run with a monitor reads, new posts or not |
| Actor start | $0.00005 per GB of memory, at least one | Each run |
Prices shown are for Apify's free plan; on paid plans they are up to 30% lower.
For example, at the default 256 MB of memory:
- 1,000 posts cost $1.50, plus $0.00005 for the start.
- 200 posts with up to 10 comments each (2,000 comments) cost $0.30 + $3.00 = $3.30.
- A monitor of 10 subreddits run daily costs about $9.60 a month: 300 checks ($0.60) and, at 20 new posts per subreddit a day, 6,000 posts ($9.00). Run hourly, it costs about $23.40 a month: 7,200 checks ($14.40) and the same posts.
Not charged: thread records, posts a filter left out, posts a monitor stored in its earlier runs, pages that could not be read, and a run that stops on an input mistake (only the platform's start fee). Set a maximum total charge in the run options to cap a run; the Actor stops before it, and what it stored is kept.
Input example
The prefilled input below is a small run that finishes quickly; it reads posts only, as Comments starts off. API and agent calls that leave a field out get its default instead, which is larger for maxPosts (100) and maxComments (100):
Last week's posts of two subreddits, with up to 10 comments each:
One thread, every comment: {"queries": ["<a post's link>"], "includeComments": true, "maxComments": 0}.
A daily monitor: {"queries": ["SaaS", "smallbusiness"], "monitorName": "saas-daily"}, run on a schedule.
A search: {"searches": ["\"customer support\""], "searchSubreddits": ["SaaS"]} runs the phrase within r/SaaS; leave searchSubreddits out to search all of Reddit. "searchType": "comments" finds comments instead of posts.
Each field's description in the input tab gives its range and default. Filters apply to subreddits and searches; a post's link is read as given.
Output example
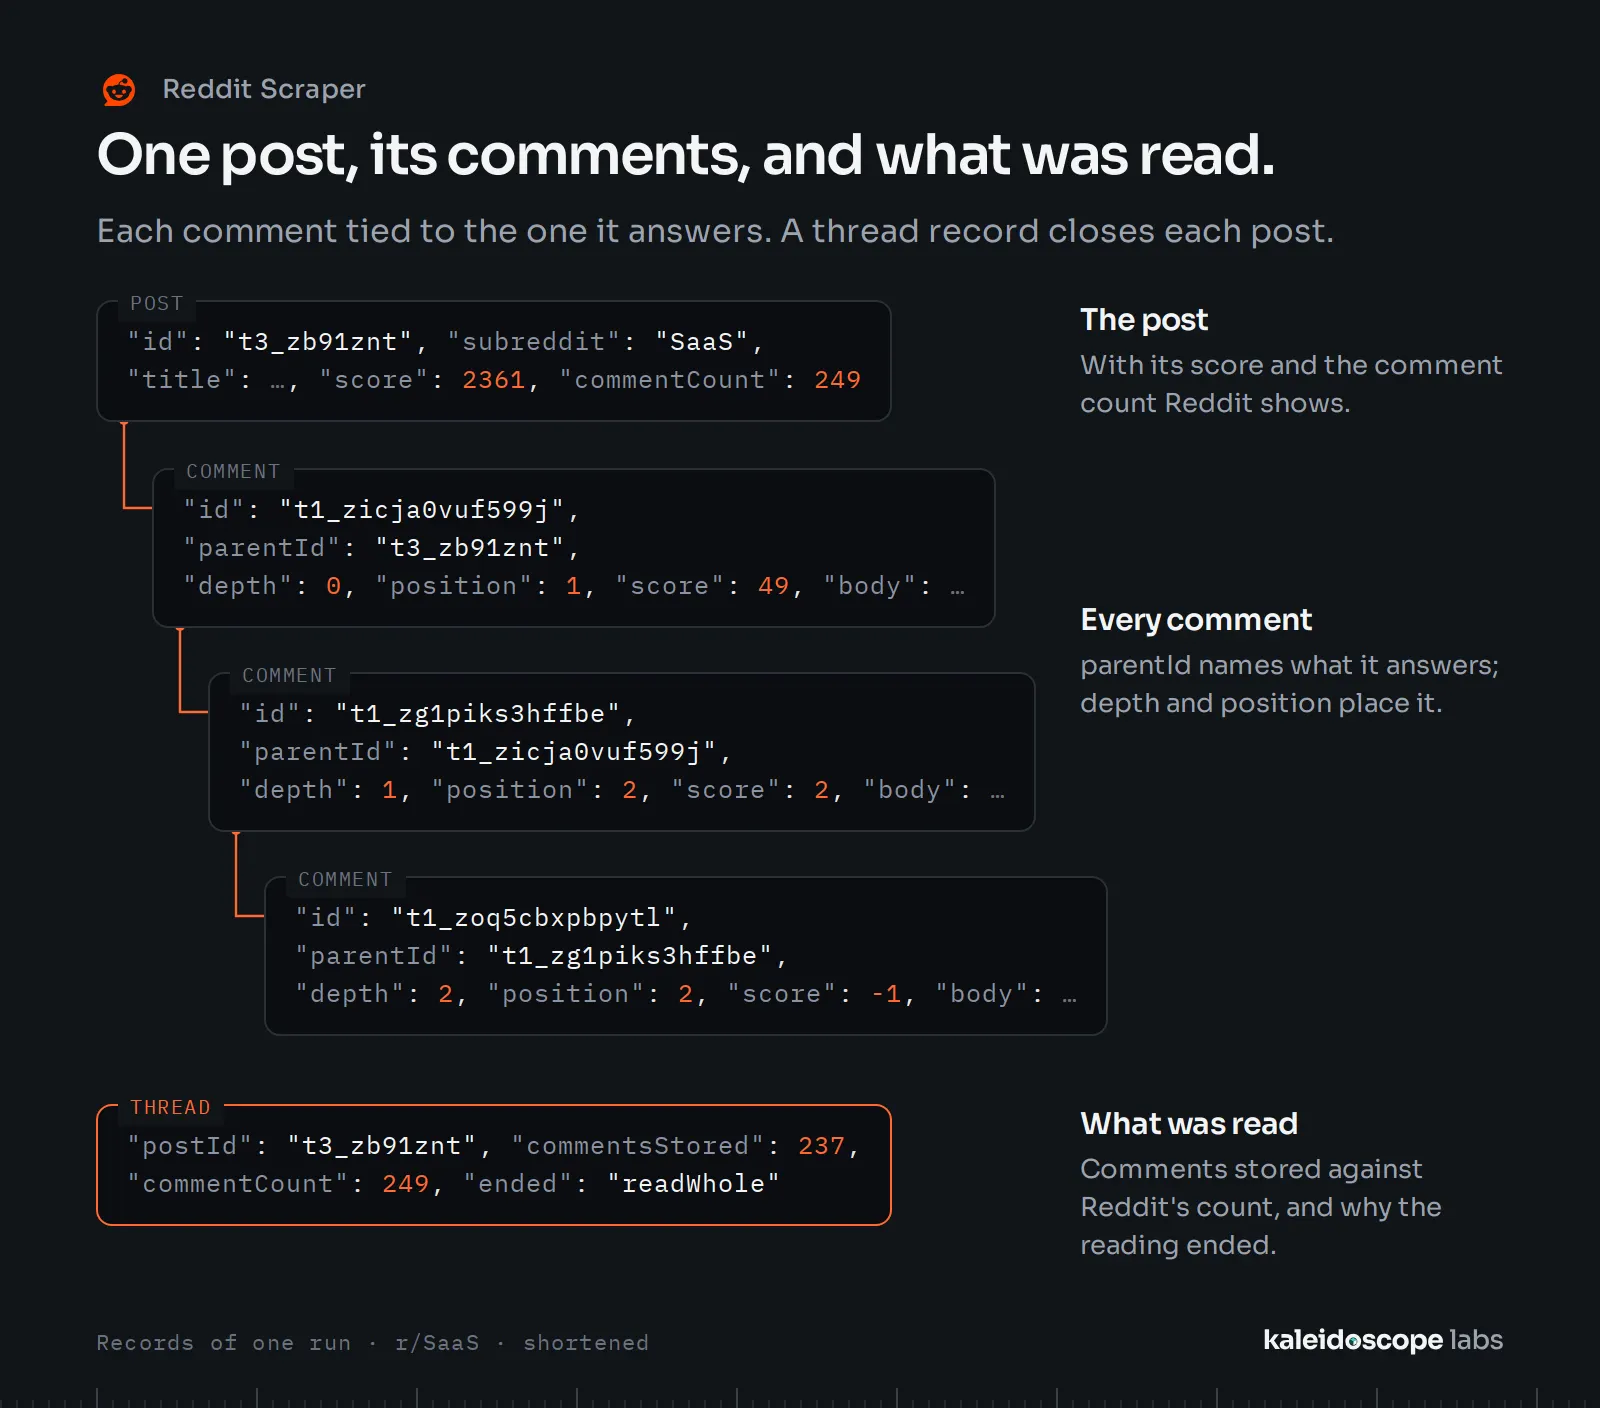
One item of the default dataset, from r/SaaS in the New order with Author names off, copied from a run:
With Author names on, the default, the record carries author (the username) and authorId, and missing leaves out the author.
For AI agents
AI agents can call Reddit Scraper through the Apify MCP server (setup prompt for your agent), or through the API like any other program.
- Minimal input:
{"queries": ["SaaS"]}gives the newest 100 posts of r/SaaS. Add"includeComments": true, "maxComments": 10for comments (the default of 100 per post costs about $15 for 100 posts). - Fields to read:
recordTypefirst; thentitle,body,score,createdAton posts,postId,parentId,bodyon comments,commentsStoredandendedon threads. - Empty results: an input mistake ends the run SUCCEEDED with an empty dataset; the key-value record RUN_SUMMARY then has
inputError(noQuery, invalidQuery, invalidSetting or notFound) andmessage. Itscompleteis false when the run ended short.missingsays what a record lacks; an empty field is never silent.
Did it save you time? A rating on this page helps others find it; an Issue tells us what to fix.
FAQ
Is it legal to scrape Reddit?
Reddit Scraper reads public pages only and needs no login. Whether you may use the data depends on your purpose, on the law that applies to you and on the terms of Reddit, so check them before you build on the results. When in doubt, ask a lawyer.
Does Reddit Scraper collect personal data?
These fields can carry personal data: each post's and comment's Author and Author ID. They are on by default, under Author names; turn it off to leave them out. Titles and texts are what people wrote and can name people too; with Author names off, records still link to the posts on Reddit, and a post made in a user's profile keeps that profile (u_name) in its subreddit and URL. Collect personal data only when you have a legal basis under the GDPR, KVKK or a similar law, and keep it no longer than you need it. When in doubt, ask a lawyer.
Why did my run return fewer posts or comments than I expected?
The target may have fewer matching posts than the maximum you set, a filter may have left posts out, or the run may have reached its maximum total charge; the run log says which. For comments, each thread record says how many were stored against Reddit's count and why the reading ended. A run has two hours by default: in our tests, 99 subreddits were read to the end in 45 minutes, and 1,000 posts with up to 10 comments each (5,666 comments) in 62 minutes.
How does the monitor work?
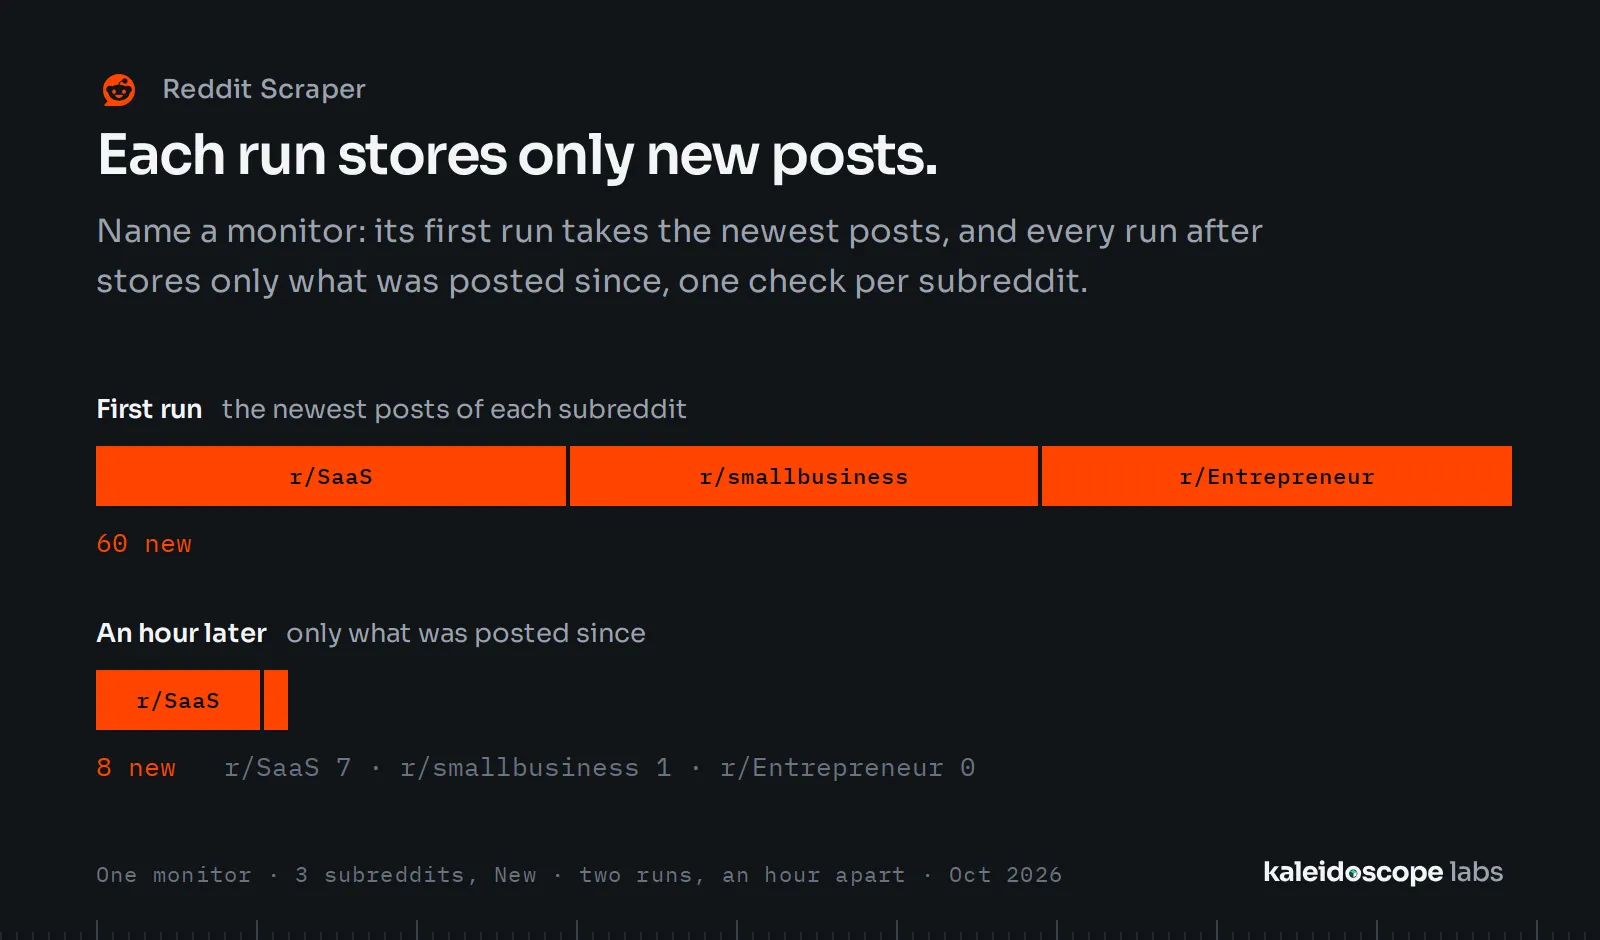
Name a monitor and schedule the run. Its first run stores up to Posts per subreddit from each subreddit as the baseline, charged as posts; after that, each run reads each subreddit in the New order down to the newest post the last run stored, so the dataset holds only new posts. Each subreddit read costs one check, new posts or not; the monitor's memory is a key-value store in your account named after it.
How do searches work?
Each line of Searches is run as you would type it into Reddit's search, across Reddit or within each subreddit under Search within, and its results are stored as posts, at the post price. Reddit's search results show less than a subreddit's feed, so with Comments off a search's post lacks its text, flair and link, named in missing as notInSearchResult; with Comments on, each post's own page is read and its record is whole. A monitor reads its searches in the New order, one check per search.
Can I connect Reddit Scraper to other tools?
Yes. Use Apify integrations, webhooks or the API to send the dataset to your tools every time a run finishes. AI agents can call it as a tool (see For AI agents).
Something went wrong: what should I check?
The run's last message says what happened. An input mistake names what to correct, and nothing is charged but the start. "Reddit has no subreddit named …" or "Reddit does not find the post" means the names or links are wrong, or the posts were removed. "Reddit stopped giving its pages" is usually temporary: run it again later. "The run's time ran out with pages left": resurrect the run to continue, or give it a longer timeout. For anything else, such as "a form this Actor does not read yet", open an issue with the Ref.
Limits
- Reddit lists about 1,000 posts per subreddit and order at most; for more, read another order or period.
- Public subreddits only: Reddit does not show a private or banned subreddit to a logged-out reader, and the run names it in its log.
- No user pages as input yet.
- Reddit's search may list no more than about 40 posts a search, whatever Posts per subreddit asks; run a monitored search often enough to catch them.
Tips
- Start from the prefilled input to see the output, then raise Posts per subreddit.
- Use the New order with Posted after to read a period exactly; in the other orders every post read is checked against the dates.
- With Comments on, set Comments per post: it decides most of a run's cost and time.
- Turn Deep threads on when the deepest replies matter: it also opens Reddit's "more replies" pages, and is slower.
Support and feedback
Open an issue on the Issues tab with the run's ID and the Ref from the run's last message: it tells us what happened without your data.
Other Actors
| Actor | Use it with this one to |
|---|---|
| YouTube Transcript API & Scraper | Turn the videos a subreddit discusses into text for the same research |
| Ads Transparency Center: Google Ads Scraper | See which of the companies people discuss advertise, and what their ads say |
| Meta Ad Library & Facebook Ad Library Checker | See whether the companies people discuss run Facebook and Instagram ads, how many, and the day the newest started |
Reddit Scraper is an independent tool, not affiliated with, endorsed by or sponsored by Reddit, Inc. Reddit is a trademark of Reddit, Inc.


