
Meta Ad Library Scraper
Pricing
from $0.70 / 1,000 ads
Meta Ad Library Scraper
Scrape Facebook and Instagram ads from Meta's Ad Library by keyword or advertiser page: ad text, headline, call to action, link, image and video URLs, format, platforms and run dates. One flat row per ad, with a hard cap. Export data, run via API, schedule runs.
Pricing
from $0.70 / 1,000 ads
Rating
5.0
(2)
Developer

Matvey
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
0
Monthly active users
2 days ago
Last modified
Categories
Share
Meta Ad Library Scraper turns Meta's public Ad Library into clean rows: for any keyword or any advertiser's page, every ad running on Facebook, Instagram, Messenger, Audience Network and Threads — headline, body text, call to action, destination link, image and video URLs, format, platforms and run dates, one flat row per ad.
$1 per 1,000 ads. The cap you set is checked before every request, so a run stops where you told it to and never bills you past it. Rows that explain a block or an empty result are free.
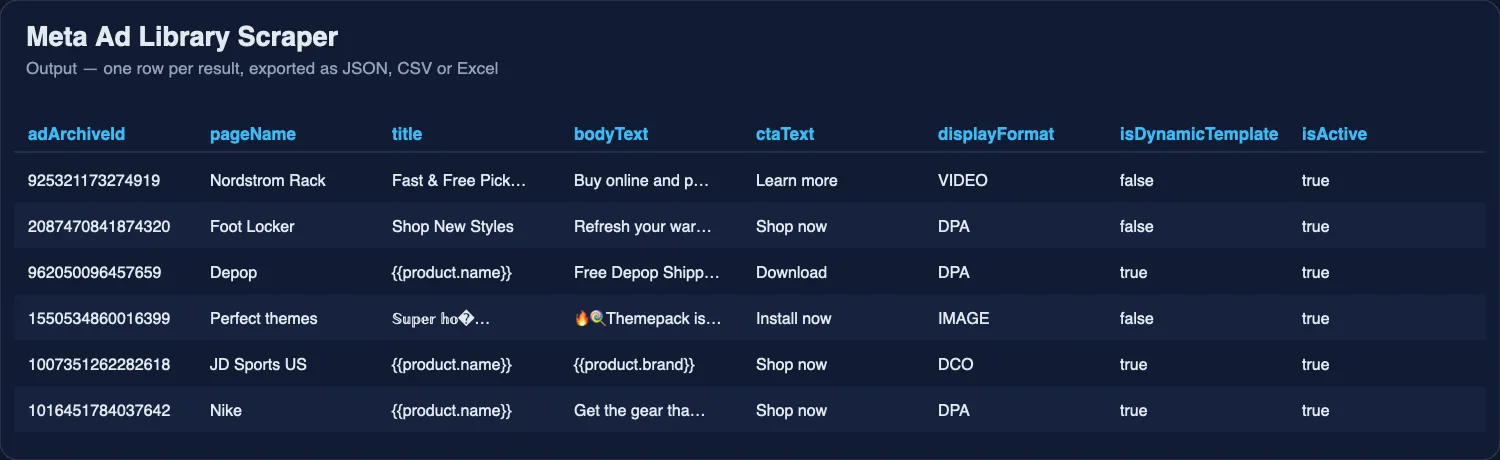
One run on the keyword «nike»: 30 ads in 7 seconds, 0.68 MB of traffic.
The whole thing, start to finish: a keyword in, 30 ads out in 6 seconds for $0.001, and a run summary that shows the cap was honoured. Watch the 84-second demo.
Paste a keyword or a page ID, press Start, and download JSON, CSV or Excel — or pull the rows through the API into Google Sheets, n8n, Make, a database or an AI agent.
What is Meta Ad Library Scraper?
Meta publishes every ad running on its platforms in the Ad Library, and offers an official API only for political and social-issue ads, behind an access review. This Actor is the Ad Library API alternative for everything else: competitor and creative research, ad-copy swipe files, agency reporting, e-commerce and dropshipping research, lead generation from active advertisers, brand protection, and political-ad monitoring.
It reads the same public data the Ad Library page shows any visitor, without a login and without an access review.
| You give | You get |
|---|---|
Keywords — nike, meal kit, crypto wallet | every matching ad, from every advertiser |
| Page IDs | every ad of one advertiser, their whole current campaign set |
| Country, status, format, platform, date range | the same filters the Ad Library page offers, applied by Meta itself |
| Political and social-issue shelf | the ads where Meta also publishes spend, impressions and reach |
What other Ad Library scrapers get wrong — and what this one does instead
The most-used Actor in this niche carries a 4.2 rating across 57 reviews and eight pages of open issues. Those complaints fall into three groups, and each one is a design decision here.
| What buyers write on other Actors | Meta Ad Library Scraper |
|---|---|
| "onlyTotal ignored — 127K items returned instead of 583, $95 wasted" | maxAds is counted here and checked before every request, not after rows arrive. Ask for 30, get 30 |
| "Instead of returning six results it kept scraping for an hour without signalling. I spent $17 for nothing" | One cap, one meaning. There is no second limit field that quietly does nothing |
| "Analyzed 3000+ ads despite less than 200 being active" · "Filter on Active ads not working" · "Mediatype prefilter issue (video)" | Meta accepts a date range and a media type and then ignores them — measured 19 September 2026: a search for ads started after 1 September returned 28 of 30 that started earlier, one in March 2025, and a video-only search returned 14 ads with no video. Here every row is re-checked on our side, an ad that fails a filter is never charged, and the run summary shows scanned against filteredOut so you can see how much of Meta's answer did not match |
| "Meta says 34k results but scraper only returned 2.5k" | Every run writes a summary with what you asked for, what was delivered, how many requests it took and why it stopped: MAX_REACHED, END_OF_RESULTS, NO_RESULTS or BLOCKED |
| "Actor gives incomplete data" · "Returning no ads results" | Meta answers a datacentre address with HTTP 200 and an empty body — it looks exactly like "no ads matched". This Actor detects that and says blocked in plain words instead of handing you an empty dataset |
| "Spend, reach and ad text never being pulled" · "ad spend around 100 billion, I doubt that is real" | Spend, impressions and reach exist only on the political and social-issue shelf. Set Ad type to that shelf and the columns carry Meta's own values (>$1M, $350K - $400K). On ordinary ads they are null, and the README says so rather than inventing a number |
| "After several runs the number of exported fields decreases even when selecting all fields" | A fixed row shape. Every ad has the same columns in the same order, run after run |
Raw Meta JSON with fev_info, tw_anti_scam, hide_data_status inside | A flat row in plain names. No unwrapping before a spreadsheet, an n8n node or a database can read it |
What data does it extract?
One row per ad. Values below are from a real run on the keyword nike, United States.
The ad
| Field | Example |
|---|---|
adArchiveId, adLibraryUrl | 925321173274919 · https://www.facebook.com/ads/library/?id=925321173274919 |
title, bodyText | "Fast & Free Pickup" · "Buy online and pick up in store for free! Get up to 70% off…" |
caption, linkUrl, linkDescription | display domain · destination URL · text next to the link |
ctaText, ctaType | "Learn more" · LEARN_MORE |
displayFormat | IMAGE, VIDEO, DPA, DCO, CAROUSEL |
imageUrls, videoUrls | direct media URLs — links, not downloads, so nothing bloats your run |
cardCount, cardTexts | carousel cards and the text on each |
isDynamicTemplate | true when the headline still reads {{product.name}} — catalogue ads are served that way, and a flag beats a surprise |
isActive, startDate, endDate | true · 2026-08-03 · 2026-09-30 |
publisherPlatforms | ["FACEBOOK","INSTAGRAM","MESSENGER"] |
variantCount | how many near-identical variants Meta groups under this ad |
The advertiser
| Field | Example |
|---|---|
pageId, pageName, pageUrl | 89516513179 · Nordstrom Rack · link to the page |
pageLikes, pageCategories, pageProfilePicture | 2 518 019 · page categories · avatar URL |
Transparency — political and social-issue ads only
| Field | Example |
|---|---|
spend, currency | ">$1M", "$350K - $400K" · USD |
impressionsText, reachEstimate | ">1M" · ">1M" |
categories, targetedCountries | ["POLITICAL"] · countries the ad was aimed at |
Meta publishes these for the political shelf and for nothing else. On commercial ads they are null, and that is Meta's limit, not a bug in the Actor.
How much does it cost to scrape the Meta Ad Library?
$1 per 1,000 ads delivered. One ad, one row, one charge — ads are deduplicated inside a run, so a keyword that matches the same ad twice is billed once.
- No start fee, no rental, no per-run charge.
- Diagnostic rows are free: a block, a bad page ID or an empty result costs nothing.
- The cap is real.
maxAdsis checked before each request. A run cannot overshoot it. - Higher Apify plans pay less: Bronze $0.90, Silver $0.80, Gold and above $0.70 per 1,000.
- The $5 of free credit on Apify's free plan is about 5,000 ads before you pay anything.
How to scrape the Meta Ad Library
- Click Try for free and sign in to Apify.
- Put keywords into 🔍 Search keywords, or page IDs into 📄 Facebook page IDs.
- Set 🌍 Country — Meta indexes ads per country, so this decides which ads exist at all.
- Set 💯 Maximum ads. The default of 30 finishes in seconds.
- Press Start, then download JSON, CSV or Excel, or read the dataset through the API.
⬇️ Input
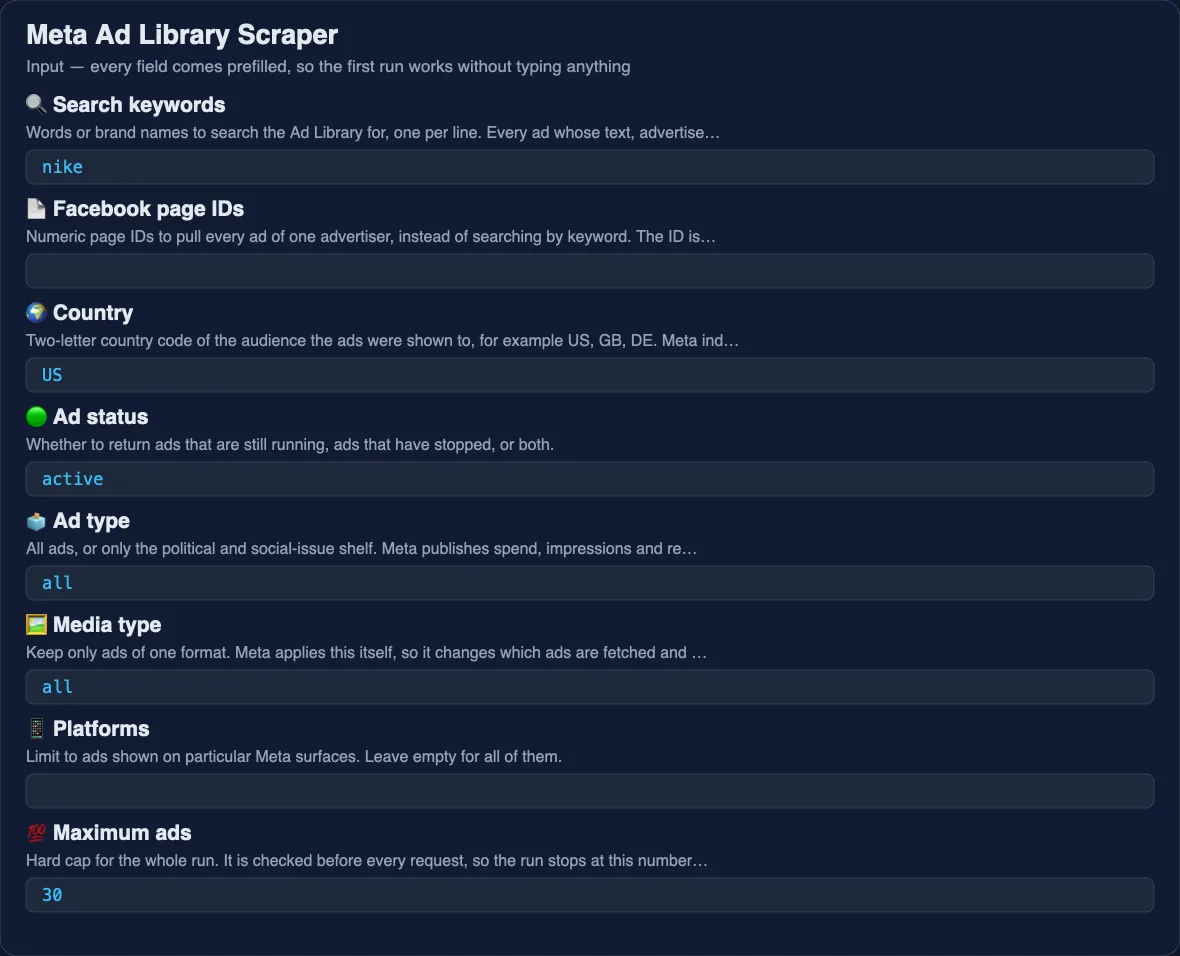
Every ad of one advertiser:
Political ads with spend and reach:
⬆️ Output
Run summary
Every run writes a RUN_SUMMARY record to the key-value store:
That is the answer to "Meta says 34k, I got 2.5k": you can see what was asked, what arrived, and why it stopped. scanned and filteredOut appear per target when a date range or a media type is set — on one measured run, 181 ads were read from Meta, 161 did not match the date filter, and 20 were delivered and charged.
Use cases
Competitor and creative research
Pull every active ad of a competitor by page ID and you have their current positioning: which products they push, which hooks they repeat, which formats they bet on, and how long each ad has been running. startDate plus isActive is the closest public proxy for what is working — advertisers do not keep losing creatives alive.
Ad copy and hook libraries
title, bodyText, ctaText and cardTexts across a whole vertical give you a swipe file in a spreadsheet instead of a folder of screenshots.
E-commerce and dropshipping research
Search a product category, sort by how long ads have run, and read linkUrl to see which stores are behind them.
Agency reporting and pitching
Show a prospect what their competitors are running today, with dates and platforms, straight from Meta's own public record.
Political ad monitoring
On the political shelf every row carries spend, impressions and reach ranges. Schedule a daily run over a set of keywords or pages and you have a spend timeline of a campaign.
Lead generation
An advertiser running ads is an advertiser with a budget. pageName, pageUrl, pageLikes and pageCategories qualify them before you ever write the first line of outreach.
AI agents
Pay-per-event, limited permissions, no Standby — callable from the Apify MCP server. "What is this brand advertising right now?", "Which ads has this page run since August?", "How much has this campaign spent?"
Integrations
API, scheduler, webhooks, and the connectors for n8n, Make, Zapier, Google Sheets, Slack, LangChain and LlamaIndex.
MCP server
Point an agent at https://mcp.apify.com?tools=lergassy/meta-ad-library-scraper and it can call this Actor as a tool.
Error rows and troubleshooting
Problems become rows, and none of them are charged.
errorCode | What it means | What to do |
|---|---|---|
blocked | Meta did not serve this exit address — usually a datacentre proxy | Leave the proxy on its residential default |
no-results | The search genuinely matched nothing | Widen the country, the date range or the status; check the page ID |
no-input | Neither a keyword nor a page ID was given | Fill one of them |
scrape-failed | Something unexpected, with Meta's own message attached | Open an issue with the run id |
❓ FAQ
Is it legal to scrape the Meta Ad Library?
The Ad Library is published by Meta deliberately, as advertising transparency, and is readable without an account. This Actor reads that public record and bypasses no protection. How you then use the data — republishing creatives, storing personal data — is a separate question governed by copyright, by data-protection law and by Meta's terms. Use it for research and analysis, and take legal advice before republishing someone's creative.
Do I need a Facebook account or an API access review?
No. Meta's official Ad Library API covers political and social-issue ads and requires identity verification; this Actor needs neither.
Why are spend and reach empty?
Because Meta only publishes them for political and social-issue ads. Set Ad type to that shelf and they fill in. No scraper can produce them for a commercial ad, and one that shows a number there is showing you something invented.
Why does a headline say {{product.name}}?
That is a catalogue ad whose headline is generated per product at delivery, and the Ad Library stores the template. The row carries it verbatim and flags it with isDynamicTemplate.
Can I get every ad of one advertiser?
Yes — put their numeric page ID into 📄 Facebook page IDs. It is the pageId on any row of theirs, and the view_all_page_id in an Ad Library URL.
Will the run stop where I tell it to?
Yes. maxAds is checked before every request. That is the main reason this Actor exists.
Can I use it through an MCP server?
Yes — see Integrations.
Your feedback
Found an advertiser or a country where results look wrong? Open an Issue with the run id — that is the fastest way to get it fixed. If it did the job, a short review helps more than anything I can write myself.
You might also like
| Actor | What it does |
|---|---|
| Threads Scraper | Posts, replies, profiles and keyword search on Meta Threads |
| YouTube Transcript Scraper | Transcripts with timecodes from videos, playlists and channels |
| Website Contacts API | E-mails, phones and social links from any website |
| Email & Phone Verifier | Checks contacts before you send anything |


