
Website Contact Scraper
Pricing
from $10.50 / 1,000 website with contacts
Website Contact Scraper
Extract contacts from any list of websites: e-mails, phone numbers, WhatsApp, Telegram, social profiles, contact page and postal address. One clean row per website, priced per website, not per page. No API key, no proxy, no browser. Run via API, schedule runs, or call from AI agents.
Pricing
from $10.50 / 1,000 website with contacts
Rating
5.0
(1)
Developer

Matvey
Maintained by CommunityActor stats
0
Bookmarked
17
Total users
9
Monthly active users
3 days ago
Last modified
Categories
Share
Website Contact Scraper turns a list of websites into a ready-to-use contact list: e-mail addresses, phone numbers, WhatsApp and Telegram links, social profiles, the contact page and the postal address — one clean row per website, each contact carrying the page it was found on. No API key, no login, no proxy, no browser. You pay per website, never per page. Export to JSON, CSV or Excel, run it via API, schedule it, or plug it into n8n, Make, Zapier, Google Sheets or an AI agent through MCP.
Tested head-to-head — 24 September 2026
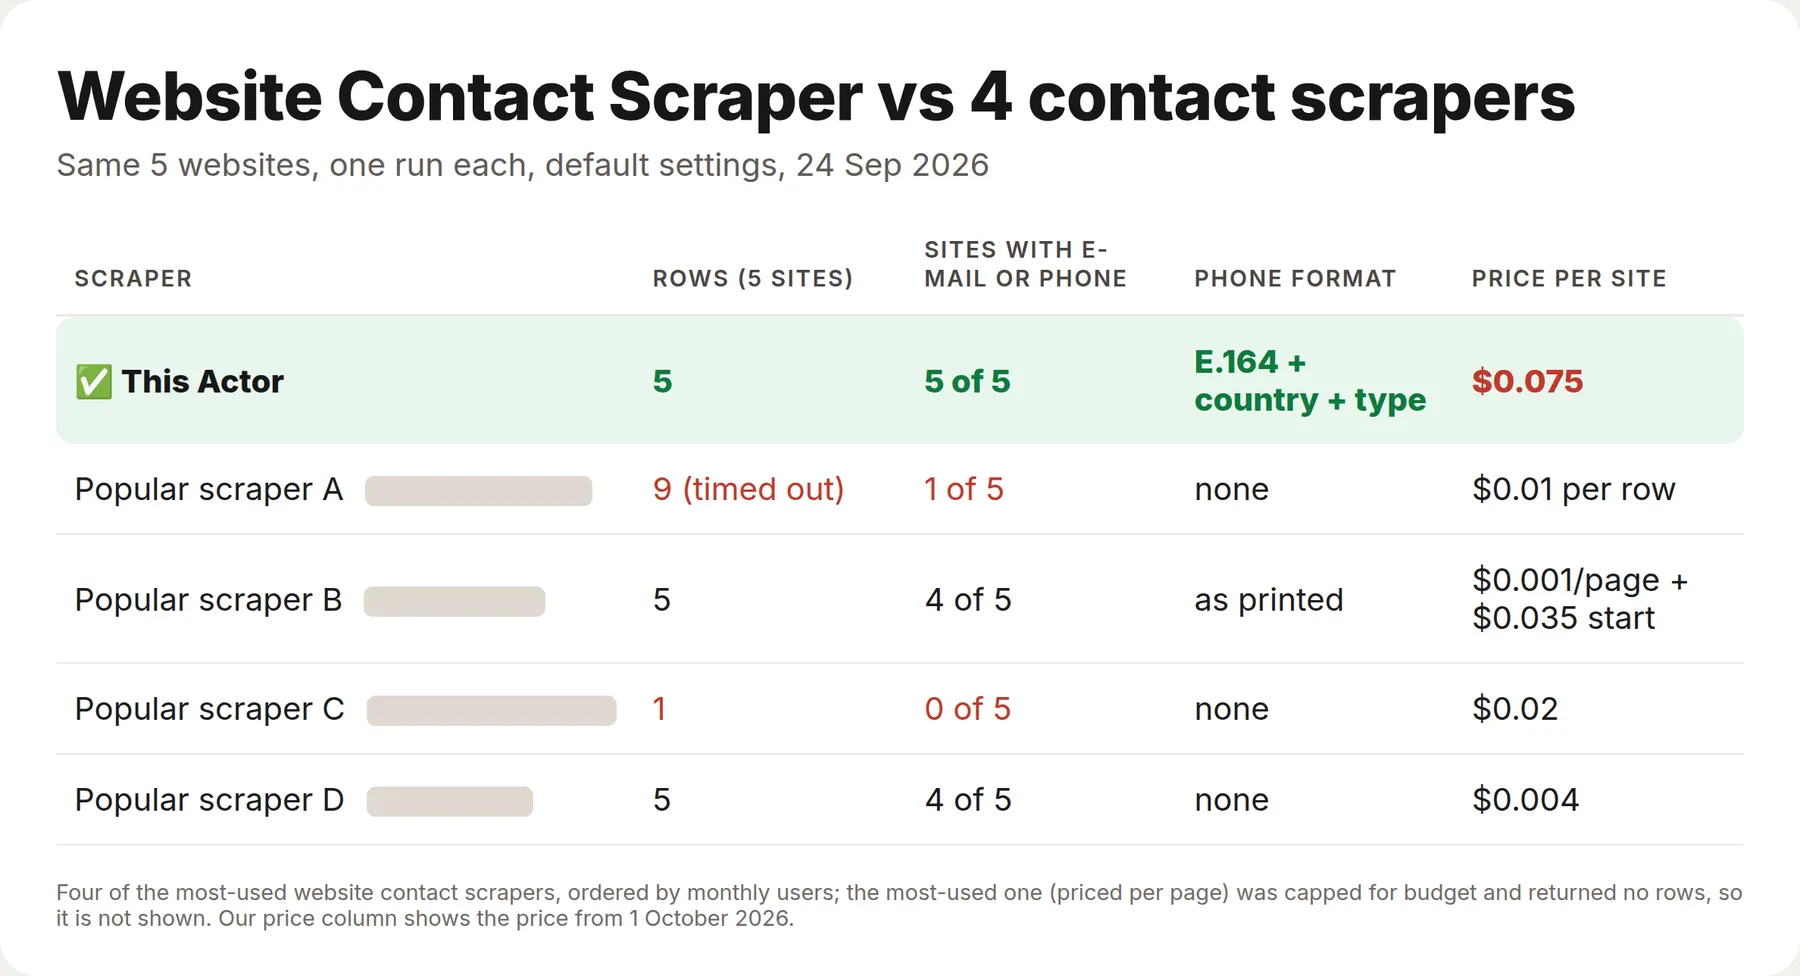
The same five websites — a SaaS company, a software vendor, a foundation, a Las Vegas dental group and an online coffee brand — went into this Actor and into four other contact scrapers from the Apify Store, each run once from the same account with its default settings. (The most-used one was also tried, capped at 60 pages to fit the test budget, and returned no rows, so it is left out of the table.)
| This Actor | The 4 others | |
|---|---|---|
| Websites with an e-mail or phone found | 5 of 5 | 4 of 5 at best |
| Phone numbers | E.164, with country and number type | as printed on the page, or none |
What is Website Contact Scraper?
Website Contact Scraper turns a list of websites into a contact list: one clean row per website with the company's e-mail addresses, phone numbers, WhatsApp and Telegram links, LinkedIn, Facebook, Instagram, X, YouTube and TikTok profiles, contact page, contact form and postal address — each contact with the page it was found on and how it was found. Paste domains from Google Maps, a CRM export or a spreadsheet, press Start, and download the contacts as JSON, CSV or Excel, or pull them through the API into n8n, Make, Zapier, Google Sheets or an AI agent.
It reads the home page and the few pages that actually carry contacts (contact, about, team, imprint, legal), decodes Cloudflare-protected addresses and name [at] domain [dot] com obfuscation, reads schema.org markup, validates every phone against the international numbering plan, even reads the hidden search index of Framer sites that show nothing without JavaScript, and on Shopify stores reads every content page the store publishes plus its privacy and terms pages — where staff, press and wholesale addresses usually sit (deathwishcoffee.com: 10 addresses instead of 1). No API key, no login, no proxy, no browser.
The price is per website, not per page. You pay one flat event for every website where at least one e-mail or phone was found. Websites with nothing found, unreachable or blocked websites are free, and the number of pages read never changes your bill — so a 1,000-row list costs what the pricing tab says, not twenty times more.
What data does Website Contact Scraper extract?
| Field | Example | Where it comes from |
|---|---|---|
bestEmail, bestEmailType | hello@apify.com, role | The best address: the site's own domain first, general inboxes (info@, hello@, contact@) over side mailboxes, mailto links over page text |
emails[] | {email, type, isOwnDomain, isFree, source, sourceUrl} | Every distinct address with its type (role, personal, generic), whether it is on the website's own domain, whether it is a free mailbox (gmail.com …), and the source: mailto, schema.org, cloudflare or text |
bestPhone, bestPhoneFormatted | +18884827768, +1 888 482 7768 | Best number in E.164, tel links first |
phones[] | {phone, formatted, country, kind, source, sourceUrl} | Every valid number with country, kind (mobile, fixed_line, toll_free …) and source (tel, schema.org, whatsapp, text) |
whatsapp, telegram | https://wa.me/628179677771 | Messenger links; the WhatsApp number is also added to phones |
linkedin, facebook, instagram, x, youtube, tiktok, pinterest, threads, github | https://linkedin.com/company/apify | Normalised profile URLs; share buttons, login pages and hashtags are ignored |
contactPageUrl, contactFormUrl | https://apify.com/contact | The contact page that was read and the page with a contact form |
addressStreet, addressCity, addressRegion, addressPostalCode, addressCountry | 2 Canal Park, Cambridge, MA, 02141, US | schema.org PostalAddress; addressText falls back to an <address> tag |
companyName | HubSpot | schema.org Organization, og:site_name or the page title |
status, note | ok, javascript_rendered_site | ok, no_contacts, unreachable, blocked; the note tells you when a site is an empty JavaScript shell |
pagesScanned, pagesScannedCount, durationMs, fetchedVia | […], 3, 1497, fetch | What was read and how long it took |
summary | HubSpot: +18884827768 (2 e-mails, 25 phones); linkedin, facebook, instagram, x, youtube, tiktok. | One sentence for agents, Slack alerts and spreadsheets |
emailChecks[], bestEmailStatus | deliverable | Only with the e-mail check add-on: DNS-level deliverability, mail provider, disposable / role / free flags, typo suggestion |
Every row also carries inputUrl, website (final URL after redirects), domain, language, phoneCountryUsed and scrapedAt. Failed websites come back as type: "error" rows with status, httpStatus and error, so a batch never silently loses a domain.
How much does it cost to extract contacts from websites?
Website Contact Scraper uses pay-per-event pricing with two events:
| Event | Price | When it is charged |
|---|---|---|
| 🌐 Website with contacts | $75.00 per 1,000 websites ($0.075 each) | Once per website where at least one e-mail or phone number was found |
| ✅ Add-on: e-mail check | $10.00 per 1,000 addresses | Only when you switch the add-on on, once per checked address (up to 20 per website) |
These prices apply from 1 October 2026. Until then the same events cost less: $0.015 per website with contacts and $0.002 per e-mail check.
What is free: websites with no contacts, unreachable domains, websites behind an anti-bot wall, and every page read. Apify platform usage is included in the price — you do not pay separately for compute, and there is no proxy cost because none is used by default.
The bill is known before the run: a list of 1,000 websites costs at most $75, and less when some of them publish no contact, because empty sites are not billed. The number of pages read per site never changes it. Apify's free plan includes $5 of usage every month, enough for roughly 65 websites with contacts.
Bulk export
This Actor is built for bulk jobs — put hundreds of inputs into one run, or call it from the API on a schedule. There is no fee per run, no fee per page and no proxy charge: you pay for the rows you keep, and error rows are free, so a 50,000-row job costs exactly 50,000 × the row price with nothing added on top.
How to extract contacts from a list of websites
- Open Website Contact Scraper on Apify and click Try for free (an Apify account is created in a minute).
- Paste your websites into 🌐 Websites — one per line, with or without
https://— or bare domains into 🌐 Domains. You can also upload a text file or link a Google Sheet through the ⬇️ Input editor. - Optionally set 📞 Default phone country (used only for numbers written without a country code; a site's own country domain always wins) and switch on the ✅ e-mail check add-on.
- Click Start. A hundred websites take about a minute.
- Open the Contacts tab to read the results, or Export them as CSV, Excel, JSON or XML.
⬇️ Input
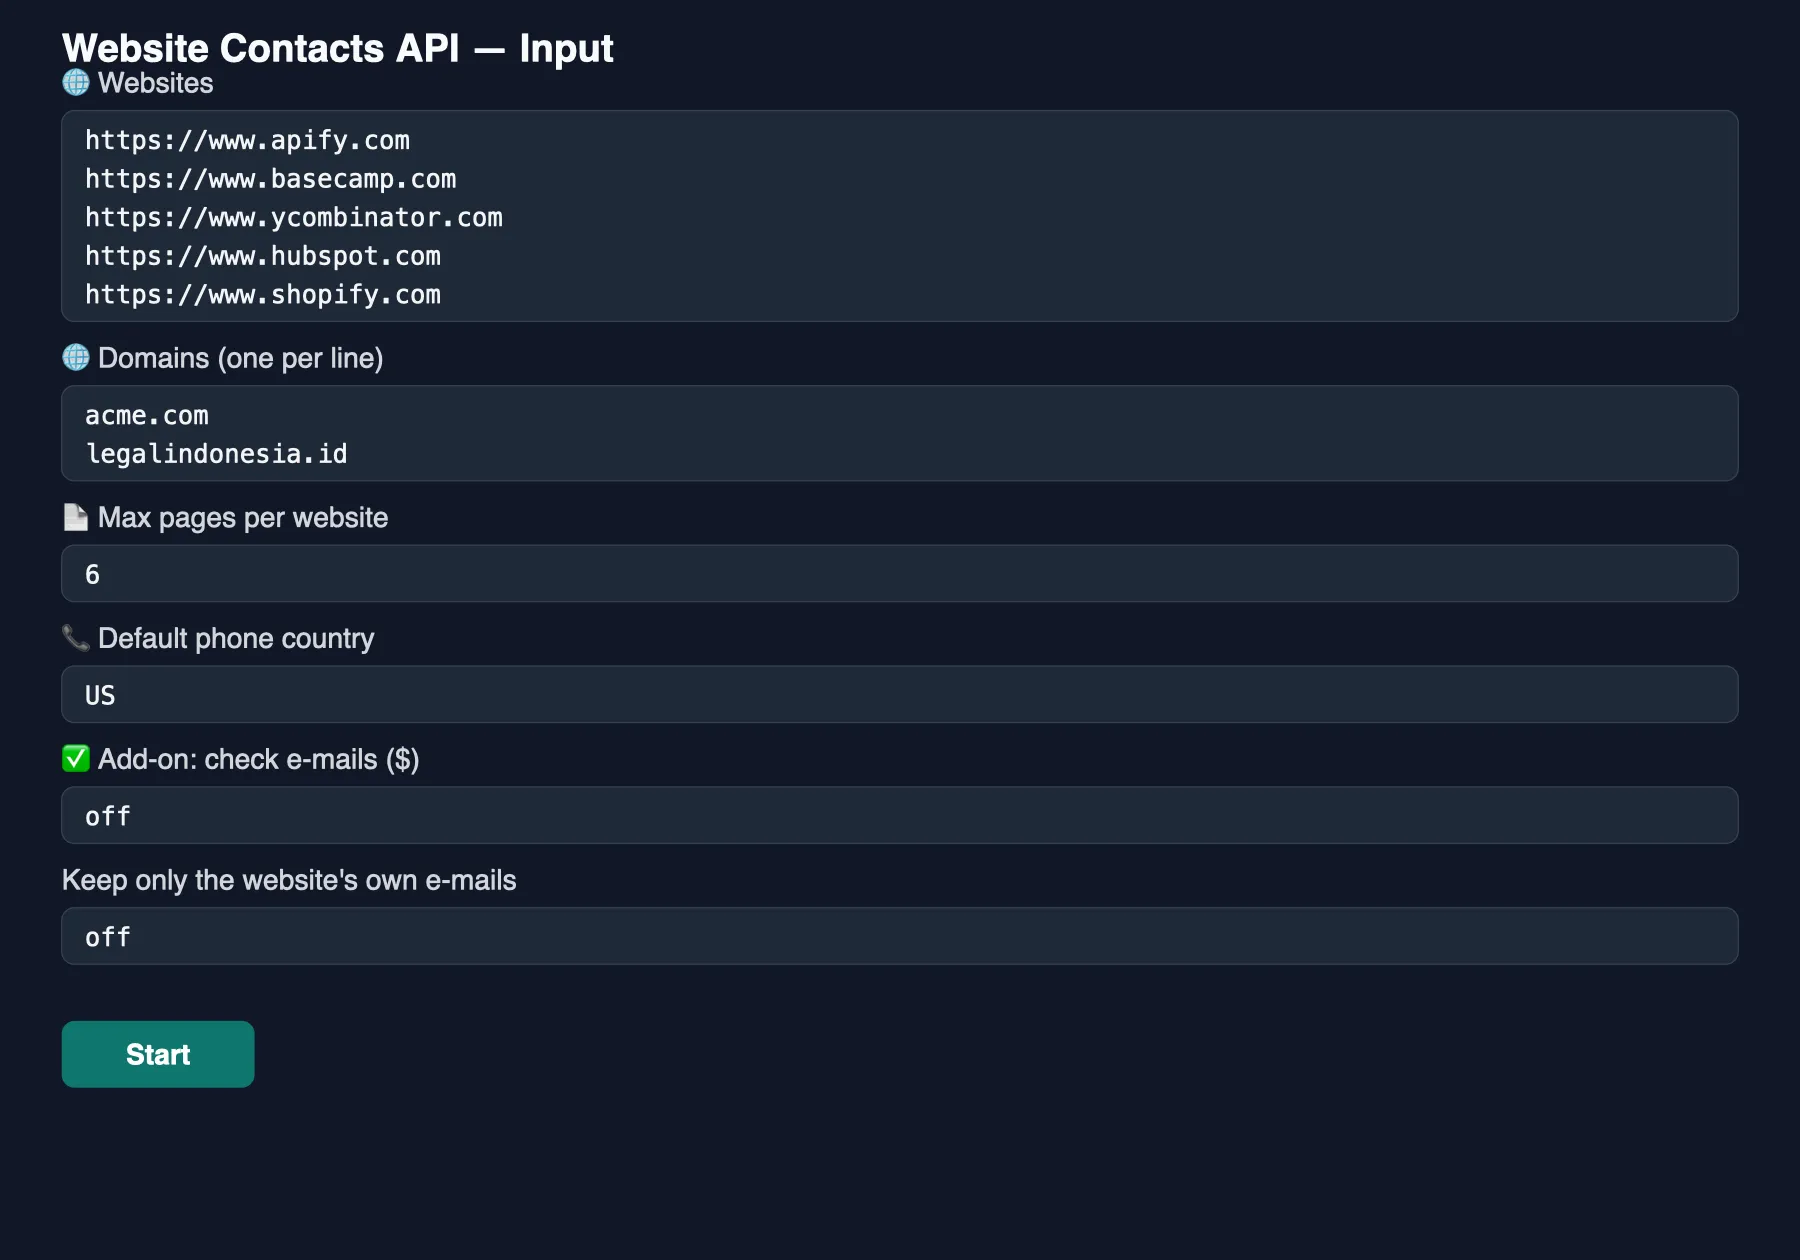
| Field | Default | What it does |
|---|---|---|
startUrls | 5 example sites | Websites as URLs; the Apify editor accepts a pasted list, a file or a Google Sheet |
domains | [] | Bare domains, one per line — for lists exported from Google Maps or a CRM |
maxPagesPerSite | 6 | Home page plus the most contact-like pages; 6 finds nearly everything on a normal business site |
defaultCountry | US | Two-letter country used for phone numbers without a country code |
checkEmails | false | Add-on ($): DNS deliverability, provider, disposable / role / free flags per address |
onlyOwnDomainEmails | false | Drop addresses on other domains (an agency, a partner, a gmail.com mailbox) |
stopEarly | true | Skip remaining pages once an own-domain e-mail and a phone were found |
maxWebsites, concurrency, pageTimeoutSecs, proxyConfiguration | 1000, 10, 15, off | Safety cap, parallelism, per-page timeout, optional Apify Proxy |
🌐 Which pages are read?
The home page first. Then links whose path or text says contact, kontakt, contacto, contatti, impressum, imprint, about, team, support, legal, privacy, locations and their equivalents in a dozen languages, best-scored first. If the navigation is rendered by JavaScript and no such links exist, the well-known paths /contact, /contact-us, /about, /about-us, /impressum and /kontakt are tried. Blog posts, product pages, carts and search pages are never read.
⬆️ Output
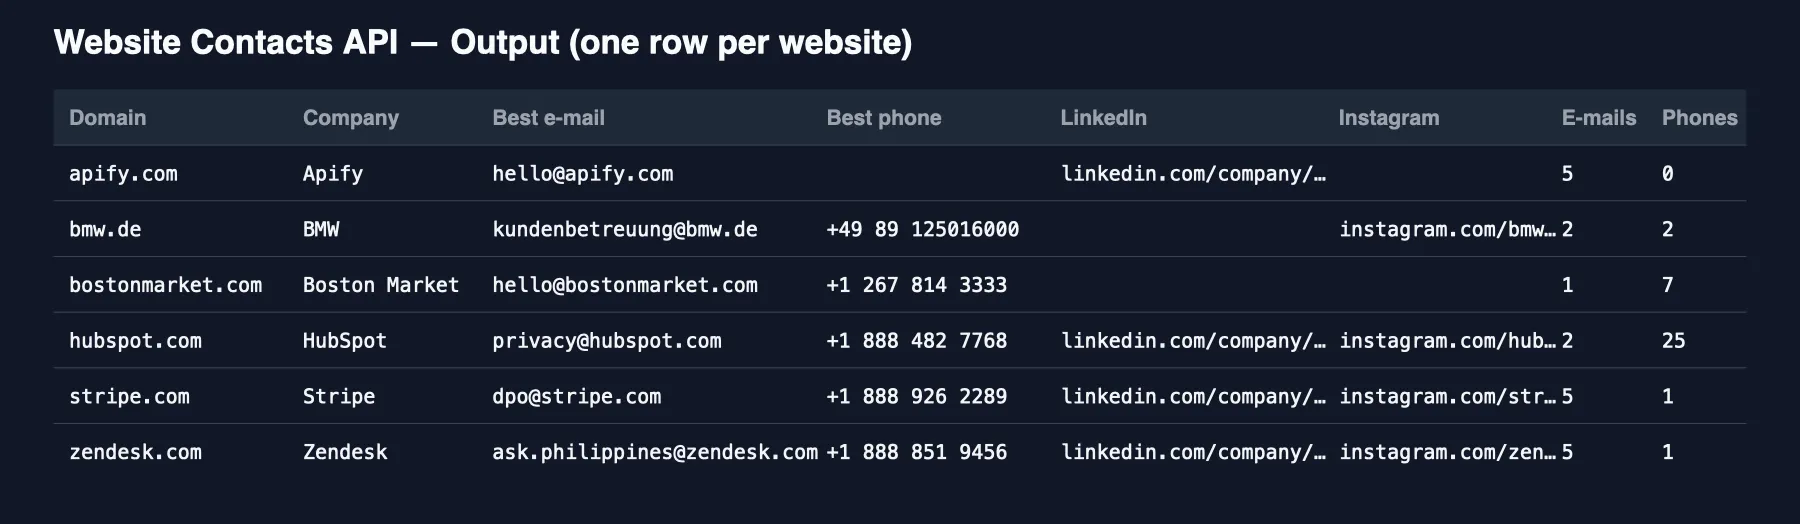
One row per website:
An unreachable or blocked website:
📧 How e-mails are found and cleaned
mailto:links, schema.orgemail, Cloudflare-protected addresses (data-cfemailand/cdn-cgi/l/email-protectionlinks are decoded), and addresses written in the page text, includingname [at] company [dot] comandname (at) company.com.- Addresses found only in prose are kept only when their domain really exists (a DNS check), which removes the "partner@YC. He…" class of false matches that page-text scrapers produce.
- Placeholders (
example@,yourname@,test@), template domains (example.com,yourdomain.com), error-tracker addresses (sentry.io,wixpress.com) and image file names that contain an@are dropped. typeisrolefor function mailboxes (info@, sales@, support@, privacy@ …),personalforfirst.last@shapes, andgenericfor everything else (a country office, a brand word, a first name alone). The distinction is a heuristic, not a promise.
📞 How phones are validated
Every candidate goes through the international numbering plan (libphonenumber): the number must be valid for its country, with the country taken from a + prefix, else from the site's country domain (.de, .co.uk, .id …), else from 📞 Default phone country. Numbers in page prose need at least seven national digits, so order numbers and dates are not reported as phones. WhatsApp links (wa.me/…) are read as phone numbers as well.
Use cases for website contact data
🎯 Lead generation and outreach
Export businesses from Google Maps, a directory or a trade-show list, run the domains through Website Contact Scraper and get the general inbox, a direct phone and the LinkedIn page for each — with the page each contact came from, so an SDR can check it in one click.
🧹 CRM enrichment
Fill the empty e-mail, phone and social columns of an existing account list. isOwnDomain and isFree tell you whether an address is the company's own or a sole trader's gmail.com mailbox before it enters a sequence.
🤖 AI agents and workflows
One flat row per website with a ready summary sentence is what an agent needs: give it a company website, get back who to contact. The Actor is listed for the Apify MCP server, and its input needs nothing but a list of websites.
🔎 Research and due diligence
Registered addresses from schema.org markup, imprint pages and the contact channels a company actually publishes — useful for supplier checks, partnership research and compliance reviews.
Integrations
- API — start a run and read the dataset with any HTTP client, or with the Apify client for Python and JavaScript.
- n8n, Make, Zapier — use the Apify node/module, pick this Actor, map
startUrlsordomainsfrom your sheet, and writebestEmail,bestPhone,linkedinback. Rows are flat, so mappers show every field. - Google Sheets — schedule a run and export the dataset as CSV, or use the Apify Google Sheets integration.
- MCP server — call it from Claude, ChatGPT or any MCP-capable agent through the Apify MCP server;
summaryis written for that. - Webhooks — get notified when a run finishes and fetch the dataset in your own code.
Limits and honest notes
- JavaScript-only sites. A home page that is an empty shell (some Wix apps, single-page apps) yields
status: no_contactswithnote: javascript_rendered_site. Framer sites are handled through their search index. A browser mode may be added if enough users ask — open an Issue. - Anti-bot walls. Large sites behind Akamai, DataDome or Cloudflare challenges come back as
status: blocked, free of charge. Business websites rarely have them; the Chrome-fingerprint fallback clears the simpler ones without a proxy. - E-mail check is domain-level. It tells you whether the domain accepts mail, who hosts it, and whether the address is disposable or a role account. It cannot confirm that a specific mailbox exists — no service can do that reliably without sending mail, and the ones that claim to are guessing for Gmail and Microsoft 365 domains.
- Public data only. The Actor reads what the website publishes to any visitor. It never logs in, never guesses addresses and never pulls data from third-party databases.
❓ FAQ
Is it legal to extract contact details from websites?
The Actor collects only information that the website publishes to every visitor, which is generally lawful to collect. What you may do with it — cold outreach, storage, profiling — is governed by laws such as GDPR, CAN-SPAM and local rules on unsolicited messages. Consult a lawyer for your use case; personal e-mail addresses in particular carry obligations.
Why is it priced per website and not per page?
Because a website is what you want back. The Actor reads only the pages that carry contacts — usually three to five — and charges once per website that gave at least one e-mail or phone, so the bill does not grow with the size of the site and empty sites are not billed at all.
Can I pass bare domains without https://?
Yes — put them in 🌐 Domains, one per line. The 🌐 Websites field needs full URLs because it also accepts files and Google Sheets.
Why is bestEmail info@ when a personal address was also found?
The general inbox is the address a company chooses to publish as its contact, so it ranks first. Personal addresses are still in emails[] with type: "personal". Set your own rule in your workflow if you prefer them.
Does it work through the Apify API and the MCP server?
Yes. Every run can be started through the API, and the Actor is listed for the Apify MCP server so AI agents can call it directly.
Can I integrate it with Google Sheets, n8n or Make?
Yes — see Integrations above. Rows are flat, so every field maps to a column.
Does the run stop when I run out of budget?
Set Max total charge on the run (or in the n8n node). The Actor charges only after a website has been written to the dataset, so you always keep what you paid for.
Your feedback
Found a site where a published address was missed or a wrong number was reported? Open an Issue on this page with the URL — every report is answered, and fixes ship within days. Reviews help other buyers find the Actor.
You might also like
| Actor | What it does |
|---|---|
| Email & Phone Verifier | Deliverability signals, disposable and role flags, US area code, state and time zone for a list of e-mails and phones |
| US Business Leads | Newly registered US businesses from state registries with owner contacts and a lead score |
| Website Business Evidence | Is a website a real, active business? Signals from the site itself |
| Google Flights Scraper | Flight prices and itineraries from Google Flights |


