
YouTube Shorts, TikTok & Reels Transcript Scraper
Pricing
from $1.40 / 1,000 videos
YouTube Shorts, TikTok & Reels Transcript Scraper
One run for all three platforms: YouTube Shorts, TikTok and Instagram Reels turned into text — transcript with timestamps, on-screen captions and the first-3-second hook. Shorts use YouTube's own captions, so they cost less. Links or whole profiles, no login.
Pricing
from $1.40 / 1,000 videos
Rating
0.0
(0)
Developer

Matvey
Maintained by CommunityActor stats
0
Bookmarked
7
Total users
4
Monthly active users
a day ago
Last modified
Categories
Share
YouTube Shorts, TikTok & Reels Transcript Scraper covers all three short-video platforms in one run — without a login, cookies or an official API. Paste links, or a TikTok handle and a YouTube channel, and get one clean row per video: transcript with timestamps, the text burned into the picture, and the first-3-second hook.
YouTube Shorts use the caption track YouTube has already made, so they come back in seconds and are billed at the video price alone, with no charge for audio.
If you only ever work with one platform, we keep narrower Actors for TikTok and Instagram Reels — same engine, same price, a simpler form.
What is YouTube Shorts, TikTok & Reels Transcript Scraper?
YouTube Shorts, TikTok & Reels Transcript Scraper turns a short vertical video into structured text: the spoken transcript, the text written on screen, and the first three seconds of both — the hook. It works on Instagram Reels, TikTok videos and YouTube Shorts, with no login, no cookies and no official API needed.
Most transcript scrapers stop at the audio. In short-form video the audio is often not where the message is: in our test set of 26 real videos, only 69% carried a narrated script, 19% had no usable speech at all, and 12% ran on someone else's trending sound. 81% had text on screen. An actor that reads only the audio returns noise or nothing on roughly a third of a real feed.
This one reads both, tells them apart, and says which kind of video you gave it.
What data can YouTube Shorts, TikTok & Reels Transcript Scraper extract?
| Field | Example |
|---|---|
transcriptText | Today, I wanted to do a quick tips and tricks or best practices for posting reels… |
firstThreeSecondsSpeech | Today, I wanted to do a quick tips and tricks or best practices for |
onScreenText | Reels Tips & Tricks, No Watermarks, Under 3 Minutes, Add Music/Audio |
firstThreeSecondsOnScreen | Reels Tips & Tricks |
contentClass | narrated · borrowed_audio · silent · empty |
speechDetected, speechCoverage | true, 0.89 |
burnedInCaptionCount | 41 |
screenRecording | false |
language, durationSeconds, platform, videoId | en, 61.3, instagram, DFIWSVoy1UQ |
Why on-screen text is separated from subtitles
Half the videos we measured carry burned-in subtitles that simply repeat the speech. Dumping every recognised string into one field means the same sentence appears twice and the actual title cards drown in it.
This actor separates them by two signals: how closely a line matches what is being said at that exact moment, and which horizontal band of the frame it lives in. On a labelled video with 54 text tracks the split came out with no errors. onScreenText therefore contains what the author wrote for the viewer; burnedInCaptionCount tells you how many subtitle tracks were removed.
Why the content class matters
Speech recognition models do not stay silent over music — they invent. On a wordless branded clip the model returned "We'll be right back.", and its own confidence score for that invention was 0.00 false positive — the metric that is supposed to catch this says nothing. So the class is decided from word density and how much of the clip speech actually covers.
| Class | What it means | What you get |
|---|---|---|
narrated | The voice carries the script | Transcript + on-screen text |
borrowed_audio | A trending sound or a clip from someone else — not the author's words | On-screen text; the audio is labelled, not passed off as a script |
silent | No speech; the meaning is in the captions | On-screen text only |
empty | Neither speech nor on-screen text | An explicit refusal instead of blank fields |
A looping trending sound is caught by its own repetition: when one line comes back word for word three times or more, it is a sound, not a script.
How much does it cost to extract Reel transcripts?
Pay-per-event, no subscription, and short clips are not billed as if they were long ones.
| Event | Price |
|---|---|
reel-processed — one video: transcript with timestamps, language, hook | $0.002 |
audio-10-seconds — each started 10 seconds of speech recognised | $0.001 |
on-screen-text — one video read frame by frame for burned-in text | $0.06 |
A 15-second TikTok costs $0.004. A 30-second Reel costs $0.005. A 60-second Short costs $0.008. Reading on-screen text is a separate switch and a separate charge, because it is a separate job: the video is downloaded and read frame by frame.
Failed URLs, videos above your duration limit and silent videos are never billed. A row you cannot use is a row you do not pay for.
Bulk export: what 50,000 videos actually cost
This Actor is built for bulk jobs — put hundreds of URLs into one run, or call it from the API on a schedule. Videos are processed three at a time, and there is no fee per run, no fee per page and no proxy charge.
| Job | This Actor | Most-used transcript Actor in this category |
|---|---|---|
| 50,000 TikToks or Reels of 30 seconds | $250 | $305 |
| 50,000 YouTube Shorts (captions, no recognition) | $100 | $305 |
| 50,000 clips of 15 seconds | $200 | $239 |
Checked on the Apify Store on 21 September 2026 against the Reel-transcript Actor with the most monthly users, which charges per dataset item plus per minute of audio, rounded to the minute. Ours is billed in 10-second steps, which is where most of the difference comes from: a 9-second TikTok should not cost the same as a 59-second one.
Two things here that the alternatives do not do at all: three platforms in one run — TikTok, Instagram Reels and YouTube Shorts, one integration instead of three — and on-screen text read and separated from speech, so caption cards and hard subtitles do not get mixed into what the author actually said.
How to extract TikTok, Reels and Shorts transcripts
- Click Try for free.
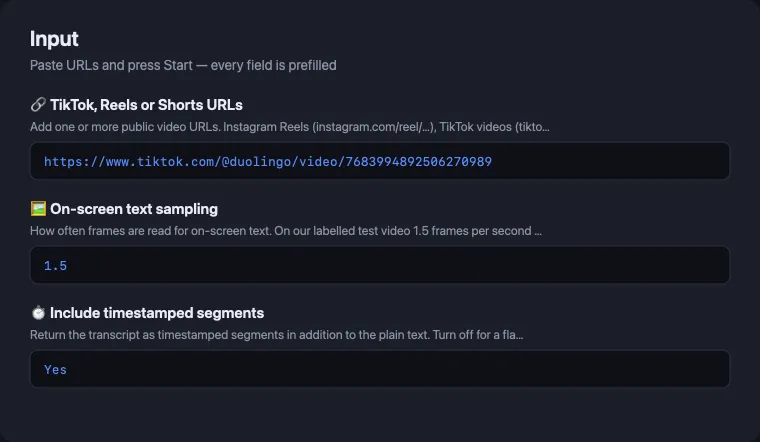
- Paste one or more video URLs into 🔗 Reel, TikTok or Shorts URLs. The field comes prefilled with a working example, so you can just press Start.
- Press Start. Results appear in the dataset, one row per video.
⬇️ Input
Video URLs
Public Instagram Reels, TikTok videos and YouTube Shorts. Private and deleted videos return an error row naming the reason.
On-screen text sampling
How many frames per second are read for on-screen text. On our labelled video, 1.5 frames per second found every caption card; 1 frame per second lost three of six. 1.5 is the default; raise it only for dense motion graphics.
Whole profiles, not just links
Paste a TikTok handle (@duolingo), a TikTok profile link or a YouTube channel into Whole
profiles, set how many of the newest videos you want, and the Actor collects the links itself.
Add a date in Only videos newer than to keep a weekly watch cheap: anything older is skipped
before it is downloaded, so it costs nothing.
Instagram profiles need a login, so they are not supported — paste Reel URLs instead. A profile link dropped into the URL field is understood too; you do not have to pick the right box.
YouTube Shorts cost less than the rest
For YouTube the Actor takes the caption track YouTube has already made, instead of downloading the video and recognising speech. That means Shorts are billed at the video price alone, with no per-audio charge at all, and they come back in seconds.
⬆️ Output
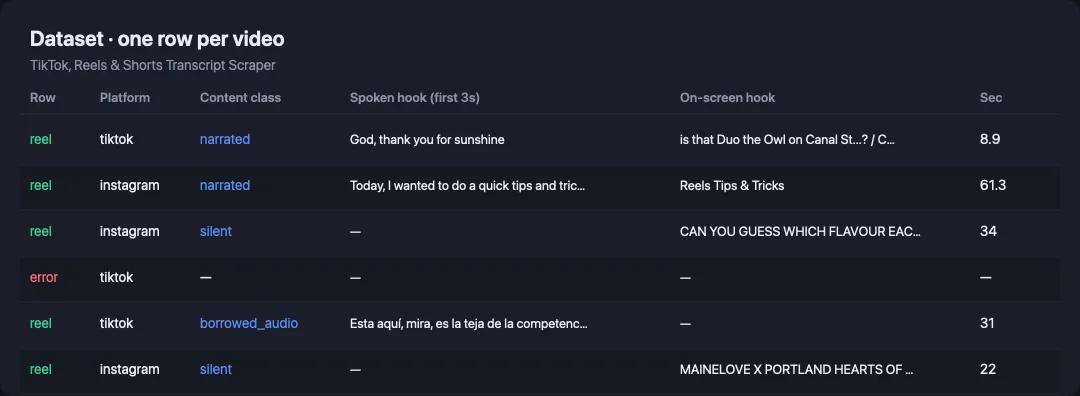
One row per video:
Error rows
A URL that cannot be processed returns a row of its own and is not billed:
Codes: download_failed, timeout, unsupported_url, audio_failed, transcription_failed, ocr_failed, processing_failed.
Use cases for Reel and TikTok transcript data
Competitive research
Feed a list of a competitor's videos and read their hooks side by side. firstThreeSecondsSpeech and firstThreeSecondsOnScreen are cut on the 3.0-second boundary, so the comparison is between what viewers actually received, not between opening sentences of different lengths.
Content repurposing
Turn a back catalogue into text for blog posts, newsletters and captions. onScreenTextJoined gives the written layer separately, which is what carries the message in silent videos.
Feeding an LLM or a RAG index
The output is flat, typed and one row per video. The content class tells your prompt when the transcript is not the author's words — which is what stops a summarising agent from confidently describing someone else's trending sound as this creator's message.
Accessibility and archiving
Transcripts and on-screen text for captioning, search and long-term storage of a feed that platforms may take down.
Integrations
- API: run it from any language with the Apify API, or the Python and JavaScript clients.
- MCP: callable by AI agents through the Apify MCP server, like any other Actor.
- No-code: Make, Zapier, n8n, Google Sheets, Slack through Apify's integrations.
- Webhooks: trigger a downstream run when a batch finishes.
❓ FAQ
Is it legal to scrape Instagram Reels and TikTok?
This Actor reads only public videos, the same ones any visitor can open without logging in, and it does not collect personal profiles. Laws differ by country and by intended use; consult a lawyer before building a commercial product on scraped data.
How much does it cost to transcribe 1,000 reels?
About $5 for 30-second clips and about $4 for 15-second ones — one event per video plus the seconds of speech actually recognised. Failed URLs are free.
Can I use it with the Apify API?
Yes — it is a standard Actor. Start a run, poll it, read the dataset, or use a webhook.
Can I use it through an MCP server?
Yes. It is exposed through Apify's MCP server and its input schema is written so an agent can call it correctly without reading this page.
Does it return one row per video?
Yes. One row per video, plus a separate error row for any URL that failed. Nested arrays (transcript, onScreenText) are provided alongside flat string versions so spreadsheets stay readable.
What languages does it handle?
Speech recognition is multilingual. On-screen text has been verified on Latin and Cyrillic scripts; other scripts are not claimed.
Why is the transcript empty on some videos?
Because the video has no speech. Rather than return an invented sentence, the Actor sets speechDetected to false and tells you the class. This is intended behaviour, not a failure.
Does it need proxies?
No. It runs without residential proxies, which is why extraction is priced where it is.
You might also like
Part of our speech-and-text toolkit — the Store only recommends within a category, so here they are:
| Actor | What it does |
|---|---|
| Whisper Transcriber | Any audio or video file to text, 90+ languages |
| YouTube Transcript Scraper | Transcripts from YouTube videos and playlists |
| SRT Subtitle Generator | Ready-to-upload subtitle files from any video |
| Audio Transcriber | Podcasts, calls and meetings to text |
| OCR Text Extractor | Text out of images and screenshots |
Use this Actor for short vertical video, where the message is split between the voice and the screen; use the others when you already have a file or a long-form video.
Your feedback
Found a video it handles badly? Open an issue on the Actor's Issues tab with the URL — that is the fastest way to get it fixed, and every issue gets a reply.


