
Website Email Extractor — Emails, Phones & Socials
Pricing
from $17.50 / 1,000 website with contacts
Website Email Extractor — Emails, Phones & Socials
[$25/1K websites with contacts] Website email extractor: paste website URLs or domains, get every public e-mail with the page it was found on, plus phones, WhatsApp, Telegram and social profiles. One row per website, empty and blocked sites free, no fee per page.
Pricing
from $17.50 / 1,000 website with contacts
Rating
0.0
(0)
Developer

Matvey
Maintained by CommunityActor stats
0
Bookmarked
4
Total users
0
Monthly active users
9 hours ago
Last modified
Categories
Share
Website Email Extractor pulls e-mail addresses out of any list of websites. Paste website URLs or bare domains, press Start, and get one clean row per website: every public e-mail address with the page it was found on, plus phone numbers, WhatsApp and Telegram links, social profiles, the contact page and the postal address when the site publishes them. No API key, no login, no browser. You pay per website with contacts, never per page. Export to JSON, CSV or Excel, or call it through the API.
This Actor is a focused entry point for the query "website email extractor". It runs the same engine as Email Scraper — Phones, Socials & Contacts from Any Website, at the same price. Use either one — the output is identical.
Tested head-to-head — 9 October 2026
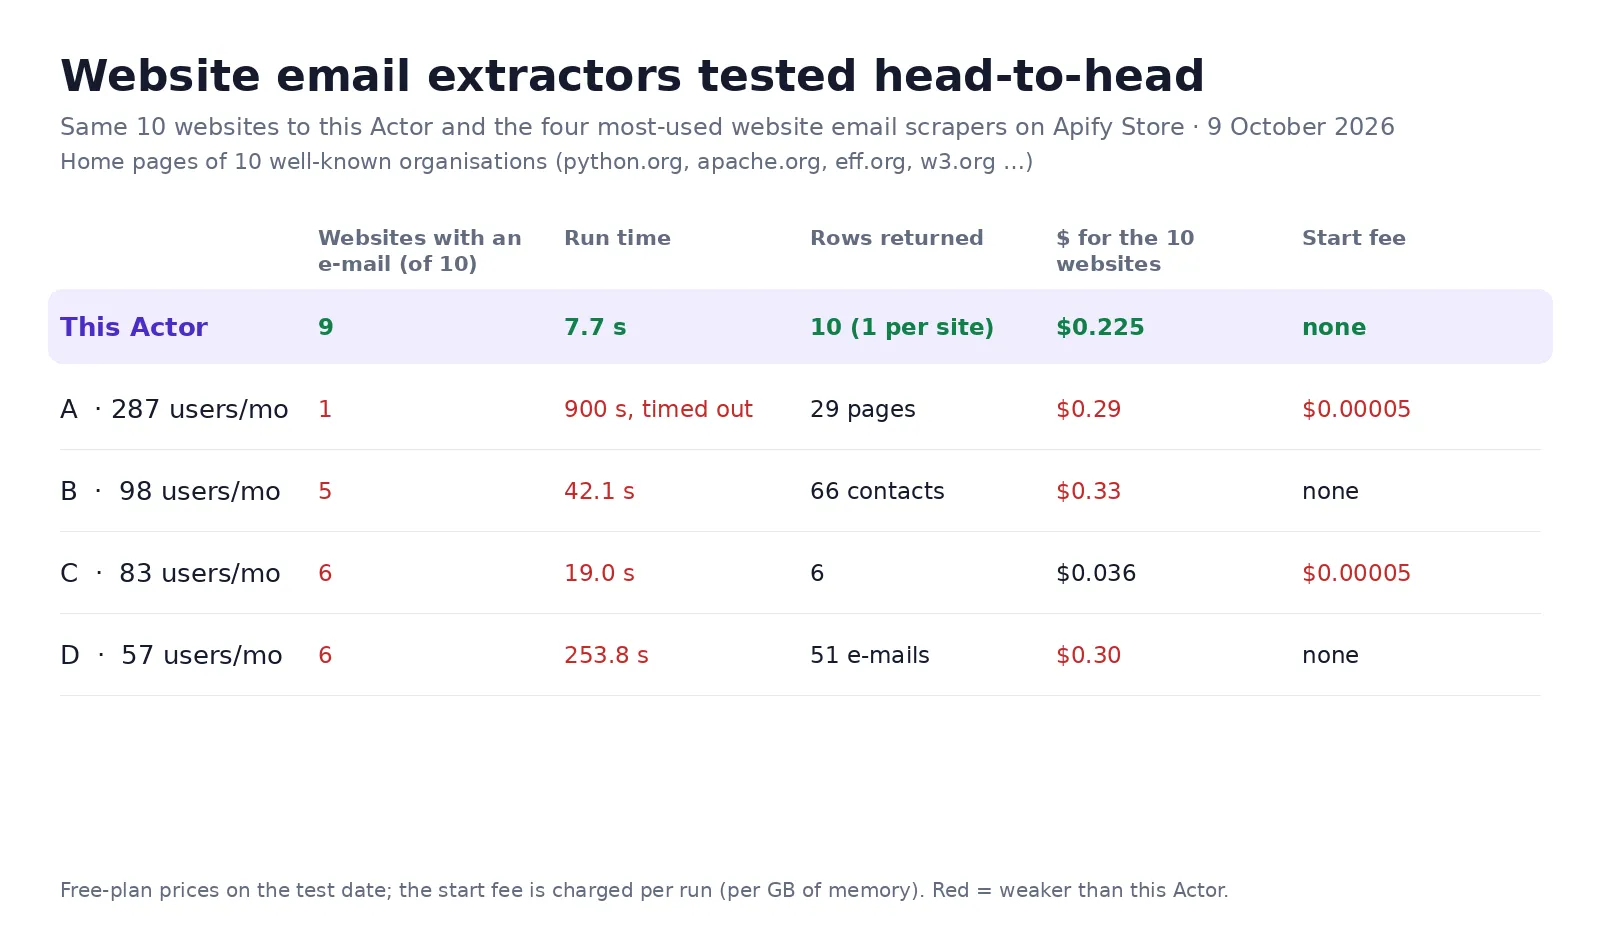
We sent the same 10 websites (python.org, apache.org, eff.org, w3.org and six more) to this Actor and to the four website email scrapers with the most monthly users on Apify Store (A–D, most users first).
- Found: an e-mail on 9 of 10 websites. The others found one on 1, 5, 6 and 6.
- Speed: 7.7 s for all 10; the others took 19 s to 900 s (one timed out).
- Output: one row per website with every address, its type and source page, phones and socials. The others return one row per page, per contact or per e-mail.
- Price: $0.225 for the 9 websites with contacts (the 10th, blocked, was free). Three Actors charged $0.29–$0.33 for the same list; one charged $0.036 and found e-mails on 6 sites.
- Where we were weaker: w3.org sits behind an anti-bot wall; two of the other Actors got its contact address, we returned a free
blockedrow.
What does the website email extractor do?
For every website in your list it reads the home page and the few pages that actually carry contacts (contact, about, team, imprint, legal, privacy, locations — in a dozen languages), and extracts e-mail addresses from:
mailto:links and schema.orgemailmarkup;- Cloudflare-protected addresses (
data-cfemailand/cdn-cgi/l/email-protectionlinks are decoded); - addresses written in the page text, including
name [at] company [dot] comandname (at) company.com.
Addresses found only in prose are kept only when their domain really exists (a DNS check), and placeholders (example@, yourname@), template domains and error-tracker addresses (sentry.io, wixpress.com) are dropped. Each address comes with its type (role for info@/sales@/support@, personal for first.last@, generic otherwise — a heuristic), whether it is on the website's own domain, whether it is a free mailbox (gmail.com …), and the source page.
Phone numbers found on the same pages are validated with libphonenumber and returned in E.164 with country and type. Social links (LinkedIn, Facebook, Instagram, X, YouTube, TikTok, Pinterest, Threads, GitHub), WhatsApp and Telegram come in the same row at no extra cost.
How to extract emails from a list of websites
- Open the Input tab.
- Paste your websites into 🌐 Websites (one per line), or bare domains like
acme.cominto 🌐 Domains. You can also upload a file or link a Google Sheet. - Press Start. Each website takes a few seconds; 10 are scanned in parallel by default.
- Download the results as JSON, CSV or Excel from the Output tab, or read them through the API.
An empty API call works too: with no input, the Actor scans five example websites (apify.com, basecamp.com, ycombinator.com, hubspot.com, zendesk.com) so you can see the output format.
⬇️ Input
| Field | Default | What it does |
|---|---|---|
startUrls | 5 example sites | Websites to scan: a domain, a home page or any page of the site |
domains | empty | Bare domains without https://, merged with the websites above |
maxPagesPerSite | 6 | Home page plus the most contact-like pages, 1–30. The price does not depend on it |
defaultCountry | US | Country used to read phone numbers written without a country code; a site's country domain wins |
onlyOwnDomainEmails | false | Keep only addresses on the website's own domain |
checkEmails | false | Paid add-on: DNS-level deliverability, mail provider, disposable / role / free flags, typo suggestion |
stopEarly | true | Skip remaining pages once an own-domain e-mail and a phone were found |
maxWebsites, concurrency, pageTimeoutSecs | 1000, 10, 15 | Safety cap, parallelism, per-page timeout |
proxyConfiguration, useUnblocker | off | Optional Apify Proxy; Unblocker as a last attempt for the hardest sites |
⬆️ Output
One row per website:
(Shortened: every row also carries whatsapp, telegram, linkedin, x, tiktok, pinterest, threads, github, contactFormUrl, addressRegion, addressText, language, phoneCountryUsed, pagesScanned, fetchedVia and durationMs, null when not found.)
A website that could not be read comes back as an error row, free of charge, so a batch never silently loses a domain:
💰 Pricing
Pay per event, two events:
| Event | Price | When it is charged |
|---|---|---|
| 🌐 Website with contacts | $25 per 1,000 websites ($0.025 each, lower on paid Apify plans) | Once per website where at least one e-mail or phone was found |
| ✅ Add-on: e-mail check | $3 per 1,000 addresses ($0.003 each) | Only when checkEmails is on, once per checked address (up to 20 per website) |
Free: websites with no contacts, unreachable and blocked websites, and every page read. There is no fee per run and no fee per page, and Apify platform usage is included in the price. A list of 1,000 websites costs at most $25, less when some of them publish nothing.
Limits and honest notes
- Public data only. The Actor reads what a website shows to any visitor. It never logs in, never guesses addresses and never uses third-party databases — if a site publishes no e-mail, you get
status: no_contacts, free. - JavaScript-only sites. A home page that is an empty JavaScript shell yields
no_contactswithnote: javascript_rendered_site. No browser is run. - Anti-bot walls. Sites behind strong challenges come back as
status: blocked, free of charge. Ordinary business websites rarely have them. - The e-mail check is domain-level. It tells you whether the domain accepts mail and who hosts it; it does not confirm that a specific mailbox exists.
❓ FAQ
How do I extract emails from a website?
Put the website into 🌐 Websites (or its domain into 🌐 Domains) and press Start. The row lists every address found, the page each one came from, and the best address in bestEmail.
Can I extract emails from thousands of websites at once?
Yes. Put the whole list into one run — up to maxWebsites (1,000 by default, raise it as needed). You pay only for websites where a contact was found.
Does it crawl the whole website?
No. It reads the home page and the pages most likely to carry contacts — 6 by default, up to 30. That finds nearly everything on a normal business site and keeps runs fast. The price is the same whatever this number is.
Why is bestEmail info@ when a personal address was also found?
The general inbox is the address a company publishes as its contact, so it ranks first. Personal addresses are still in emails[] with type: "personal".
What is the difference from Email Scraper — Phones, Socials & Contacts from Any Website?
None in the data: this Actor runs the same engine at the same price. It is a separate entry point for people searching for a website email extractor. The main Actor is lergassy/website-contacts-api.
Is it legal to extract emails from websites?
The Actor collects only what websites publish to every visitor. What you do with it — outreach, storage, profiling — is governed by laws such as GDPR and CAN-SPAM. Check the rules for your use case; personal addresses in particular carry obligations.
Your feedback
Found a website where a published address was missed? Open an Issue on this page with the URL.


