
Careers Page Jobs Scraper (Greenhouse, Lever, Ashby, No Login)
Pricing
from $0.83 / 1,000 jobs
Careers Page Jobs Scraper (Greenhouse, Lever, Ashby, No Login)
Scrape open jobs from Greenhouse, Lever, Ashby, Personio and Teamtailor career pages by typing company names. Get title, department, location, country, remote flag, salary range and apply link. Can return only jobs new since the last run. Companies not found are free. No login. $1.50 per 1,000 jobs.
Pricing
from $0.83 / 1,000 jobs
Rating
0.0
(0)
Developer
locaihost data
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
0
Monthly active users
7 days ago
Last modified
Categories
Features
Share
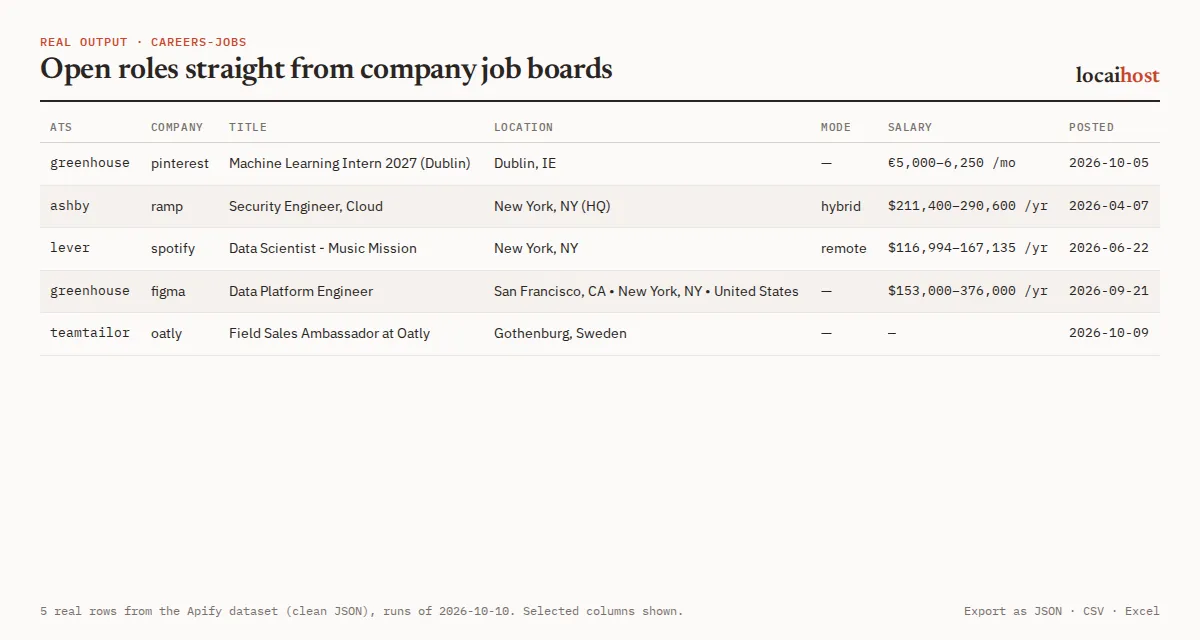
Get every open job at the companies you list, one row per job, read from their Greenhouse, Lever, Ashby, Personio or Teamtailor careers board. Every board comes out in the same format, with salary ranges parsed into numbers. Type company names and we find the job board for you. No login, no API key.
What people use it for:
- Watching target companies to see which roles, teams and cities they open.
- Sales leads. A company opening ten data-engineering roles is a lead for data tools.
- Niche job boards. Postings come from the employers themselves, not from reposts.
- Daily alerts, such as "remote engineering roles with a posted salary at these 50 companies", new jobs only.
- Pay research: published salary ranges by title, location and company.
How do I get started?
Paste this into the JSON tab of the input and click Start:
You get the design roles open at those five companies that day (17 rows on 2026-10-18), usually in about 10 seconds. Remove titleKeywords to get every open job: the same five companies had 689. Each company can be a name (airbnb), a careers-board URL (https://jobs.lever.co/spotify) or ats:name (ashby:ramp).
How long does a run take?
Measured on real runs on 2026-11-14 (Starter prices; the run start adds $0.00005):
| Input | Rows | Seconds | You pay |
|---|---|---|---|
| The prefill: 5 companies, designer roles | 17 | 3 | $0.026 |
| 3 companies, jobs with a salary, 150 max | 150 | 2 | $0.23 |
| 3 companies, engineers, not senior or staff, remote or hybrid, full-time, $150k+ | 53 | 2 | $0.08 |
5 companies, 5 jobs each (maxItemsPerCompany) | 25 | 24 | $0.038 |
| 8 companies, 300 max | 300 | 3 | $0.45 |
What does it return?
| Group | Fields |
|---|---|
| Job | title, department, team, jobId, url (posting page), applyUrl |
| Employer | source (greenhouse, lever, ashby, personio, teamtailor), company (the employer's board name) |
| Location | location, locations (all of them), country (ISO code such as US, GB, DE; null when unsure or several countries) |
| Work type | workplaceType (remote, hybrid, onsite), remote (true = fully remote), employmentType (full-time, part-time, contract, temporary, internship, other), employmentTypeRaw |
| Pay | salaryMin, salaryMax, salaryCurrency, salaryPeriod (year, month or hour) |
| Dates | postedAt, updatedAt (YYYY-MM-DD), scrapedAt |
| Text | description: plain text, up to 20,000 characters, emails and phone numbers removed; null when Include full description is off |
One real row (run on 2026-10-18, description shortened):
Salaries come from the ATS's structured pay fields (Ashby, Lever) or from the posting text ("$120K to $150K per year", "USD 120,000–150,000", "between £40,000 and £50,000"). An unlabelled figure too small to be yearly is reported as monthly, or hourly below 300.
The dataset's Jobs view exports to JSON, CSV, Excel or HTML. Each run also writes a SUMMARY record: per company, the board found, total jobs, how many matched your filters, how many were returned, and any errors or invalid entries.
Which filters can I use?
All filters are optional, and jobs they leave out are free.
| Filter | Keeps |
|---|---|
titleKeywords | Jobs whose title contains any of these words |
excludeKeywords | Drops jobs whose title contains any of these words (Senior, Intern) |
keywords | Jobs whose title or description contains any of these |
locations | Jobs whose location, country or workplace type contains any of these (London, DE, Remote) |
departments | Jobs whose department or team contains any of these |
remoteOnly | Fully remote jobs only |
workplaceTypes | Only remote, hybrid or onsite jobs (any you pick) |
employmentTypes | Only full-time, part-time, contract, temporary, internship or other jobs |
withSalaryOnly | Jobs that publish a pay range |
minSalary | Jobs whose published range reaches this much a year (hourly pay ×2080, monthly ×12) |
salaryCurrency | Jobs paid in this currency (USD, GBP, EUR); pair it with minSalary |
postedWithinDays | Jobs posted in the last N days |
maxItemsPerCompany | At most this many jobs from each company, so one big employer can't fill the run |
A filter on a field the board doesn't give leaves that job out: postedWithinDays skips jobs with no posting date,
employmentTypes skips Greenhouse and Teamtailor jobs (they don't say), and minSalary skips jobs with no published
pay.
What does it cost?
You pay per job returned. There is no charge for Apify platform usage on top.
| Row | Free and Starter | Scale | Business |
|---|---|---|---|
| Job | $1.50 per 1,000 | $1.125 per 1,000 | $0.825 per 1,000 |
Plus $0.00005 per run start. Apify's free $5 monthly credit covers about 3,300 jobs. Free-plan runs stop at 100 jobs each. Any paid Apify plan removes the cap. You can also set your own limit with Max results.
What's free: board lookups, companies that aren't found, invalid or duplicate entries, jobs removed by your filters, jobs already delivered when onlyNew is on, and companies not reached before the run's time limit. A run where every job board is down ends with a message and no job charges. To cap a run's spend, set Maximum cost per run in the run options.
Which job boards does it read, and what are the limits?
- Five job boards only: Greenhouse and Lever (both including EU-hosted boards such as
job-boards.eu.greenhouse.io/acme), Ashby, Personio and Teamtailor (including custom career-site domains, asteamtailor:careers.acme.com). For Workday, Workable and Recruitee, use Workday Jobs Scraper. - Up to 500 companies per run. Duplicate entries are skipped, and entries that can't be a board name (sentences, spaces in a long name, over 100 characters) are listed in
SUMMARY.invalidand never fetched. - A bare name is tried as a board name on each of the five systems in turn. If a company uses a different board name, or another organisation happens to use the same one, paste the careers-board URL instead.
- Only employers who publish a range have a salary.
employmentTypeisnullfor Greenhouse and Teamtailor, which don't say. Lever and Personio give the creation date aspostedAt. - Recruiter and hiring-manager fields are never collected. A description is the employer's own text and can occasionally name a person. Turn off Include full description if you don't need it.
- Data is live: each run reads every board at run time. If a long list would outlast the run's time limit, the run stops cleanly, keeps the jobs found so far and names the companies it didn't reach.
How do I get only new jobs?
Turn on onlyNew, save the input as a task and give it a daily schedule under Schedules in Apify Console. Each run then returns only postings it hasn't delivered before, and skipped jobs cost nothing. The memory belongs to that exact set of companies and filters: change either and it starts fresh. onlyNew is off by default, so a plain run always returns every matching open job.
Can I use it from the API, n8n, Make or an AI agent?
API. Run it and get the rows back in one call:
Apify's API clients for Python and JavaScript work the same way. Synchronous calls wait up to 5 minutes. Use the asynchronous run endpoint for long company lists.
n8n, Make, Zapier, Google Sheets, Slack, webhooks. Apify's built-in integrations send each run's dataset wherever you need it.
AI agents (MCP). Add this Actor to Claude, Cursor or any MCP client with https://mcp.apify.com/?tools=locaihost/careers-jobs, then ask something like "Which engineering roles are Figma, Notion and Ramp hiring for in New York right now, and what salary ranges do they post?"
FAQ
How much does it cost to scrape jobs from careers pages?
$1.50 per 1,000 jobs on the Free and Starter plans, less on Scale and Business. Lookups, unknown companies and filtered-out jobs are free. Apify's free $5 monthly credit covers about 3,300 jobs.
Can I use it through the API or from Python?
Yes. Use the run-sync-get-dataset-items call above, or Apify's Python and JavaScript clients. Every run's data is also available as JSON, CSV or Excel from its dataset.
Can I use it from an AI agent?
Yes. Through the Apify MCP server (https://mcp.apify.com/?tools=locaihost/careers-jobs) any MCP client can call it with a list of companies and read the jobs back.
Is it legal to scrape Greenhouse, Lever and Ashby job boards?
The Actor reads the public job-board feeds these systems publish so employers' openings can be shown elsewhere: the Greenhouse Job Board API, the Lever Postings API, Ashby's public job postings API, Personio's XML feed and Teamtailor's career-site RSS. None needs a login, and the Actor never gets around logins or blocks. It doesn't collect recruiter or hiring-manager details. You are responsible for how you use the results. If you republish postings, check what the employer allows.
Why are some fields empty?
Salary only exists where the employer published one (turn on With salary only to keep just those). employmentType is null when the board doesn't say, and country is null when a posting spans several countries or the location text is unclear.
My company isn't found. What now?
Open the run's SUMMARY record: it lists each company not found. Paste its careers-board URL (for example https://boards.greenhouse.io/<name> or https://jobs.lever.co/<name>) or use ats:name.
More from locaihost data
- Workday Jobs Scraper: the same job format for companies on Workday, Workable and Recruitee.
- H1B Visa Sponsor Lookup: check which of these employers sponsor work visas in the US and UK.
- Company Enrichment by Domain: company name, description, logo, socials and role contact addresses from each site.
- LinkedIn Jobs Scraper: LinkedIn job searches with no login, each job flagged with the employer's visa sponsorship record.
Did it help?
If this saved you time, a quick rating on the Store helps other people find it.
Where do I get help?
Something not working, or another job board you need? Open an issue on the Issues tab: we answer issues within 24 hours.


