
LinkedIn Jobs Scraper — Full Job Details
Pricing
from $0.26 / 1,000 job results
LinkedIn Jobs Scraper — Full Job Details
Search public LinkedIn jobs without LinkedIn login or cookies. Use keywords and location or a public Jobs search URL. Get structured jobs with full descriptions, salaries, and company or recruiter details when public. Use with n8n and Google Sheets workflows.
Pricing
from $0.26 / 1,000 job results
Rating
0.0
(0)
Developer
Meka.im
Maintained by CommunityActor stats
0
Bookmarked
121
Total users
96
Monthly active users
10 hours ago
Last modified
Categories
Features
Share
LinkedIn Jobs Scraper
Scrape public LinkedIn jobs without a LinkedIn login or cookies. Search by keywords and location, or paste a public LinkedIn Jobs search URL. Get structured job listings and full descriptions, plus salary, company, and recruiter details when publicly available.
Use it for hiring monitoring, job-market research, or automated Google Sheets workflows through the public n8n template. Coverage depends on what LinkedIn exposes publicly.
Quick start
Start with a keyword and location:
You can also paste one or more public LinkedIn Jobs search URLs. Direct /jobs/view/... job-detail URLs are not supported as inputs. When urls is provided, its search criteria take priority over structured filters.
n8n template: Google Sheets sync
Run the public workflow: Track LinkedIn jobs daily in Google Sheets. Inspect the example repository: meka-im/linkedin-jobs-scraper-examples.
The template supports a manual run or a daily Schedule. Each run starts one Actor run, waits with bounded polling, checks OUTPUT for delivery coverage, reads one batch from that run's Dataset, compares job IDs with rows already in the Google Sheet, and appends only IDs not already present.
Charging boundary: Sheet comparison happens after Actor billing, so a run can be charged for jobs the workflow later skips as existing rows and is not new-jobs-only.
Pricing
- Delivered results: $0.30 per 1,000 delivered jobs on the Free plan (base rate). Paid-plan tiers receive tiered discounts; check the Actor Pricing tab for the rates applying to your plan.
- Actor start: $0.00005 per allocated memory GB for
apify-actor-start, with at least one start event per run. The default 512 MB run is still billed for at least one start event. - Platform usage: included.
- What counts: each successfully delivered Dataset job is billed as one
apify-default-dataset-itemresult event. Duplicate jobs and failed candidates do not incur a result fee, but the run's start-event charge still applies. - Reruns: independent runs can be charged again for jobs already delivered in an earlier run. Resuming the same run does not redeliver jobs already saved.
- Google Sheets: the n8n template's Sheet-level deduplication happens after Actor delivery and does not prevent or reverse Actor charges.
What you get
- Public LinkedIn job search without a LinkedIn account, login, or cookies.
- Keyword and location search, supported filters, or public Jobs search URLs.
- Full job descriptions in HTML and plain text when the public detail is available.
- Salary, applicant, company, and recruiter information when public.
- Structured Dataset items and an
OUTPUTrun summary for downstream processing. - Recoverable runs: jobs already saved are retained if a temporary failure interrupts a run. Resuming the same run continues without delivering those jobs again.
- An optional n8n workflow that compares job IDs with Google Sheets rows after collection.
Inputs and filters
LinkedIn's current AI search no longer interprets every legacy URL filter consistently. When legacy URL conversion is enabled, the Actor handles filters as follows:
| Behavior | Filters |
|---|---|
| Preserved as URL filters | Date posted, company, Easy Apply, and under 10 applicants |
| Preserved as search inputs | Keywords, location, Geo ID, and distance |
| Converted into search terms | Experience level, job type, and workplace |
| Not reliably convertible | Industry, job function, standardized title, and other ID-only filters |
For filters that are not reliably convertible, describe the requirement in keywords instead. Do not rely on legacy remote or industry URL filters for exact filtering.
Use splitByLocation with splitCountry for large country-wide searches. Results from the split searches are merged and deduplicated within the run.
Dataset output
Each Dataset item represents one job. The published schema contains 30 fields; the representative item below lists all of them in order, with shortened descriptions and identities.
- Job ID, title, URL, location, posting date, and employment type
- Description in HTML and plain text
- Salary and applicant information when available
- Seniority, function, and industry
- Recruiter information when publicly available
- Company name, LinkedIn URL, logo, website, description, employee count, address, and slogan when available
- Source URL and LinkedIn tracking metadata
Representative Dataset item (descriptions and identities shortened):
applyUrl is part of the Dataset schema but is currently returned as an empty string; use link to open the job.
Run summary, partial results, and recovery
The OUTPUT record in the default key-value store provides a concise end-of-run summary:
statusispartialwhen valid jobs were delivered alongside a technical failure.completedisfalse, and the failed search-page position is retained so unfinished work can resume without skipping it.- Trusted target
404responses are reported asexpectedSkips. - When safe, the Actor may continue with new jobs to fill the requested count, but the run remains
partialand the failed detail is not counted as a success. - A run with only technical failures writes this summary and then fails.
- If the user time limit is reached after at least one job has been saved, the run exits successfully as
partialwithstopReason: "time_limit"and a short user message. Real search and detail failures remain visible in their existing counts; the time limit does not add an artificial technical failure. Unfinished pages remain resumable. A deadline with no saved jobs still fails. - Resuming the same run continues from saved results without delivering jobs already saved.
Coverage and limits
- Results reflect the public LinkedIn job data available when the run executes; search rankings, applicant counts, and optional recruiter or company fields can change or be absent.
limitPerSourceis a request ceiling, not a minimum or a coverage promise; available public results may be fewer than requested.- Temporary request failures may be retried a limited number of times. If company details cannot be retrieved, the valid job is still delivered with optional fields blank, and the run summary marks company details as incomplete.
- Partial results and real search or detail failures remain visible in the
OUTPUTsummary rather than being hidden as success.
Use the data responsibly and comply with applicable laws and platform terms.
Location splitting uses city data derived from SimpleMaps and distributed under CC BY 4.0.
API integration
Built and maintained by Meka. Run it from the Apify Console, API, schedules, or downstream integrations.
Related LinkedIn data tools
- LinkedIn Company Scraper for public company profiles and website domains.
- LinkedIn Profile Candidate Finder for ranked public profile candidates with evidence.
- LinkedIn Public Post Scraper for fresh public posts, media, and engagement.
FAQ
Can I scrape LinkedIn jobs without an account?
Yes. The Actor uses supported public LinkedIn job data and does not require your LinkedIn login or cookies.
Can I search by keyword and location?
Yes. Use structured inputs such as keywords, location, datePosted, and the supported filters, or paste public LinkedIn Jobs search URLs.
Can I paste a direct LinkedIn job URL?
No. Inputs accept public LinkedIn Jobs search URLs, not direct /jobs/view/... job-detail URLs.
Does each result include the full job description?
When the public job detail is available, the Dataset includes both HTML and plain-text descriptions plus recruiter and company enrichment when requested.
Will a scheduled run return only jobs not seen before?
No. Independent runs may deliver jobs seen earlier; the n8n template skips existing Sheet rows only after Actor delivery. See Pricing.
Is applyUrl an external application link?
Not currently. applyUrl is present in the Dataset schema but is returned as an empty string. Use link to open the LinkedIn job.
Historical validation
The following measurements and compatibility checks are retained as historical evidence. They are not current performance, coverage, price, or equivalence guarantees.
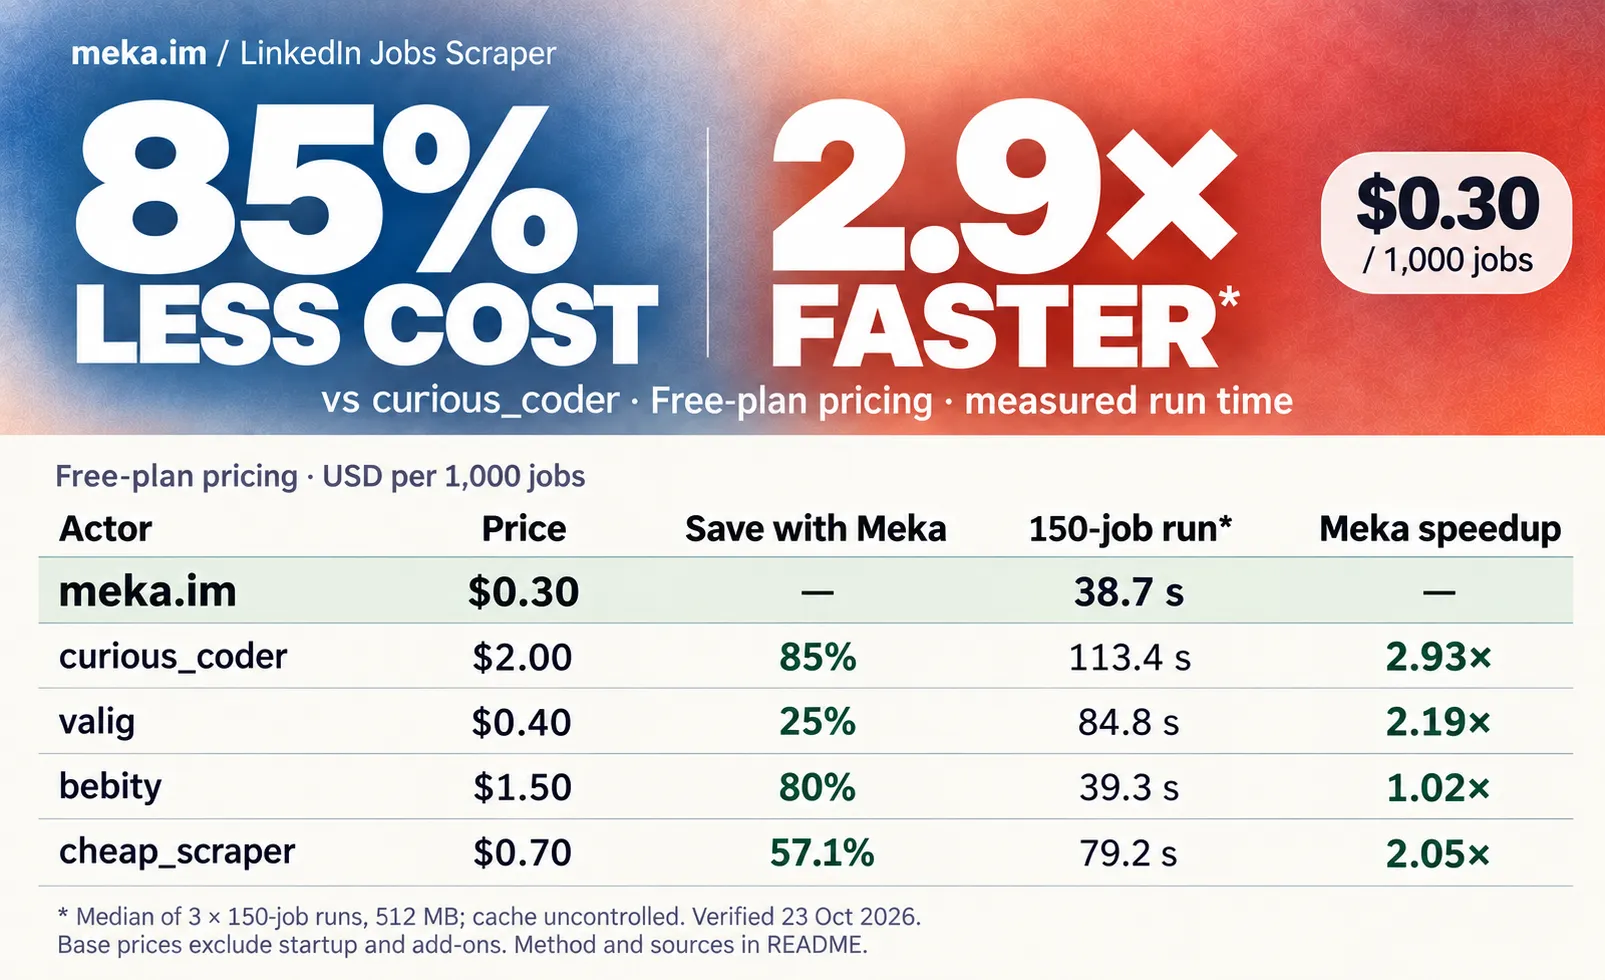
Historical benchmark: 2026-10-23
Measured on 2026-10-23 with company enrichment disabled (scrapeCompany: false): 150 jobs per run, three runs per Actor, 512 MB, and cache uncontrolled. Median runtime was 38.665 s for this Actor and 113.415 s for curious_coder. Free-plan base prices were $0.30 vs $2.00 per 1,000 jobs, an 85% lower base price and 2.93x measured speed in this comparison. Runtime varies by query and is not a current guarantee.
Historical official pricing references: curious_coder, valig, bebity, cheap_scraper.
Historical compatibility: September 16, 2026
Validated on September 16, 2026 against the leading Actor's build 1.7.14. In the 100-result comparison:
- Both runs delivered 100 unique jobs.
- Dataset field union matched 30 of 30 fields.
- The 99 common jobs had zero field-type mismatches.
- No reference-populated field was systematically missing.
- 2,170 of 2,238 stable field values matched exactly (96.96%).
Live rankings, applicant counts, tracking IDs, and some inferred fields can naturally differ between requests. This comparison is historical and is not a current parity guarantee.
Tool preview
Tool preview: Explore LinkedIn Jobs for recorded examples and the current preview status. Browse the tools directory for other sources.


