

Website Contact Details Extractor — Contact Scraper
Pricing
from $40.00 / 1,000 contact records
Website Contact Details Extractor — Contact Scraper
Website contact details extractor and website contact scraper: paste a list of website URLs to extract emails and phones from websites, plus social profiles — homepage and auto-discovered contact, about and team pages. One clean row per contact found. No API key. Pay per record.
Pricing
from $40.00 / 1,000 contact records
Rating
0.0
(0)
Developer
NexGenData
Maintained by CommunityActor stats
0
Bookmarked
157
Total users
5
Monthly active users
a day ago
Last modified
Categories
Share
Website Contact Details Extractor — Emails & Phones from URLs
Website contact details extractor: a list of sites in, every email, phone and social profile found on them out.
A website contact scraper: give it a list of URLs to extract emails and phones from websites (and social profiles), one row per contact found.
Extract emails, phones and social links from a list of website URLs. Feed it domains, get back one row per contact found (one row per email, phone number or social profile) — homepage plus auto-discovered contact/about/team pages (default 3 pages per site).
Output is a prospect list for your sales team, assembled from public web and business sources. Use it in line with applicable outreach and privacy law.
📊 Sample Output
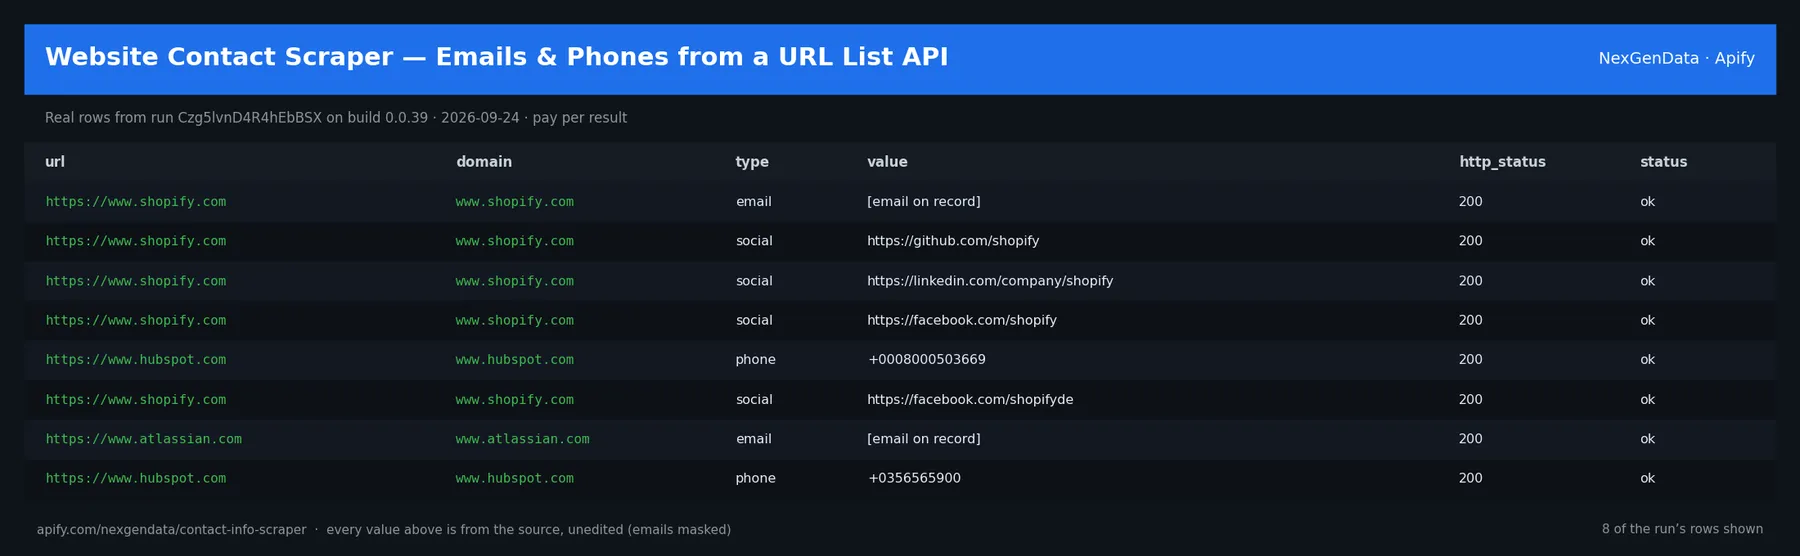
url | domain | type | value | http_status | status |
|---|---|---|---|---|---|
| https://www.shopify.com | www.shopify.com | [email on record] | 200 | ok | |
| https://www.shopify.com | www.shopify.com | social | https://github.com/shopify | 200 | ok |
| https://www.shopify.com | www.shopify.com | social | https://linkedin.com/company/shopify | 200 | ok |
| https://www.shopify.com | www.shopify.com | social | https://facebook.com/shopify | 200 | ok |
| https://www.hubspot.com | www.hubspot.com | phone | +0008000503669 | 200 | ok |
| https://www.shopify.com | www.shopify.com | social | https://facebook.com/shopifyde | 200 | ok |
Real rows from run Czg5lvnD4R4hEbBSX on build 0.0.39 (2026-09-24), unedited apart from masked emails/phones and shortened long text; fields the source does not publish are empty.
⚙️ Sample inputs
This is the Store example input — the same input Apify's automated check runs — so it is proven to return rows on the current build. Paste it into the input form, or send it through the API, CLI or a schedule:
🔧 Input reference
| Field | Type | Default | What it does |
|---|---|---|---|
urls | ['array', 'string'] | ["https://www.shopify.com", "https://www.hubspot.com", "htt… | Website URLs to scrape for contact info. Accepts a list of URLs OR a single URL string OR a comma/newline-separated list. Also accepts these alternative field names: startUrls, do… |
crawl_contact_pages | boolean | true | Also crawl /contact, /about, /team and similar pages for additional contact data. |
max_pages_per_site | integer | 3 | Maximum number of pages to visit per site (homepage + discovered contact pages). Defaults to 3 (homepage + contact + about — where contact details almost always live), which keeps… |
request_timeout_secs | integer | 20 | Per-request HTTP timeout in seconds. |
proxyConfiguration | object | {"useApifyProxy": true} | Apify proxy configuration. Residential is recommended for higher success rates. |
startUrls | ['array', 'string'] | Alternative name for urls. Accepts a list of URLs OR a single URL string OR comma/newline-separated. | |
domains | ['array', 'string'] | Alternative name for urls. Accepts a list of URLs OR a single URL string OR comma/newline-separated. | |
websites | ['array', 'string'] | Alternative name for urls. Accepts a list of URLs OR a single URL string OR comma/newline-separated. | |
targetUrls | ['array', 'string'] | Alternative name for urls. Accepts a list of URLs OR a single URL string OR comma/newline-separated. | |
siteUrls | ['array', 'string'] | Alternative name for urls. Accepts a list of URLs OR a single URL string OR comma/newline-separated. | |
url | string | Alternative — a single URL when you only need one. Comma-separated values are auto-split. | |
notionConnector | string | Optional. Connect your Notion workspace and the scraped contacts are also written as a Notion page in the same run — the Actor never sees your Notion credentials. Authorize a Noti… | |
notionParentId | string | Optional. The Notion page ID to create the page under. If blank, Notion creates a private page in your workspace. | |
supabaseConnector | string | Optional. Connect your own Supabase project and the results are also inserted into a table in the same run — the Actor never sees your Supabase credentials. Authorize a write-scop… | |
supabaseTable | string | "nexgendata_leads" | Target table in the public schema (created if missing, with id, a jsonb data column, and a scraped_at timestamp). Default: nexgendata_leads. |
supabaseProjectId | string | Your Supabase project reference (e.g. abcdefghijklmnop). Required unless your connector URL is already project-scoped. Find it in your project URL: supabase.com/dashboard/project/… | |
deliveryDedup | boolean | true | When on (default), records already delivered in a previous run are not delivered again to the same destination — so scheduled runs only push new items. Turn off to deliver every r… |
🧾 JSON sample record
One real record from run Czg5lvnD4R4hEbBSX (emails/phones masked, long text shortened):
💰 Pricing
| Event | Price (USD) | When it is charged |
|---|---|---|
Actor Start (apify-actor-start) | $0.00005 | Charged when the Actor starts running. Number of events charged depends on Actor memory (one event per GB, minimum one event). |
Contact record (apify-default-dataset-item) | $0.04 | Single result in the default dataset. |
Pay-per-event: you pay only for what the run delivers. A run that delivers nothing bills no result events (only the actor-start event, when the actor defines one). Example: a run that delivers 100 results costs 100 × $0.04 = $4.00 plus the start fee.
📊 What you get
Clean JSON, one row per contact (email, phone, or social profile) — a contact-rich site can produce 20+ rows. Every row has 6 core fields; social rows add platform and social_url, email rows add email, phone rows add phone:
url— site URL that was scrapeddomain— site domaintype—email|phone|socialvalue— the contact (email address, E.164-style phone such as+14155550142, or canonical profile URL)http_status— HTTP status of the site homepagestatus—okplatform— social rows only:linkedin,twitter,facebook,instagram,youtube,tiktok,githubsocial_url/email/phone— the value again under a type-specific key
Example row: {"url": "https://acme.io", "domain": "acme.io", "type": "email", "value": "sales@acme.io", "email": "sales@acme.io", "http_status": 200, "status": "ok"}
Pricing: $0.04 per delivered contact row (Pay-Per-Event) plus $0.00005 per run start — about 25 contact rows per $1. Pages crawled are not billed. Sites with no contacts, blocked/unreachable sites, and sites not processed within the run's time budget push no rows and cost nothing; the run status message reports each of these counts. Large lists are processed until the time budget is reached — the default 3 pages per site keeps a first run small.
🤖 Use with AI agents
Point Claude, the OpenAI Agents SDK, an n8n flow or any MCP-aware client at it and run prospecting on demand.
Agentic payments (x402): Supports agentic payment via x402 — agents can call this actor with USDC, no API key required.
Run it on a schedule
Contact details on company websites change slowly, so most lists only need a monthly refresh; weekly makes sense if you keep adding new sites to the list. Between runs, a site may add or remove an email, phone number or social profile, and new sites you add to urls produce new rows. Each run re-reads the sites and returns every contact it finds. If you deliver to Notion or Supabase, deliveryDedup (on by default) skips records already delivered to that destination in an earlier run, so a scheduled run only pushes new contacts there. Send each run's results onward with a webhook, Google Sheets, Zapier, Make or the Apify API.
Video guides from Apify: Schedule your Actor · Integrations
FAQ
Why use this instead of checking each company's website yourself?
Each website shows its contact details for free, but finding them means opening the homepage, then the contact, about and team pages, site by site. This actor does that for a whole list of URLs and returns one clean row per email, phone number or social profile found, with the site, domain and contact type. It needs no API key, you pay per contact row (not per page crawled), and it can write results straight to Notion or Supabase.
What does a typical run cost?
You pay per result, not for run time: $0.04 for each row in the results, plus $0.00005 per run start (charged per GB of run memory, minimum one). A run that returns 84 contact rows costs about $3.36. Live prices are always shown in the Pricing tab.
How do I extract emails and phone numbers from a list of websites?
Paste the sites into urls as a list, or as a comma- or newline-separated string. With crawl_contact_pages on (the default), the actor reads the homepage plus discovered contact, about and team pages, up to max_pages_per_site (default 3). Each email, phone and social profile comes back as its own row, so a contact-rich site can produce 20 or more rows.
Which social profiles does it find?
LinkedIn, X (Twitter), Facebook, Instagram, YouTube, TikTok and GitHub. Social rows carry a platform field and the canonical profile URL.
Does it check whether the emails are valid?
No. It returns emails and phone numbers as they appear on the site. To check deliverability or line type before outreach, run the results through an email verification or phone validation actor.
What happens with sites that are blocked or have no contacts?
They produce no rows and cost nothing. The run's status message reports how many sites had no contacts, were blocked or unreachable, or were not reached within the run's time budget. Large lists are processed until the time budget runs out.
Related actors
- Email Verification API — Bulk Syntax, MX & Disposable Checks — check the emails you found before you send.
- Phone Number Validation API — Format, Carrier & Line Type — validate the phone column.
- Company Email Finder — B2B Contact Discovery API — find business emails when a site does not publish them.
- B2B Contact Enricher — Emails, Roles & Firmographics API — add roles and firmographics to your contacts.
- B2B Lead List Cleaner — Dedupe, Normalize & MX-Verify API — dedupe and normalize the combined list.
Related actors from NexGenData
If this actor is useful, these related ones from the same publisher may cover your next step:
- Google Maps Business Emails — Google Maps Email Scraper & Leads — Local businesses from Google Maps with phone, website, rating and verified emails.
- Local Business Leads — Google Maps + Verified Emails API — Local businesses by industry and city with a verified business email.
- Yellow Pages Scraper — Yellow Pages API Alternative for Leads — Businesses from Yellow Pages by type and city: phone, address, website, rating.
- Phone Number Validation API — Format, Carrier & Line Type — Phone number check: format, line type, carrier and country.
- Website Tech & Contact Audit — Tech Stack + Emails API — One-call website audit: tech stack plus emails, phones and social profiles.
- Person Enrichment API — Name & Company to Public Profile — A person's public profile from their company's own site, from name + company.


