

Email Extractor — Extract Emails from Website Lists
Pricing
from $20.00 / 1,000 email extracteds
Email Extractor — Extract Emails from Website Lists
Email extractor for website lists: extract emails from website pages plus phone numbers and social profiles; crawls contact/about pages automatically. Hunter.io alternative for lead generation. Pay per record.
Pricing
from $20.00 / 1,000 email extracteds
Rating
0.0
(0)
Developer
NexGenData
Maintained by CommunityActor stats
0
Bookmarked
42
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
🔍 Email Extractor — Extract Emails from Website Lists
An email extractor for website lists: extract emails from website pages (plus phones and social profiles), contact and about pages crawled automatically.
Optional delivery: Send results straight to your own Notion database or Supabase table in the same run, via Apify's native MCP connectors — the Actor never sees your credentials. One-click connect: Notion or Supabase. Leave blank to get the dataset as usual.
Give it a list of websites. It crawls the homepage plus the contact / about / team pages and returns every publicly published email address, phone number and social profile it finds there — deduped and lowercased. Built for lead-gen, outbound sales and CRM enrichment as a pay-per-result alternative to seat-priced tools like Hunter.io, Snov.io, VoilaNorbert and FindThatLead.
📊 Sample Output
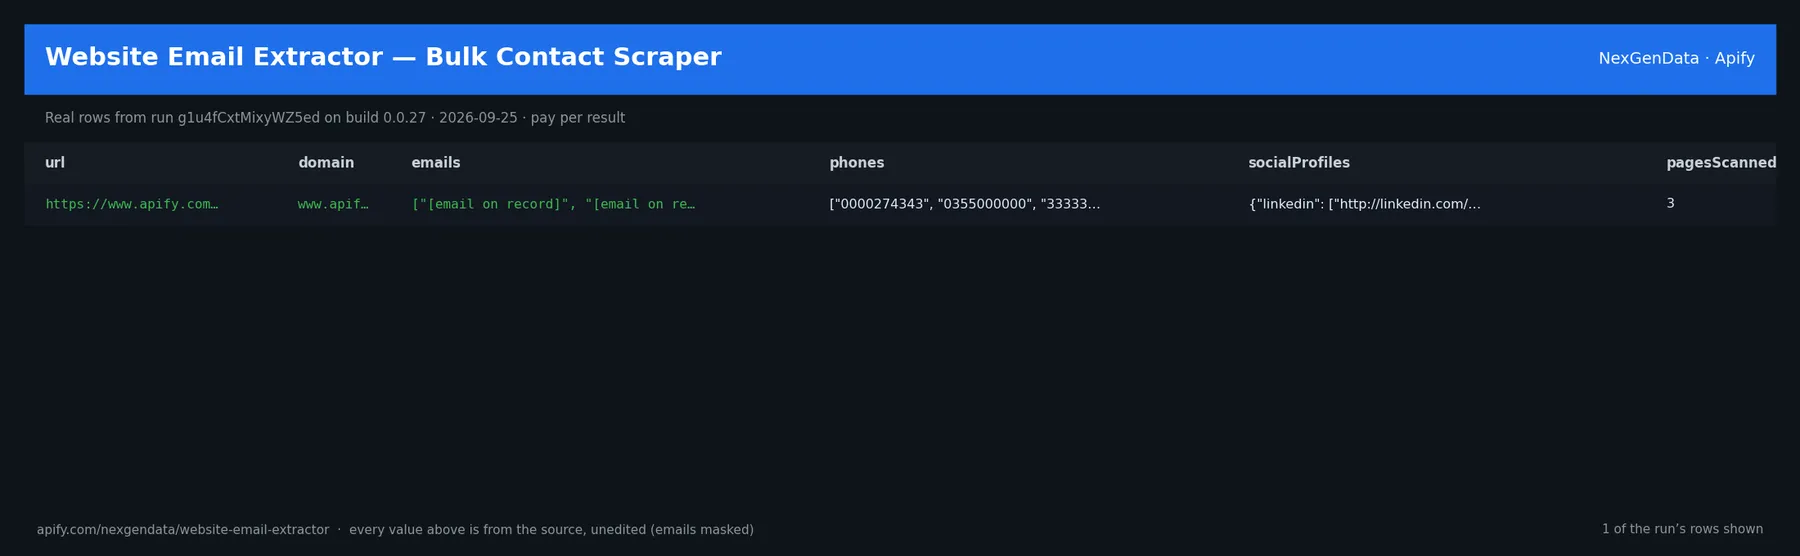
url | domain | emails | phones | socialProfiles | pagesScanned |
|---|---|---|---|---|---|
| https://www.apify.com/contact | www.apify.com | ['[email on record]', '[email on record]', '[email on record]'] | ['[phone on record]', '[phone on record]', '[phone on record]', '[pho… | {'linkedin': ['http://linkedin.com/company/apify', 'https://www.linke%E2%80%A6 | 3 |
Real rows from run g1u4fCxtMixyWZ5ed on build 0.0.27 (2026-09-25), unedited apart from masked emails/phones and shortened long text; fields the source does not publish are empty.
🧾 JSON sample record
One real record from run g1u4fCxtMixyWZ5ed (emails/phones masked, long text shortened):
🔗 Related Actors
More from the NexGenData Leads, contacts & enrichment family:
- SSL Certificate Checker — Bulk Expiry & Chain Monitor
- TikTok Creator Email Finder — Influencer Contact API
- Tech Stack Detector — Wappalyzer & BuiltWith API Alternative
- Yellow Pages Scraper — Local Business Leads API
- YouTube Creator Contact Finder — Channel Email & Links API
31 more in this family on the NexGenData Store page.
What this Actor does — and what it does not
- ✅ It extracts contact details that a site publishes in its own HTML.
- ❌ It does not verify the addresses it finds. There is no SMTP probe, no mailbox check and no deliverability scoring in this Actor. Nothing it returns is "verified".
- ❌ It does not guess or pattern-generate addresses (no
firstname.lastname@construction). Every address in the output was literally present on a page it fetched.
If you need a deliverability signal, run the returned addresses through a validator afterwards — for example email-verification-tool, which does syntax + DNS MX-record checks (also not an SMTP probe).
Pricing — the live, current prices
| Event | Price |
|---|---|
| Actor start | $0.005 (per GB of run memory, minimum one) |
| Result row in the dataset | $0.02 |
One website that yields contacts = one row = $0.02. All of that site's emails, phones and socials arrive inside that single row, so a site with twelve addresses still costs $0.02.
Worked examples at the live price:
- 100 websites that all yield contacts = $0.005 + (100 × $0.02) = $2.005
- a daily 50-domain sweep = $0.005 + (50 × $0.02) = $1.005/day
You are not charged for:
- a website that answered but publishes no email, phone or social profile — it produces no row
- a website that was blocked, timed out or 404'd — it produces no row
- retries, proxy rotation and failed sub-requests — those are absorbed by the platform
No monthly minimum, no seats.
What you get per website
One row per website that yielded at least one contact:
| Field | Meaning |
|---|---|
url | the site as you supplied it (normalised to https:// if you omitted the scheme) |
domain | host of that URL |
emails | sorted, deduped, lowercased list of every email address found |
emailCount | length of emails |
phones | sorted list of phone numbers found |
socialProfiles | object keyed by platform (linkedin, twitter, facebook, instagram, youtube, github); empty platforms are omitted |
contactPageUrl | the contact page the crawler identified, if it found one |
pagesScanned | how many pages were successfully fetched for this site |
Input
| Parameter | Type | Default | Description |
|---|---|---|---|
urls | array / string | — | Websites to crawl. Aliases accepted: startUrls, domains, websites, url, domain. Comma- or newline-separated strings work too. |
maxPagesPerSite | integer | 3 | Pages to fetch per site (1–50). Raise it for deeper crawls. |
extractEmails | boolean | true | Collect email addresses. |
extractPhones | boolean | true | Collect phone numbers. |
extractSocials | boolean | true | Collect social profile links. |
notionConnector / notionParentId | string | — | Optional MCP delivery into your Notion workspace. |
supabaseConnector / supabaseTable / supabaseProjectId | string | — | Optional MCP delivery into your Supabase project. |
deliveryDedup | boolean | true | Skip records already delivered in a previous run. |
Quick start (Python)
Example row (real shape, from a live run against https://www.apify.com/contact):
How the run ends
The Actor always tells you what happened, in plain English, in the run's status message:
- Rows returned — "Returned N website row(s) carrying M email address(es)…", plus a count of sites that had no contacts and of sites that could not be reached. Only the delivered rows were charged.
- Nothing found — the run succeeds with 0 rows and says the sites were crawled but publish no public contacts. Nothing was charged.
- Every site unreachable — the run fails with a message saying every page request was blocked, refused or timed out. Nothing was charged. Re-run with the Apify proxy enabled if the target blocks datacentre IPs.
- No input — the run succeeds with 0 rows and names the field to supply (
urls). Nothing was charged. - Time limit — the crawl stops cleanly and the message says it stopped early at the run time limit; only rows already delivered were charged.
Use cases
- Outbound sales — turn a domain list into a contact list in one run
- Cold-email agencies — build per-client lead lists without a per-seat subscription
- Lead enrichment — fill missing contact fields during a CRM cleanup
- Recruiting — surface HR and hiring contacts from company career pages
- PR / press outreach — collect press@ and media@ contacts across a list of news sites
FAQ
Q: Are the emails verified? A: No. This Actor extracts what a site publishes; it performs no SMTP probe and no mailbox check. Validate separately if you need a deliverability signal.
Q: How deep does it crawl?
A: maxPagesPerSite pages per site (default 3, max 50), prioritising contact / about / team links plus the standard /contact, /about-us, /team, /impressum paths.
Q: Why did a site return no row?
A: Either it published no contact details, or it could not be fetched. The status message and the run's OUTPUT record break the two apart.
Q: GDPR / CCPA / CAN-SPAM? A: Addresses on a public page are publicly published. You are the data controller for downstream outreach — follow your jurisdiction's prospecting and opt-out rules.
Related NexGenData Actors
| Use case | Actor |
|---|---|
| Contact info scraper (emails + phones + socials) | contact-info-scraper |
| Find emails on a domain | company-email-finder |
| Email syntax + MX checking | email-verification-tool |
| B2B leads finder (multi-source) | b2b-leads-finder |
| Company enrichment from domain | company-enrichment-tool |
| Lead-list enricher (CSV in → CSV out) | lead-list-enricher |
Integration surface
Apify console, Apify API (REST + webhooks), Python / JS SDKs, Zapier, Make.com, n8n, MCP, and built-in schedules.
Support
NexGenData ships updates regularly. Bug reports via the Apify console issues tab get a response within 24 hours.
Home: thenextgennexus.com Full catalog: apify.com/nexgendata


