
Image OCR Text Extractor — Images & Scanned PDFs
Pricing
from $33.50 / 1,000 ocr pages
Image OCR Text Extractor — Images & Scanned PDFs
OCR images and scanned PDFs by link with Tesseract: JPEG, PNG, WebP, TIFF and PDF pages, 24 languages. Text line by line with word count, confidence and optional word positions. Pages with no text are not billed. Part of NexGen Signal — data tools and official-source data products
Pricing
from $33.50 / 1,000 ocr pages
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a month ago
Last modified
Categories
Features
Share
🔎 Image OCR Text Extractor — Images & Scanned PDFs
Give image links (JPEG, PNG, GIF, WebP, BMP, TIFF) or PDF links, including scanned PDFs, and get the text in each image or PDF page as one row: text line by line with paragraphs, word and line counts, average confidence, and optionally every word with its confidence and position.
OCR runs inside the actor with Tesseract 5 and 24 language packs (English, German, French, Spanish, Italian, Portuguese, Dutch, Polish, Swedish, Danish, Norwegian, Finnish, Czech, Turkish, Russian, Ukrainian, Arabic, Hindi, Chinese simplified and traditional, Japanese, Korean, Vietnamese, Indonesian); pick up to five per run. Images are converted to grayscale and small images are enlarged before reading; PDF pages are rendered at 300 DPI by default.
The unit of output is one image or PDF page delivered. Pages where no text is found are not billed.
Who buys this and for what job
- Back-office and finance teams reading scanned letters, forms and receipts they hold the rights to.
- Archivists and researchers making historical scans searchable.
- AI builders adding scanned documents to a knowledge base.
- Developers needing an OCR step without running Tesseract themselves.
Buyers usually search for this as "OCR API", "image to text" or "scanned PDF to text".
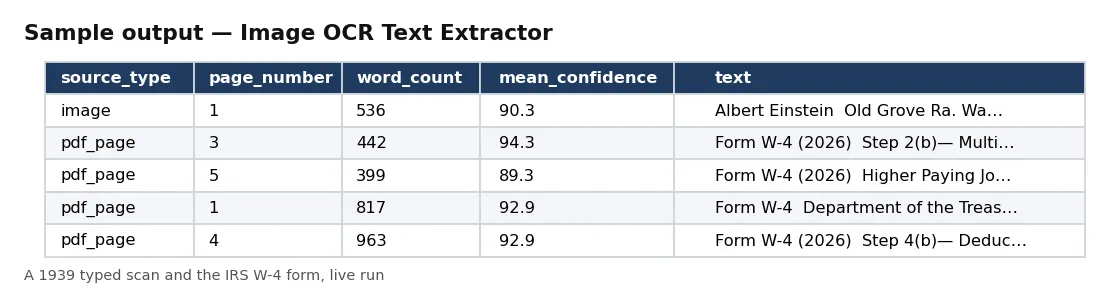
📊 Sample Output
| source_type | page_number | word_count | mean_confidence | text |
|---|---|---|---|---|
| image | 1 | 536 | 90.3 | Albert Einstein Old Grove Ra. Wassau Point Peconic, Long Is … |
| pdf_page | 3 | 442 | 94.3 | Form W-4 (2026) Step 2(b)— Multiple Jobs Worksheet (Keep fo … |
| pdf_page | 5 | 399 | 89.3 | Form W-4 (2026) Higher Paying Job Annual Taxable Wage & Sal … |
| pdf_page | 1 | 817 | 92.9 | Form W-4 Department of the Treasury Internal Revenue Servic … |
| pdf_page | 4 | 963 | 92.9 | Form W-4 (2026) Step 4(b)— Deductions Worksheet (Keep for y … |
Rows from live run ntbOdvzs0bJP180ct on Apify (the Store example: the 1939 Einstein–Szilard letter (a typed scan) and the five pages of the IRS W-4 form). Notice the confidence: about 90 on the 1939 typewritten scan and 89 to 96 on the printed form pages.
✅ What you get
Every field of each record:
record_id— file hash plus page number.url,final_url,found_on_page— the link, where it was served from, and the page it was found on (with followImageLinks).source_type,page_number,page_count— image or pdf_page, and its position.width,height— pixels (PDF pages as rendered).languages— OCR languages used.text,text_chars,word_count,line_count— the text and its size.mean_confidence— average word confidence, 0 to 100.words— each word with confidence and bounding box (with includeWords).sha256,processed_at— file hash and when it was read (UTC).
⚙️ Sample inputs
A scanned letter and a PDF (the Store example)
One image and five PDF pages.
Word positions in two languages
Each word with its box, for highlighting or redaction tools.
Labels and signs
Sparse mode finds scattered text such as labels and screenshots.
Input fields:
| Field | Meaning |
|---|---|
imageUrls | image or PDF links, or pages with followImageLinks (up to 5,000). |
languages | 1 to 5 language codes (default eng). |
pageSegmentation | auto, single_block, single_column, sparse, single_line. |
includeWords | add word boxes and confidences (default false). |
followImageLinks | read images and PDFs on pages you give (default false). |
maxPdfPages | pages read per PDF (default 50). |
pdfDpi | PDF render resolution, 72 to 400 (default 300). |
maxFileMb | skip files bigger than this (default 50). |
maxPages | stop after this many delivered pages (default 1,000). Each delivered page is billed. |
🧾 JSON sample record
🔧 How it works
Files are downloaded 6 at a time; pages are read in parallel up to the run's CPU count. Tesseract's word table (TSV) is turned into lines and paragraphs; the average of the word confidences is reported.
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
Delivery is pushed first and charged after. The run receipt (RUN_RECEIPT) lists every link with its outcome and pages delivered, page outcomes with counts (delivered, no text found, unreadable), the robots.txt result per host, and the delivered and charged counts.
💰 Pricing example
Per page delivered, no start fee, no monthly charge:
| Apify plan | Price per page |
|---|---|
| Free | $0.05 |
| Bronze | $0.045 |
| Silver | $0.04 |
| Gold, Platinum, Diamond | $0.0335 |
- 10 pages: $0.50 on the Free plan, $0.335 on Gold.
- 1,000 pages: $50.00 on Free, $33.50 on Gold.
- 10,000 pages: $500.00 on Free, $335.00 on Gold.
Coverage and size. Proof runs on 17 Oct 2026: 40 pages of IRS Publication 17 at 200 DPI in about 4 minutes on the default 4 GB memory (more memory gives more CPU and runs faster); the Store example (6 pages) in about 20 seconds. Handwriting is not read reliably.
⚖️ Legal & ToS
Images belong to their owners. You choose the links. Make sure you have the right to download and use the content you point it at; the actor fetches only what you give it (and, where you turn it on, what those pages link to).
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
❓ FAQ
Does it read handwriting? Not reliably. Tesseract is built for printed and typed text.
Why is a page missing? Pages where OCR found no text are not delivered or billed; RUN_RECEIPT counts them.
Can I make it faster? Give the run more memory (Apify gives more CPU with more memory) or lower pdfDpi.
🆘 Troubleshooting
- Low confidence or garbled text — Check the languages; try pageSegmentation single_block or sparse; raise pdfDpi for small print.
- not an image or PDF — The link returned something else, such as a web page; use followImageLinks for pages.
- SOURCE UNAVAILABLE — None of your links could be reached after retries. Nothing was charged.
🔗 Related Actors
- Brand Logo & Favicon Lookup — a company's logo from its domain
- Website Performance Audit — Lighthouse scores and web vitals per page
- PR Newswire Scraper — press releases by company or topic
🏢 About NexGen Signal — data tools and official-source data products on Apify. Browse the catalog: apify.com/nexgensignal
⭐ Found this useful?
If this actor saved you time, a rating on its Apify Store page helps other buyers find it.
Part of NexGen Signal — data tools and official-source data products.


