
Speech to Text — Whisper Audio & Video Transcription
Pricing
from $33.50 / 1,000 audio minutes
Speech to Text — Whisper Audio & Video Transcription
Transcribe audio and video files by link with the open Whisper model: MP3, M4A, WAV, MP4 and more, about 100 languages. Full text, timed segments, word timings, SRT/VTT subtitles, or translate to English. Billed per minute. Part of NexGen Signal — data tools and official-source data products
Pricing
from $33.50 / 1,000 audio minutes
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
🎙️ Speech to Text — Whisper Audio & Video Transcription
Give direct links to audio or video files (MP3, M4A, WAV, OGG, FLAC, MP4, WebM, MOV and more) and get a transcript of each file: full text, timed segments, optional word timings, and ready-to-use SRT and WebVTT subtitles, in about 100 languages, or translated to English.
Transcription runs inside the actor with OpenAI's open Whisper model (base or small) through faster-whisper, so your audio is not sent to any outside speech service. Silence and music without speech are skipped, the language is detected automatically or set by you, and long recordings can be capped to their first minutes.
The unit of billing is one started minute of audio transcribed: a 20-second clip is 1 minute, a 40-minute episode is 40. Files with no speech, web pages, and files over your limits are not billed.
Who buys this and for what job
- Podcasters and video creators making transcripts and subtitles for their episodes.
- Researchers and journalists turning recorded interviews and talks into searchable text.
- AI builders adding audio and video to a knowledge base.
- Developers needing a speech-to-text step in an Apify workflow without another account or API key.
Buyers usually search for this as "speech to text", "Whisper transcription" or "audio to text API".
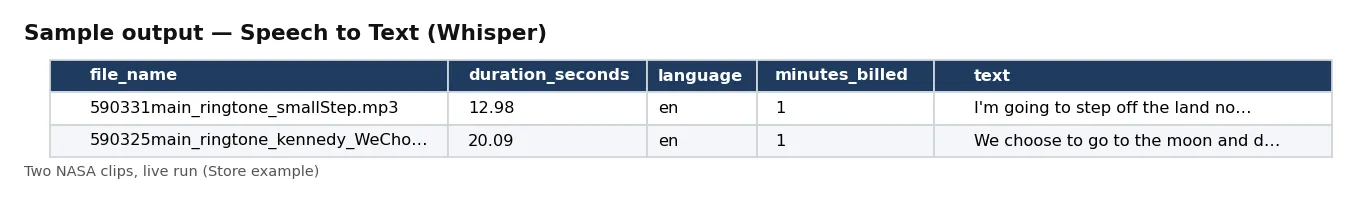
📊 Sample Output
| file_name | duration_seconds | language | minutes_billed | text |
|---|---|---|---|---|
| 590331main_ringtone_smallStep.mp3 | 12.98 | en | 1 | I'm going to step off the land now. It's one small step for man. One b … |
| 590325main_ringtone_kennedy_WeChoose.mp3 | 20.09 | en | 1 | We choose to go to the moon and disdicate and do the other things, not … |
Rows from live run T3fwibcdgAwRSi1nB on Apify (the Store example: two short NASA Apollo-era clips). Notice that short clips are billed as one started minute each.
✅ What you get
Every field of each record:
record_id,sha256,bytes— file hash (record_id is its first 24 characters) and size.url,final_url,file_name,content_type— the link, where it was served from, the file name and type.duration_seconds,transcribed_seconds,truncated,minutes_billed— length of the recording, how much was transcribed (maxMinutesPerFile), and the started minutes billed.language,language_probability,task,model— the language (detected or set) with its confidence, transcribe or translate, and the Whisper model.text,word_count— the transcript.segments— timed segments (start and end in seconds, text), with word timings when wordTimestamps is on.srt,vtt— subtitles (with includeSubtitles).processed_at— when it was transcribed (UTC).
⚙️ Sample inputs
Two short clips (the Store example)
About 2 minutes billed.
Subtitles and word timings with the small model
SRT and VTT text in the row.
First 40 minutes of a podcast episode
Caps the minutes billed per file.
Input fields:
| Field | Meaning |
|---|---|
mediaUrls | direct audio or video file links (up to 500). Not YouTube or other video pages. |
model | base (fast) or small (more accurate, slower); same price. |
language | auto, or a code such as en, es, de, fr, ja. |
task | transcribe, or translate to English. |
includeSegments, wordTimestamps, includeSubtitles | timed segments (default on), word timings, SRT/VTT. |
vadFilter | skip silence and music (default on). |
maxMinutesPerFile | transcribe at most this many minutes per file (default 120, up to 300). |
maxFileMb | skip files bigger than this (default 500). |
maxFiles | stop after this many files (default 100). Billing is per started minute transcribed. |
🧾 JSON sample record
🔧 How it works
Files are downloaded (3 at a time), decoded with FFmpeg (through PyAV) to 16 kHz mono, cut to maxMinutesPerFile, and transcribed one at a time with faster-whisper (int8 on CPU, beam search 5). The run uses 8 GB of memory by default, which gives it 2 CPU cores; more memory means more cores and faster runs.
Before a file is transcribed, its minutes are checked against your maximum charge: a file that would go over is skipped (not cut short) and smaller files can still follow.
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
Delivery is pushed first and charged after (the minutes for each file are charged when its row is delivered). The run receipt (RUN_RECEIPT) lists every link with its outcome and minutes, the robots.txt result per host, and the minutes delivered and charged.
💰 Pricing example
Per minute delivered, no start fee, no monthly charge:
| Apify plan | Price per minute |
|---|---|
| Free | $0.05 |
| Bronze | $0.045 |
| Silver | $0.04 |
| Gold, Platinum, Diamond | $0.0335 |
- The Store example, two short clips: 2 minutes = $0.10 on the Free plan, $0.067 on Gold.
- A 40-minute episode: $2.00 on Free, $1.34 on Gold.
- 10 hours of recordings: $30.00 on Free, $20.10 on Gold.
Coverage and size. Proof runs on 17 Oct 2026: the first 40 minutes of a 72-minute NASA podcast episode transcribed in about 4.5 minutes (7,128 words); the two Store-example clips in about 18 seconds. Accuracy depends on the recording; Whisper can mishear names and technical words, and the small model is more accurate than base.
⚖️ Legal & ToS
Recordings belong to their owners. You choose the links. Make sure you have the right to download and use the content you point it at; the actor fetches only what you give it (and, where you turn it on, what those pages link to).
The transcript is what the recording says; the actor adds nothing and does not identify speakers.
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
❓ FAQ
Can I give a YouTube link? No. Give a direct link to the audio or video file.
Is my audio sent to OpenAI or another service? No. The open Whisper model runs inside the actor.
How is a minute counted? Started minutes of audio transcribed per file: 61 seconds is 2 minutes. Only the part up to maxMinutesPerFile is billed.
🆘 Troubleshooting
- skipped: the link is a web page — Give the direct file link (for podcasts, the enclosure URL from the feed).
- Wrong language detected on a short clip — Set language, e.g. en.
- not processed: its N minute(s) would go over your maximum charge — Raise your maximum charge or lower maxMinutesPerFile.
- SOURCE UNAVAILABLE — None of your links could be reached after retries. Nothing was charged.
🔗 Related Actors
- PR Newswire Scraper — press releases by company or topic
- Website Tech Stack Detector — what a site is built with
- Brand Logo & Favicon Lookup — a company's logo from its domain
🏢 About NexGen Signal — data tools and official-source data products on Apify. Browse the catalog: apify.com/nexgensignal
⭐ Found this useful?
If this actor saved you time, a rating on its Apify Store page helps other buyers find it.
Part of NexGen Signal — data tools and official-source data products.


