
CATS ATS Jobs Scraper
Pricing
from $33.50 / 1,000 job_records
CATS ATS Jobs Scraper
One structured jobrecord per record from the official public source, logged-out. Public, robots-honoured.
Pricing
from $33.50 / 1,000 job_records
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
13 days ago
Last modified
Categories
Share
🧑💻 CATS ATS Jobs Scraper
One job_record per LIVE posting from a CATSone tenant career portal, deduped on the CATS job id. Category pages are navigated only to discover detail links and are never billed.
Public, robots-honoured.
Output is one job_record row per result; billing is pay-per-event, the value event being one job_record (a $0.02 start fee per run, then $0.05 per job_record). Source: addisonkenway.catsone.com.
No login, no API key and no CAPTCHA solving are involved: the source is read logged-out with an identified contact User-Agent.
Who buys this
Buyers usually search for CATS jobs or CATS ATS careers.
- Recruiters and staffing agencies pulling CATS jobs at target employers.
- Job boards and aggregators adding CATS ATS careers as clean, deduplicated rows.
- Sales and labour-market analysts using new postings as a hiring signal.
📊 Sample Output
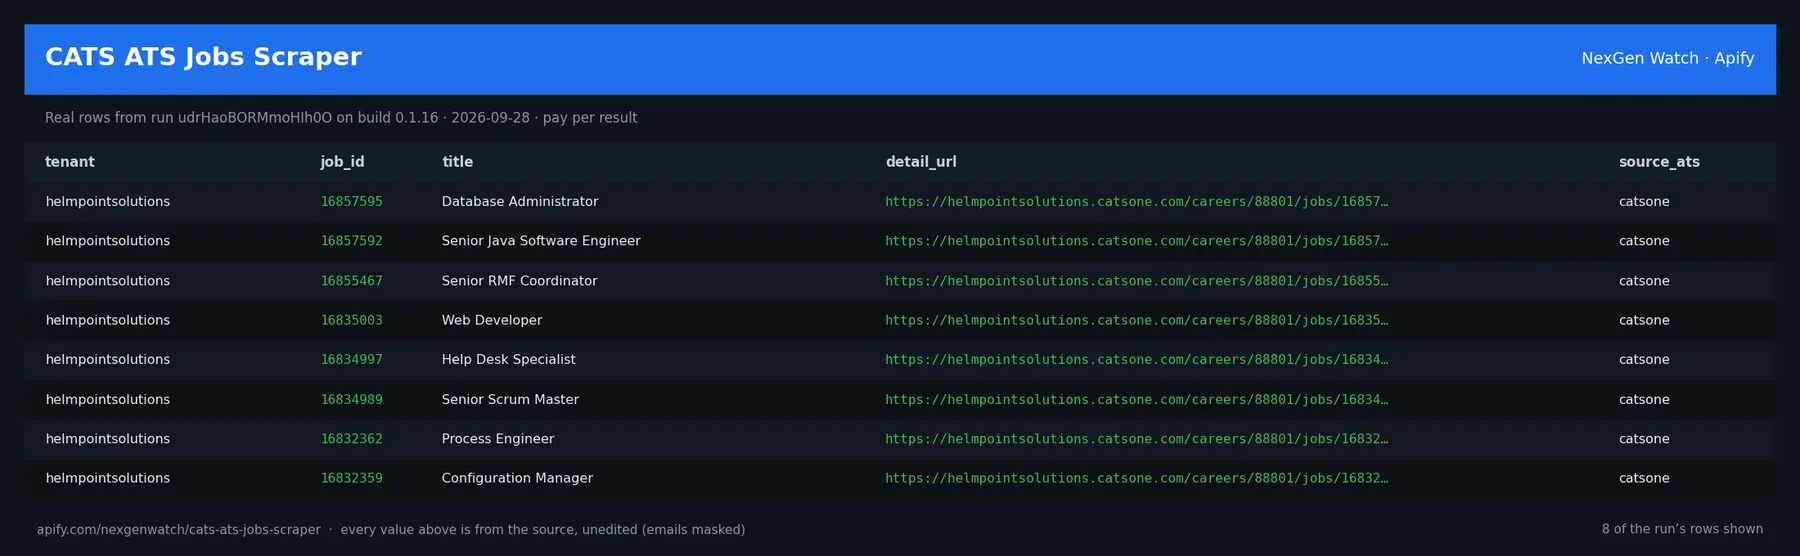
Real rows from run udrHaoBORMmoHIh0O on build 0.1.16 (2026-09-28), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
The run finished with the status message: NORMAL: 16 unique rows (0 duplicates collapsed). billable=16
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
record_type(string) — e.g.job_recordtenant(string/null) — e.g.helmpointsolutionsjob_id(string/null) — e.g.16857595title(string/null) — e.g.Database Administratordetail_url(string/null) — e.g.https://helmpointsolutions.catsone.com/careers/88801/jobs/16857595-Database-Admisource_ats(string/null) — e.g.catsonesource(string/null) — e.g.cats-ats-jobs-scraperrelease_date(string/null) — null in every sample rowsource_url(string/null) — e.g.https://{tenant}.catsone.com/careers/{id}/jobsobserved_at(string/null) — e.g.2026-09-28T04:24:01Zterminal(string/integer/null) — null in every sample rowreported_total(string/integer/null) — null in every sample rowraw_seen(string/integer/null) — null in every sample rowduplicates(string/integer/null) — null in every sample rowunique_found(string/integer/null) — null in every sample rowdelivered(string/integer/null) — null in every sample rowscope(string/integer/null) — null in every sample rownote(string/integer/null) — null in every sample row
✅ What you get
record_type(string) — e.g.job_recordtenant(string/null) — e.g.helmpointsolutionsjob_id(string/null) — e.g.16855467title(string/null) — e.g.Senior RMF Coordinatordetail_url(string/null) — e.g.https://helmpointsolutions.catsone.com/careers/88801/jobs/16855467-Senior-RMF-Cosource_ats(string/null) — e.g.catsonesource(string/null) — e.g.cats-ats-jobs-scraperrelease_date(string/null) — null in every sample rowsource_url(string/null) — e.g.https://{tenant}.catsone.com/careers/{id}/jobsobserved_at(string/null) — e.g.2026-09-23T16:06:45Zterminal(string/integer/null) — null in every sample rowreported_total(string/integer/null) — null in every sample rowraw_seen(string/integer/null) — null in every sample rowduplicates(string/integer/null) — null in every sample rowunique_found(string/integer/null) — null in every sample rowdelivered(string/integer/null) — null in every sample rowscope(string/integer/null) — null in every sample rownote(string/integer/null) — null in every sample row
✅ What you get
record_type(string) — e.g.job_recordtenant(string/null) — e.g.helmpointsolutionsjob_id(string/null) — e.g.16855467title(string/null) — e.g.Senior RMF Coordinatordetail_url(string/null) — e.g.https://helmpointsolutions.catsone.com/careers/88801/jobs/16855467-Senior-RMF-Cosource_ats(string/null) — e.g.catsonesource(string/null) — e.g.cats-ats-jobs-scraperrelease_date(string/null) — null in every sample rowsource_url(string/null) — e.g.https://{tenant}.catsone.com/careers/{id}/jobsobserved_at(string/null) — e.g.2026-09-17T17:03:55Zterminal(string/integer/null) — null in every sample rowreported_total(string/integer/null) — null in every sample rowraw_seen(string/integer/null) — null in every sample rowduplicates(string/integer/null) — null in every sample rowunique_found(string/integer/null) — null in every sample rowdelivered(string/integer/null) — null in every sample rowscope(string/integer/null) — null in every sample rownote(string/integer/null) — null in every sample row
What you get
One job_record per entity, deduplicated on the source-native id. Fields the source does not publish are honest null. A run_receipt row carries the source URL, scope, reconciliation counts, and delivered/duplicate totals.
Every run also writes a RUN_RECEIPT record to its key-value store with the source checks it made and the counts it charged — diagnostics never land in the paid dataset.
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 16 × $0.05 job_record = $0.82 on the Free tier — every delivered row was billed.
2. A smaller, narrowed run
Caps the run at 5 rows — about $0.27 on the Free tier ($0.02 start + 5 × $0.05).
3. A full-size run
Up to 5000 rows (the schema default for maxRecords) — about $250.02 on the Free tier ($0.02 start + 5000 × $0.05) if the source has that many.
4. A filtered run
Keeps only rows whose title contains Database Administrator (a value from the sample run above), matched case-insensitively after the source is read and before the maxRecords cap, so the cap counts matches and only delivered matches are billed. searchText does the same across every column. Zero matches end the run as EMPTY_SELECTION with no row charged — if the source has moved on since that sample run, pick a value you see in your own first run. The source is still read in full — this narrows what you receive and pay for, not what the source serves.
🧾 JSON sample record
One real record from run udrHaoBORMmoHIh0O, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Source. The actor reads addisonkenway.catsone.com — endpoints: https://addisonkenway.catsone.com/careers. Public pages and feeds only; nothing behind a login.
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent.
Charging. Each job_record is charged at the moment it is pushed (job_record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
🔧 How it works
🔧 How it works
How it behaves
Supply one or more CATSone tenant subdomains. Each board is read server-side, job-detail links harvested and deduped on (tenant, job id), category pages mined bounded for completeness. A 404/structure change fails loud; no live postings fails loud.
Source
https://{tenant}.catsone.com/careers
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
job_record (job_record) | $0.05 | $0.045 | $0.04 | $0.0335 |
Worked at the live Free-tier price:
- 8 job_records: $0.02 start + 8 × $0.05 = $0.42
- 25 job_records: $0.02 start + 25 × $0.05 = $1.27
- 5000 job_records: $0.02 start + 5000 × $0.05 = $250.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
Yield on the sample run: NORMAL: 16 unique rows (0 duplicates collapsed). billable=16. maxRecords is a hard ceiling on what is delivered and billed, never a target.
⚖️ Legal & ToS
This actor reads public, logged-out pages and feeds published by addisonkenway.catsone.com. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. The source (addisonkenway.catsone.com) is read logged-out; the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How many rows can one run return?
A: Up to maxRecords (default 5000). Raise the cap for a bigger run; you pay per delivered row.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other ATS job board scrapers actors?
A: Same output shape and billing model; this one covers addisonkenway.catsone.com. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Status says CAPPED → your cap (
maxRecords) was reached → raise it for a bigger run. - Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- ApplicantStack Jobs Scraper - Any Employer Board — Scrape job postings from any ApplicantStack careers board: title, location, department, posting date and apply link. One record per result. Pay per r…
- BambooHR Jobs Scraper - Any Employer Board — Scrape job postings from any BambooHR careers board: title, location, department, posting date and apply link. One record per result. Pay per result
- BreezyHR Jobs Scraper - Any Employer Board — Scrape job postings from any BreezyHR careers board: title, location, department, posting date and apply link. One record per result. Pay per result
- Comeet Jobs Scraper - Any Employer Board — Scrape job postings from any Comeet careers board: title, location, department, posting date and apply link. One record per result. Pay per result
- Flair Hosted Jobs Scraper — One structured jobrecord per record from the official public source, logged-out. Public, robots-honoured
- HireBridge Jobs Scraper — One structured jobrecord per LIVE job posting from a public, logged-out ATS board. Public, robots-honoured
- 🏢 About NexGen Watch — NexGen Watch is a catalog of more than 300 public data actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


