
Merger and Acquisition Announcements Scraper
Pricing
from $33.50 / 1,000 merger acquisition alerts
Merger and Acquisition Announcements Scraper
Scrape announced mergers and acquisitions from GlobeNewswire releases: acquirer, target, deal value, headline and date. One record per result. Pay per result.
Pricing
from $33.50 / 1,000 merger acquisition alerts
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
1
Monthly active users
8 days ago
Last modified
Categories
Share
📰 Merger and Acquisition Announcements Scraper
Scrape announced mergers and acquisitions from PR Newswire, Newswire.ca and GlobeNewswire releases: acquirer, target, deal value, headline and date. Run it once and you get the current records as a dataset; put it on a schedule to keep the list current.
Announced mergers and acquisitions, classified from the headline of the wire release itself. Each row carries the structured facts pulled from that headline plus the headline, the publish date and the release link — never the article body. Source: public wire RSS feeds — PR Newswire and Newswire.ca topic feeds, plus GlobeNewswire's subject-coded and keyword feeds (the M&A subject feed plus Joint Venture, Business Contracts and Company Announcement) whenever GlobeNewswire answers; public RSS only, no login, no paywall, robots honoured per feed.
Never billed twice (2026-09-17). Every alert delivered is remembered (release id and headline) in a named key-value store under historyId, so a run on a schedule delivers only releases it has not billed before; syndicated copies of the same release inside one scan are collapsed; releases older than maxAgeDays (default 30) are never billed. Measured yield on a fresh history: 5 alerts from 54 headlines on 2026-09-18.
Output is one event_alert row per result; billing is pay-per-event, the value event being one merger acquisition alert (a $0.02 start fee per run, then $0.05 per merger acquisition alert). Sources: www.prnewswire.com, www.newswire.ca, www.globenewswire.com.
No login, no API key and no CAPTCHA solving are involved: the source is read logged-out.
Who buys this
Buyers usually search for M&A announcements or acquisition announcements.
- B2B sales and account teams using M&A announcements as a trigger signal.
- PR, comms and market-intelligence teams monitoring acquisition announcements.
- Investors and analysts tracking company events as they are announced.
📊 Sample Output
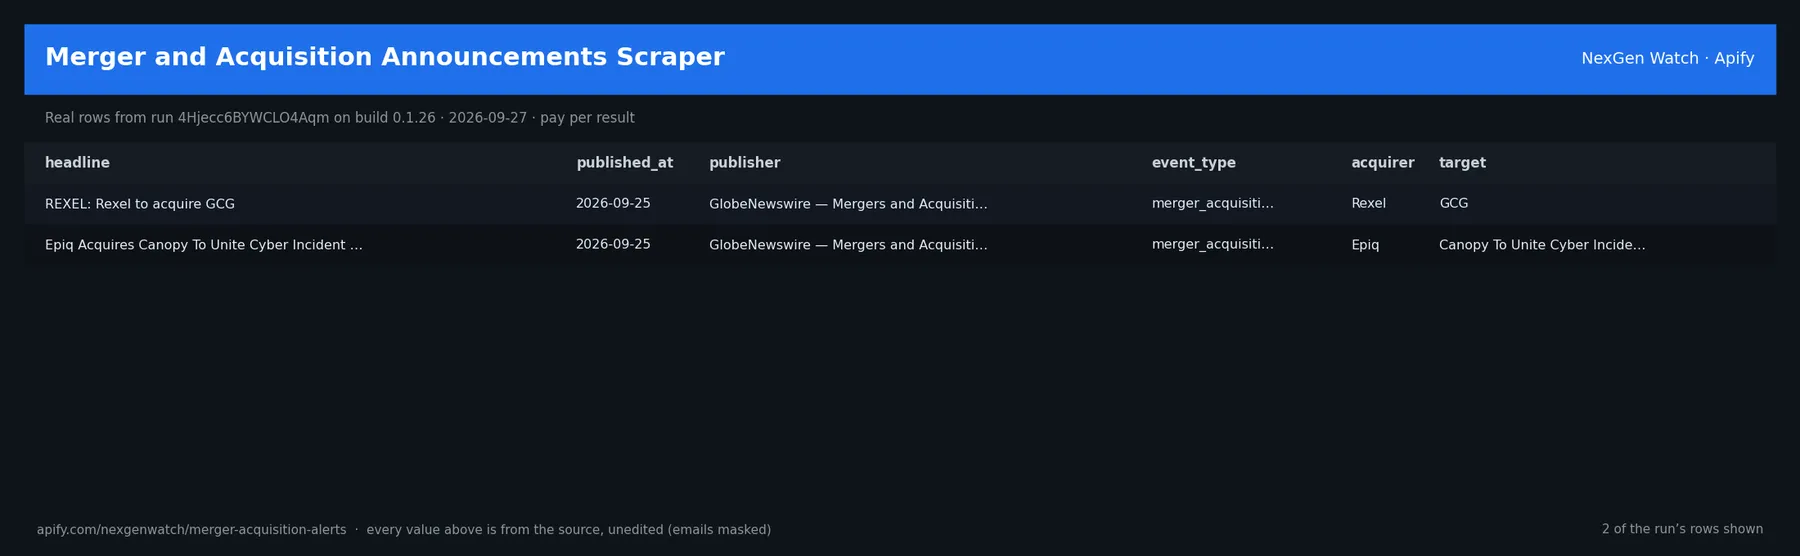
Real rows from run 4Hjecc6BYWCLO4Aqm on build 0.1.26 (2026-09-27), from an earlier Store example input ({"maxRecords": 25}) — every value is as the source published it (emails masked, long text shortened):
| headline | published_at | publisher | event_type | acquirer | target |
|---|---|---|---|---|---|
| REXEL: Rexel to acquire GCG | 2026-09-25 | GlobeNewswire — Mergers and Acquisitions | merger_acquisition | Rexel | GCG |
| Epiq Acquires Canopy To Unite Cyber Incident Response Technology and S | 2026-09-25 | GlobeNewswire — Mergers and Acquisitions | merger_acquisition | Epiq | Canopy To Unite Cyber Incident |
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
record_type(string) — e.g.event_alertevent_slug(string/null) — e.g.merger-acquisitionheadline(string/null) — e.g.REXEL: Rexel to acquire GCGpublished_at(string/null) — e.g.2026-09-25publisher(string/null) — e.g.GlobeNewswire — Mergers and Acquisitionssource_url(string/null) — e.g.https://www.globenewswire.com/news-release/2026/09/25/3369234/0/en/rexel-rexel-tguid(string/null) — e.g.https://www.globenewswire.com/news-release/2026/09/25/3369234/0/en/rexel-rexel-tobserved_at(string/null) — e.g.2026-09-27T16:23:20Zevent_type(string/null) — e.g.merger_acquisitionacquirer(string/null) — e.g.Rexeltarget(string/null) — e.g.GCGdeal_value(string/null) — null in every sample rowstake— null in every sample rowcompanies(array/null) — e.g.["Rexel", "GCG"]person(string/null) — null in every sample rowrole(string/null) — null in every sample rowdirection(string/null) — null in every sample rowcompany(string/null) — null in every sample rowexpansion_type(string/null) — null in every sample rowlocation(string/null) — null in every sample rowcompany_a(string/null) — null in every sample rowcompany_b(string/null) — null in every sample rowpartnership_type(string/null) — null in every sample rowproduct(string/null) — null in every sample rowcategory(string/null) — null in every sample rowterminal(string/null) — null in every sample rowscanned(integer/null) — null in every sample rowmatched_no_date(integer/null) — null in every sample rowfeed_errors(array/null) — null in every sample rowdelivered(integer/null) — null in every sample row
Every run also writes a RUN_RECEIPT record to its key-value store with the source checks it made and the counts it charged — diagnostics never land in the paid dataset.
⚙️ Sample inputs
1. Quick start — the Store example
Returns up to 10 rows on any day: delivery memory is off for this run (skipPreviouslyDelivered: false) and there is no age limit (maxAgeDays: 0), so releases delivered on an earlier run are shown again. For a scheduled feed that only bills new releases, leave skipPreviouslyDelivered on (the default).
2. A smaller, narrowed run
Caps the run at 5 rows; same billing shape as the sample run above. historyId narrows what the source is asked for.
3. A full-size run
The same input run on a schedule; each run is billed only for what it delivers.
🧾 JSON sample record
One real record from run 4Hjecc6BYWCLO4Aqm, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Source. The actor reads www.prnewswire.com, www.newswire.ca and www.globenewswire.com — endpoints: https://www.prnewswire.com/rss/financial-services-latest-news/acquisitions-mergers-and-takeovers-list.rss, https://www.newswire.ca/rss/financial-services-latest-news/acquisitions-mergers-and-takeovers-list.rss, https://www.prnewswire.com/rss/general-business-latest-news/real-estate-transactions-list.rss, https://www.globenewswire.com/RssFeed/subjectcode/27-x/feedTitle/GlobeNewswire, https://www.globenewswire.com/RssFeed/subjectcode/23-x/feedTitle/GlobeNewswire, https://www.globenewswire.com/RssFeed/subjectcode/37-x/feedTitle/GlobeNewswire. Since 2026-10-06 GlobeNewswire has refused requests from Apify's servers; those feeds are still tried every run and the refusal is listed in the run receipt, while the other feeds keep the run going. Public pages and feeds only; nothing behind a login.
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched.
Terminal states. A run ends NORMAL, CAPPED (your cap was reached), PARTIAL (something was withheld and the message says what), GENUINE_EMPTY (the source was read and truly had nothing in scope) or BLOCKED (the source refused or changed shape — the run FAILS loud and bills nothing). A zero-row run is never reported as a silent success.
Charging. Each merger acquisition alert is charged at the moment it is pushed (merger_acquisition_alert); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
Classification. A headline is an alert only when it clearly states this event type; the classifiers are mutually exclusive (an M&A headline is never a partnership, and so on) and a headline that does not clearly state the event is skipped, unbilled. Entities (companies, person, role, location, deal value) are extracted from the headline only — a wire label such as "PR Newswire — Joint Ventures" is never taken as the company.
Feeds. Each wire's public RSS feeds carry the 20 most recent releases in that topic, subject or keyword tag, so a scheduled run sees a rolling window; sources can be replaced with any public RSS/Atom/JSON feed list.
Delivery memory. skipPreviouslyDelivered (default true) keeps the ids and headlines of everything billed under historyId in a named key-value store for 120 days; set it to false for a one-off full scan, or use a different historyId per client.
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
⏰ Optional: run it on a schedule
A single run returns the current records. If you also want to be told what changed over time, open the actor in Apify Console → Schedules → Create new, add this actor with the input you want, and pick a cadence:
- Daily —
0 7 * * *(07:00 UTC): catch changes within a day. - Weekly —
0 7 * * 1: a Monday digest.
Each run is independent; keep the same input on the schedule so the results stay comparable. Schedules can also POST results to a webhook (Console → Integrations).
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Merger Acquisition Alert (merger_acquisition_alert) | $0.05 | $0.045 | $0.04 | $0.0335 |
Worked at the live Free-tier price:
- 2 merger acquisition alerts: $0.02 start + 2 × $0.05 = $0.12
- 25 merger acquisition alerts: $0.02 start + 25 × $0.05 = $1.27
- 200 merger acquisition alerts: $0.02 start + 200 × $0.05 = $10.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
maxRecords is a hard ceiling on what is delivered and billed, never a target.
⚖️ Legal & ToS
This actor reads public, logged-out pages and feeds published by www.prnewswire.com, www.newswire.ca and www.globenewswire.com. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. The sources (www.prnewswire.com, www.newswire.ca, www.globenewswire.com) are read logged-out; the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How many rows can one run return?
A: Up to maxRecords (default 200). Raise the cap for a bigger run; you pay per delivered row.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other newswire announcement scrapers actors?
A: Same output shape and billing model; this one covers www.prnewswire.com, www.newswire.ca and www.globenewswire.com. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Status says CAPPED → your cap (
maxRecords) was reached → raise it for a bigger run. - Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- Company Expansion Announcements Scraper — Scrape company expansion announcements from PR Newswire, Newswire.ca and GlobeNewswire releases: company, expansion type, location, headline and date. One record per result. Pay…
- Executive Appointment Announcements Scraper — Scrape executive appointments and departures from PR Newswire, Newswire.ca and GlobeNewswire releases: company, person, role, headline and date. One record per result. Pay per re…
- Partnership Announcements Scraper — Scrape announced partnerships, joint ventures and integrations from PR Newswire, Newswire.ca and GlobeNewswire releases: parties, type, headline and date. One record per result.…
- Product Launch Announcements Scraper — Scrape product and service launches from PR Newswire, Newswire.ca and GlobeNewswire releases: company, product, category, headline and date. One record per result. Pay per result
- 🏢 About NexGen Watch — NexGen Watch is a catalog of more than 300 public data actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


