
PDF & Document to JSON Extractor (AI) — Invoices, Forms
Pricing
from $10.20 / 1,000 rules-based extracted documents
PDF & Document to JSON Extractor (AI) — Invoices, Forms
Turn PDF, DOCX and HTML documents into JSON that matches your own schema: invoices, contracts, forms, statements. Free rules mode, or Claude with your key or ours (fast, balanced, best tiers). Pay per document and page, no browser, no proxies.
Pricing
from $10.20 / 1,000 rules-based extracted documents
Rating
0.0
(0)
Developer
Owlabee
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
9 hours ago
Last modified
Categories
Security
Limited permissionsShare
Document to JSON extractor: send PDF, DOCX or HTML documents by URL together with your own JSON schema and get back one JSON object per document that matches it, for invoices, contracts, forms and statements. Use the rules mode without any model, or Claude with your own key or the hosted tiers; there is no browser and no proxy.
Renamed on 2026-11-07: this Actor's address changed from
owlabee/document-to-json-extractortoowlabee/pdf-to-json. Saved tasks, schedules, webhooks and integrations keep working, because they point to the Actor's ID, which did not change. Update anything that calls it by name: API URLs (owlabee~pdf-to-json), MCP tool lists (owlabee/pdf-to-json) and bookmarks.
What it does
AI Document to JSON Extractor turns documents into structured data that matches a schema you define. Give it the URLs of PDF, DOCX, HTML, Markdown or text files and a JSON Schema of the object you want (vendor, invoice number, line items, totals; parties, effective date, termination clause, governing law; form title, fields, revision date), and for each document it writes one dataset item with the filled object in data, a per-field confidence score, the list of fields it could not find, and the document's metadata (filename, pages, title, author). The documents are read with a real layout engine (headings, tables, lists, page markers from PDFs; DOCX structure; HTML), not a plain text dump, so tables become rows and labels stay next to their values.
It has three extractors, chosen with the extractor input and recorded on every item as extractionMethod. AI extraction is the default: when extractor is left empty the Actor uses the hosted Claude model; set extractor=rules for a free, model-free run, or extractor=byok to use your own key.
hosted(default): Claude on the Actor's own key, tokens included, from $0.02 per document plus $0.002 per page. Nothing to set up. Pick a model tier:fast(Claude Haiku 5.5),balanced(Claude Sonnet 5.5) orbest(Claude Opus 5.5). The model fills your schema through structured output, so the JSON always has your shape; fields the document does not state come backnull, and the model lists the fields it was unsure about inlowConfidenceFields. If the model cannot be reached, the document gets the rules extraction instead, markedextractionMethod: "rules-fallback"with anextractionWarning, and is charged the rules price; a run never fails because of the model.byok(bring your own key): Claude fills the schema using theanthropicApiKeyyou supply (stored as a secret, sent only to api.anthropic.com), on the same three tiers. You pay Anthropic for the tokens and $0.01 per document here; each item recordstokensIn,tokensOutandmodelCostUsdEstimate.rules: a deterministic extractor with no language model. It collects label/value pairs, tables, numbered form fields, dates, amounts, emails, phone numbers and URLs from the document and matches them to your field names, titles and descriptions, coercing types (money text to numbers, dates to ISO, yes/no to booleans, table rows to arrays of objects). No key, runs in seconds, costs $0.012 per document. Right for well-labeled documents (invoices, forms, statements), for bulk first passes, and for checking what the model modes add.
Built for finance and legal operations (invoices, purchase orders, bank statements, contracts, NDAs, lease abstracts), procurement and compliance teams processing government forms, and AI agents that find a document and need it as JSON on demand. Results are available as JSON, CSV, Excel, through the API, webhooks and the Apify MCP server.
Construction estimators use it too: a roof takeoff schema run on drawing and spec PDFs with a text layer, and supplier quotes turned into line items for estimate reconciliation; see the task examples.
Scanned documents go first through PDF to Markdown for RAG — DOCX, OCR & Chunks with OCR on; it is the same layout engine, so the Markdown it writes to a key-value store drops straight into this Actor.
Why this Actor
| This Actor | Typical converter in this category | Do it yourself | |
|---|---|---|---|
| Inputs accepted | PDF, DOCX, HTML, Markdown and text by public URL, kvs:// reference or data: URL, many per run, plus the JSON Schema of the object you want | A PDF upload and a free-text list of field names | A PDF text library, a prompt and a JSON parser you maintain |
| Modes or model tiers | rules (no model, deterministic), byok (your own key, three tiers) and hosted (fast, balanced, best tiers with tokens included) | One model with no choice of tier, or model only with no model-free option | One model call per document, retries and fallbacks written by you |
| Output fields | data in exactly the shape of your schema, per-field confidence, missingFields, extraction notes, token counts, document metadata and a text preview | A JSON blob whose keys can change from one document to the next | Whatever the model returns, repaired by hand when it is not valid JSON |
| Pricing unit | Per document at the tier you chose, plus per page on the hosted tiers; error items at the rules rate | Per PDF at one flat rate whatever the mode, or a subscription | Your tokens and compute, plus the hours spent on prompt and parser upkeep |
| Needs an API key or proxies | No proxies; a key only in byok mode | Often needs your own model key for every run | A model key |
| Agent/MCP ready | Yes: pin link, fetch-actor-details, pay per run | Sometimes | You write the tool wrapper |
| Limits | Files up to 50 MB, about 60 pages of text per model call, 200 schema fields; a scan without a text layer returns a NO_TEXT item (OCR via the converter) | Usually undocumented | Whatever your machine and quota allow |
- The JSON always has your shape: every property present, unfilled ones
null, so downstream code never checks for missing keys. - The
rulesextractor gives a model-free first pass over well-labeled documents, and a failed model call falls back to it at the rules price instead of failing the run. - Per-field confidence and the
missingFieldslist let you route only the uncertain documents to a human. - The run's maximum total charge is checked before every model call, so a batch never overruns the limit you set.
- Structured output from the model, with values that do not fit your types set to
nulland listed invalidationWarnings.
Free alternatives vs this Actor
| Tables kept | OCR | Batch of URLs | Structured output | Runs on a schedule or from an agent | Cost unit | |
|---|---|---|---|---|---|---|
| Copy-paste from a PDF viewer | No, columns collapse into lines | No | No, one file at a time | No, you retype the values | No | Your time per document |
| Open-source CLI tools run locally | Partly, depends on the tool | Only with a separate OCR install | Yes, with a shell loop you write | Text only; the field mapping is still your code | Only with your own scheduler and server | Your machine and maintenance hours |
| Generic LLM chat upload | Usually | Yes, the model reads the page image | No, a few files per conversation | Only when prompted, and keys drift between conversations | No | A chat subscription, one conversation at a time |
| This Actor | Yes, table rows become arrays of objects | Not inside this Actor; scans go through the converter first | Yes, many URLs per run | Exactly your schema, with confidence per field | Yes: Console schedules, API, webhooks, MCP | Per document, plus per page on the hosted tiers |
How to use
- Enter your Document URLs (one per line): public links to PDF, DOCX, HTML, Markdown or text files,
kvs://<storeId>/<key>references to files in an Apify key-value store, ordata:URLs. - Paste the JSON Schema of the object you want per document. Give every field a
descriptionso the extractor knows what to look for; useformat: "date"for dates andenumfor fixed choices. The prefilled schema describes a government form; replace it with yours. - Leave Extractor empty for hosted AI extraction and pick a Model tier (
fastis the default); or choosebyokand paste your Anthropic API key; or chooserulesfor a free, model-free run. Click Start. One item per document appears in the dataset as each extraction is ready.
Quick start input
The same input the Store runs in its daily automated test, so it is cheap and always available; paste it into the JSON tab of the input form or send it as the body of an API or MCP call:
Ready-to-run inputs
Replace the example URLs with your own; each block validates against the input schema. The key placeholder is a string you replace, never a real key in a README.
An invoice batch on the rules tier (no model, no key)
A contract on the hosted balanced tier
A bank statement with your own key (BYOK)
Input
| Field | Type | Required | Description |
|---|---|---|---|
urls | string[] | yes | Document URLs, kvs://<storeId>/<key> references or data: URLs, one per line |
schema | object | yes | JSON Schema (draft-07 subset) of the object to extract: type: object with properties; field types string, number, integer, boolean, array, object; description, format (date, date-time, email, uri), enum. Nested objects and arrays of objects are supported; $ref, oneOf/anyOf are not |
extractor | string | no | hosted, byok or rules. Empty = hosted when the Actor's model key is configured, else rules |
anthropicApiKey | string (secret) | for byok | Your Anthropic API key; used only in byok mode |
modelTier | string | no | fast (default, Claude Haiku 5.5), balanced (Claude Sonnet 5.5) or best (Claude Opus 5.5); applies to hosted and byok |
instructions | string | no | Extra guidance for the model (conventions, what to ignore, how to choose between candidates). Ignored by rules |
maxInputTokens | integer | no | Per-document input cap for model modes, 2,000–40,000 (default 40,000, about 60 pages). Longer documents are cut and the item marked inputTruncated: true |
maxConcurrency | integer | no | Documents processed in parallel, 1–5 (default 2) |
includeMarkdown | boolean | no | Also write the document's full converted Markdown on the item (default false; a 1,000-character textPreview is always there) |
maxFileSizeMb | integer | no | Files larger than this become a TOO_LARGE error item (default 25, max 50) |
downloadTimeoutSecs | integer | no | Per-file download timeout (default 20, max 120) |
webhookUrl | string | no | POST target for the run summary (documents, errors, pages, fields filled, token totals, charges) |
Output example
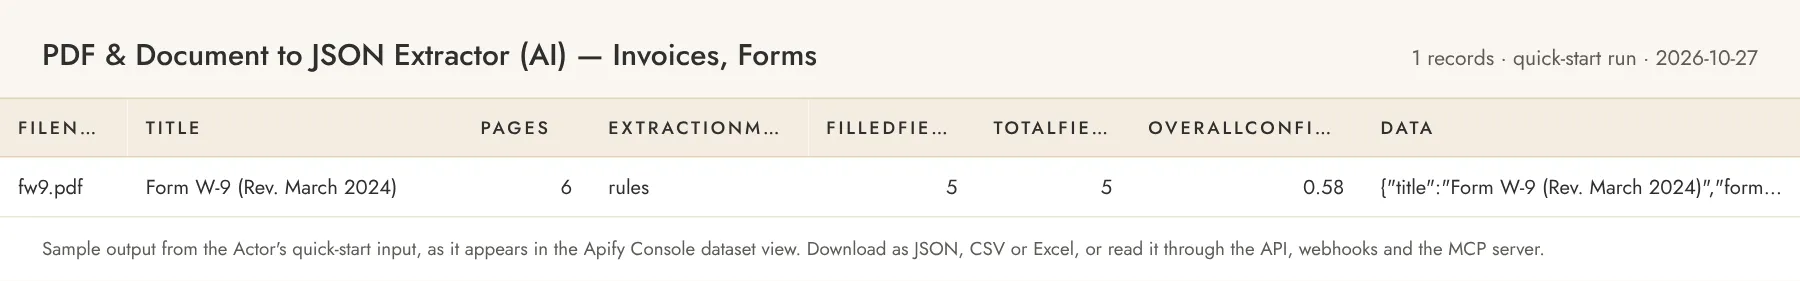
An item produced in rules mode from the IRS Form W-9 with the prefilled schema (title, formNumber, revisionDate, issuer, fields[]):
data always has exactly the shape of your schema: every property is present, unfilled ones are null (nested objects keep their keys, each null). confidence has one number per top-level property (0 = not found, up to 0.9 for an exact label match in rules mode; in model modes it is the model's overall confidence, lowered to at most 0.5 for the paths it lists in lowConfidenceFields). filledFields, totalFields and missingFields count the fields a document can fill (each scalar, each array once).
Items written in byok or hosted mode carry the same data and confidence and additionally modelTier, model, tokensIn, tokensOut, modelCostUsdEstimate (USD at Anthropic list prices), inputTruncated (with inputKeptRatio and inputTruncationNote when the document was cut to the cap), lowConfidenceFields, extractionNotes (the model's remarks: unreadable tables, conflicting values) and validationWarnings (values the model returned that did not fit your types and were set to null). If a model call fails (rate limit, API error, timeout, refusal, invalid JSON) or the hosted model is not configured, the item falls back to the rules extraction with extractionMethod: "rules-fallback", records the reason in extractionWarning, and is charged the rules price.
Error items look like { "recordType": "document", "url": "…", "error": "NOT_FOUND", "errorMessage": "HTTP 404 for …" } with codes INVALID_URL, DOWNLOAD_FAILED, NOT_FOUND, TIMEOUT, TOO_LARGE, UNSUPPORTED_TYPE, CORRUPT_FILE, PASSWORD_PROTECTED, PROCESSING_FAILED and NO_TEXT (a scanned PDF without a text layer, see FAQ). They are charged at the rules price, because the work to discover the problem was done. An unusable schema, a byok run without a key, or a key Anthropic rejects fails the run with a clear message before any further document is charged.
If the output saves you time, a review on the Store page helps other buyers find this Actor; the Store invites you to leave one after you have run it a few times.
Batch and pipeline use
- URLs from another run. Any dataset whose items carry a document link can feed this Actor: read it with
GET https://api.apify.com/v2/datasets/<datasetId>/items?format=json&fields=url, collect the links, and send them asurlstogether with yourschemain a new run (POST https://api.apify.com/v2/acts/owlabee~pdf-to-json/runs), or from code with the Apify client:client.actor('owlabee/pdf-to-json').call({ urls, schema, extractor: 'rules' }). - Files you hold. Upload them to a key-value store (
PUT https://api.apify.com/v2/key-value-stores/<storeId>/records/<key>) and reference them askvs://<storeId>/<key>; scans go through the PDF to Markdown Converter withocrandsaveToKeyValueStoreon first, and itskvs://output is accepted here as is. - Reading results.
GET https://api.apify.com/v2/actor-runs/<runId>/dataset/items?format=json&fields=url,data,confidence,missingFields,extractionMethodreturns just the filled objects and their quality signals;format=csvflattens them for a spreadsheet. TheSUMMARYrecord in the run's key-value store totals documents, errors, pages, fields filled, model calls and tokens, fallbacks and the charges per event; the latest run is reachable atGET https://api.apify.com/v2/acts/owlabee~pdf-to-json/runs/last/dataset/items. - Run-end notification.
webhookUrlreceives one POST withactor,runIdand that summary when the run finishes, and theSUMMARYrecord then carrieswebhookDelivered; for per-run events (succeeded, failed, timed out) use the Actor webhooks on the Integrations tab. - Routing by confidence. Filter the items on
overallConfidenceor a non-emptymissingFieldsin your own code to send only the doubtful documents to review; the rest can post straight into your accounting or contract system.
Pricing
Pay per event. You only pay for what the Actor produces; set a maximum cost per run in the run options to cap spend.
| Event | Price | Notes |
|---|---|---|
| Rules-based extracted document | $0.012 | Per document item in rules mode or on a rules-fallback; error items are charged at this price too |
| BYOK extracted document | $0.01 | Per document extracted by Claude in byok mode, any tier, any length; your tokens are billed by Anthropic, not here |
| Hosted fast-tier extracted document | $0.02 | Claude Haiku 5.5 on the Actor's key, tokens included, up to 40,000 input tokens per document |
| Hosted fast-tier processed page | $0.002 | Per chargeable page of a fast document, on top of the document event |
| Hosted balanced-tier extracted document | $0.15 | Claude Sonnet 5.5, same caps |
| Hosted balanced-tier processed page | $0.02 | Per page of a balanced document |
| Hosted best-tier extracted document | $0.30 | Claude Opus 5.5, same caps |
| Hosted best-tier processed page | $0.04 | Per page of a best document |
| Actor start | $0.00005 | Apify platform event |
A chargeable page is a physical page read (PDF; the declared page count for DOCX) or 3,000 characters of converted text, whichever is more, counting only the part of the document within the 40,000-token input cap: a dense 30-page contract that fills the cap is charged as the ~47 pages of text it contains, and a 500-page PDF is charged only for the pages the model reads. Each item records pagesCharged in hosted mode.
Store pricing discounts: users on the Scale plan (Silver) pay 10% less per event, Business (Gold) 15–20% less.
Worked examples. 100 three-page invoices on hosted fast (the default) ≈ $2.60 (100 × $0.02 + 300 × $0.002), nothing else to pay; balanced ≈ $21.00; best ≈ $42.00. Bring your own key: the same 100 invoices ≈ $1.00 here plus roughly $0.10 of Claude Haiku 5.5 tokens on your Anthropic bill (about 5,000 input and 800 output tokens per three-page document at $0.10 and $0.50 per million); about $1.90 on Sonnet 5.5 ($2 and $10 per million) or $3.80 on Opus 5.5 ($4 and $20 per million). Rules: 1,000 documents ≈ $12.00.
Spending limit and model tiers. The hosted model is called before its events are charged, so before every model call the Actor checks that your run's maximum total charge still covers the document event plus the per-page events for that document. When it does not, the model is not called: the document gets the rules extraction instead, charged at the rules price, with an extractionWarning that names the tier, the amount and the limit to set (the run's SUMMARY counts these as modelSkippedForSpendingLimit). When not even a rules item fits, the run stops cleanly with a log line and nothing more is charged. A run with no limit set behaves as before. In practice: set the maximum total charge to at least (document price + page price × pages) times the number of documents you want the model to handle.
How the hosted prices are set. Against the worst case, not the average. The document is capped at 40,000 input tokens (about 60 pages of text), every call carries about 1,700 fixed tokens of instructions and schema on top, and output is capped at 4,000 tokens per document, so the most one document can cost in tokens is: fast 41,700 × $0.10/M + 4,000 × $0.50/M ≈ $0.0062; balanced 41,700 × $2/M + 4,000 × $10/M ≈ $0.12; best 41,700 × $4/M + 4,000 × $20/M ≈ $0.25. A document that fills the cap holds about 140,000 characters, which is at least 47 chargeable pages whatever its physical layout, so it is charged at least $0.114, $1.09 and $2.18 respectively (document + 47 pages); Apify pays developers 80% of that, so every tier clears its worst-case token and compute cost even at the cap, by about 12×, 7× and 7× (a margin above 85% on every tier), and a typical three-page document costs a fraction of a cent in tokens on fast. The per-page events are what keep short documents cheap and long ones covered. Reasoning tokens are kept out of the output cap (thinking is turned off on Haiku and Sonnet; Opus runs at low effort). A model failure is never charged at the hosted price: the item falls back to the rules extraction at $0.012.
Limits and fair use
- Documents are fetched with plain HTTP from Apify datacenter IPs (up to 25 MB each by default, 50 MB maximum, 20 s download timeout) and converted in memory; conversion of one document stops after 5 minutes and the item says so in
warnings(PROCESSING_TIMEOUT). The Actor runs with 512–1024 MB of memory because the PDF engine caches pages and fonts; default run memory is 512 MB, andmaxConcurrencyshould stay at 2 for large PDFs. - Time budget. Each document gets its download time (
downloadTimeoutSecs, a single deadline for the whole download that is not retried) plus 5 minutes of PDF conversion. A document that cannot be downloaded in time returns aTIMEOUTerror item, charged at the rules rate like every error item, and a blocked or failing URL is never retried. A model call that takes longer than 60 seconds is cancelled without a retry and the document gets the rules extraction at the rules rate (modelFallbacksToRulesin the summary counts these). - Supported inputs: PDF (text layer), DOCX, HTML, Markdown and plain text. Scanned PDFs without a text layer produce a
NO_TEXTerror item and list their pages inneedsOcrPages; run them through the PDF & DOCX to Markdown Converter (same account) with OCR on, save the Markdown to a key-value store, and pass thekvs://reference here. Password-protected PDFs producePASSWORD_PROTECTED. - Schema:
type: objectat the top, at most 6 levels deep and 200 fields; field types object, array, string, number, integer, boolean, null;enum,description,title,format. Numeric and string constraints (minimum,pattern,maxLength…) and$ref/oneOf/anyOfare not enforced; the former are ignored with a warning in the log, the latter are rejected before any charge. The model modes work with schemas of any size up to that cap: the schema is sent to the model in a form that stays within the Anthropic structured-output limits (16 union-typed and 24 optional parameters per request), so a 50- or 150-field schema is extracted by the model, not by the rules fallback. - Model modes cut the document to
maxInputTokens(at most 40,000 tokens, about 60 pages) before the call and say so on the item; fields that appear only later in the document are thennull. Output is capped at 4,000 tokens per document, so very large arrays (hundreds of line items) may be cut: split such documents or use therulesextractor, which has no output cap, for the table and the model for the rest. - The rules extractor is deterministic and language-agnostic in its mechanics (labels, tables, numbers) but its date and amount parsing is tuned to English-language business documents; day-first dates are read correctly only when the day is above 12 or the month is spelled out.
- Only public data is accessed: the URLs you give, your own key-value stores and, in model modes, the Anthropic API. Document and webhook URLs must point at public hosts: a URL (or a redirect, at most 5 hops) that resolves to a loopback, private, link-local or cloud-metadata address is rejected with
INVALID_URL. YouranthropicApiKeyis stored encrypted by Apify and is never logged or written to the dataset. Document text is sent to the Anthropic API only in model modes and only to produce the extraction.
Related Actors
- PDF & DOCX to Markdown Converter for AI Agents (same account): the same layout engine without a schema, with OCR for scanned pages and RAG chunks, $0.001 per page. Use it first for scans, then feed the Markdown here.
- AI Drone Roof Inspection Report — Findings & Repair Scope — turns drone roof photos into findings and a repair scope; feed it extracted supplier price lists for costed estimates.
- Grant Matching & RFP Bid/No-Bid Scorer (AI) — Grants.gov — score extracted RFP and grant documents against your organization profile for a bid/no-bid call.
Guide and code examples
- Guide: PDF to JSON with Your Own Schema: Invoices, Forms, Quotes, covering the source, its fields and limits, and curl and MCP examples.
- Runnable examples (curl, Python, Node.js and an MCP config): owlabee/owlabee on GitHub.
Use from AI agents (MCP)
Pin this Actor in the Apify MCP server with one link: https://mcp.apify.com?tools=owlabee/pdf-to-json, or let the agent find it with the search-actors tool. It is pay-per-event with limited permissions, so agents can discover it, inspect the input schema with fetch-actor-details and pay per run through agentic payments. Prompts that map directly onto the input:
- "Extract vendor, invoice number, date, line items and total from these 20 invoice PDFs into JSON with the AI Document to JSON Extractor."
- "Pull the parties, effective date, term, termination clause and governing law out of this NDA (DOCX link) as a JSON object."
- "Turn this bank statement PDF into a list of transactions with date, description and amount, using my Anthropic key, and tell me which fields it was unsure about."
The agent receives the same dataset records shown in the output example above.
Copy this block to call the Actor through the Apify MCP server with the call-actor tool; the input is the quick-start input above, so it runs at the same low cost, and the tool returns the run's dataset items. Clients that want the schema first call fetch-actor-details with owlabee/pdf-to-json.
FAQ
Which extractor should I use? The default, hosted on the fast tier, fills almost any schema from invoices, forms, statements and short contracts for $0.02 plus $0.002 per page with nothing to set up; move to balanced or best for long contracts, messy scans converted with OCR, or fields that need reading comprehension ("the party that bears the cost of…"). Use byok when you already have an Anthropic key and want to control the model and the token spend yourself. Use rules for bulk first passes over well-labeled documents, for the daily reconciliation of invoices whose layout you know, and when a model is not allowed on the data: it is free of model costs, needs no key, and every value it returns is verbatim from the document.
Does this need proxies or an API key? No proxies. Documents are downloaded over plain HTTP from Apify's standard infrastructure, and there is no third-party site to scrape. An API key is needed only for byok mode; hosted and rules need nothing.
How is cost controlled? Cost = documents × the price of the mode and tier you chose, plus pages × the page price in hosted mode. Keep documents short (split large files), lower maxInputTokens in byok mode to cut your own token bill, and set the run's maximum total charge; the Actor checks it before every model call and stops cleanly when it is reached. Every model-mode item records tokensIn, tokensOut and modelCostUsdEstimate, and the run's SUMMARY record in the key-value store totals them.
How do I write the schema? Like any JSON Schema: { "type": "object", "properties": { "invoiceNumber": { "type": "string", "description": "The invoice number, usually top right" }, "total": { "type": "number", "description": "Grand total including tax" }, "lineItems": { "type": "array", "items": { "type": "object", "properties": { "description": { "type": "string" }, "quantity": { "type": "integer" }, "amount": { "type": "number" } } } } } }. Descriptions matter in every mode: the rules extractor matches them against labels, the model reads them as instructions. Use format: "date" to get YYYY-MM-DD, enum for fixed choices, nested objects for parties and addresses.
What does a scanned PDF produce? The converter finds no text layer, so the item is a NO_TEXT error with the scanned pages in needsOcrPages, charged at the rules price. Convert it with OCR using the PDF & DOCX to Markdown Converter (same account), write the Markdown to a key-value store, and pass kvs://<storeId>/<key> here; the extraction then works on the OCR text.
Can an AI agent use this? Yes; see "Use from AI agents (MCP)" above for the pin link and example prompts. Schedules and webhooks work the same way from the Console or the API.
What happens on errors? A document that cannot be downloaded, read or converted produces an error item with a clear code instead of failing the whole run; other documents are unaffected. A model call that fails falls back to the rules extraction (extractionMethod: "rules-fallback", reason in extractionWarning) and is charged the rules price, so a hosted run never fails because of the model. Only an unusable schema or a byok run with a missing or rejected key stops the run, with a clear message and before any further charge.
Can I try it for free? Yes. The Apify free plan comes with monthly platform credit, and the quick-start input above costs a few cents per run, so you can test it on your own inputs before paying anything.
How do I find this Actor again? Bookmark it on the Store page (the bookmark icon next to the title); bookmarked Actors are listed in your Console, and the Store page shows new versions as they ship.
Support
Questions, bugs or a source you'd like added? Open an issue on the Actor's Issues tab, or email jacob@owlabee.com.
Changelog
- 2026-11-07 Renamed from
owlabee/document-to-json-extractortoowlabee/pdf-to-jsonso the address matches what people search for. Input, output and pricing are unchanged; calls by Actor ID, saved tasks and schedules are unaffected. Name-based calls to the old address stop resolving: update API URLs and MCP tool lists. - 2026-10-27 README: comparison and free-alternatives tables, ready-to-run inputs, batch and pipeline section, this changelog.
- 2026-10-25 Pricing round: the rules-based document is now the primary event shown on the Store card (the cheapest tier), pluralized event titles, Store discount tiers for the Scale and Business plans; Console rows confirmed 2026-10-26.
- 2026-10-23 Time budgets: one download deadline per file that is not retried, a conversion cap per document, a 60-second model deadline with fallback to the rules extraction, charged error items for abandoned work, worst-case margin tests; Store title now leads with "PDF & Document to JSON", SEO fields, quick-start input and the MCP section added; default run memory lowered from the platform default.
- 2026-10-19 Model schema sent without union types so hosted and BYOK extraction handle schemas beyond 16 fields; document and webhook URLs that resolve to private, loopback or metadata addresses are rejected; roofing task examples (supplier quotes, roof takeoff).
- 2026-10-17 First release on the Store.
Legal
Use the data in compliance with applicable law and the rights you hold in the documents. The Actor processes only the documents you supply (public URLs, your own key-value stores or inline data); you are responsible for having the right to process them. In model modes the document text is sent to the Anthropic API solely to produce the extraction; in rules mode nothing leaves Apify. Extracted values are machine-generated and may contain errors; verify amounts, dates and legal terms against the source before acting on them. The Actor is not a consumer reporting agency and its output must not be used for employment, credit, insurance, or tenant screening decisions.


