
PDF to Markdown for RAG — DOCX, OCR & Chunks
Pricing
from $0.85 / 1,000 converted pages
PDF to Markdown for RAG — DOCX, OCR & Chunks
Convert PDF, DOCX, PPTX, XLSX, EPUB, HTML, text and image URLs into clean Markdown with headings, tables, links and metadata, plus optional RAG chunks, OCR in 21 languages, table CSVs and embedded images. No browser, no external API. Pay per page converted ($0.001).
Pricing
from $0.85 / 1,000 converted pages
Rating
0.0
(0)
Developer
Owlabee
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Features
Share
PDF to Markdown converter: give it links to PDF files and get back clean Markdown with the headings, lists, tables and links kept, ready to paste into ChatGPT or Claude, load into a knowledge base or feed a RAG pipeline. It is built for developers, AI and data teams, researchers and anyone who needs PDFs (and Word, PowerPoint, Excel, EPUB, HTML or scanned pages, read with OCR) turned into text an AI model can use.
Try it: press Start with the prefilled input and in about 5 seconds you get two PDFs converted to Markdown, including the 15-page "Attention Is All You Need" paper with its headings and 12 tables, for a few cents.
What you get
One record per document, with the full Markdown in markdown and the outline, tables and links alongside. A real record from the prefilled run (trimmed):
Turn on Create RAG chunks for embedding-ready chunks, OCR scanned pages and images for scans and photos, or Save Markdown files to the key-value store to download each document as a .md file. The full field list is under Output example.
What it does
PDF to Markdown converter for RAG: give it PDF, Office (DOCX, PPTX, XLSX, OpenDocument), EPUB, HTML, text, CSV or image URLs and get clean Markdown with headings, lists, tables, links and metadata, plus optional heading-aware chunks ready for embedding, OCR in 21 languages for scans and photos, table records with CSV files, and embedded images. It runs without a browser or any external API.
Point this Actor at document URLs and get back clean, LLM-ready Markdown: headings with the right levels, bullet and numbered lists, tables as GFM tables, links, page markers and document metadata (title, author, producer, creation date, page count). It reads PDF (text layout reconstructed from the PDF's own text layer — no browser, no external API), DOCX, PPTX (one page per slide, speaker notes kept), XLSX/XLSM (one table per sheet), OpenDocument (ODT, ODP, ODS), EPUB (chapters in reading order), HTML, Markdown, plain text and CSV/TSV, and images (PNG, JPEG, GIF, WebP, TIFF including multi-page, BMP, AVIF and HEIC iPhone photos, read with OCR), so agents and RAG pipelines can send it anything they find and always get the same shape back.
Optional extras: heading-aware chunking (recordType: chunk records with page range, heading path and a token estimate, ready to embed), OCR for scanned PDF pages and image inputs (bundled tesseract models for 21 languages, up to 3 per run, runs inside the Actor, no data leaves Apify), table records (recordType: table, one per table with its page, heading path and rows as objects, plus a CSV file per table; free), embedded image extraction (pictures inside PDF, DOCX, PPTX, OpenDocument and EPUB files saved to the key-value store and linked from the Markdown; $0.0005 per image), and writing every document's Markdown as a .md file into the run's key-value store.
One dataset record per document; results stream in as each file finishes and are available as JSON, CSV, Excel, via the API, webhooks or the Apify MCP server.
When you need the document as a filled JSON object rather than Markdown, pair it with PDF & Document to JSON Extractor (AI) — Invoices, Forms, which runs the same layout engine against a schema you define.
Why this Actor
| This Actor | Typical converter in this category | Do it yourself | |
|---|---|---|---|
| Inputs accepted | PDF, DOCX, PPTX, XLSX, OpenDocument, EPUB, HTML, Markdown, plain text, CSV and images by public URL, kvs:// reference or inline data: URL, many per run | PDF only, often one file or one upload per run | Whatever your script handles; every new format is more code to maintain |
| Modes | Text layer first; optional OCR for scanned pages and images; optional heading-aware RAG chunks; optional table records with CSV files; optional embedded image extraction; optional .md files written to the key-value store | A text dump, sometimes OCR; chunking is usually a separate tool | Several libraries glued together, maintained by you |
| Output fields | Markdown with real heading levels, GFM tables, lists, links and page markers, plus the heading outline, table and link counts, document metadata, warnings, and per-chunk page range and heading path | A plain-text or flat Markdown string | Whatever you parse out yourself |
| Pricing unit | Per converted page plus a small per-document charge; OCR pages and chunks are charged only when you turn them on | Per PDF whatever its length, or per page at a higher rate, sometimes a monthly plan | Your compute and your time |
| Needs an API key or proxies | No key, no proxies, no external conversion service | Often a third-party API behind the scenes | Depends on the library |
| Agent/MCP ready | Yes: pin link, fetch-actor-details, pay per run | Sometimes | You write the tool wrapper |
| Limits | Files up to 50 MB, 10 minutes of conversion per file, OCR in 21 bundled languages (3 per run), up to 500 embedded images per document; all written down in "Limits and fair use" | Page or size caps that are often undocumented | Whatever your machine allows |
- One record shape for every input type, so a pipeline that receives PDFs today and DOCX tomorrow needs no branching.
- Charged for the work done, page by page, so a two-page letter costs a fraction of a 200-page manual instead of the same flat fee.
- Nothing leaves Apify: PDF parsing, DOCX conversion and OCR all run inside the Actor.
- Chunks carry
startPage,endPageandheadingPath, so citations and filters work without re-parsing the document. - A bad URL or a corrupt file becomes a charged error item with a code, never a failed run that loses the other documents.
Free alternatives vs this Actor
| Tables kept | OCR | Batch of URLs | Structured output | Runs on a schedule or from an agent | Cost unit | |
|---|---|---|---|---|---|---|
| Copy-paste from a PDF viewer | No, columns collapse into lines | No | No, one file at a time | No | No | Your time per document |
| Open-source CLI tools run locally | Partly, depends on the tool | Only with a separate OCR install | Yes, with a shell loop you write | Plain text or basic Markdown | Only with your own scheduler and server | Your machine and maintenance hours |
| Generic LLM chat upload | Usually, but values can be paraphrased | Yes, the model reads the page image | No, a few files per conversation | Free text unless you prompt for it, not guaranteed | No | A chat subscription, one conversation at a time |
| This Actor | Yes, GFM tables rebuilt from column alignment | Yes, in-process OCR in 21 languages when ocr is on, for scans and image inputs | Yes, many URLs per run | One dataset record per document and per chunk with the same fields every time | Yes: Console schedules, API, webhooks, MCP | Per converted page plus a small per-document charge |
How to use
- Enter Document URLs — public
https://links to PDF/DOCX/HTML/text files,kvs://<storeId>/<key>references to files you uploaded to an Apify key-value store (kvs://default/<key>for the run's own store), ordata:URLs with inline content. - Optionally turn on Create RAG chunks (set chunk size and overlap), OCR scanned pages, or Save Markdown files to the key-value store.
- Click Start. Each document appears in the dataset as soon as it is converted; open the
markdownfield or download the.mdfiles.
Quick start input
The same input the Store runs in its daily automated test, so it is cheap and always available; paste it into the JSON tab of the input form or send it as the body of an API or MCP call:
Ready-to-run inputs
Replace the example URLs with your own; each block validates against the input schema.
A scanned PDF with OCR on, saved as a .md file
A DOCX to Markdown
A RAG chunking run over several documents
Input
| Field | Type | Required | Description |
|---|---|---|---|
urls | string[] | yes | Documents to convert: http(s)://, kvs://<storeId>/<key> or data: URLs, one per entry |
chunk | boolean | no | Also emit heading-aware chunk records (default false) |
chunkTokens | integer | no | Target chunk size in estimated tokens (default 800, 100–8000) |
chunkOverlapTokens | integer | no | Overlap repeated from the previous chunk (default 80, capped at half the chunk size) |
ocr | boolean | no | Run OCR on PDF pages without extractable text and on image inputs (default false) |
ocrLanguages | string[] | no | Tesseract codes OCR reads, up to 3 (default ["eng"]; also spa, fra, deu, por, ita, nld, pol, rus, ukr, tur, ara, hin, chi_sim, chi_tra, jpn, kor, vie, ind, tha, heb) |
extractTables | boolean | no | Also emit one table record per table and a CSV file per table in the key-value store (default false, free) |
extractImages | boolean | no | Save embedded images to the key-value store, list them in images and link them from the Markdown (default false, $0.0005 per image) |
maxImagesPerDocument | integer | no | Stop saving images after this many per document (default 50, 1–500) |
saveToKeyValueStore | boolean | no | Write <slug>.md into the default key-value store and record kvsKey (default false) |
pageBreaks | boolean | no | Keep <!-- page N --> markers between PDF pages (default true) |
maxFileSizeMb | integer | no | Reject larger files with a TOO_LARGE error item (default 25, max 50). Image inputs (PNG, JPEG, TIFF, HEIC and the rest) are capped at 10 MB whatever this says |
downloadTimeoutSecs | integer | no | Per-file download timeout (default 20, 5–120) |
webhookUrl | string | no | POST target for the run summary |
Output example
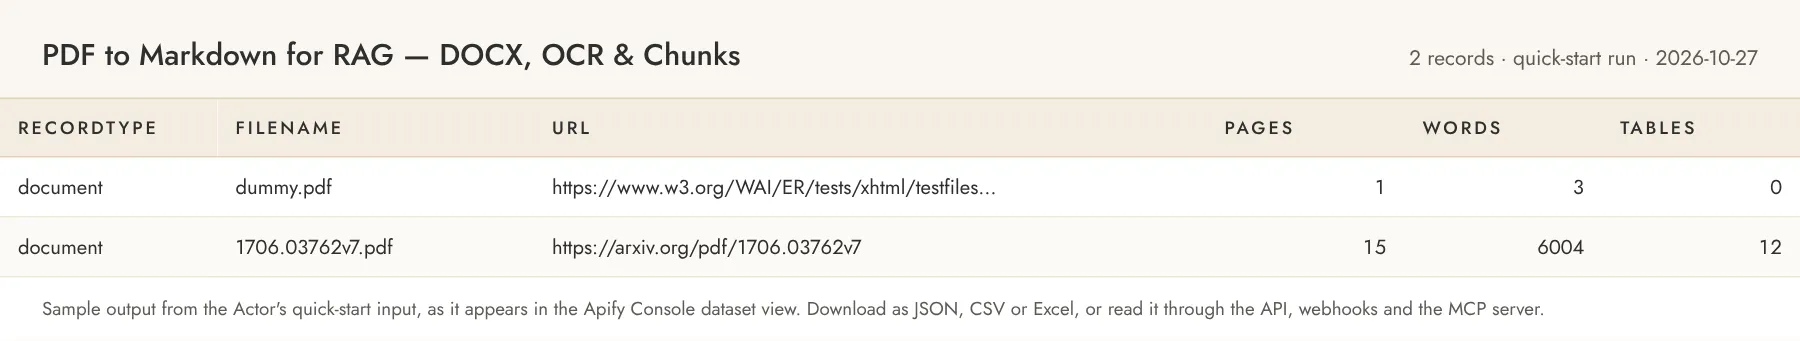
Document record (recordType: "document"), one per input URL:
Chunk record (recordType: "chunk"), only when chunk is on:
Table record (recordType: "table"), only when extractTables is on. The same table is written as a CSV file to the run's default key-value store (csvKey, csvUrl); the record keeps up to 5,000 rows (rowsTruncated says when the CSV has more):
With extractImages on, the document record gets an images list (key, url, mimeType, bytes, page, width, height) and the Markdown links each image after its page's text, for example .
Error items look like { "recordType": "document", "url": "...", "error": "NOT_FOUND", "errorMessage": "HTTP 404 for ..." } with codes INVALID_URL, DOWNLOAD_FAILED, TIMEOUT, TOO_LARGE, NOT_FOUND, UNSUPPORTED_TYPE, CORRUPT_FILE, PASSWORD_PROTECTED or PROCESSING_FAILED. They are charged as one page, because the work to discover the problem was done.
If the output saves you time, a review on the Store page helps other buyers find this Actor; the Store invites you to leave one after you have run it a few times.
Batch and pipeline use
- URLs from another run. Any dataset whose items carry a document link can feed this Actor: read it with
GET https://api.apify.com/v2/datasets/<datasetId>/items?format=json&fields=url, collect the links, and send them asurlsin a new run (POST https://api.apify.com/v2/acts/owlabee~pdf-to-markdown/runs). The same works from code with the Apify client:client.actor('owlabee/pdf-to-markdown').call({ urls }). - Files you hold. Upload them to a key-value store (
PUT https://api.apify.com/v2/key-value-stores/<storeId>/records/<key>with the file's content type) and reference them askvs://<storeId>/<key>; the Actor reads your stores without any public link. - Reading results.
GET https://api.apify.com/v2/actor-runs/<runId>/dataset/items?format=jsonreturns the records (format=csvfor a spreadsheet); therecordTypefield separates document, chunk and table records. WithsaveToKeyValueStoreon, each document's Markdown is also a file atGET https://api.apify.com/v2/key-value-stores/<storeId>/records/<kvsKey>. TheSUMMARYrecord of the run's key-value store holds the counts (documents, pages, OCR pages, chunks, tables, images, errors), the truncated units and the charges per event; the latest run is reachable without its id atGET https://api.apify.com/v2/acts/owlabee~pdf-to-markdown/runs/last/dataset/items. - Run-end notification.
webhookUrlreceives one POST withactor,runIdand that same summary when the run finishes; for per-run events (succeeded, failed, timed out) use the Actor webhooks on the Integrations tab of the Actor page. - Chaining. Turn on
saveToKeyValueStore, then pass thekvs://references to the PDF & Document to JSON Extractor to fill a schema from the Markdown, including OCR text that the extractor cannot produce on its own.
Pricing
Pay per event. You only pay for what the Actor produces; set a maximum cost per run in the run options to cap spend.
| Event | Price | Notes |
|---|---|---|
| Converted page | $0.001 | Per page of every document record (PDF pages; slides; one per image or TIFF page; DOCX and ODT declared page count; spreadsheets, EPUB, HTML, text and CSV ≈ 1 page per 3,000 characters). Error items count as 1 page |
| OCR page | $0.005 | Per scanned page or image page recognized, only with ocr: true, on top of the page price |
| Chunk | $0.0002 | Per chunk record, only with chunk: true |
| Extracted embedded image | $0.0005 | Per embedded image saved to the key-value store, only with extractImages: true; an image reused on several pages is saved and charged once |
| Table record | free | recordType: table records and their CSV files, only with extractTables: true |
| Processed document | $0.004 | Once per input document the run attempts (URL, uploaded file or key-value store record), on top of the page events, including documents that fail to download, time out or cannot be parsed |
| Actor start | $0.00005 | Apify platform event |
Examples: a 30-page PDF ≈ $0.03 + 1 document $0.004 ≈ $0.034; 1,000 pages in 10 documents ≈ $1.00 + $0.04 ≈ $1.04; chunking those 1,000 pages into ~1,200 chunks adds ≈ $0.24; OCR on a 100-page scan adds $0.50; a phone photo of a receipt with OCR is $0.001 + $0.005 + $0.004 = $0.010; saving the 40 pictures of a slide deck adds $0.02.
Store pricing discounts: users on the Scale plan (Silver) pay 10% less per event, Business (Gold) 15–20% less.
Limits and fair use
- Files up to 25 MB by default (
maxFileSizeMb, max 50 MB); image inputs up to 10 MB each (larger images return aTOO_LARGEerror item, stopped before or early in the download; a scan inside a PDF keeps the file limit); 20 s download timeout by default; 10 minutes of processing per file, after which the pages converted so far are returned with aPROCESSING_TIMEOUTwarning. - Two documents are processed concurrently; a text-based PDF converts at roughly 15 pages per second (dense publications with many tables) to 200 (simple pages), OCR at 2–5 seconds per page.
- Time budget. Each document gets its download time (
downloadTimeoutSecs, a single deadline for the whole download that is not retried) plus 10 minutes of conversion, text and OCR passes together; page 1 is always converted. When the conversion time runs out, the pages converted so far are returned and charged, with aPROCESSING_TIMEOUTwarning. A document that cannot be downloaded in time returns aTIMEOUTerror item charged as one page, and the Actor never retries a blocked or failing URL. Chunking (chunk: true) stops after 5 minutes per document; the document record is already saved and the shortfall is listed undertruncatedin theSUMMARYrecord (TIME_BUDGET). - Memory is set to 512–2048 MB (higher than our usual 256–1024 MB default) because pdf.js keeps page content and fonts in memory and OCR renders pages to bitmaps; 50 MB scans with
ocr: trueshould run with 2048 MB. Default run memory is 512 MB. - Layout reconstruction is heuristic: headings come from font-size and bold clusters, tables from column alignment, two-column pages are read column by column, running headers/footers and page numbers are stripped. Complex forms, rotated text, equations and multi-line table cells are best effort. Table records come from the tables found in the Markdown (PDF column alignment, DOCX/HTML/slide/OpenDocument tables, one per spreadsheet sheet, CSV inputs); ruled-line table detection is not built. At most 5 table records per charged page plus 5, 500 per document. Embedded images smaller than 32 px are skipped; vector drawings and charts that are not raster images are not extracted.
- OCR reads the languages in
ocrLanguages(21 bundled tessdata_fast models, at most 3 per run; English by default) and runs only whenocris on, so scanned documents and images cost nothing extra until you ask. Image inputs withocroff return their pages inneedsOcrPagesand no text. A dense scanned page takes about 4.5 s; measured peak memory for OCR of a 16 MB scan is about 550 MB, so run OCR jobs at 1024 MB. - Spreadsheets: up to 20,000 rows and 200 columns per sheet, 1 million cells per workbook. ZIP-based files (Office, OpenDocument, EPUB) are capped at 256 MB expanded. Legacy DOC/XLS/PPT, RTF, email (EML/MSG) and ZIP archives are not supported.
- HEIC photos are decoded with libheif (LGPL-3.0) running as WebAssembly inside the run; see THIRD_PARTY_LICENSES.
- Only publicly reachable URLs and your own key-value stores are accessed. No proxies, no login, no third-party APIs. The Actor contacts only the URLs you give it and the optional webhook.
Related Actors
Other pay-per-event Actors from the same account, all limited-permission and agent-friendly:
- Website Change Monitor — Sitemap Monitor & Page Diff — find new or changed pages on a site, then convert the documents they link to.
- Podcast RSS Scraper — Episodes, Transcripts & Apple Podcasts — episode metadata and transcript text from podcast feeds, ready for the same RAG pipeline.
- Grants.gov API & SAM.gov Scraper — Federal Grants Feed — grant and contract opportunities whose attached PDFs this Actor can turn into Markdown.
Guide and code examples
- Guide: PDF to Markdown for RAG: Headings, Tables, Chunks and OCR, covering the source, its fields and limits, and curl and MCP examples.
- Runnable examples (curl, Python, Node.js and an MCP config): owlabee/owlabee on GitHub.
Use from AI agents (MCP)
Pin this Actor in the Apify MCP server with one link: https://mcp.apify.com?tools=owlabee/pdf-to-markdown, or let the agent find it with the search-actors tool. It is pay-per-event with limited permissions, so agents can discover it, inspect the input schema with fetch-actor-details and pay per run through agentic payments. Prompts that map directly onto the input:
- "Convert https://arxiv.org/pdf/1706.03762v7 to Markdown with the PDF to Markdown Converter and give me the heading outline plus the full text of the 'Model Architecture' section."
- "Take these three supplier contracts (PDF and DOCX links) and chunk them into 800-token pieces with 80-token overlap so I can load them into my vector store — include page numbers for each chunk."
- "This invoice PDF is a scan with no text layer. Run it through the converter with OCR on and tell me the total amount due and the payment terms."
The agent receives the same dataset records shown in the output example above.
Copy this block to call the Actor through the Apify MCP server with the call-actor tool; the input is the quick-start input above, so it runs at the same low cost, and the tool returns the run's dataset items. Clients that want the schema first call fetch-actor-details with owlabee/pdf-to-markdown.
FAQ
Does this need proxies, a browser or an API key? No. It downloads files with plain HTTPS and converts them in-process with pdf.js, mammoth, turndown and tesseract.js. Nothing is sent to an external conversion service.
Which files can I send? PDF, DOCX, PPTX, XLSX/XLSM, ODT, ODP, ODS, EPUB, HTML, Markdown, plain text, CSV/TSV and images (PNG, JPEG, GIF, WebP, TIFF, BMP, AVIF, HEIC). The type is detected from the file's bytes, so a URL without an extension works. Images and scans need ocr: true to produce text.
How is cost controlled? Every page is charged as it is converted and every chunk as it is saved; the Actor stops cleanly when the run's maximum total charge is reached. maxFileSizeMb and the 10-minute per-file cap bound the work a single URL can cause. Scanned pages are only OCR'd (and billed at $0.005) when ocr is on.
What happens with scanned PDFs? Pages with no extractable text are listed in needsOcrPages and marked <!-- page N: no extractable text --> in the Markdown. Turn on ocr to have them recognised; the result is marked <!-- page N: ocr --> and the pages appear in ocrPages.
Can an AI agent use this? Yes; see "Use from AI agents (MCP)" above for the pin link and example prompts. Schedules and webhooks work the same way from the Console or the API.
How do chunks reference pages? Each chunk carries startPage/endPage (from the <!-- page N --> markers) and headingPath, the heading hierarchy the chunk's content lives under, so citations and filters work without re-parsing the document.
Why is a DOCX or HTML file charged as N pages? DOCX files declare their last-saved page count (docProps/app.xml); when that is missing, and for HTML/Markdown/text, pages are estimated at one per ~3,000 characters (pagesEstimated: true).
What if the URL is not a document? You get an error item (UNSUPPORTED_TYPE, NOT_FOUND, ...) instead of a failed run, charged as a single page.
Can I try it for free? Yes. The Apify free plan comes with monthly platform credit, and the quick-start input above costs a few cents per run, so you can test it on your own inputs before paying anything.
How do I find this Actor again? Bookmark it on the Store page (the bookmark icon next to the title); bookmarked Actors are listed in your Console, and the Store page shows new versions as they ship.
Support
Questions, bugs or a source you'd like added? Open an issue on the Actor's Issues tab, or email jacob@owlabee.com.
Changelog
- 2026-11-09 README opens with "PDF to Markdown", who it is for, a trimmed real record and a one-click "Try it" line; Store description and SEO title and description now lead with "PDF to Markdown". No input, output or price change.
- 2026-11-09 More inputs and outputs (image inputs capped at 10 MB each), all opt-in or additive, same defaults and prices for existing inputs: PPTX, XLSX/XLSM, OpenDocument (ODT, ODP, ODS), EPUB, CSV/TSV and image inputs (PNG, JPEG, GIF, WebP, TIFF, BMP, AVIF, HEIC); OCR in 21 bundled languages (
ocrLanguages);extractTablestable records with a CSV file per table (free);extractImagessaves embedded images to the key-value store (newimage-extractedevent, $0.0005 per image). - 2026-10-27 README: comparison and free-alternatives tables, ready-to-run inputs, batch and pipeline section, this changelog.
- 2026-10-25 Pricing round: a per-document processed event added next to the per-page event so each attempted document carries its own small charge, pluralized event titles, Store discount tiers for the Scale and Business plans; Console rows confirmed 2026-10-26.
- 2026-10-23 Time budgets per document, one download deadline per file that is not retried, pages converted before a timeout kept and returned, charged error items for abandoned work; Store title now names DOCX, OCR and RAG chunks, SEO fields, quick-start input and the MCP section added; default run memory lowered from the platform default.
- 2026-10-16 First release on the Store.
Legal
Only convert documents you are allowed to access and process. Use the output in compliance with the source's terms and applicable law. This Actor is not a consumer reporting agency and its output must not be used for employment, credit, insurance, or tenant screening decisions.


