
LinkedIn Profile Scraper
Pricing
from $3.89 / 1,000 results
LinkedIn Profile Scraper
LinkedIn Profile Scraper — Extract LinkedIn profile data including names, job titles, work experience, education, skills, locations, company details, profile URLs, and professional summaries. Useful for lead generation, recruitment, prospecting, market research, and professional networking.
Pricing
from $3.89 / 1,000 results
Rating
0.0
(0)
Developer

Social Data API
Maintained by CommunityActor stats
0
Bookmarked
6
Total users
3
Monthly active users
a day ago
Last modified
Categories
Share
LinkedIn Profile Scraper — experience, education, posts, followers
LinkedIn Profile Scraper extracts public LinkedIn profile data from profile URLs: name, photo, location, followers, connections, about text, experience, education, recent posts, activity, articles, publications, projects, recommendations and similar profiles. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed a lead enrichment pipeline. No LinkedIn account or cookies needed: paste profile links and turn each one into one row. Start with a handful of links, then scale to your full candidate or lead list in one run.
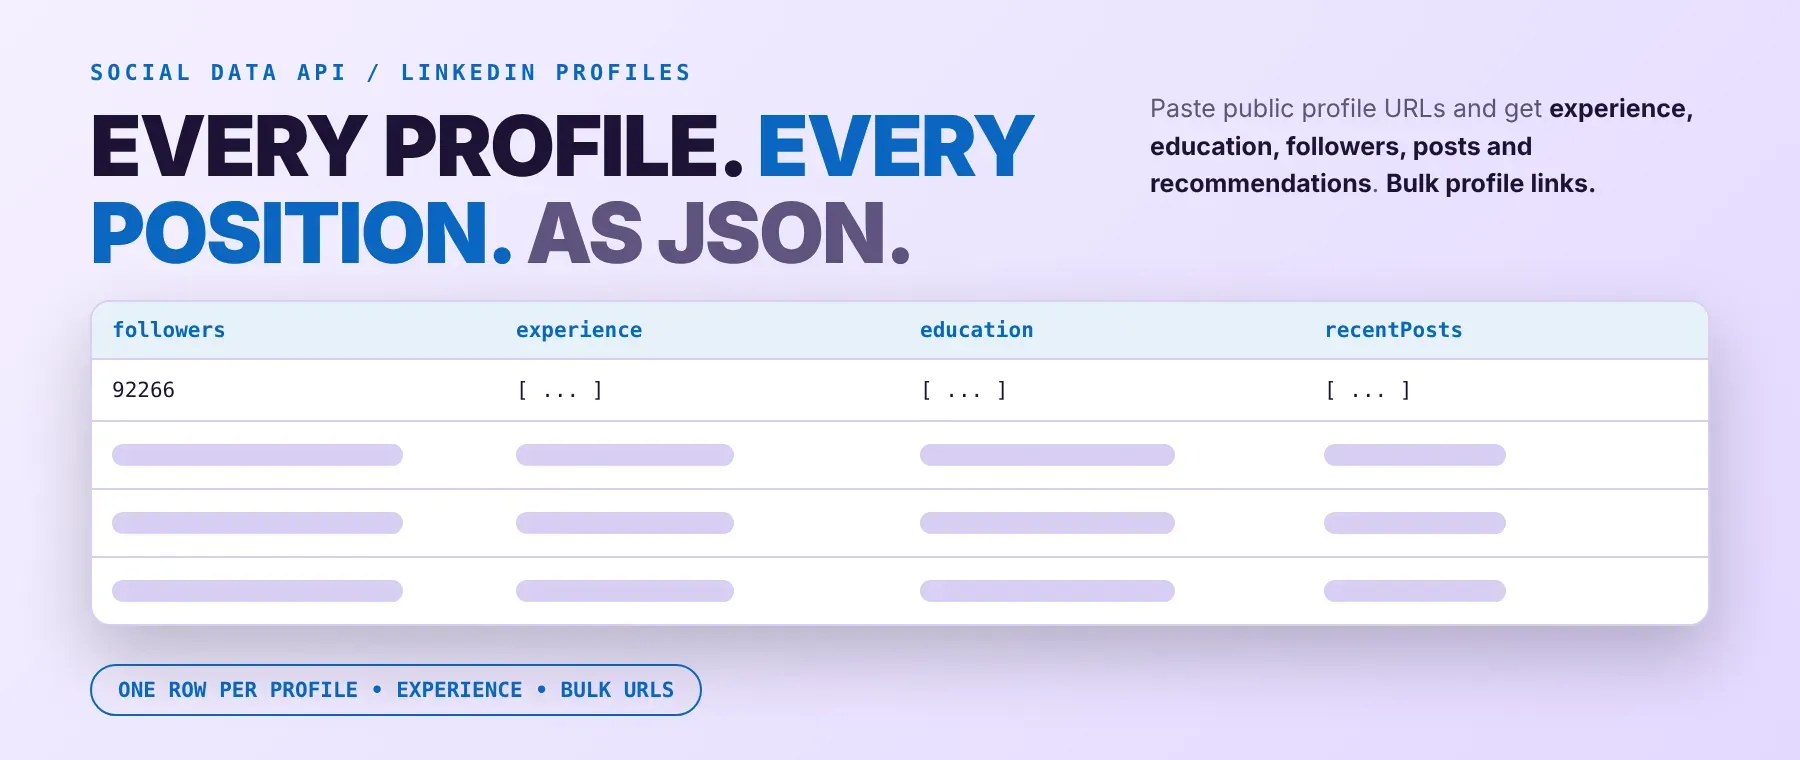
What data can I extract with LinkedIn Profile Scraper?
Using this LinkedIn Profile API, you can extract LinkedIn profile data covering:
| 👤 Full name | 🖼️ Profile photo | 📍 Location | 👥 Follower count |
|---|---|---|---|
| 🤝 Connections (e.g. "500+") | 📝 About text | 💼 Experience (company, page, location) | 🎓 Education (school, page, years) |
| 💬 Recent posts (title, link, image) | 📣 Activity (posts, shares, likes) | 📰 Articles (headline, date, cover image) | 📚 Publications (name, link) |
| 🧩 Projects (name, dates, contributors) | 🗣️ Recommendations (name, link, text) | 👫 People also viewed | ✅ Scraped successfully |
| 🔶 Partial profile flag |
How to use LinkedIn Profile Scraper
It is for anyone who needs to scrape a LinkedIn profile from a list of links and get the same structured data back for every one of them, in one run.
Copy to your AI assistant:
LinkedIn Profile Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Point your AI assistant at Apify's MCP server with this Actor already loaded as a tool, and it can run it on its own. Ask it for someone's LinkedIn profile data and it picks the right tool, runs it with the profile URL, and hands back clean JSON you can use immediately in the conversation. No glue code, no scraping logic in your prompts.
Step by step
- Create a free Apify account.
- Open LinkedIn Profile Scraper in the Apify Store.
- Enter the LinkedIn profile URL(s).
- Click Start (or send your API request).
- Download or stream your results in JSON, CSV or Excel.
How to scale LinkedIn Profile Scraper to bulk
Add more links to the same urls list — as a LinkedIn profile bulk scraper it takes the whole list in one run, scrapes three profiles at a time, and saves each row the moment its profile is done. Duplicate links in the list are scraped once. For a candidate pipeline or a lead list that grows over time, paste the new links into a fresh run; already-known profiles cost nothing extra to skip on your side since every run returns the full data again for whatever you send it.
✨ Features
LinkedIn Profile Scraper fetches clean, structured profiles from LinkedIn and works as a LinkedIn profile data extractor for recruiting shortlists, lead enrichment, sales research and AI agent context. It extracts, per profile:
- Full name – the name shown on the profile
- Photo – the profile photo URL
- Location – the location text shown on the profile
- Followers – the follower count
- Connections – the connections count the way LinkedIn shows it, e.g. "500+"
- About – the About text
- Experience – current and past jobs with the company's LinkedIn page
- Education – schools with the school's LinkedIn page and years
⚡ Rows are saved to the dataset as soon as each profile is done, turning a LinkedIn profile to JSON in seconds while the run is still going.
Use cases 💡
- Recruiter — pull experience and education for every shortlisted candidate link.
- Sales rep — read a prospect's about text and recent posts before a call.
- Lead enrichment — add location, followers and current company to a contact list.
- Market researcher — compare where people at a company worked and studied.
- AI agent builder — feed one profile's JSON into a RAG pipeline or agent context.
Building an AI agent? Connect it over MCP and let it call the actor on its own.
Why choose this actor?
- Three profiles scraped in seconds, not minutes. A recorded run saved three LinkedIn profiles in 3.6, 5.3 and 6.5 seconds each, over a direct connection with no proxy.
- One profile, dozens of data points. Working as a LinkedIn profile experience and education scraper too, a recorded profile came back with 10 experience entries, 3 schools, 6 recent posts, 7 articles, 2 projects, 2 recommendations and 10 similar profiles.
- Three optional sections, three backup sources. People also viewed, projects and recommendations can each be turned off, and a profile LinkedIn keeps blocking falls back to your own scraping API, the latest archived copy, or a freshly archived copy, in that order.
⬇️ Input
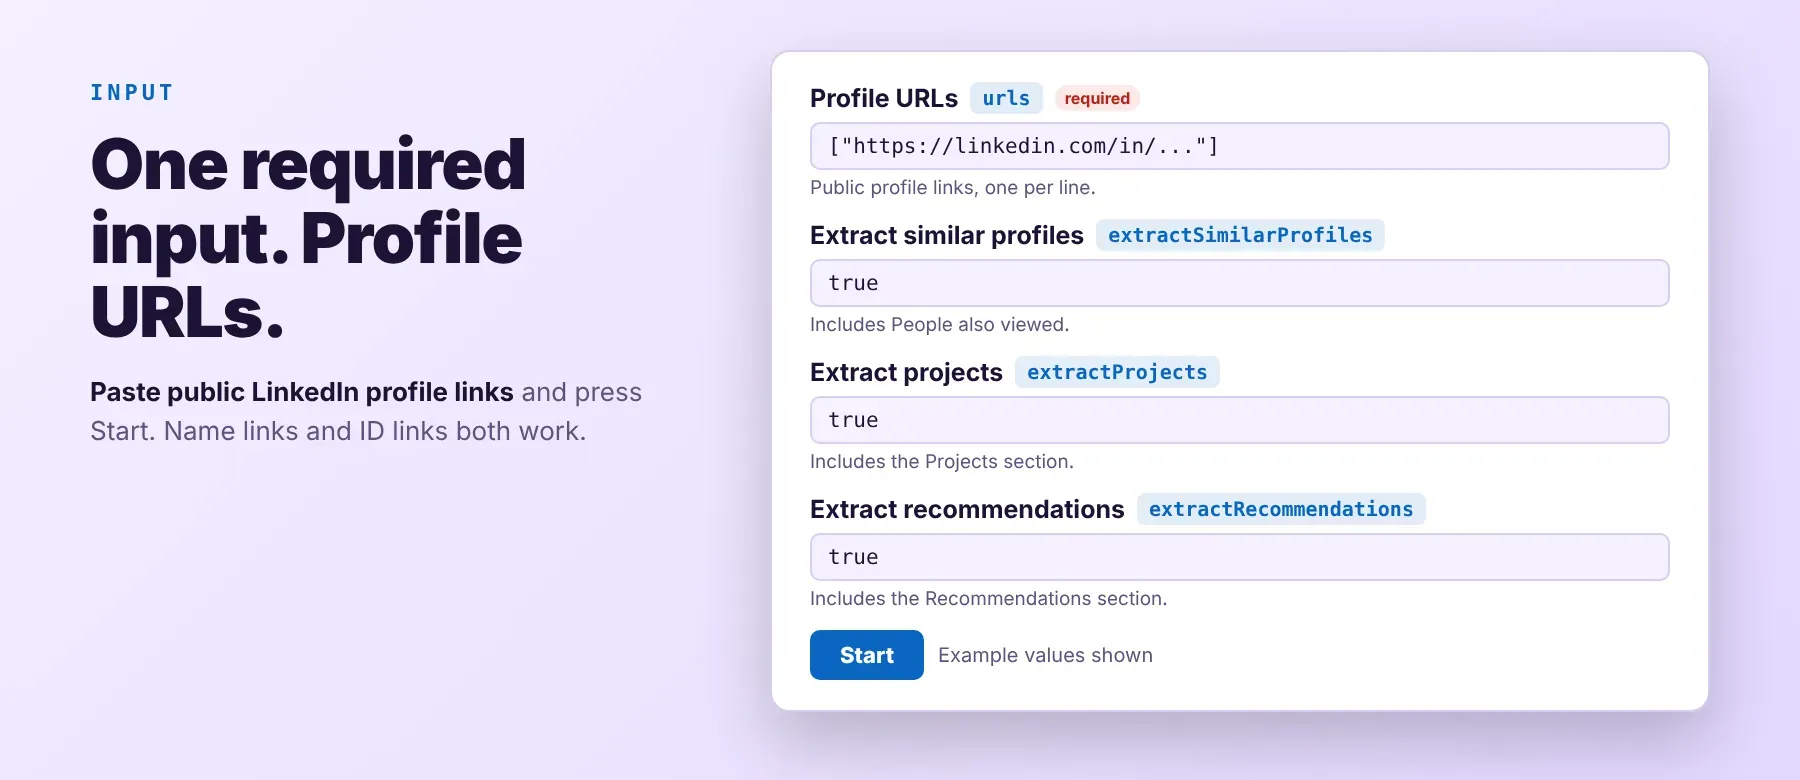
It works as a LinkedIn profile URL scraper: give it a list of public LinkedIn profile URLs, and urls is the only field you need to fill in.
| Parameter | Required | Type | Description | Example value |
|---|---|---|---|---|
urls | Yes | Array | Public profile links, one per line. Both name links (/in/handle) and ID links (/in/ACoAA...) work; duplicates are scraped once. Free plan: up to 20 profiles per run (all profile URLs together) and 200 per month; paid plans have no limit. | ["https://www.linkedin.com/in/timbakke/"] |
extractSimilarProfiles | No | Boolean | Include "People also viewed" (default on) | true |
extractProjects | No | Boolean | Include Projects (default on) | true |
extractRecommendations | No | Boolean | Include Recommendations (default on) | true |
customFetcherUrlTemplate | No | String (secret) | Your own scraping API URL with {url} where the profile URL goes; used only when LinkedIn blocks a profile | "https://api.example.com/?api_key=YOUR_KEY&url={url}" |
enableWaybackFallback | No | Boolean | Use the latest archived copy when LinkedIn blocks a profile (default on) | true |
enableWaybackSaveFallback | No | Boolean | Create a fresh archived copy when none exists; slow, up to 90 seconds per profile (default on) | true |
maxRetries | No | Integer | Quick retry rounds per blocked page, 1 to 15 (default 5) | 5 |
requestTimeoutSecs | No | Integer | Seconds one request may take, 5 to 180 (default 30) | 30 |
proxyConfiguration | No | Object | Apify Proxy settings (default: residential) | {"useApifyProxy": true, "apifyProxyGroups": ["RESIDENTIAL"]} |
A run without any LinkedIn profile URL stops right away with a clear status message.
Free plan limits
Users on the Apify free plan can fetch up to 20 profiles per run (all profile URLs together) and 200 profiles per month. When the limit is reached, the run finishes successfully with a status message explaining the limit. Upgrade to any paid Apify plan to remove these limits.
Example input
⬆️ Output
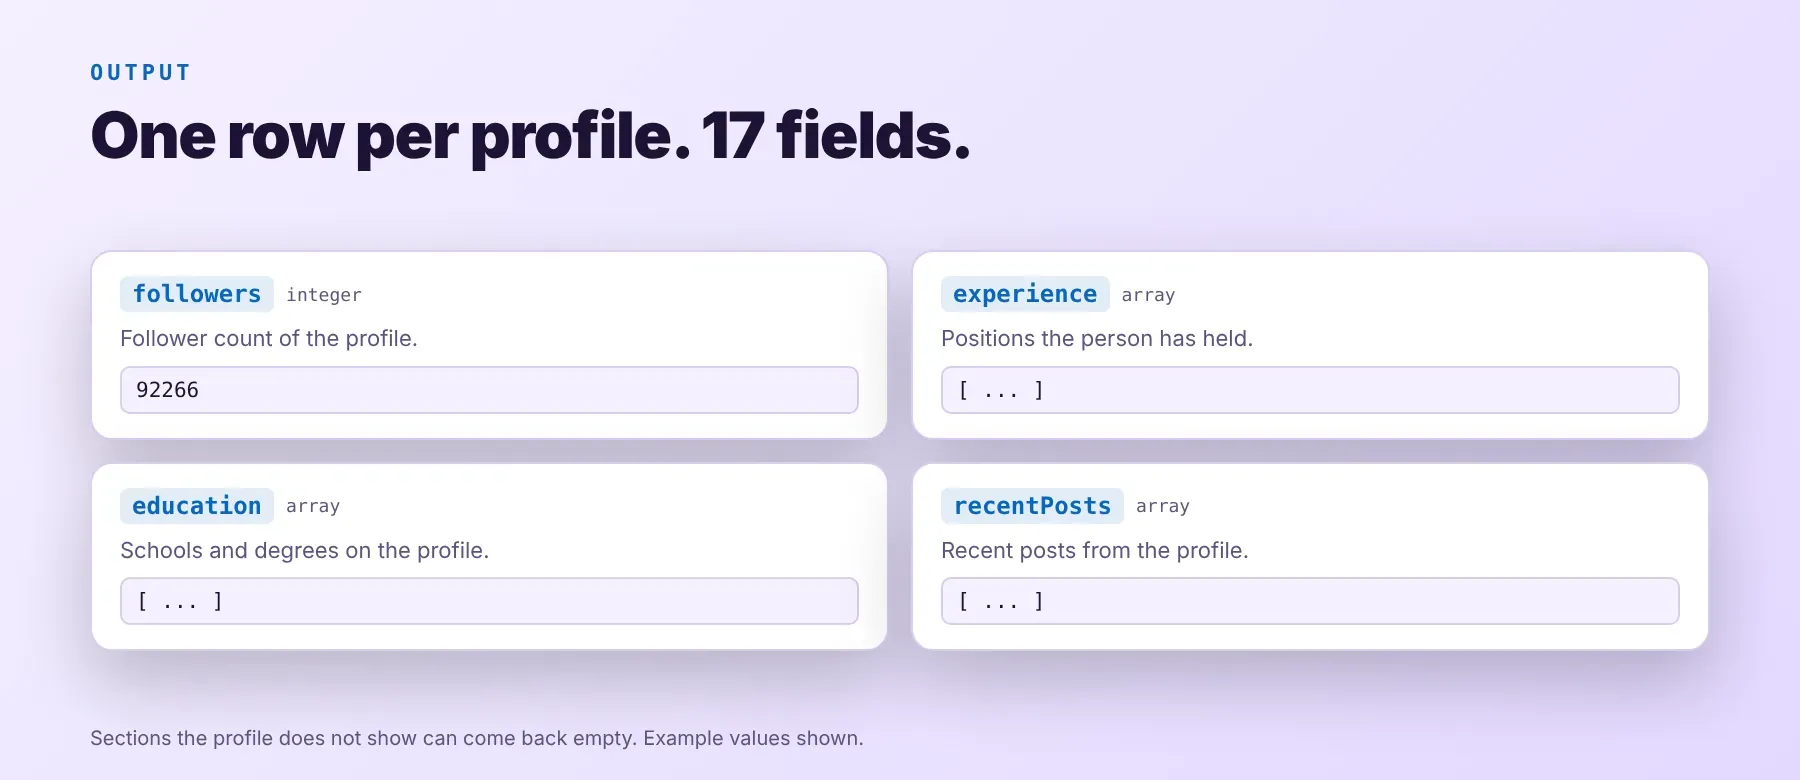
Every LinkedIn profile URL becomes one typed, normalized JSON item with the same field set on every run; a profile that could not be scraped gets the same fields with only the URL and a plain-word reason filled in, and that row is not charged. Export the results as JSON (default), CSV or Excel.
Example output
Rows from this real run, with each list shortened to its first two entries and long texts cut (...):
How does it work?
LinkedIn Profile Scraper is a LinkedIn public profile scraper: it reads the same public profile pages any logged-out visitor can open, so no LinkedIn account is needed. Plain HTTP requests fetch each page; there is no browser to launch. Requests go through a rotating Apify proxy with a fresh connection each time, and the run switches to a residential proxy as soon as LinkedIn blocks a request. Only publicly visible data is returned — nothing behind a login wall. When a profile stays blocked after every retry, and you've turned the option on, it can also be read from your own scraping API or a public web archive copy, never for a profile that is genuinely private or missing. The output schema is normalized and stays the same shape even when LinkedIn changes its pages, so your downstream code never has to change.
How do you integrate LinkedIn Profile Scraper into your stack?
It works with what you already use: a REST API from any language, MCP for AI agents, and no-code automation tools.
MCP integration for AI agents
Think of it as a LinkedIn profile API you can also hand straight to an agent. Register Apify's MCP server once with this Actor as a tool, and any agent that supports MCP can call it on its own, passing in profile links and reading the JSON straight back without you writing any request code.
This registers Apify's MCP server as a tool your agent can call directly, compatible with Claude Code, Cursor and Windsurf.
No-code tools (n8n, Make, LangChain)
In n8n, use the Apify node's "Run an Actor" operation, or the HTTP Request node pointed at the run-sync endpoint with your token. In Make, use the Apify app's "Run an Actor" module followed by "Get Dataset Items". In LangChain, read the run's dataset with ApifyDatasetLoader once the run has finished.
Is it legal to scrape LinkedIn profile data?
Collecting publicly available data is generally lawful, although LinkedIn's User Agreement restricts automated access. LinkedIn Profile Scraper returns only publicly available data — what any visitor sees without logging in. Profile data is personal data under GDPR and similar laws, so storing and using it must comply with local data-protection rules. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does LinkedIn Profile Scraper return?
The top fields are full name, photo, location, follower count and about text, alongside experience, education, posts and more. See the data fields section for the full list.
Does LinkedIn Profile Scraper require a LinkedIn account or login?
No. Only public profile data is extracted. No credentials needed.
How fast does LinkedIn Profile Scraper run?
A recorded run saved three real LinkedIn profiles in 3.6, 5.3 and 6.5 seconds each, over a direct connection with no proxy. Every run reads the live profile page, never a cached copy.
What happens if a profile is private or doesn't exist?
The row still comes back, with the profile URL and a plain reason in error, and every other field empty. That row is not charged.
Can I scrape multiple LinkedIn profiles at once?
Yes. Put as many links as you want in the urls list and it works through all of them in one run as a LinkedIn profile bulk scraper, three at a time.
Does LinkedIn Profile Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — it is available as an MCP tool. Run claude mcp add --transport http apify "https://mcp.apify.com?tools=socialdataapi/linkedin-profile-scraper" to register Apify's MCP server with this Actor as a tool in Claude Code, Cursor or Windsurf. Any agent that can call an HTTP endpoint can use the REST API directly.
Does LinkedIn Profile Scraper return data in a format LLMs can use directly?
Yes. Every response is typed, normalized JSON with consistent field names. No HTML parsing, no selectors. Pass the response straight to an LLM, index it into a vector store, or feed it to an agent tool — no transformation step needed.
What happens when LinkedIn changes its layout or updates its anti-bot system?
The actor is maintained, and when LinkedIn changes its pages the actor is updated so your calls keep returning the same JSON schema with no changes on your end. No specific update turnaround is guaranteed.
Can I use LinkedIn Profile Scraper without managing proxies or browser infrastructure?
Yes. Proxy rotation and the switch to a residential connection when LinkedIn blocks a request run on the actor's side. You send one request and get structured JSON back — no proxy accounts, no browser setup, no maintenance.
Which LinkedIn profile fields work best for AI training data and RAG indexing?
For RAG indexing: the about text, experience and education entries give rich, readable context. For training data: the follower count, connections and the success and partial flags are the most structurally consistent fields across profiles. All fields are typed primitives or arrays of objects — no normalization needed.
Your feedback
Found a bug or a profile that didn't come out right? Open an issue in this Actor's Issues tab on Apify Console. Every report is read and feeds into the next fix.


