
YouTube Community Posts Scraper
Pricing
from $2.99 / 1,000 results
YouTube Community Posts Scraper
YouTube Community Posts Scraper — scrape YouTube Community posts, including post text, images, videos, engagement metrics, timestamps, and post URLs. Extract valuable data from channels for research, monitoring, and content analysis.
Pricing
from $2.99 / 1,000 results
Rating
0.0
(0)
Developer

Social Data API
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
5 days ago
Last modified
Categories
Share
YouTube Community Posts Scraper — Text, Polls, Images and Likes
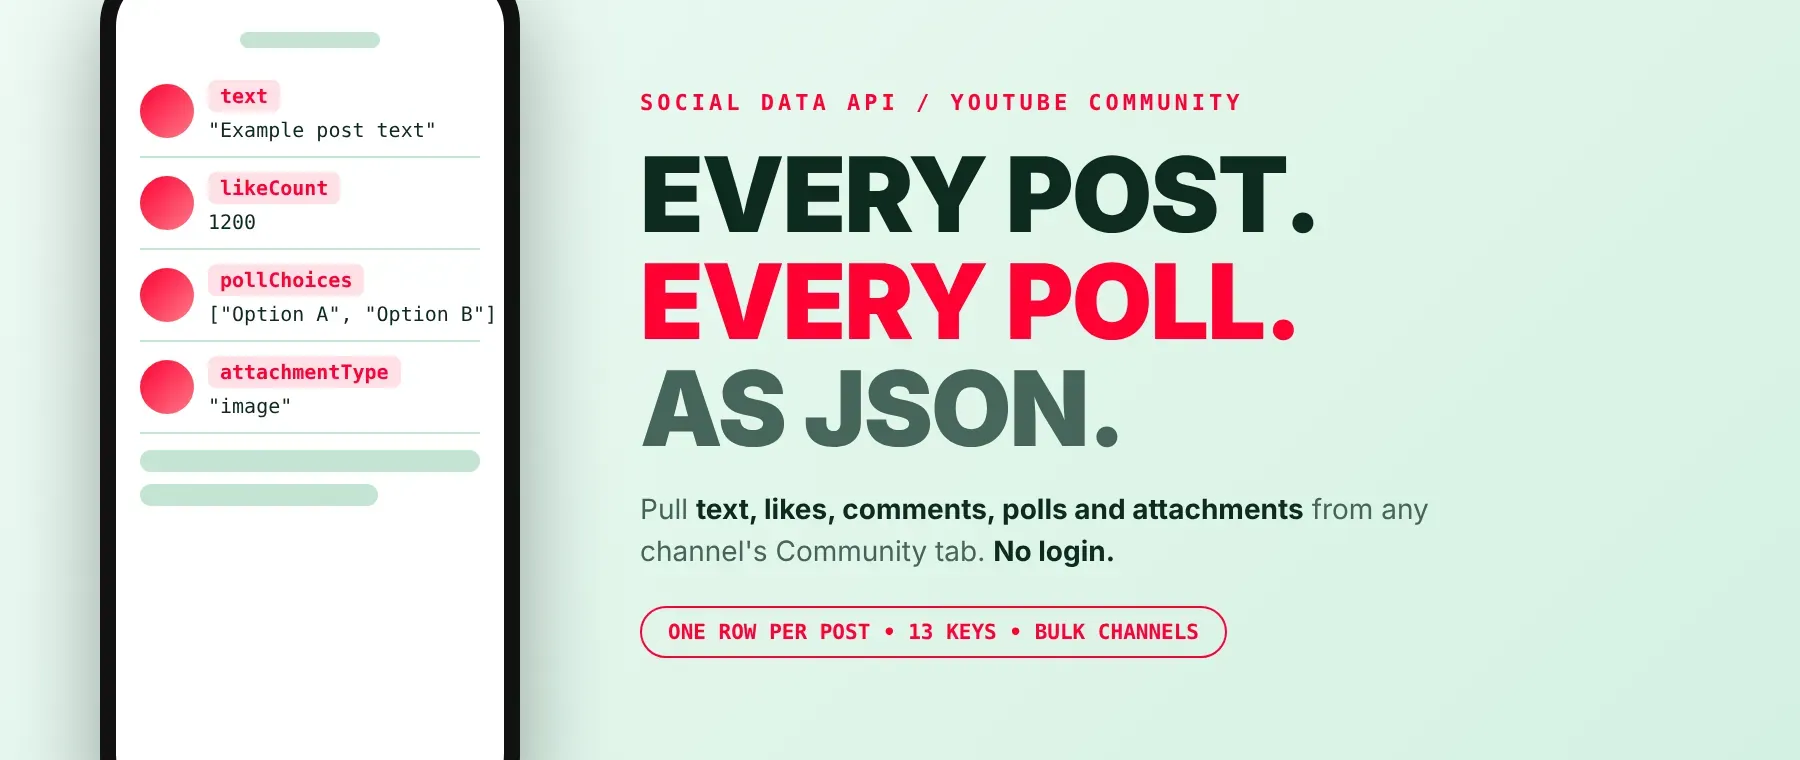
YouTube Community Posts Scraper extracts public posts from the Community (Posts) tab of YouTube channels. Each post comes back with its full text, publish time, like and comment counts, poll answer options, attached images and video thumbnail, plus the channel's name, ID and link. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed a social listening pipeline. No YouTube account or cookies needed. Start with one channel, then add every creator you track.
What data can I extract with YouTube Community Posts Scraper?
Using this YouTube Community Posts API, you will be able to extract the following YouTube community post data:
| 💬 Post text | 🕐 Publish time | 👍 Like count | 💭 Comment count |
|---|---|---|---|
| 📋 Poll answer options | 🖼️ Images (single and carousels, every size) | 🎬 Video thumbnail | 📎 Attachment type (video, image, poll) |
| 📌 Post ID | 🆔 Channel ID | 👤 Channel name | 🔗 Channel link |
| 🧭 Source channel URL you entered |
How to use YouTube Community Posts Scraper
It is built for creator, brand and research teams that want to scrape YouTube community posts, with their engagement numbers, from many channels in one run.
Copy to your AI assistant:
YouTube Community Posts Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Point your AI assistant at the Apify MCP server and it can read YouTube community posts on its own: the server starts with this Actor already available as a tool, so the agent runs it directly with call-actor, then reads the post text, polls and engagement counts from the result. No glue code, no scraping logic in your prompts.
Step by step
- Create a free Apify account.
- Open YouTube Community Posts Scraper in the Apify Store.
- Enter the YouTube channel URLs, one per line (a bare @handle works too).
- Click Start (or send your API request).
- Download or stream your results in JSON, CSV or Excel.
How to scale YouTube Community Posts Scraper to bulk
Put every channel in the channel list of one run of this YouTube posts scraper: up to three channels are read at the same time, and the max-posts setting applies to each channel on its own, so 50 channels at 100 posts each can return up to 5,000 rows. For recurring monitoring, save the input as a task and schedule it daily or weekly in Apify Console, or start runs from your own code through the Apify API. To export YouTube community posts into a sheet or BI tool, download the dataset as CSV or Excel after each run.
✨ Features
YouTube Community Posts Scraper fetches clean, structured community posts from YouTube channels ⚡. It's ideal for creator monitoring, brand mention tracking, campaign reporting and building post archives for AI agents. Use it as a YouTube channel posts scraper or a YouTube Community tab scraper for one creator or for hundreds.
It extracts, per post:
- Post text – the full message, poll question or caption.
- Like count and comment count – the engagement numbers YouTube shows on the post.
- Poll answer options – every choice of a poll post, so it doubles as a YouTube poll scraper.
- Images – every image of single-image posts and image carousels, in all available sizes.
- Video thumbnail – the largest thumbnail of a video shared in the post.
- Attachment type – video, image or poll, for quick filtering.
- Publish time – when the post went up, as YouTube shows it ("2 months ago").
- Channel name, ID and link – to join posts with other channel data.
⚡ Plain HTTP requests with no browser and 1024 MB default memory; a recorded test run returned 141 posts from 3 channels in 2.3 seconds.
Use cases 💡
- Talent manager — track every post and like count across a creator roster.
- Brand team — find sponsored announcements in creators' community posts.
- Market researcher — collect poll questions and answer options by niche.
- Data analyst — compare YouTube community engagement data between channels each week.
- AI engineer — feed post text into a RAG index for a creator-insights agent.
Building an AI agent? Connect YouTube Community Posts Scraper over MCP and let it call the actor on its own.
Why choose this actor?
- Many channels in one run. A recorded test run returned 141 posts from 3 channels (50 + 50 + 41, the last channel's full public feed) in 2.3 seconds, with up to three channels read at the same time.
- The engagement behind each post. A recorded poll post came back with 104K likes, 10K comments and both answer options; image carousels return every image, not just the first.
- 13 fields, every channel URL format. Each post carries the same 13 fields, and the channel list accepts full links, links without https://, bare @handles, /channel/ and /user/ links, and links to any channel tab.
⬇️ Input
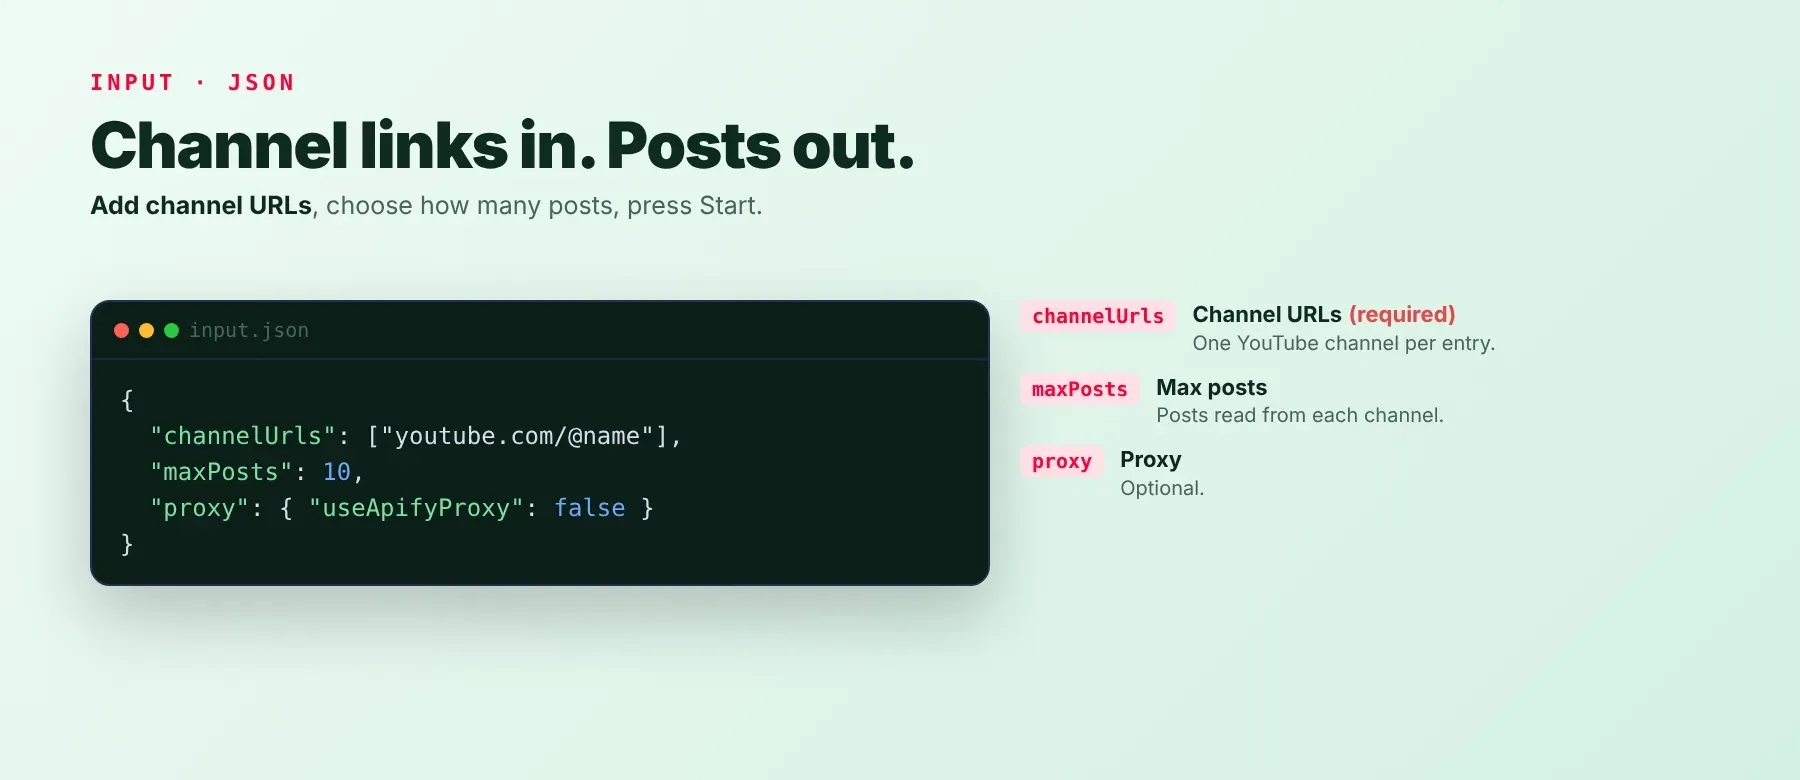
The actor takes a list of YouTube channel URLs (required) and how many posts to read from each channel. A proxy is optional.
| Parameter | Required | Type | Description | Example value |
|---|---|---|---|---|
channelUrls | Yes | array of strings | One YouTube channel per entry. Accepted: https://www.youtube.com/@name, youtube.com/@name, @name, https://www.youtube.com/channel/UC…, /user/… links. Links to a channel tab (/videos, /shorts, /featured, /posts…) or with ?si= are cut back to the channel. Empty lines are skipped. | ["https://www.youtube.com/@MrBeast"] |
maxPosts | No | integer | Posts to read per channel. Default 10, allowed 1–10,000. A channel can return fewer: YouTube shows logged-out visitors roughly its latest 200 posts. | 50 |
proxy | No | object | Proxy settings. Default: direct connection. Choose Apify Proxy or add your own proxy URLs; a channel that fails through the proxy is retried on a direct connection. | {"useApifyProxy": false} |
Accepted channel URL formats:
https://www.youtube.com/@MrBeastoryoutube.com/@MrBeastor@MrBeasthttps://www.youtube.com/channel/UCX6OQ3DkcsbYNE6H8uQQuVAhttps://www.youtube.com/user/MrBeast6000https://www.youtube.com/@MrBeast/shorts,https://m.youtube.com/@MrBeast/community,https://www.youtube.com/@MrBeast?si=…
Free plan limits
Users on the Apify free plan can fetch up to 20 posts per run (all channels together) and 200 posts per month. When the limit is reached, the run finishes successfully with a status message explaining the limit. Upgrade to any paid Apify plan to remove these limits.
Example input
The input of a real test run (141 posts in 2.3 seconds):
⬆️ Output
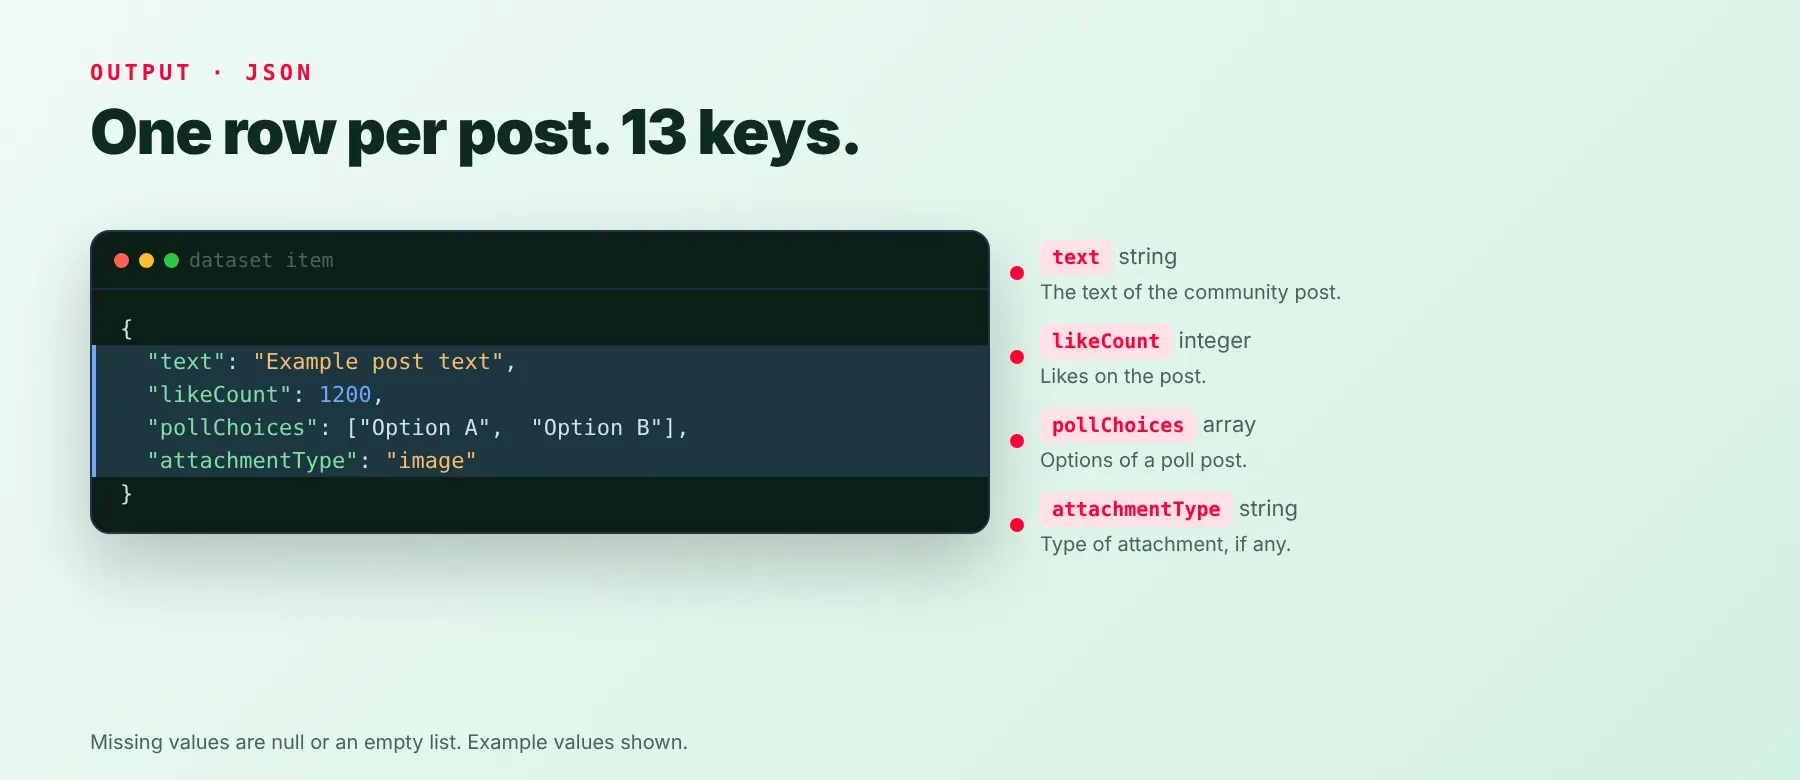
Every community post is one typed, normalized JSON item with the same 13 keys on every run; missing values are null or an empty list, never a missing key. Export the dataset as JSON (default), CSV or Excel; a run summary record (total posts, channels with and without posts) is also saved in the run's key-value store.
Example output
Real rows from the test run above (the image list is shortened to its first and last size here; the real row lists every size):
How does it work?
The actor works like a logged-out visitor opening a channel's Posts tab: it reads the same public pages the YouTube site loads, with plain HTTP requests and no browser, and keeps paging through the feed until it has the number of posts you asked for or the channel has no more. It returns only publicly visible data — what any visitor sees without logging in — so no YouTube account, cookie or API key is used. Each channel page is tried up to three times, with growing pauses between attempts. By default it uses a direct connection; if you choose Apify Proxy or your own proxy URLs, requests go through them, and a channel that fails through the proxy is tried again on a direct connection. Every post becomes one row with the same 13 fields and is saved to the dataset as soon as it is read.
How do you integrate YouTube Community Posts Scraper into your stack?
It works with what you already use: the REST API from any language, MCP for AI agents, and no-code tools.
MCP integration for AI agents
Add the Apify MCP server to your client with one command:
This registers YouTube Community Posts Scraper as a tool your agent can call directly, with no search or add-actor step needed: the agent runs it with call-actor. It works in Claude Code, Cursor and Windsurf, and in any client that supports remote MCP servers.
No-code tools (n8n, Make, LangChain)
- n8n — use the Apify node's "Run an Actor" operation with this Actor and your channel list, or the HTTP Request node pointed at the Apify API's run-sync endpoint with your token. The node returns the dataset items for the next step.
- Make — add the Apify app's "Run an Actor" module, then "Get Dataset Items" to pass each post to Google Sheets, Airtable or Slack.
- LangChain — install
langchain-apifyand wrap this Actor withApifyActorsTool, so an agent can fetch a channel's posts as context.
Is it legal to scrape YouTube data?
Scraping publicly available YouTube data is generally legal when you collect only what any visitor can see and use it responsibly. This actor returns only publicly available data — what any user sees without logging in; members-only posts are never collected. Under GDPR, scraping public data is generally permissible, but storing and using it must comply with local data-protection law, especially where posts mention people by name. Respect YouTube's terms and the rights of the creators whose posts you analyse. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does YouTube Community Posts Scraper return?
As a YouTube community post extractor, it returns each post's text, publish time, like count, comment count and poll answer options, plus image URLs, video thumbnail, attachment type and the channel's name, ID and link. See the data fields section for the full list.
Does YouTube Community Posts Scraper require a YouTube account or login?
No. Only public community post data is extracted, and no credentials, cookies or API keys are needed.
How fast does YouTube Community Posts Scraper run?
A recorded test run returned 141 posts from 3 channels in 2.3 seconds. Every run reads live data; nothing is cached.
What happens if a channel has no posts or doesn't exist?
A channel with no public Posts tab, no posts, or a URL that doesn't exist adds no rows and is not charged; the log names the channel and the reason, and the run continues with the next channel. In code, count rows per source channel URL to see which channels returned nothing.
Can I scrape multiple YouTube channels at once?
Yes. Add as many channels as you like to the channel list; up to three are read at the same time, and the max-posts setting applies to each channel.
Does YouTube Community Posts Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — YouTube Community Posts Scraper is available as an MCP tool through the Apify MCP server. Register it in Claude Code, Cursor or Windsurf with claude mcp add --transport http apify "https://mcp.apify.com?tools=socialdataapi/youtube-community-posts-scraper". Any agent that can call an HTTP endpoint can also use the REST API directly.
Does YouTube Community Posts Scraper return data in a format LLMs can use directly?
Yes. Every post is typed, normalized JSON with consistent field names — no HTML parsing, no selectors. Pass it straight to an LLM, index it into a vector store, or feed it to an agent tool with no transformation step.
What happens when YouTube changes its layout or updates its anti-bot system?
The actor is maintained, and when YouTube changes its pages, the actor is updated so your calls keep returning the same JSON schema with no changes on your end.
Can I use YouTube Community Posts Scraper without managing proxies or browser infrastructure?
Yes. No browser is involved, retries happen on the actor's side, and most runs need no proxy at all; Apify Proxy is one switch away when you want it. You send one request and get structured JSON back.
Which YouTube community post fields work best for AI training data and RAG indexing?
For RAG, use the post text, the poll answer options and the channel name. For training data, use the like count, comment count, attachment type and publish time. Counts are kept as YouTube displays them (for example 230K), so convert them to numbers if your model needs integers.
Your feedback
Found a bug or missing a field? Let us know. Include the input you used and the run's log so the problem can be reproduced; every report is read, and fixes ship to the actor.


