
YouTube Video Details Scraper
Pricing
from $0.67 / 1,000 results
YouTube Video Details Scraper
YouTube Video Details Scraper extracts details for public YouTube videos from links or IDs: title, description, views, likes, comment count, duration, publish date, tags, thumbnails, channel info and transcript. No login needed. Export to JSON, CSV or Excel, or use the API.
Pricing
from $0.67 / 1,000 results
Rating
0.0
(0)
Developer

Social Data API
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
YouTube Video Details Scraper — Views, Likes, Channel and Transcripts
YouTube Video Details Scraper reads public YouTube videos from their links or IDs and returns the title, description, views, likes, comment count, duration, publish date, tags, hashtags, category, caption language, highest resolution, thumbnails, channel details and the full transcript. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed a content research pipeline. No YouTube account or cookies needed. Start with one video, then track every video your channel or your competitors publish.
What data can I extract with YouTube Video Details Scraper?
Using this YouTube Video API, you will be able to extract the following YouTube video data:
| 🎬 Title | 📝 Description | 👁️ View count | 👍 Like count (if shown) |
|---|---|---|---|
| 💬 Comment count | ⏳ Duration in seconds | 📅 Publish date | 🏷️ Tags |
| #️⃣ Hashtags from the description | 🗂️ Category | 🌍 Caption language | 🖥️ Highest resolution |
| 🖼️ Thumbnails (up to 5 sizes) | 📺 Channel name and ID | 🔖 Channel handle and link | 👥 Subscriber count |
| 🧑 Channel avatar (900 px and all listed sizes) | ✔️ Channel badges | 📜 Transcript, one entry per caption line | 🔴 Live status |
| 🎞️ Upload type (normal, short or live) | 📈 Engagement rate | 🆔 Video ID | ⚠️ Reason an entry gave no video |
How to use YouTube Video Details Scraper
Built for content teams, researchers and AI builders: one run turns a list of YouTube links into a table of video details with channel data and transcripts.
Copy to your AI assistant:
YouTube Video Details Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Point your AI assistant at Apify and it can read YouTube on its own: video details, channel data and full transcripts for any public video link. No glue code, no scraping logic in your prompts.
Step by step
- Create a free Apify account.
- Open YouTube Video Details Scraper in the Apify Store.
- Paste the YouTube video links or IDs, one per line.
- Click Start (or send your API request).
- Download or stream your results in JSON, CSV or Excel.
How to scale YouTube Video Details Scraper to bulk
Used as a bulk YouTube video scraper, put any number of video links in one run: six videos are read at the same time and each row is saved as soon as its video is ready, so the table fills while the run goes. A recorded run with nine entries — five videos, a repeated link, a playlist, a channel and a missing video — saved five videos and three free error rows in 20.4 seconds. To export YouTube video data for a whole channel, collect its video links first and paste them in. To track views and likes over time, schedule the same run daily or weekly in Apify Console.
✨ Features
YouTube Video Details Scraper fetches clean, structured video details from YouTube ⚡. It's ideal for YouTube transcript collection, content research, and tracking the YouTube views and likes of your own or competing videos — a YouTube video scraper that also reads Shorts links. It extracts, per video:
- Transcript – one entry per caption line with its start time and duration, from the video's default captions
- Audience numbers – view count, like count, comment count and engagement rate
- Video facts – title, description, duration, publish date, category, tags and hashtags
- YouTube channel details – channel name, ID, handle, link, subscriber count, avatar and badges
- Format – highest resolution, live status and upload type (normal, short or live)
- Thumbnails – up to five standard sizes, only the ones that exist for the video
⚡ Entries that give no video, such as playlist or channel links, get a free row with the reason and are never charged.
Use cases 💡
- Content strategist — compare views, likes and tags across competitor uploads every week.
- Researcher — collect transcripts and publish dates of a video list for analysis.
- Social media manager — track YouTube views and likes of your own videos and Shorts.
- Media buyer — check subscriber counts and badges of channels before sponsoring them.
- AI engineer — feed transcripts and descriptions into a RAG index for video Q&A.
Building an AI agent? Connect YouTube Video Details Scraper over MCP and let it call the actor on its own.
Why choose this actor?
- Video details and transcripts in seconds. A recorded run returned four videos, two of them Shorts, each with its transcript, in 4.0 seconds.
- The numbers behind each video. A recorded video came back with 1,826,093,015 views, 19,486,544 likes, a 61-line transcript, 3840x2160 resolution and five thumbnail sizes.
- 26 fields from one link. Watch, short, Shorts, live and embed links and bare video IDs all work, and every row carries the video, its channel and its transcript together.
⬇️ Input
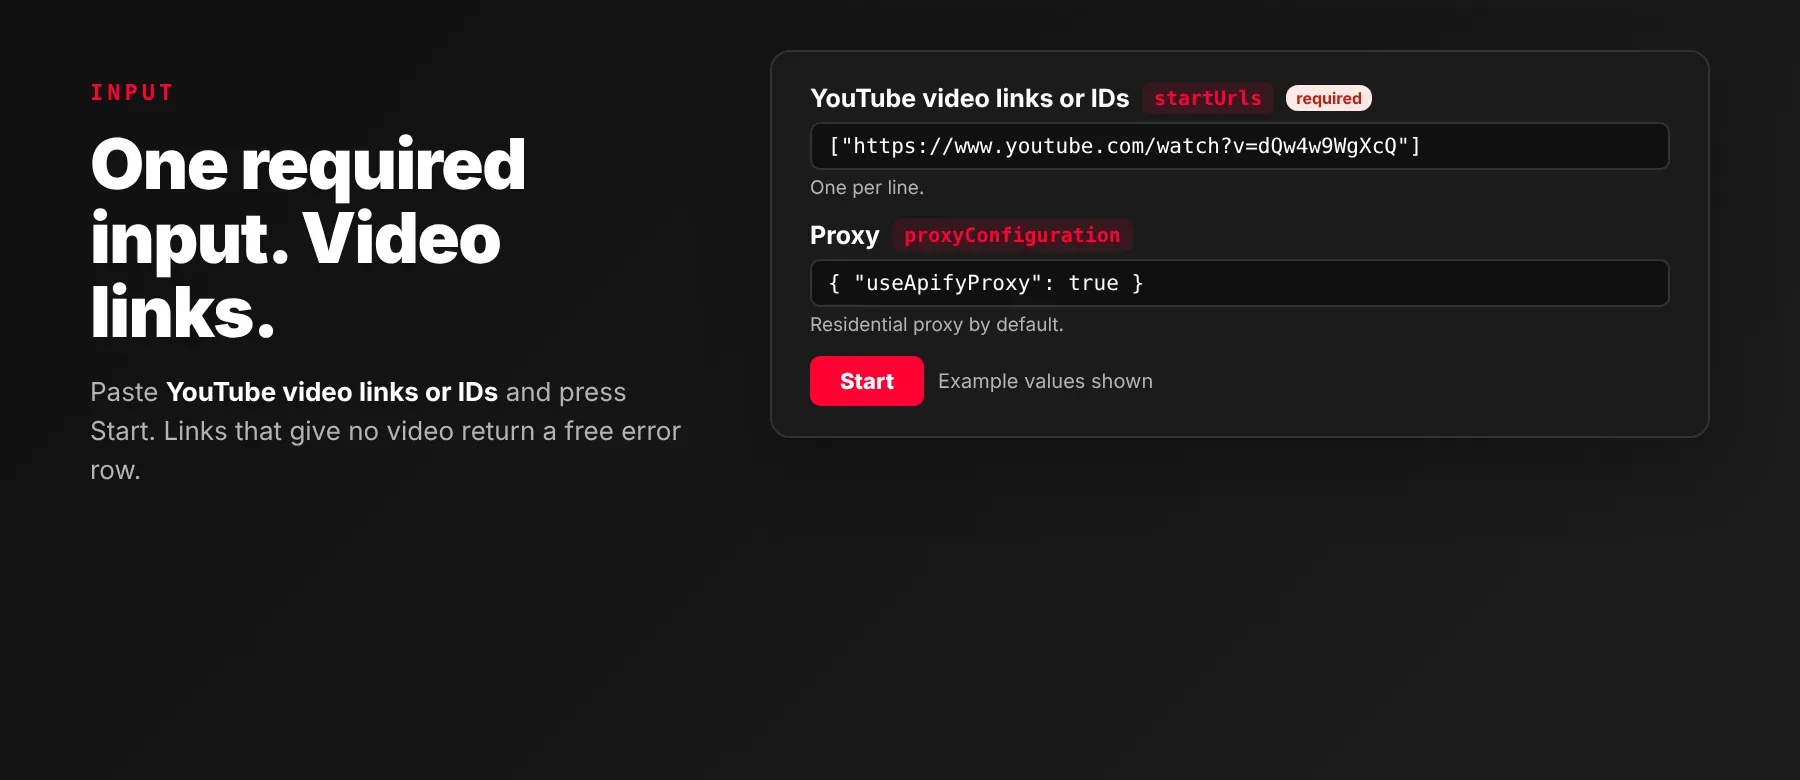
Enter one or more YouTube video links or IDs in startUrls (required). The proxy setting is optional.
| Parameter | Required | Type | Description | Example value |
|---|---|---|---|---|
startUrls | Yes | array | YouTube video links or bare 11-character video IDs, one per entry. Playlist and channel links are not supported and get a free error row. The same video added twice is saved once. | ["https://www.youtube.com/watch?v=dQw4w9WgXcQ"] |
proxyConfiguration | No | object | Connection used to reach YouTube. Default: Apify residential proxy ({"useApifyProxy": true, "apifyProxyGroups": ["RESIDENTIAL"]}). Every retry uses a new proxy session; other proxy groups move to residential when YouTube blocks, and with no proxy the actor starts direct and switches to a proxy when blocked. | {"useApifyProxy": true, "apifyProxyGroups": ["RESIDENTIAL"]} |
Accepted formats:
https://www.youtube.com/watch?v=dQw4w9WgXcQhttps://youtu.be/jNQXAC9IVRwhttps://www.youtube.com/shorts/aNI2jv7lBPQhttps://www.youtube.com/live/VIDEO_IDandhttps://www.youtube.com/embed/VIDEO_ID- a bare video ID such as
8jPQjjsBbIc
Free plan limits
Free plan: up to 20 videos per run (all video links together) and 200 per month; paid plans have no limit.
Example input
⬆️ Output
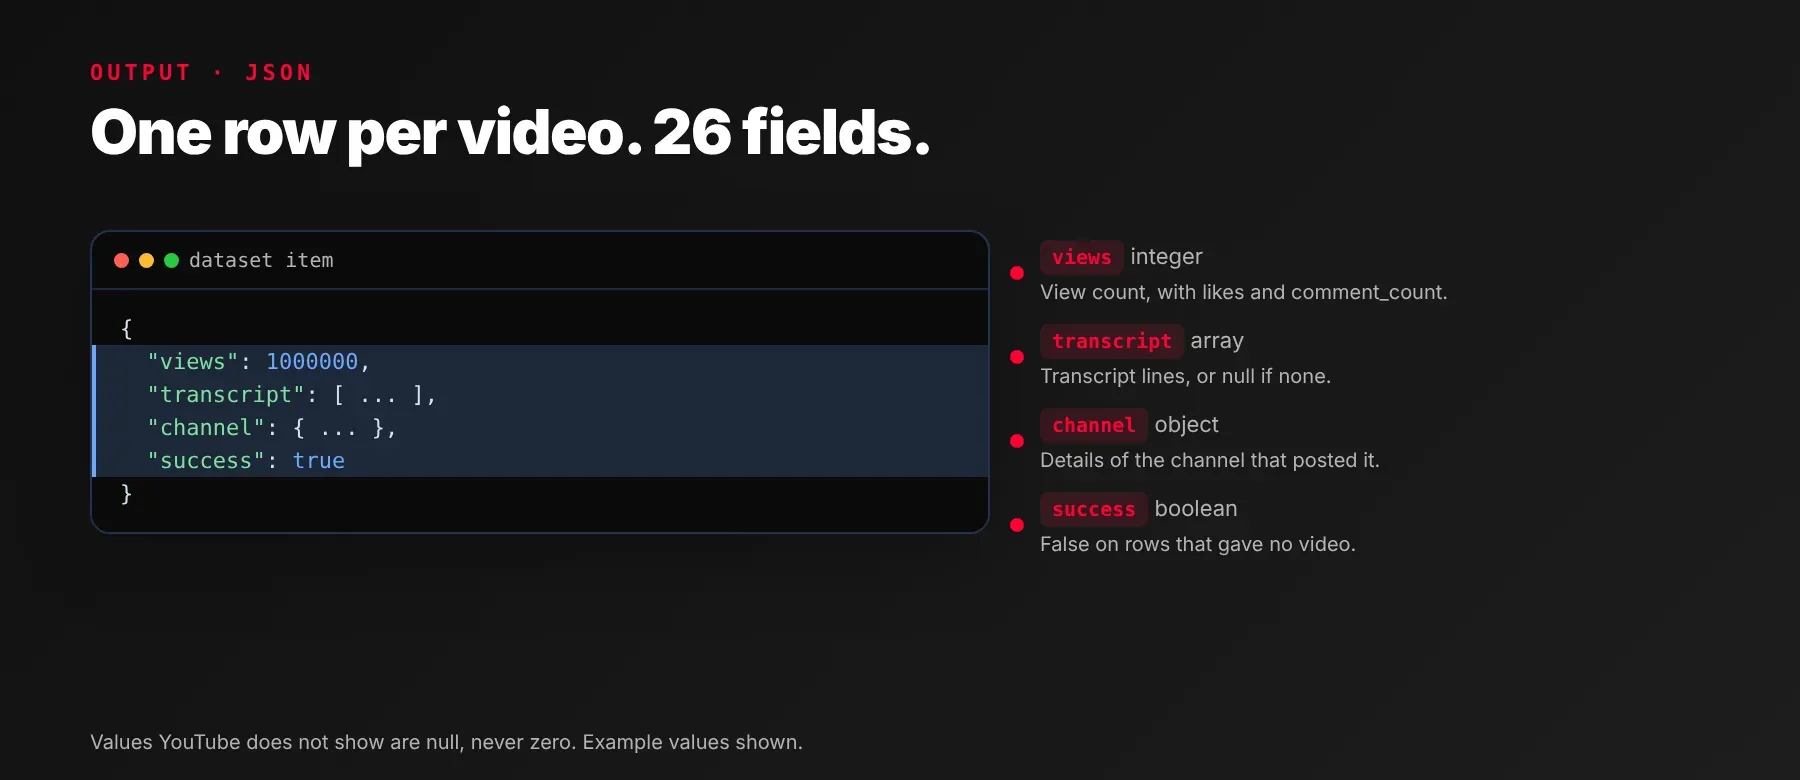
Every video is one typed, normalized JSON item with the same 26 fields on every run; values YouTube does not show are null, never a made-up zero. Entries that give no video come back as free rows with success set to false and the reason in the error field, in the same dataset, which you can export as JSON (default), CSV or Excel.
Example output
A recorded video (description shortened, 4 of 27 tags and 2 of 61 transcript lines shown) and the row for a playlist link:
The transcript is an empty list when a video has no captions, and null with a note when the captions could not be read this time. The language is the language of the video's default captions, so a song with English default captions shows en. The publish date is given in UTC. Rows with success set to false are not charged.
How does it work?
The actor reads the same public data the YouTube website loads for any visitor, with plain web requests and no browser. For each video it reads the video details, the channel panel, the captions and the available video sizes at the same time, checks which thumbnail sizes exist, and turns the default captions into a transcript with one entry per line. Requests go through Apify residential proxies by default, and every retry uses a fresh exit address; when YouTube limits a request, the actor waits, switches address and tries again. It returns only publicly visible data — what any visitor sees without logging in — and the output fields stay the same from run to run, so your code and spreadsheets keep working when YouTube changes its pages.
How do you integrate YouTube Video Details Scraper into your stack?
It works with what you already use: the REST API from any language, MCP for AI agents, and no-code tools.
Using YouTube Video Details Scraper with the Apify API
Call the Actor's run-sync-get-dataset-items endpoint with your Apify token and a startUrls list, or use the apify-client package for your language to start the run and read back the dataset items. Works in Python, Go, Ruby, Node.js, cURL — any language that can make an HTTP request.
MCP integration for AI agents
Add the Apify MCP server to your AI client with one command:
This registers YouTube Video Details Scraper as a tool your agent can call directly: the agent finds it through the server's search, adds it and runs it, then reads the videos back as JSON. Ask for "the transcripts and view counts of these five videos" and it does the rest. It works in Claude Code, Cursor and Windsurf.
No-code tools (n8n, Make, LangChain)
n8n: add the Apify node and choose "Run an Actor", or use the HTTP Request node pointed at the run-sync endpoint with your token. Send each video's transcript to a summarizer or a Google Sheet in the next node.
Make: use the Apify app's "Run an Actor" module, then "Get Dataset Items" to pull the videos into the rest of your scenario.
LangChain: install langchain-apify and wrap the actor with ApifyActorsTool() so your agent can fetch YouTube video info and transcripts on demand.
Is it legal to scrape YouTube data?
Collecting public YouTube video details is generally lawful: titles, view counts, channel names and captions are shown to every visitor without an account. This actor returns only publicly available data — what any visitor sees without logging in. GDPR: scraping public data is generally permissible, but storing and using it must comply with local data-protection law. Transcripts and descriptions can be copyrighted, so check how you reuse them. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does YouTube Video Details Scraper return?
It returns each video's title, view count, like count, comment count and full transcript, plus the description, publish date, tags, thumbnails and channel details. See the data fields section for the full list.
Does YouTube Video Details Scraper require a YouTube account or login?
No. Only public YouTube video data is extracted, and no credentials are needed.
How fast does YouTube Video Details Scraper run?
A recorded run returned four videos with transcripts, two of them Shorts, in 4.0 seconds, and a run with nine mixed entries finished in 20.4 seconds. Six videos are read at the same time, and every run reads live data, not a cache.
What happens if a video is private or doesn't exist?
You get one free row with success set to false and the reason in the error field, for example "YouTube says: Video unavailable", or playlist_url_not_supported and channel_url_not_supported for links that are not a single video. In code, keep rows where success is true.
Can I scrape multiple YouTube videos at once?
Yes. Put any number of links or IDs in the video list; six are read at the same time, each row is saved as soon as it is ready, and a video added twice is saved once.
Does YouTube Video Details Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — YouTube Video Details Scraper is available as an MCP tool. Register it in Claude Code, Cursor or Windsurf with claude mcp add --transport http apify "https://mcp.apify.com?tools=socialdataapi/youtube-video-details-scraper". Any agent that can call an HTTP endpoint can use the REST API directly.
Does YouTube Video Details Scraper return data in a format LLMs can use directly?
Yes. Each video is typed, normalized JSON with consistent field names, so there is no HTML parsing and no selectors. Pass it straight to an LLM, index it into a vector store, or feed it to an agent tool — no transformation step.
What happens when YouTube changes its layout or updates its anti-bot system?
The actor is maintained, and when YouTube changes, it is updated so your calls keep returning the same JSON fields with no changes on your end.
Can I use YouTube Video Details Scraper without managing proxies or browser infrastructure?
Yes. Residential proxies, fresh exit addresses on every retry, pauses and retries all run on the actor's side, and no browser is needed. You send one request and get structured JSON back, with no proxy accounts and no maintenance.
Which YouTube video fields work best for AI training data and RAG indexing?
For RAG, use the transcript, the description, the title and the tags. For training data and analytics, use the view count, like count, comment count, engagement rate, duration and publish date. All fields are plain strings, numbers, booleans and short lists, so no normalization is needed.
Your feedback
Found a bug or missing a field? Let us know in the actor's Issues tab. Every report is read, and fixes ship as new versions of the actor.


