
SERP Competitor Overlap Analyzer
Pricing
from $14.00 / 1,000 competitor assessments
SERP Competitor Overlap Analyzer
Find repeated domains across Google Search result datasets. Compare observed query coverage and rank evidence in each competitor assessment, with country, device and source coverage preserved.

SERP Competitor Overlap Analyzer — turn a keyword SERP batch into an observed competitive set
Feed it an existing Google Search Results dataset and get back one competitor assessment per domain — keyword coverage, verified page-1 rank evidence, and unique ranking URLs — sampled from the queries you actually ran, never a global market-share claim.
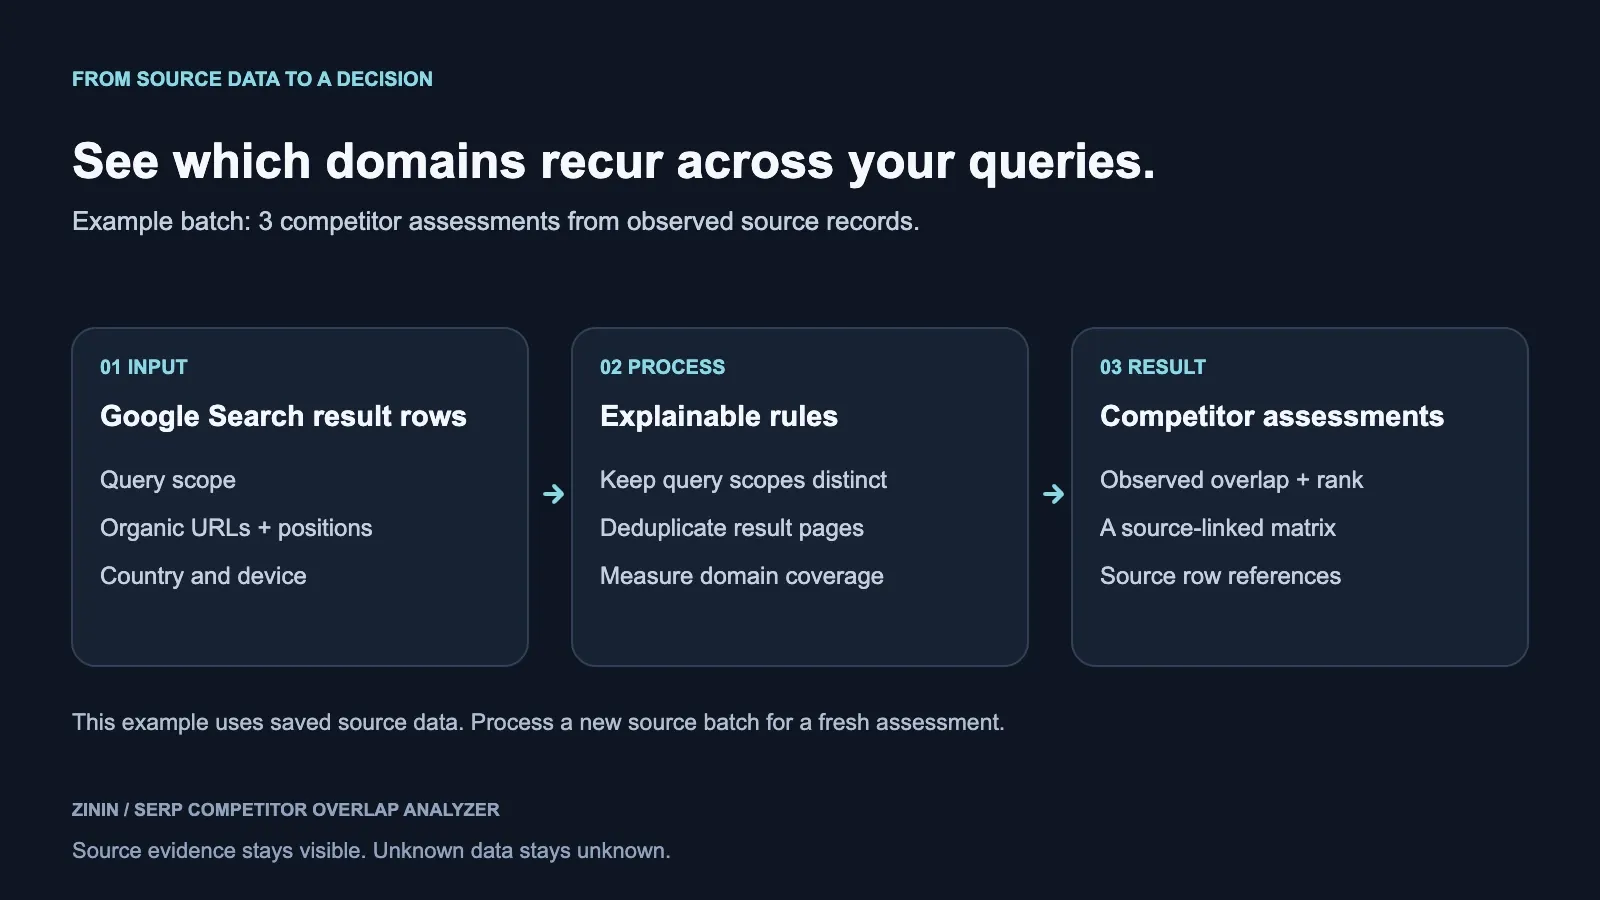
This Actor does not scrape Google. It reads a keyword SERP batch you already have — most naturally from Google Search Results Scraper — and turns it into one competitor assessment per domain: how many of your observed query scopes it appears in, an explicit weighted-rank score derived only from verified page-1 positions, and the bounded list of keywords/URLs behind that score. It is a competitive-research tool for teams working from a SERP batch they already collected — not a rank tracker with historical trending, not a market-share estimate, and not a claim about search volume or traffic.
What you get
For each distinct domain found across your source batch, you get one assessment record containing:
entityId/domain— the normalized hostname (http/https only, no embedded userinfo credentials, leadingwww.and a trailing DNS dot stripped, DNS labels validated; no public-suffix/last-2-label stripping).keywordCoverageCount— the number of distinct query scopes (term + countryCode + device + languageCode + locationUule, pages merged) where this domain appears at least once, on any page.page1CoverageCount— ofkeywordCoverageCount, how many query scopes have verified page-1 evidence for this domain — the only scopes contributing toweightedRank/bestGlobalPosition.totalObservedQueries— the batch-wide denominator: distinct valid query scopes observed across the whole run, including valid empty-organic-results pages.coverageRatio—keywordCoverageCount / totalObservedQueries.weightedRank— sum of1/page1Positionacross every query scope with verified page-1 evidence for this domain;nullwhen the domain has no page-1 evidence at all — never derived from a page-relative position on a later page.bestGlobalPosition— the lowest verified page-1 position across this domain's query scopes;nullwhen no page-1 evidence exists.action—single_query_appearance(exactly one query, always),partial_overlap_competitor(≥2 queries), orstrong_repeated_competitor(≥2 queries andcoverageRatio ≥ 0.5) — describes query-scope overlap breadth, never a rank claim.keywords— up to 50 entries, each withterm/countryCode/device/languageCode/locationUule,bestPosition/bestPositionPage(best page-relative position observed on any page, informational only), andglobalRank(the verified page-1 position, ornull).uniqueUrls/uniqueUrlCount— every distinct URL observed for this domain, up to 50, sorted deterministically.evidence— the matched field, value, and rule behind every claim, tied to a source row index.- Honest diagnostics for everything else — an invalid row, a source-reported failure, an invalid query scope, a conflicting duplicate page, or an unparseable result entry are all free, separate rows.
What this Actor is explicitly not: no global market-share estimate, no search-volume or traffic inference, no historical rank trending, no claim that a page-2+ position is a "real" global rank.
Who uses it
- SEO teams turning a fresh keyword SERP batch into a ranked list of who actually shows up, instead of eyeballing dozens of result pages by hand.
- Competitive-research teams who need a defensible, evidence-linked reason a domain is flagged a repeated competitor, not an opaque score.
- Content/PR teams identifying which domains repeatedly rank on page 1 across a keyword set to prioritize outreach or content gap analysis.
- Data-quality teams using
partial/partialQueryScopesas a signal for how clean an upstream SERP scrape actually is.
Not a scraper: point it at an existing SERP Dataset producing the row shape in Input contract, most naturally Google Search Results Scraper (users30d=17421, successfulRuns30d=7,948,982). This Actor never starts it, and never fetches a page from the open web.
How to run
- Console (fastest for a one-off run). Open the Actor, go to Input, paste rows into Source records (inline) or fill in Source Dataset, leave defaults, hit Start.
- From an existing SERP Dataset. Put its Dataset ID in
datasetId— read with your own run's permissions, no separate authorization step. - Chained via Integrations. Add this Actor as an "Actor/task run" integration on your SERP-scraper run; map
{{resource.defaultDatasetId}}into this Actor'sdatasetIdfield explicitly (see Integration recipes) for aREADgrant — a bare Dataset ID or webhook payload alone does not grant access. - Via the API. Call
POST /v2/acts/bRZ5G3R7VVMg4FZyx/runs(orrun-sync-get-dataset-items) withdatasetId(oritems) and, for a spending ceiling, the run optionmaxTotalChargeUsd. - Set your batch size.
maxInputRows(default 100, max 1000) bounds source rows examined;maxResults(default 3, max 1000) bounds delivered assessments independently of spend. - Read the results. One row per unique domain lands in the run's default Dataset, with a matching
OUTPUT/SUMMARYrecord.
Every run is independent processing — see Operating guide for what that means for re-running against the same batch.
Pricing
Pay-per-event, one event type: result-found ("Competitor assessment" in the platform's pricing UI — the primary pricing noun used throughout this listing, the Dataset terminology, and the pricing record itself) — one delivered competitor assessment (one unique domain). There is no start fee, and every free diagnostic (an invalid row, a source-reported failure, an invalid query scope, a conflicting duplicate page, a budget stop, an empty batch) requests no charge event at all.
| Tier | Price per competitor assessment | Discount |
|---|---|---|
| Free (default) | $0.02 | — |
| Bronze | $0.018 | 10% |
| Silver | $0.016 | 20% |
| Gold | $0.014 | 30% |
| Platinum | $0.014 | 30% |
| Diamond | $0.014 | 30% |
These are Apify's platform-wide account pricing tiers — not a volume schedule this Actor invents — assigned automatically by your account's usage; you don't select one. One competitor assessment is one unique domain, never billed per duplicate/observed page.
A note on the evidence in this README: every output example below comes from the product owner's own verification runs against this Actor's accepted build — cost to the owner, not sales or customer revenue. The saved public example is a retained snapshot of a real search results run, not a fresh scrape performed for this README.
Set the platform's own Max total charge (USD) run option to cap spend. If testing the zero-paid path via a raw API call, do not rely on literal maxTotalChargeUsd: 0 — use a small positive value below every tier's price (e.g. $0.005, below Gold/Platinum/Diamond's $0.014) instead, and confirm the run's actual effective cap after it starts rather than trusting the requested value silently — see Evidence and boundaries.
Input contract
| Field | Type | Default | Notes |
|---|---|---|---|
items | array | curated public prefill | Inline source rows; overridden by datasetId/runId/payload when set. Max 1000 items. |
datasetId | string (resourcePicker) | — | Existing source Dataset, read with your run's permissions. Overrides inline rows. |
runId | string | — | Alternative to datasetId: reads that run's own default Dataset with your run's permissions. |
payload | object | — | Optional ACTOR.RUN.SUCCEEDED webhook payload with resource.defaultDatasetId/resource.id. A bare payload does not grant access. |
maxInputRows | integer | 100 (max 1000) | Source rows examined before grouping; also bounded to 4 MiB total, 64 KiB/row. |
maxResults | integer | 3 (max 1000) | Useful competitor assessments delivered, independent of maxTotalChargeUsd. |
Source precedence (never merged): explicit datasetId/payload.resource.defaultDatasetId > runId/payload.resource.id > inline items. A malformed or conflicting reference is rejected outright, not silently ignored.
Supported adapter fields (the actual keys this Actor reads — from the upstream source above, or any dataset shaped the same way): searchQuery.term/searchQuery.countryCode/searchQuery.device (all required, bounded, non-empty strings), searchQuery.languageCode/searchQuery.locationUule (optional, bounded strings — an object/array is rejected, never silently merged into scope identity), searchQuery.page (a positive integer, defaults to 1 when absent), organicResults[].url/organicResults[].position (position must be an integer 1..100). Paid results, AI-overview citations, and any other non-organicResults block are never read as organic ranking data. A page carrying an explicit statusCode other than exactly 200 (numeric or the numeric string "200") is treated as a failed page, never silently as full coverage.
Output examples
Example 1 — a single-query, page-1 competitor (final-prefill, real public snapshot, exact Dataset row).
coverageRatio: 0.5 here means this domain appeared in 1 of the batch's 2 total observed query scopes — a fact about this sampled batch, never a market-share percentage.
Example 2 — the same domain under a controlled incomplete-source test ("partial-columns" scenario), exact Dataset row. This actor's own adversarial-provenance.json states: "Historical label only. Actual source values retained; explicit found:true/partial:true injected as a controlled incomplete-source flag. This is a derived adversarial scenario, not observed upstream incompleteness or actual column removal." Every ranking field below is identical to Example 1's real source snapshot — only the injected source-level partial:true flag (and its consequence, one added evidence entry, a lower confidence, and partial:true) distinguishes it; no page or column was actually removed from this fixture:
Example 3 — below-price boundary run, exact free diagnostic row (real settled receipt). With maxTotalChargeUsd set to $0.005 (below every tier's $0.014+ price), the run reads no source at all:
Example 4 — empty inline source, exact free diagnostic row (real settled receipt).
Field dictionary
Result fields: entityId/domain (normalized hostname); keywordCoverageCount; page1CoverageCount; totalObservedQueries (batch-wide denominator, including valid empty-organic pages); coverageRatio; weightedRank (sum of 1/page1Position across page-1-verified scopes, null if none); bestGlobalPosition (lowest verified page-1 position, null if none); action (single_query_appearance | partial_overlap_competitor | strong_repeated_competitor); confidence (starts at 1, reduced per partial/unknown-rank/truncation signal, floored at 0.3); keywords[] (term/countryCode/device/languageCode/locationUule/bestPosition/bestPositionPage/globalRank/urls, up to 50 entries) + keywordsTruncated; uniqueUrls/uniqueUrlCount + uniqueUrlsTruncated (up to 50); sourceRowIndexes/sourceRowIndexesTruncated (up to 50); evidence (up to 50 entries); partial (true when any conflicting page was excluded ANYWHERE in the whole source batch — a global dataset-coverage flag, not scoped to this domain's own supporting queries — or when a scope specifically supporting this domain had an errored/malformed page, when any supporting scope has no page-1 evidence, or when any reference list was truncated at 50; see Evidence and boundaries).
Ranking and rank-tie semantics, exactly as coded: a globalRank is only ever a verified page-1 position — a page-relative position observed on page 2+ is never converted into a claimed global rank by guessing page sizes; it stays bestPosition/bestPositionPage (informational) with globalRank: null for that keyword occurrence. When the SAME domain+scope shows a tied best position across two different pages (e.g. position 1 observed on both page 1 and page 2), the tie always resolves to the lower page number, deterministically — a real, disclosed fact about the page, never a side effect of which page happened to arrive first in source order. Duplicate-page comparison is order-independent: two reports of the same query+page whose organic entries are identical but listed in a different array order are recognized as duplicates, not a conflict; a genuine content difference (a different URL, position, or entry count) excludes the entire page from aggregation as a free conflicting_duplicate_page diagnostic. The published keywords/uniqueUrls lists, and which keyword-scope entries survive the 50-entry display cap, are sorted by a deterministic key (the query scope's own identity, or the URL itself) — never by which source row happened to arrive first; sourceRowIndexes alone is allowed to reflect genuine source order, since it describes provenance, not a factual/ranking choice.
Free product-specific diagnostic states: invalid_row (unusable row shape); invalid_query_scope (missing/malformed searchQuery.term/countryCode/device, an invalid languageCode/locationUule type, or a non-positive-integer searchQuery.page); source_row_error (a hard-failure signal — found:false, failed:true, a status like failed/error/timed-out/aborted, or a non-200 statusCode — always wins over a contradictory found:true/partial:true claim); invalid_or_error_page (no organicResults array on an otherwise-accepted page — treated as an error, never silently full coverage); conflicting_duplicate_page (two reports of the same query+page with genuinely different organic content — the entire page is excluded from aggregation); invalid_result_entry/invalid_result_url/invalid_position (a malformed organic entry, an unparseable/credentialed URL, or a position outside 1..100 — never inventing a rank from array order).
Common shared-runtime free Dataset notices (apply identically across the whole value-add product line, not specific to this Actor): invalid_input; source_unavailable; partial_source (carries reason: total_byte_cap_reached | pagination_interrupted | invalid_json_page | unexpected_shape | unexpected_page_size | max_input_rows_reached | oversized_rows_dropped); source_rows_dropped (carries count); result_dropped_oversized (carries count); budget_stopped (carries reason; mid-run also carries delivered/totalUseful); max_results_reached (carries reason, delivered, totalUseful); no_results. Every free notice's error/reason is a short, disclosed code — never a raw exception message or untrusted input value.
Runtime OUTPUT/SUMMARY fields: schemaVersion/product/errorCode; fatalFailure (true only when outcome:'failed'); outcome (delivered | budget_stopped | max_results_reached | no_results | diagnostic | failed); deliveryUncertain — true under either of two named ledger conditions: FREE_WRITE_FAILED (an unbilled/free write failed and may or may not exist) or DELIVERY_UNKNOWN (a paid row's delivery/charge outcome could not be confirmed); replayBlocked — true on either of two distinct refusal causes: the run's own result-found event counter didn't match its expected record (EXISTING_RESULT), or this run's claim key was already set from a prior attempt and automatic resurrection is unsupported (EXISTING_CLAIM); requested — the count of source rows counted within the read bound, including any later dropped for being oversized; never maxResults; usefulResults — every schema-valid business result transform() produced, counted before the delivery loop applies maxResults/budget caps (but after per-row 64 KiB oversized filtering, counted separately in failed); delivered/paid — confirmed, actually-written paid rows only; free — every free row actually written, uncapped total; failed — business results dropped for exceeding the 64 KiB per-row cap after decoration; businessPartialResults — counts all partial results transform() actually produced, computed directly on the raw business output before any oversized/delivery filtering; sourcePartial/sourcePartialReason — true/the disclosed reason when the source read itself stopped early (mirrors the partial_source notice's reason); sourceDroppedOversized — count of source rows dropped for exceeding the 64 KiB per-row read cap; budgetStopped/resultsCapped — true when this run's own delivery loop stopped early on the spend cap or the maxResults cap respectively (mirrors outcome, exposed as discrete booleans); oversizedDiagnosticsDropped/diagnosticsTruncated (see Evidence and boundaries); partialOverall; budgetMode/maxTotalChargeUsd; replaySafety; businessSummary (this product's own transform() summary object, verbatim); processedAt.
businessSummary (this Actor's own fields): totalSourceRows; resultsCount; diagnosticsCount — business-only diagnostics transform() itself produced, never including the runtime's own partial_source/source_rows_dropped notices layered on top; statusBreakdown ({competitor_assessed: N} when at least one domain result was produced — this Actor has one status bucket; {} when the run produced zero results, e.g. an empty or fully-excluded source); totalObservedQueries; partialQueryScopes — count of distinct query scopes that had at least one errored/malformed/conflicting page; excludedConflictingPages — count of pages entirely excluded from aggregation for genuine content conflict; domainsFound; observedAt — always null in every canary in this README, because this Actor never reads a source-side capture timestamp field at all; it only ever reflects a caller-supplied context.observedAt, which the shared runtime deliberately never synthesizes from wall-clock/processing time. A blank observedAt here is honest, not a bug.
Evidence and boundaries
Sampled coverage, never global market share. totalObservedQueries and coverageRatio describe only the query scopes actually present in your source batch — a domain's coverageRatio says nothing about its share of all possible searches, and this Actor never extrapolates beyond the queries you ran.
Global rank is only ever page-1-verified. bestGlobalPosition/weightedRank/a keyword's globalRank are derived exclusively from confirmed page-1 positions. A page-2+ position is preserved as bestPosition/bestPositionPage (a real, useful, page-scoped observation) but never converted into a guessed global rank — there is no page-size assumption anywhere in this calculation.
Organic results only — never ads, AI citations, or other blocks. Only the organicResults array is read; paid placements, AI-overview citations, knowledge-panel content, and any other non-organic block on the same page are never counted as an organic ranking signal, and never silently blended into coverage or rank.
Rank ties resolve deterministically, never by source-arrival order. See the Field dictionary entry above — a tied best position across two pages always picks the lower page number, and duplicate-vs-conflicting page detection is order-independent (identical content in a different array order is a duplicate, not a conflict).
Hard-failure priority. A hard failure signal (found:false, failed:true, a normalized status like failed/error/timed-out/aborted, or a non-200 statusCode) always overrides a contradictory found:true/partial:true claim on the same page — a source cannot simultaneously report "this page failed" and "this page is usable." A non-empty error/errors field with no hard-failure signal is retained as a harmless warning ONLY when the same row explicitly carries both found:true and partial:true; in every other case — including a valid SERP row with a bare error/errors value and no found:true/partial:true — it still produces the free source_row_error diagnostic with zero results for that page.
A single excluded conflicting page marks the WHOLE batch's results partial, not just the domains it touched. excludedConflictingPages is a single batch-wide counter, not a per-domain one — the moment it is greater than 0 anywhere in the run, partial:true is set on every domain result in that run, even a domain whose own supporting query scopes never had a conflicting page. A domain-specific errored/malformed page (without a genuine content conflict) or missing page-1 evidence can independently also set partial:true for that one domain, but the batch-wide conflict flag is the broader, dataset-level trigger.
No blanket 200-free-row cap, and businessSummary does not count every notice. The initial diagnostics array the shared runtime writes consists of this product's own report.diagnostics plus the runtime's own partial_source/source_rows_dropped notices, combined and then sliced to a 200-row write cap. businessSummary.diagnosticsCount counts business-only diagnostics — uncapped, so it can exceed 200. diagnosticsTruncated covers that combined (business + runtime-notice) list, not the business-only count. Separately, later notices — result_dropped_oversized, budget_stopped, max_results_reached — are written on top of the 200-row cap and are not counted against it. This actor's own mixed-boundary receipt (1000 synthetic-invalid-scope rows ahead of 2 real SERP rows, maxResults:1) confirms it exactly: businessSummary.diagnosticsCount: 998 (uncapped business count), 200 invalid_query_scope rows actually written to the free cap, plus 1 additional max_results_reached notice on top — 201 total free rows, diagnosticsTruncated: true, while usefulResults: 17 (every domain the batch actually produced, before the maxResults:1 cap dropped it down to delivered: 1).
Zero-charge cap normalization. A raw API maxTotalChargeUsd: 0 is normalized per a recorded observation — a positive value below every tier's price (Example 3 above used $0.005) reliably guarantees zero paid results, but the run's effective enforced cap should be inspected after the run starts, not simply trusted from the request.
Billing sequencing. Dataset-write happens before charge confirmation and is non-transactional. An ambiguous outcome finalizes the run as FAILED with no automatic retry and a possible unconfirmed row. There is no cross-run exactly-once delivery guarantee — a new run is new processing and can bill again.
Exact numeric and length caps, as coded, not paraphrased: MAX_EVIDENCE = 50 entries per result; MAX_REFERENCES = 50 (keywords, uniqueUrls, and sourceRowIndexes display caps, all independently tracked); MAX_SCOPE_STRING_LEN = 200 characters (searchQuery.term/countryCode/device/languageCode/locationUule); organic position must be an integer in 1..100. Shared runtime source-read bounds: at most 1000 rows, 4 MiB total source JSON, 100 rows per page, 64 KiB per row.
Source capture time is genuinely unknown when absent — never relabeled from another date or from processing time. This Actor does not read or parse any source-side capture/scrape timestamp field at all. businessSummary.observedAt reflects only a caller-supplied context.observedAt; the shared runtime deliberately never substitutes a synthetic "now" for it, so it is honestly blank in every canary in this README rather than fabricated from the moment this run happened to execute.
Decision routing
action: 'strong_repeated_competitor'→ prioritize for competitive content/backlink analysis; ≥2 query scopes and at least half your observed batch.action: 'partial_overlap_competitor'→ track, but do not yet treat as a primary competitor on this keyword set.action: 'single_query_appearance'→ informational only; never escalate a one-off appearance to "repeated competitor" status.globalRank: nullon a keyword occurrence → treat as page-relative-only evidence; never plot it on a global rank-tracking chart.- Free diagnostics (
invalid_query_scope,conflicting_duplicate_page, etc.) → route to a data-quality backlog for the upstream SERP scraper, not the competitive-research queue.
Commercial playbooks
- Competitive content gap analysis. Filter for
strong_repeated_competitordomains across your target keyword set and pull theiruniqueUrlsas a starting content-audit list. - Rank-tracking sanity check. Cross-reference
bestGlobalPositionagainst your own rank-tracker's numbers for the same query scopes as an independent, evidence-linked spot check. - SERP-feature displacement audit. Use
partialQueryScopes/excludedConflictingPagesto flag keyword sets where your SERP scraper's coverage itself looks unreliable, before drawing competitive conclusions from it. - Multi-market coverage comparison. Because query scope preserves
countryCode/device/languageCode/locationUule, compare the same keyword set's competitive set across markets without ever merging distinct scopes.
Integration recipes
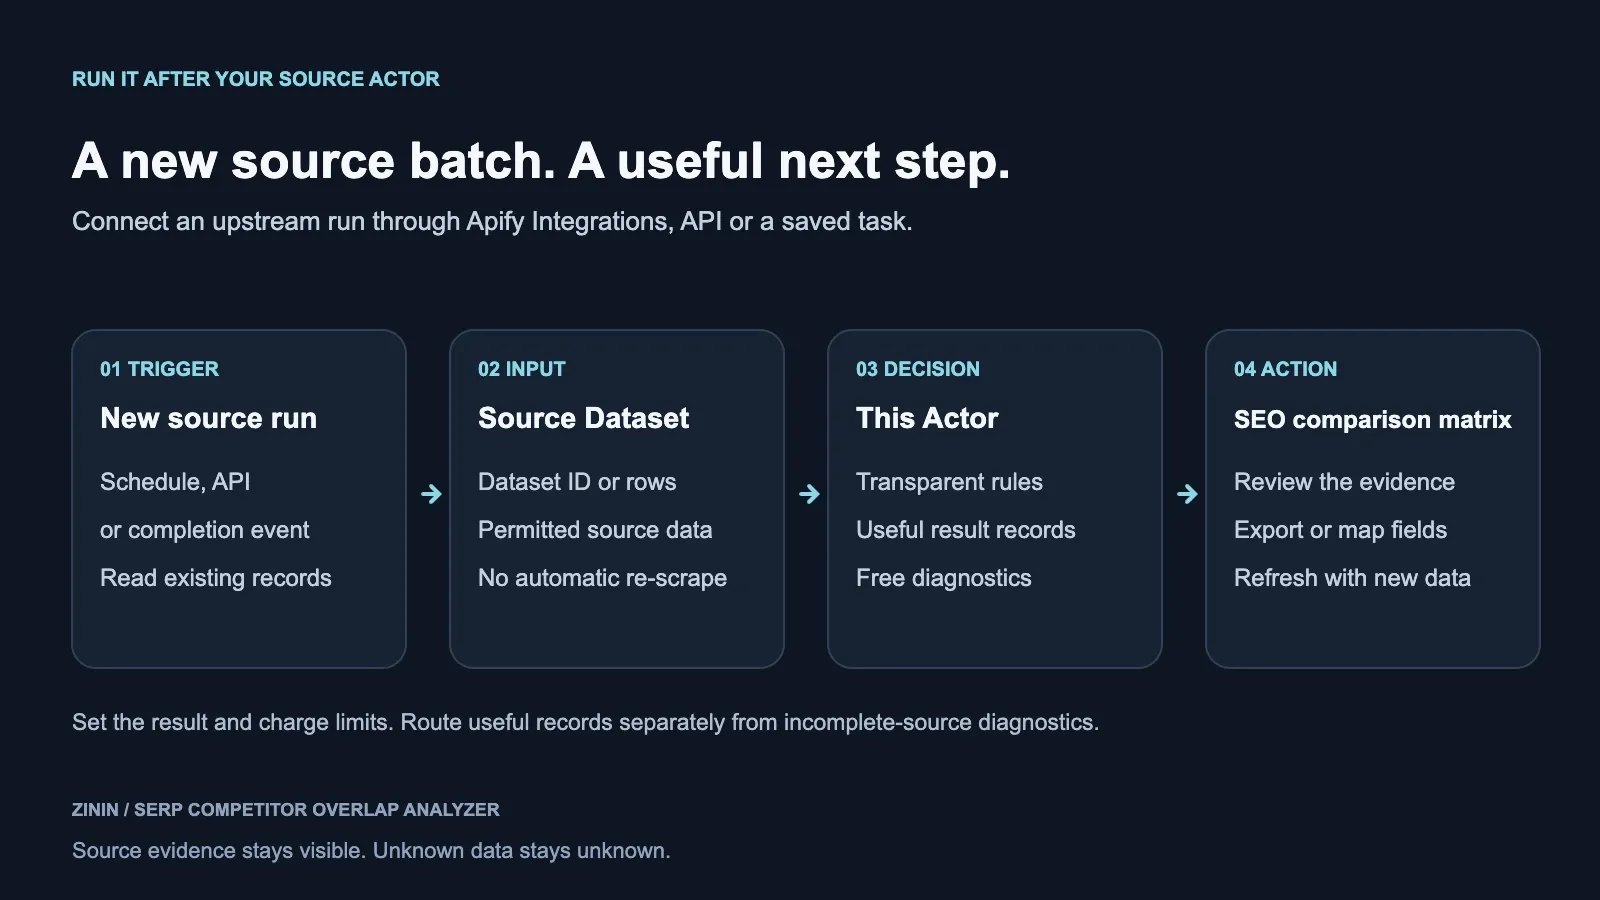
This Actor's ID is bRZ5G3R7VVMg4FZyx. The natural upstream source is Google Search Results Scraper (Actor ID nFJndFXA5zjCTuudP).
1. Console-native chaining (no code). On your SERP-scraper run page, open Integrations, add an "Actor/task run" action targeting this Actor, and let the Integrations UI populate the payload with {{resource.defaultDatasetId}}. Map that value explicitly into this Actor's datasetId field — not the generic payload pass-through alone — to request READ access under LIMITED_PERMISSIONS; the caller must already be authorized, and a private source can still deny access.
2. Direct webhook (POST /v2/webhooks), full recipe. Configure a webhook on your upstream SERP-scraper Actor for the ACTOR.RUN.SUCCEEDED event, scoped via condition.actorId, targeting this Actor's run-creation endpoint:
Submit this to POST https://api.apify.com/v2/webhooks with your own Authorization: Bearer <APIFY_TOKEN> header. The <APIFY_TOKEN> placeholder is never a literal token embedded in the template — it is filled in from your own secrets-provisioning store at the moment the webhook is registered, not an implicit platform template variable that resolves automatically. doNotRetry: true avoids a duplicate-charge risk from an automatic retry. datasetId is set explicitly — the resource picker or an authorized Integrations mapping can only request READ access; it never guarantees the platform actually grants it. A positive maxTotalChargeUsd on the request URL caps this chained run's spend; avoid the literal value 0 (see Evidence and boundaries) — a preserved positive value keeps enforcing your intended cap for the life of the run.
3. Generic automation tools (n8n, Zapier, Make, or your own tooling). Use a generic Apify/HTTP node to call run-sync-get-dataset-items on this Actor's ID with a JSON body containing datasetId and your chosen maxInputRows/maxResults — a plain authenticated HTTPS POST, no native Apify-integration support required. The same isApifyIntegration/payloadTemplate shape from recipe 2 applies to any integration definition your own tooling submits.
4. Export / content-planning mapping. Every run's Dataset supports CSV/Excel/JSON export via the Console or GET /v2/datasets/{datasetId}/items?format=csv. domain, keywordCoverageCount, bestGlobalPosition, weightedRank, and action alone drive a working competitor shortlist in a spreadsheet or content-planning import.
Operating guide
- Confirm your source batch shape first. Spot-check rows against Input contract — each needs a valid
searchQuery.term/countryCode/device, or you'll mostly getinvalid_query_scopediagnostics. - Start with a small
maxResultson a new source to confirm output matches expectations before a full batch. - Set
maxTotalChargeUsdvia the platform run option, and check its effective value after the run starts. For a guaranteed-zero-paid API call, use a small positive value below $0.014, not literal0— see Evidence and boundaries. - Read the
OUTPUT/SUMMARYrecord, not just the Dataset row count — it reportsdelivered/paid/free/failed, whetherbudgetStopped/resultsCappedended the run early, anddiagnosticsTruncated. - If a run finalizes
FAILED, inspect its Dataset andOUTPUTrecord before retrying — a blind retry can duplicate already-successful paid assessments. - Re-running is always new billing — no cross-run dedup key. Reserve it for a new or updated batch, not a routine safety retry.
FAQ
Does this Actor scrape Google itself? No. It only reads an existing SERP batch you or an upstream Actor already collected — no open-web fetch, no upstream Actor started.
Does coverageRatio measure market share? No. It is keywordCoverageCount / totalObservedQueries — a fact about this sampled batch's own query set, never a claim about the domain's share of all possible search traffic.
Does a page-2 ranking ever get reported as a global rank? No. globalRank is null for any keyword occurrence without verified page-1 evidence; the page-relative position is preserved separately as bestPosition/bestPositionPage, informational only.
Are ads or AI Overview citations ever counted as organic results? No. Only the organicResults array is read; any other block on the page is never treated as an organic ranking signal.
What does a FAILED run mean? The runtime can finalize FAILED for several distinct reasons, not one: a pricing-verification failure (PRICING_UNREADABLE/PRICING_UNSUPPORTED/DATASET_PRICE_UNSAFE/RESULT_PRICE_UNSAFE) before any processing starts; a spend/budget-ledger failure (BUDGET_UNREADABLE/COUNTER_UNREADABLE/CLAIM_UNKNOWN/TRANSPORT_UNSAFE); an ambiguous delivery outcome (DELIVERY_UNKNOWN/FREE_WRITE_FAILED, reflected in deliveryUncertain); the product module itself misbehaving (ALGORITHM_FAILED); the selected source being unreadable (SOURCE_UNAVAILABLE); or the final OUTPUT/SUMMARY write itself failing after results were already delivered (FINALIZATION_FAILED). None of these auto-retry — always inspect the Dataset and OUTPUT record first.
Is the "partial-columns" style example a demonstration of missing upstream data? No — see Output example 2. Every ranking field is identical to Example 1's real source snapshot; only the injected partial:true source flag (and its consequence, one added evidence entry and a lower confidence) is synthetic — not a simulation of real page removal.
Why did one run report 201 free rows instead of the usual 200-row diagnostic cap? The initial business-diagnostic list is capped at 200 entries when written, but a later result-size/cap notice like max_results_reached is added on top and not counted against that cap — see Evidence and boundaries for this actor's own confirmed 998/200/201 numbers.
Sources and rights
Public source example: XuRi68bcFSukcZOlT — a curated, non-sensitive snapshot of a real upstream Google Search Results run, with original values and provenance retained. All output examples and canary numbers in this README come from the product owner's own verification runs — cost to the owner, not customer sales or revenue.
Related tools
Related tools for adjacent AI and search visibility workflows, plus this Actor's own verified upstream source.
| Actor | What it does |
|---|---|
| AI Overview Citation Tracker | Pair it in the AI and search visibility workflow: track which public URLs and domains selected grounded AI models cite for buyer-supplied queries. |
| Domain Health Checker | Pair it in the AI and search visibility workflow: audit DNS resolution, MX, SPF, DMARC, name servers, and TLS for a list of domains. |
| LLM Brand Visibility Tracker | Pair it in the AI and search visibility workflow: for each query that matters, check whether AI assistants recommend your brand — and which competitors they mention instead. |
| Google Search Results Scraper | This Actor's own verified primary upstream source — the one used to capture the public example above. |
| Website Content Crawler | A content-crawler-adjacent workflow tool, not a direct SERP input: pull the actual page content behind a competitor domain's ranking URLs for a follow-on content audit. |


