Reddit Comments Scraper
Pricing
from $1.05 / 1,000 comment or posts
Reddit Comments Scraper
Scrape Reddit comments from post links without an API key or login: every comment as its own record with depth, parent, score, date and text, in thread order. Optional post record. Only-new mode returns just the comments written since your last run.
Pricing
from $1.05 / 1,000 comment or posts
Rating
0.0
(0)
Developer

Akatra
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
22 days ago
Last modified
Categories
Share
Reddit Comments Scraper: comments from any Reddit post
Scrape the comments of any public Reddit post without an API key, an app registration or a Reddit account. Paste post links and get every comment as its own record: text, score, date, the depth of the reply and the id of the comment it answers, in thread order, down to depth 10 (deeper branches are skipped). Optionally get the post itself as one more record.
Run it on a schedule with Only new items turned on and you get just the comments written since your last run.
Pay per result · No login, no API key · Public data only · LLM-ready JSON for AI agents (MCP)
🛠️ What does Reddit Comments Scraper do?
- 💬 Comment trees. Every comment is its own record with
postId,parentIdanddepth, in thread order: a comment, then its replies. - 🔗 Many posts at once. Paste several post links, one per line (
reddit.com/r/.../comments/...orredd.it/...). - 📄 The post too, if you want it. One extra record per post with title, text, score and link. Turn it off to save comments only.
- 🔢 Per-post limit. Set how many comments you want from each post.
- 🆕 Only new items mode. Schedule it on a busy thread and get just the comments written since the last run.
- 🔒 No user profile data. Only the public username shown next to a comment is saved. Profiles, karma and posting history are never collected.
This is the slim edition of Reddit Scraper: the comments of the posts you link, with a short input form. It does not read subreddit listings or searches.
- 🛡️ Built to get through blocking. Requests go out with a real browser fingerprint through rotating proxies, and a blocked request is retried from a fresh IP. A result that could not be completed is never charged.
What people use it for
- Customer voice and feedback. Read what people say under launch posts, reviews and complaint threads.
- Sentiment and topic analysis. Run your own models over comments with scores, timestamps and thread structure.
- Datasets for AI and NLP. Build question and answer datasets from discussions, keeping who answered what (
parentId,depth). - Thread monitoring. Watch a post you care about and send new comments to Slack, Google Sheets or your CRM.
- Research and moderation tools. Export whole discussions for archiving or analysis.
📊 What data can you extract?
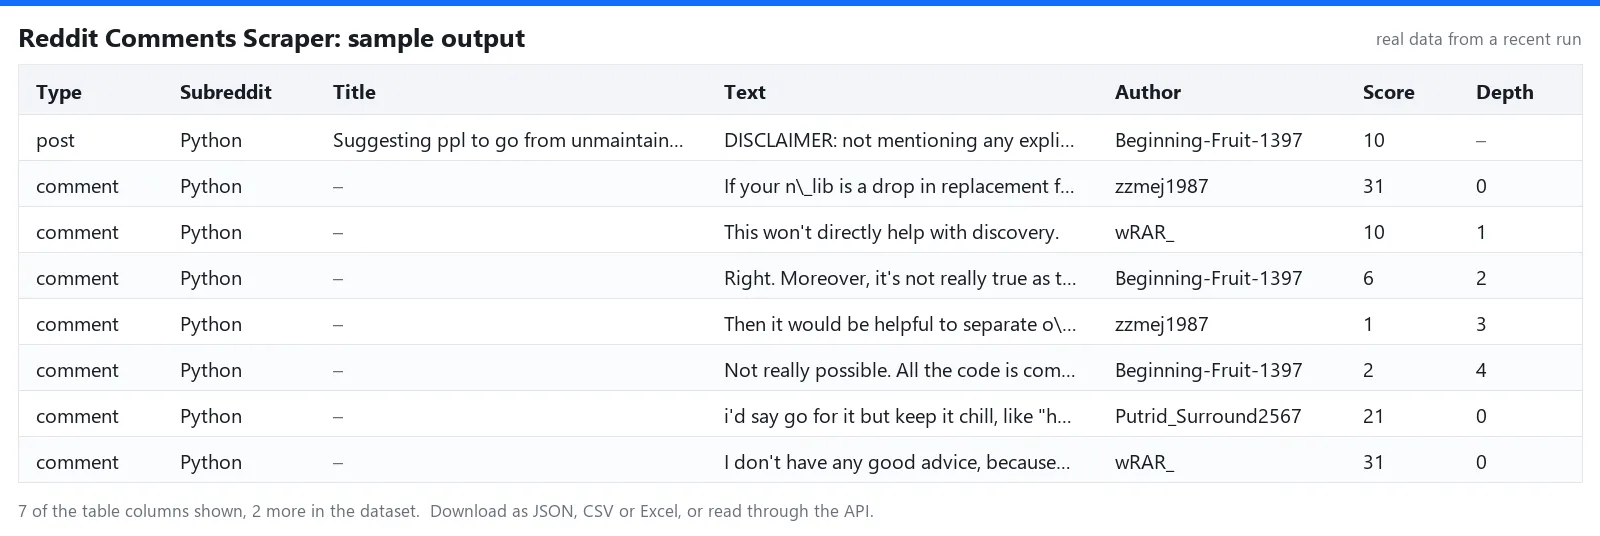
Every result is one JSON object (one row in CSV or Excel). The type field says whether it is a comment or a post.
Comment fields
| Field | Meaning |
|---|---|
type, id, url | comment, Reddit's comment id and the link to the comment |
postId, parentId, depth | The post it belongs to, the post or comment it replies to, and its depth (0 for top-level comments) |
text | The comment as Reddit markdown |
createdAt, score | When it was written (UTC) and its score (null while Reddit hides the score of new comments) |
isSubmitter | true when the author of the post wrote it |
author, subreddit | The public username and the community |
scrapedAt | When the record was collected (UTC) |
Post fields (with Include the post)
| Field | Meaning |
|---|---|
type, id, url | post, Reddit's post id and the link to the post |
subreddit, title | The community and the post title |
text | The post body as Reddit markdown, null for link and image posts without text |
createdAt | When the post was created (UTC) |
score, upvoteRatio, numComments | Net score, share of upvotes (0 to 1) and number of comments |
flair, isNsfw, isSpoiler, isStickied, isVideo | The post flair and flags |
linkUrl, domain, thumbnailUrl, imageUrls, videoUrl | The outside link, its domain and the media of the post |
isCrosspost, crosspostParentId, crosspostParentSubreddit | Whether the post is a crosspost, and the id and subreddit of the original post |
author | The public username of the poster ([deleted] for deleted accounts) |
searchQuery | Always null here (it is filled by searches in Reddit Scraper and Reddit Search Scraper) |
scrapedAt | When the record was collected (UTC) |
A field that does not exist for a record is null.
🚀 How to use Reddit Comments Scraper
- Create a free Apify account and open this Actor.
- Paste the post links, one per line.
- Set max comments per post.
- Leave Include the post on if you want a record for the post itself, or turn it off for comments only.
- Run it and download the results as JSON, CSV or Excel, or read them through the API.
📥 Input example (JSON)
📤 Sample output (JSON)
A comment:
A reply to it:
The post (with Include the post):
🤖 Use it with AI agents, MCP and the API
The output is clean JSON with stable field names, ready for LLM pipelines, RAG and agent tools without extra parsing.
- AI agents and MCP (Claude, ChatGPT, Cursor and others). Add the Apify MCP server with this Actor as a tool:
https://mcp.apify.com?tools=akatra/reddit-comments-scraper. The agent can then run it and read the results by itself. - API. Start a run and get the results in a single call:
- No-code tools and SDKs. Works with Make, n8n, Zapier and LangChain through Apify's integrations, and with the Apify clients for Python and JavaScript. Schedule it and send the results to a webhook, Google Sheets or your own database.
💰 Pricing: pay per result
You pay per result: every comment and every post record saved to the dataset is one result. See the price on the Pricing tab. Runs that return nothing cost only a tiny start fee. There is no subscription or rental fee. New to Apify? The free plan includes $5 of platform credit every month, enough for about 3,300 comments with this Actor, and no credit card is needed.
🚦 Run status and error messages
Every run ends with a plain status message, so automated workflows (API, Make, n8n, AI agents) can tell what happened without reading the log:
| Situation | What you get |
|---|---|
| Finished normally | Saved N posts and M comments., or Saved M comments. when the post record is off or was already returned |
| Nothing matched | The run succeeds with No results saved. Check that the post links are public and still available, or turn off 'Only new items'. You pay only the start fee. |
| Missing or invalid input | The run fails at once with Invalid input: … naming the field to fix, for example Add at least one post link., a link that is not a Reddit post, or 'subreddits' is not supported in this Actor; use Reddit Scraper. Nothing is scraped. |
| Post link not available | Post abc123 is not available (it may be deleted, removed or private). The other posts are still read. |
| Reddit blocked every request | The run succeeds with Reddit blocked the requests for post abc123, so nothing was saved. You were not charged. Please try again later. |
| Some comments stayed blocked | Results may be incomplete for: post abc123. Run again to get the rest. |
| Your maximum charge is reached | Stops cleanly with Stopped at your maximum charge limit. Everything saved so far stays in the dataset. |
ℹ️ Good to know
- Max comments per post applies to each post. Comments come in thread order, a comment followed by its replies, and the limit counts in that order, so you get the comments from the start of the thread.
- Replies nested deeper than 10 levels are skipped. Deleted and removed comments are skipped and not charged. The comment
textand the posttextare Reddit markdown as the author wrote it. - Include the post adds one post record per link, and it counts as a result. Turn it off to pay for comments only.
- Only new items remembers each post link between runs. The first run returns the post and its comments up to your limit. Later runs return only comments that were not returned before and were written since 15 minutes before the previous run started; the post record is returned once.
- Posts with many comments need several requests, so a run on a very large thread takes longer. If a post has fewer usable comments than your limit, you get all of them.
- This Actor does not read subreddit listings or searches. For those use the full Reddit Scraper.
- How it reads Reddit: the Actor does not use Reddit's official API. It reads the public pages Reddit shows to any visitor who is not logged in, with an anonymous visitor session, through residential IPs. Reddit's robots.txt disallows automated access, and Reddit can change or close this way of reading without notice. If that happens the run ends with a status message that Reddit blocked the requests, and you are not charged.
- If you set a maximum charge for a run, the scraper stops as soon as that limit is reached.
- Privacy: only content and the public username shown next to it are collected. User profiles, karma, account age and posting history are never read.
📝 Changelog
- 2026-10-03 First release: comment trees from post links, optional post record and only-new mode.
⚖️ Legal and privacy
This scraper is an independent tool and is not affiliated with, endorsed by, or sponsored by Reddit. Reddit and its logo are trademarks of their owner and are used here only to describe which website the tool works with. Reddit's robots.txt disallows automated access and Reddit's terms of use restrict it; the Actor is not an official Reddit tool and does not use Reddit's API. Your use of the data is subject to Reddit's terms and to the laws that apply to you.
The Actor reads only pages that are public without logging in. Posts and comments are written by Reddit users under pseudonyms and can contain personal information their authors chose to publish. How you store and use the data is your responsibility: follow the laws that apply to you, such as GDPR and CCPA.
🔗 More scrapers from Akatra
- Indeed Jobs Scraper: 💼 job ads from Indeed in 30 countries, with yearly salary and only-new mode.
- Google News Scraper: 📰 news by keyword or topic in 50 editions, with the real article URLs.
- Google Trends Scraper: 📈 interest over time, by region, and rising related queries.
- Google Ads Transparency Scraper: 🔎 every ad a company runs on Google, with regions and dates.
- Airbnb Listings Scraper: 🏠 Airbnb listings with prices, ratings and map coordinates.
- YouTube Transcript Scraper: 🎬 video transcripts as clean text and timestamped lines.
💬 Support
Found a bug or need a field that is missing? Open an issue on the Issues tab and we usually reply within a day.
🔗 Need more?
Subreddit listings, searches and the full set of options are in the complete Reddit Scraper.