
Reddit Posts & Search Scraper
Pricing
from $1.00 / 1,000 post results
Reddit Posts & Search Scraper
Search public Reddit posts by keyword, scrape subreddit feeds, or paste post and search URLs. One deduplicated row per post with title, text, author, community, score, comments, flair, media, timestamps and source lineage. One global limit. No Reddit login or API key.
Pricing
from $1.00 / 1,000 post results
Rating
0.0
(0)
Developer
Delowar Munna
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
5 days ago
Last modified
Categories
Share
Search public Reddit posts by keyword, scrape subreddit feeds, or paste known Reddit post/search URLs. Every match becomes one clean, deduplicated post row with text, author, community, engagement, flair, media, timestamps and source lineage. No Reddit account, cookies or API key required.
- One global limit.
maxResultsbounds the whole run, across every subreddit, query and URL. - One row per post, whichever source found it. A post matched by two queries and its subreddit is delivered once, with every matching query and community on the row.
- Built for scheduled runs. Skip lists for IDs and URLs, a
publishedAfterboundary that stops paging anewfeed the moment it reaches old posts, and a chronological sort by default. - Honest about depth. Reddit's public search returns at most about 250 posts per query or community for one sort and time window. The run says so per source instead of paging in circles.
Comments are a separate Actor: Reddit Comments Scraper
takes the url or postId from these rows. User histories belong to the Reddit User Scraper.
Quick start
Subreddits and keyword searches together:
Four sources, 200 posts at most, newest first, deduplicated across all four. The run summary in the key-value store says how many candidates each source produced and where each one stopped.
Reddit URLs, with filters:
A search restricted to r/Python plus two direct posts. The search URL carries its own query; the two post URLs are looked up directly. Posts under 10 points, non-text posts and posts mentioning "hiring" are dropped before they are saved, and are not charged.
A daily scheduled run:
Each community stops paging once it reaches posts older than a day, and the IDs from the previous run are skipped. See Incremental scheduled runs.
Search Reddit
Put keywords or Reddit search syntax in searchQueries, one query per line:
Each query is a site-wide Reddit search. sortBy chooses the ordering Reddit applies (relevance,
hot, top, new, comments), timeFilter the window. A search URL in startUrls works the same
way and keeps the sort and window it carries.
Scrape subreddits
Put community names in subreddits in any spelling — python, r/Python,
https://www.reddit.com/r/python/ — or a subreddit URL with a sort segment such as
https://www.reddit.com/r/python/top/?t=week, which keeps that sort and window for that source
only. rising and controversial are feed orderings; where a surface lacks them the run substitutes
hot / top and says so in the log.
r/all and r/popular are aggregate feeds rather than communities and are not supported.
Direct posts and search URLs
startUrls accepts every common form of a post reference — full post URLs on any Reddit host,
redd.it short links, /r/<sub>/s/ share links, t3_ fullnames and bare IDs — plus subreddit URLs
and search URLs (https://www.reddit.com/search/?q=…, https://www.reddit.com/r/python/search/?q=…&restrict_sr=1).
Anything else (a user profile, a wiki page, a multireddit) is reported as invalid with a reason, never guessed at.
Input reference
| Field | Default | What it does |
|---|---|---|
subreddits | [] | Communities to scrape (names, r/name, or URLs) |
searchQueries | [] | Site-wide keyword searches |
startUrls | [] | Post, subreddit or search URLs |
maxResults | 500 | Global ceiling on unique posts delivered by the run |
sortBy | new | new, hot, top, relevance, comments, rising, controversial |
timeFilter | all | hour … all; applies to top, relevance, comments |
publishedAfter | — | ISO date or relative window (24h, 7d, 2w); stops a new feed at the boundary |
publishedBefore | — | Upper date bound |
includeNsfw | false | Include over-18 posts |
minScore, minComments | — | Engagement floors |
flairs, authors | [] | Allow-lists (case-insensitive) |
includeKeywords, excludeKeywords | [] | Substring filters on title and body |
postTypes | [] | text, link, image, video, gallery, poll, crosspost |
skipPostIds, skipUrls | [] | Incremental skip lists — never saved, never charged |
enrichPostDetails | true | Full post details on every row — body, flair, post type, media and flags — at no extra charge |
maxResultsPerSource | 250 | Fairness cap per source |
maxPagesPerSource | 20 | Crawl ceiling per source (7 posts per page on Reddit's public search) |
maxConcurrency | 3 | Sources paged in parallel (1–5) |
requestDelayMs | — | Extra pacing on top of the built-in rate control |
debugMode | false | Verbose logging |
proxyConfiguration | Apify Datacenter | See the proxy policy below |
At least one of subreddits, searchQueries or startUrls is required. Every filter keeps a post
whose value Reddit does not publish — an unknown score is not a low score.
Global max and cost control
You are charged once per unique post saved to the dataset, and nothing else: not duplicates across
sources, not posts your filters removed, not skip-list matches, not posts discovered past the limit,
not invalid inputs, not sources that failed, not empty searches, not the run summaries. maxResults
is the only number you need to bound a run. If your Apify account has a per-run spending limit, the
run stops fetching the moment it is met rather than working on unpaid.
Incremental scheduled runs
- Sort by
new(the default). - Set
publishedAfterto the interval —24hfor a daily schedule,7dfor weekly. Eachnewfeed stops paging as soon as it reaches posts older than that, so a quiet subreddit costs one page. - For exact de-duplication across runs, pass the previous run's
postIdvalues asskipPostIds(or itsurlvalues asskipUrls). Skipped posts are neither saved nor charged.
Overlapping sources within one run are deduplicated automatically; the matchedQueries,
matchedSubreddits and sourceInputs fields on each row say which inputs found it.
Output fields
One flat row per post, recordType: "post".
| Field | Meaning |
|---|---|
postId, postFullId | Reddit's ID and t3_ fullname — the dedupe key |
url, permalink | Canonical post URL and its path |
title, text | Title and body text (plain text; "" for a post with no body) |
authorUsername, authorId | Author (null when deleted) |
subreddit, subredditPrefixed, subredditId | Community |
flair | Post flair text |
score, upvoteRatio, commentCount, awardCount | Engagement |
createdAt, editedAt | ISO timestamps |
isNsfw, isSpoiler, isStickied, isLocked, isArchived, isQuarantinedSubreddit, isDeletedOrRemoved | Flags |
postType | text, link, image, video, gallery, poll, crosspost |
outboundUrl, domain, thumbnailUrl, mediaUrls, crosspostParentId | Link and media |
detailLevel | full (all fields) or listing (see below) |
matchedQueries, matchedSubreddits, sourceInputs | Which inputs found the post |
capturedSequence, scrapedAt | Capture order and time |
null always means "not published by the source", never a guess.
Listing rows. Reddit's public listing carries the identity, engagement and timestamp fields
only. With enrichPostDetails on (the default) the Actor reads every source through a search
service that returns full records, looks up direct post URLs one by one, and every row is
detailLevel: "full". With it off, or when the detail service is unavailable for a run, rows are
detailLevel: "listing" and text, flair, postType, upvoteRatio, editedAt, the media
fields and the stickied/locked flags are null. The run log says which applied.
Dataset views and sample records
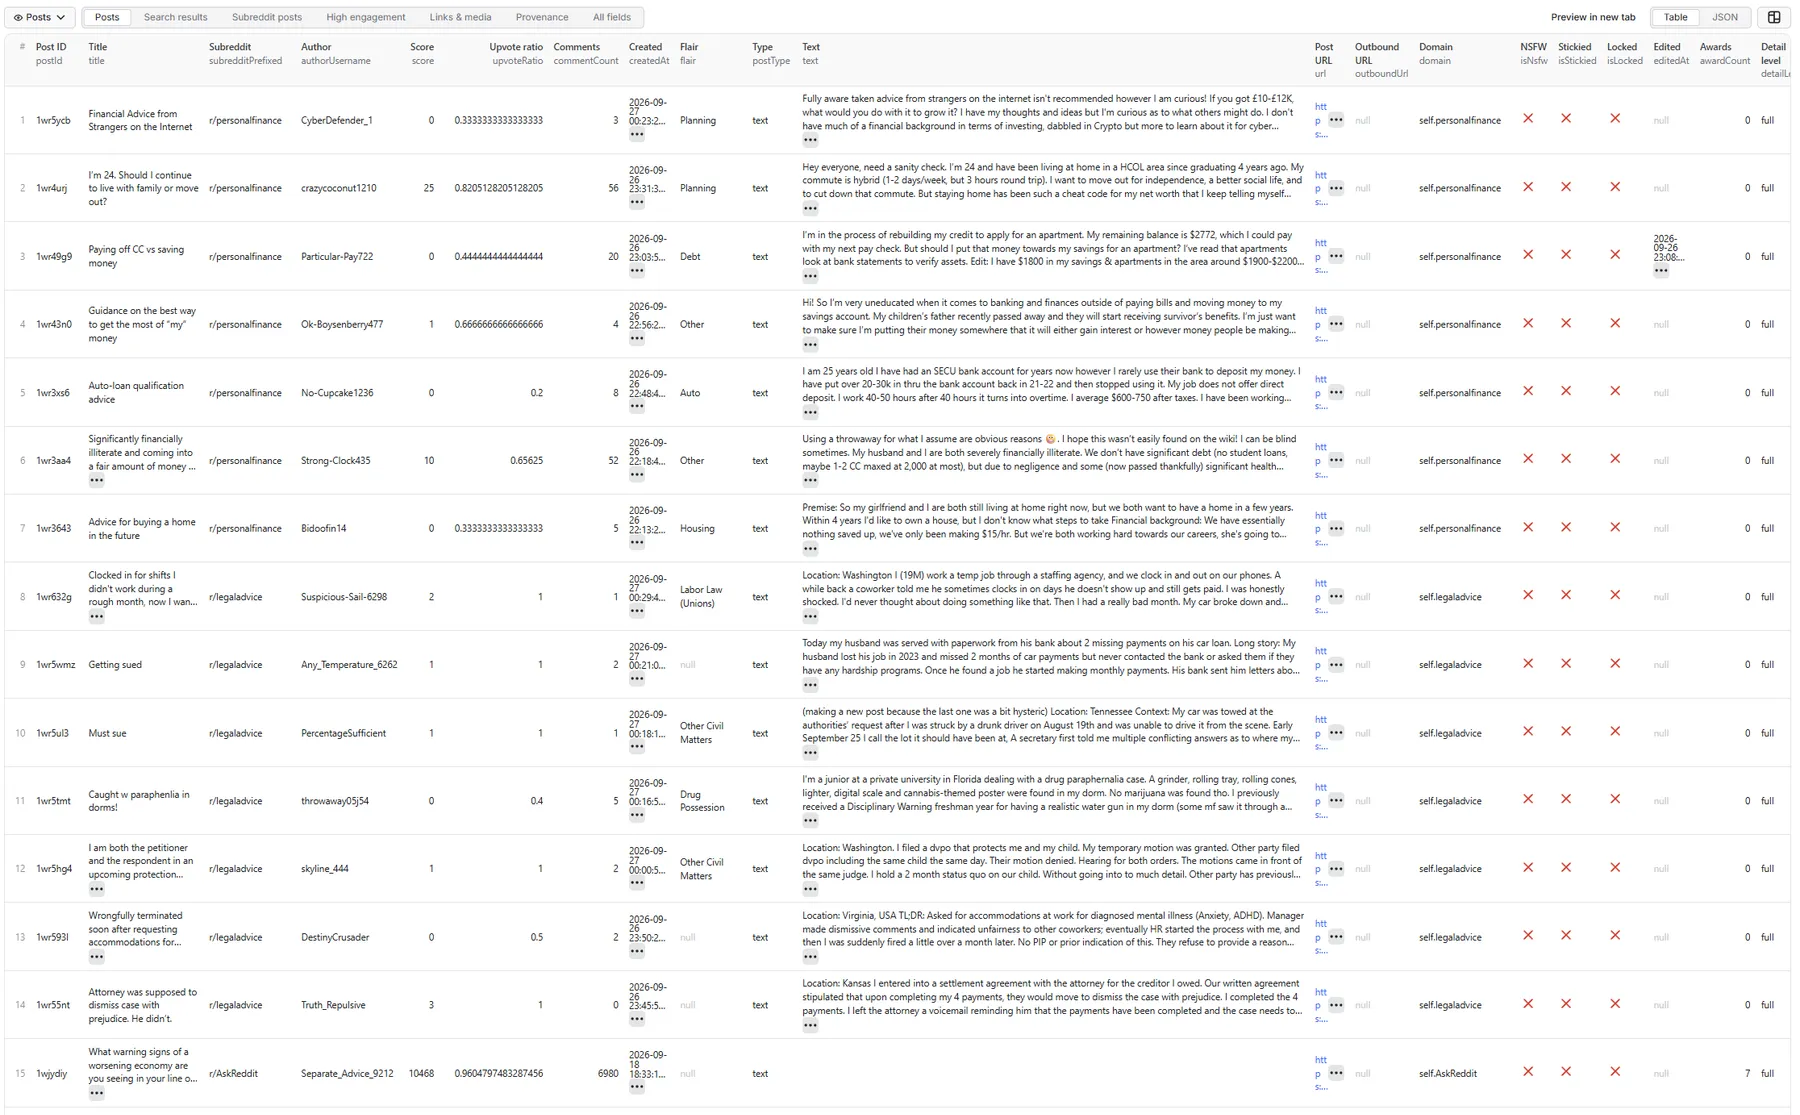
The dataset has six views. They are projections of the same dataset, so no row appears twice. Below is one real record for each view, from a 150-post run over r/personalfinance, r/legaladvice, two keyword searches, an r/Python search URL and two direct posts. Usernames are anonymised.
Posts — every field
The full schema. This is a text post found by the r/Python search URL:
Search results
Rows found by a query, with the queries that matched:
Subreddit posts
Rows read from a community feed:
High engagement
Score, upvote ratio, comments and awards, compact. This is a direct post URL:
Links & media
Outbound URL, domain, thumbnail and media URLs for link and media posts:
Provenance
Which inputs produced each row, in capture order. This row came from a redd.it short link:
Pricing
Pay per result: one post-result event per unique post saved, with full post details included.
There is no start fee and no charge for an empty run. The rate per post depends on your Apify
plan. This README deliberately quotes no figures — the Pricing tab shows the live rate for each plan.
Limits and Reddit search depth
- Reddit's public search returns at most about 250 posts per query or community for one sort
and time window (measured: 36 pages of 7, then no next page). A source that hits it is reported
as
truncationReason: "search-depth-limit"inSOURCE_SUMMARY. To go deeper, split the source:sortBy: "top"withtimeFilter: "week","month","year"are three different 250s. maxResultsPerSourcedefaults to that ceiling.- The search surfaces have no
risingorcontroversialordering. With full post details on (the default) those sorts are substituted withhot/topand the run log says so; with details off they are honoured where a subreddit's own feed supports them. - Private, quarantined-behind-a-wall and banned communities answer "not found".
No-login / proxy posture
The Actor asks Reddit's public, server-rendered search surface as a plainly named client — no account, no cookies, no API key, no browser. It paces itself to Reddit's published logged-out budget and rests an exit that draws a challenge page.
🚦 Proxy policy
Use Apify Datacenter proxy (the default) or no proxy. Both work for Reddit's public search surface at this Actor's conservative concurrency.
Apify Residential proxy is not supported. The run fails at startup if apifyProxyGroups
includes RESIDENTIAL: in pay-per-event Actors, residential bandwidth is billed to the developer
rather than to the run, and Reddit serves the same results to datacenter addresses. If you
genuinely need residential routing, supply your own provider under Custom proxy URLs — that
traffic goes through your account and is honoured in full:
Troubleshooting
| Symptom | Where to look | Likely cause |
|---|---|---|
Fewer posts than maxResults | SOURCE_SUMMARY.truncationReason | search-depth-limit (Reddit's ceiling), publishedAfter, maxResultsPerSource, or the sources simply ran out |
A source is failed: not-found | run log | the community does not exist, is private, or the search URL had no query |
A source is failed: blocked / challenge | RUN_SUMMARY.blocks, challenges | Reddit refused the exit; RETRY_INPUT in the key-value store is a ready-to-run input for those sources |
detailLevel: "listing" rows | run log | enrichment off, or the detail service was unavailable for the run |
text is "" | — | the post has no body (a title-only or link post); null would mean unknown |
Rows have matchedQueries: [] | sourceInputs | the post came from a subreddit or a direct URL, not a search |
API and integrations
Call the Actor with the JSON input above through the Apify API, a webhook or a schedule. Small
runs are fine synchronously (run-sync-get-dataset-items); use asynchronous runs for hundreds of
posts. Rows are pushed as they are found, so a webhook on ACTOR.RUN.SUCCEEDED sees the whole
dataset and a partial run keeps what it captured. Three key-value records accompany every run:
RUN_SUMMARY (counts, stop reason, economics), SOURCE_SUMMARY (one record per source) and,
when relevant, RETRY_INPUT.
Responsible use
This Actor collects public Reddit content only. You are responsible for lawful use, for privacy and data-protection obligations, for Reddit's terms, and for how you handle personal data downstream. Deleted or removed content is not reconstructed from anywhere.
Changelog
- 1.0 — Initial release: subreddits, search queries and Reddit URLs in; one deduplicated post
row out; global limit, incremental skip lists,
publishedAfterboundary, full post details, six dataset views, pay per result.


