
Job Scraper - LinkedIn Jobs, Indeed & Multi-City Job Alerts
Pricing
from $1.85 / 1,000 results
Job Scraper - LinkedIn Jobs, Indeed & Multi-City Job Alerts
Job scraper for LinkedIn Jobs and Indeed in one run. Search many keywords across up to 20 cities, filter titles, companies and salary, dedupe across boards, and schedule alerts that return only new jobs. Exports salary, company data and apply links. $2 per 1,000 jobs, no login.
Pricing
from $1.85 / 1,000 results
Rating
5.0
(1)
Developer
Group Oject
Maintained by CommunityActor stats
1
Bookmarked
32
Total users
9
Monthly active users
21 hours ago
Last modified
Categories
Share
Scrape LinkedIn Jobs and Indeed in one run, across up to 20 cities, and get one clean, deduplicated row per job with salary, company, description and apply link. Schedule it to receive only new jobs. No job-board login, cookies or API key.
One job scraper instead of several: search many keywords and locations, choose your job boards, filter out irrelevant titles and companies, and export to CSV, Excel, JSON or straight into your pipeline. Indeed and LinkedIn are the tested sources; Google Jobs, Glassdoor, ZipRecruiter, Bayt and Naukri are optional beta boards.
Run the job scraper | Pricing | Input fields
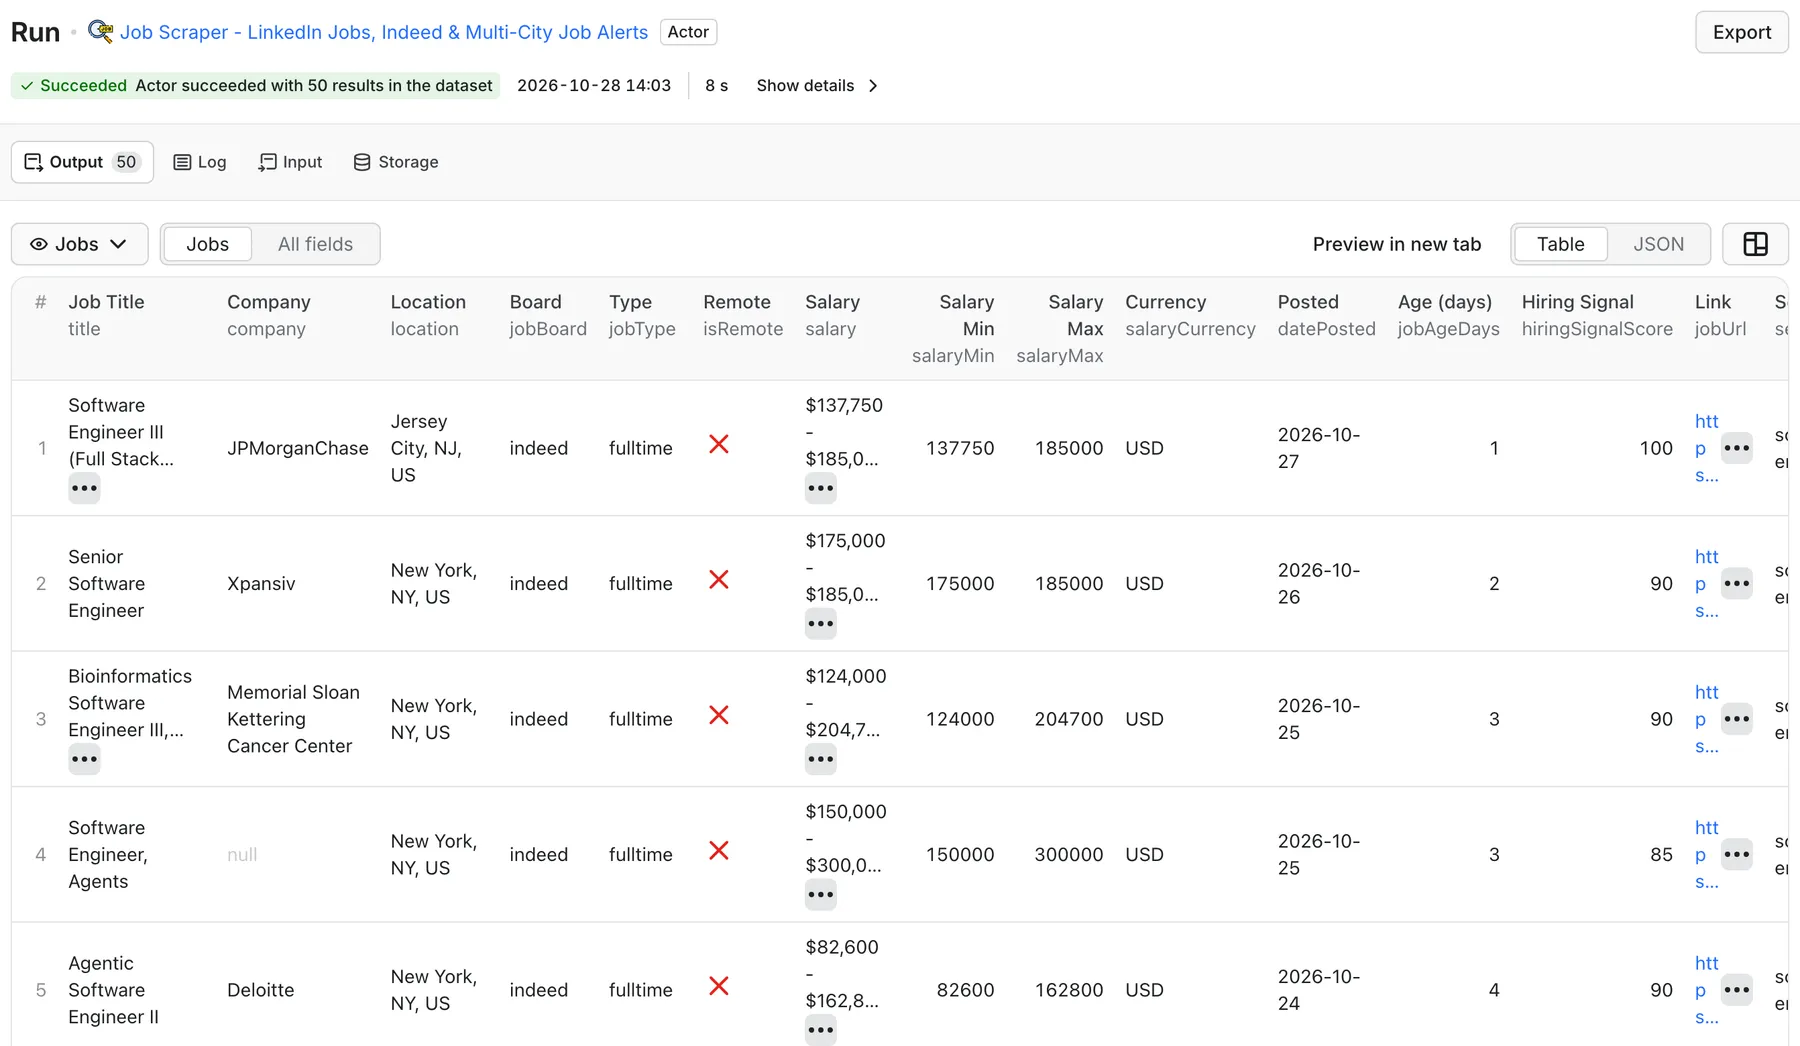
Real output from a default run of Job Scraper in Apify Console.
What can this job scraper do?
- LinkedIn jobs scraper + Indeed scraper in one dataset - pick one board or several; every row has the same schema and a
jobBoardfield. - Multi-keyword, multi-city search - several search terms and up to 20 locations per run. Each row keeps the
searchTermandsearchLocationthat found it. - Job alerts that only return new jobs - turn on
onlyNewJobswith astateKey, schedule the run, and each run delivers only jobs not delivered before. - Relevance filters - include/exclude title keywords, exclude exact company names, require salary data, remote only, job type, posted within N hours, search radius, Easy Apply.
- Salary data - min/max, currency, interval, plus optional conversion of hourly/daily/weekly/monthly pay to annual estimates.
- Cross-board deduplication - shared listing URLs and shared direct-apply URLs are merged so you do not pay twice for the same posting.
- Transparent diagnostics - per board/term/location outcomes (
returned,delivered,durationSeconds, error) inSEARCH-OUTCOMES.
What data can I extract?
| Field | Example / meaning |
|---|---|
title, company, location | Job title, employer, job location |
jobBoard | indeed, linkedin, google, glassdoor, zip_recruiter, bayt, naukri |
jobType, isRemote | Employment type and remote flag (null when the board does not say) |
salary, salaryMin, salaryMax, salaryCurrency, salaryInterval, salarySource | Pay range as published or extracted by the source |
datePosted, jobAgeDays | Posting date and age in days |
jobUrl, directApplyUrl | Listing URL and the employer's direct application URL when available |
companyUrl, companyWebsite, companyIndustry, companySize, companyRevenue, companyRating, companyReviewsCount, companyLogo | Company details when the board supplies them (mostly Indeed) |
description | Job description in Markdown or HTML |
skills, emails, jobLevel, jobFunction, experienceRange, vacancyCount, easyApply, listingType | Extra fields some boards provide |
hiringSignalScore | 0-100 freshness/completeness heuristic (not proof of buying intent) |
searchTerm, searchLocation, scrapedAt | Provenance for every row |
Fields are only filled when the source board publishes them. Missing salary is not zero salary.
How much does it cost to scrape jobs?
Pay per result: you pay for jobs saved to the dataset, not for searches that return nothing.
| Apify plan discount tier | Price per 1,000 jobs |
|---|---|
| Free / no discount | $2.00 |
| Bronze | $1.95 |
| Silver | $1.90 |
| Gold, Platinum, Diamond | $1.85 |
- 100 jobs = $0.20, 1,000 jobs = $2.00, 10,000 jobs = $20 (base rate).
- Plus a tiny Actor start charge of $0.00005 per GB of memory per run.
maxItems(default 100) caps output, and the Actor also stops at your maximum run charge.
The Pricing tab is authoritative for current rates.
How to scrape LinkedIn and Indeed jobs
- Open the input form.
- Enter a Search term (for example
software engineer) and a Location (or a list of Multiple locations). - Choose Job boards: Indeed (default), LinkedIn, or both. Beta boards are optional.
- Set Max results per board and Max total jobs. Start small (20 / 50) to check relevance.
- Click Start, then export the dataset as CSV, Excel or JSON, or read it through the API.
- For job alerts, enable Only new jobs, set a Monitor state key, save the input as a task and add a schedule.
Input example
More ready-made inputs: remote AI jobs, healthcare, finance, sales hiring alerts, salary research and others in examples/.
Output example
The run's key-value store also holds SUMMARY (totals, per-board counts, warnings), SEARCH-OUTCOMES (one entry per board/term/location search) and SEARCH-PROGRESS (live checkpoint).
Supported job boards
| Board | Status | Notes |
|---|---|---|
| Indeed | Tested default | Most reliable and fastest. Use countryIndeed for non-US searches. Company details included. |
| Tested | Public guest job search, no login. Slower (pages of about 10 jobs with pauses between them). Enable linkedinFetchDescription for full descriptions and direct apply URLs (slower again). | |
| Google Jobs | Beta | Uses Apify's Google SERP proxy; up to 10 jobs per query; descriptions may be shortened. |
| Glassdoor, ZipRecruiter, Bayt, Naukri | Beta | Often challenged by anti-bot systems; may return no data even with a residential proxy. |
Job alerts: get only new jobs on a schedule
- Configure your search and set
"onlyNewJobs": trueand a stable"stateKey"such as"sales-hiring-alerts". - Save it as an Apify task and add a schedule (for example every morning).
- The first run delivers all matches; later runs deliver only jobs that were not delivered before under that state key. Jobs removed by filters or the output cap are not marked as seen.
- Send new rows to Slack, email, Google Sheets or a CRM with an Apify webhook, Make, Zapier or n8n. The Actor itself does not send notifications.
A repeat run that returns zero rows usually means "no new jobs". Check SEARCH-OUTCOMES to tell that apart from a source failure. Do not run two monitors with the same stateKey at the same time.
Keep big runs fast and reliable
Searches run one after another: the number of searches is search terms x locations x job boards. Each board search is stopped after 120 seconds, and the whole run is limited by the run timeout (1 hour by default).
| Plan | Searches | Typical fit |
|---|---|---|
| 1 term, 1 city, Indeed | 1 | Seconds |
| 3 terms, 5 cities, Indeed | 15 | Comfortable |
| 3 terms, 5 cities, Indeed + LinkedIn | 30 | Keep LinkedIn at 20-50 results per search |
| 5 terms, 20 cities, 2+ boards | 200+ | Split into several saved tasks |
Tips:
- Keep LinkedIn at 100 results per search or fewer; add more locations or keywords instead of raising
maxResultsPerSite. - Leave
linkedinFetchDescriptionoff unless you need full LinkedIn text. - Add beta boards one at a time and check
SEARCH-OUTCOMESbefore scheduling them. - Jobs are saved after every search, so results collected before a timeout stay in the dataset.
Use the job scraper via API, Python or JavaScript
Python
JavaScript
Integrations: Make, Zapier, n8n, Google Sheets, Airbyte, webhooks and the Apify API. In n8n, call the Actor by its ID LzsIpToRTUZSnqjbS, wait for the run to finish, then read the dataset and upsert rows by jobUrl.
AI agents / MCP: the Actor can be called from the Apify MCP server, so Claude, ChatGPT, Cursor or your own agent can ask for "remote senior Python jobs posted this week with salary ranges" and get structured rows back.
Who uses it
- Recruiters and sourcers - fresh openings from several boards in one sheet.
- Job seekers and career coaches - repeatable searches with daily new-job alerts.
- Job-board and newsletter builders - a feed of niche jobs by keyword and city.
- Sales and lead generation teams - companies hiring for roles that signal a need for your product.
- Labor-market and salary researchers - salary ranges and posting volume by role and city.
FAQ
Is it legal to scrape LinkedIn and Indeed jobs? The Actor collects publicly listed job postings without logging in. Job postings are generally not personal data, but you are responsible for how you use the data and for complying with applicable laws and the boards' terms. Do not use it to collect private profiles.
Do I need a LinkedIn or Indeed account, cookies or an API key? No. You only need an Apify account (and an Apify API token for programmatic calls).
Do I need a proxy?
Apify Proxy is used automatically. For LinkedIn or the beta boards, a residential proxy can help: {"useApifyProxy": true, "apifyProxyGroups": ["RESIDENTIAL"]}. The proxyConfiguration field is stored encrypted.
Why did I get fewer jobs than I asked for?
maxResultsPerSite and maxItems are ceilings. Filters, deduplication, the run-charge limit and what the board actually has all reduce output.
One board returned nothing. Did the run fail?
No, as long as another board delivered jobs. SEARCH-OUTCOMES shows each board's status (ok, empty, failed) and SUMMARY.partialResults is true. If every search fails, the run fails.
My run timed out. What should I change? Reduce terms x locations x boards per run (see "Keep big runs fast and reliable"), keep LinkedIn at 100 results per search or fewer, and split large plans into several scheduled tasks. Jobs saved before the timeout remain in the dataset.
Can I search outside the US?
Yes. Set the location and countryIndeed (for example UK, Canada, Germany). Naukri (India) and Bayt (Middle East) are optional beta boards.
Related job scrapers
- Greenhouse & Lever Jobs Scraper - jobs straight from company ATS career boards, with hiring-signal scoring.
- Teamtailor Jobs Scraper - jobs from any Teamtailor career site.
- SmartRecruiters Jobs Scraper - jobs from SmartRecruiters company boards.
Feedback and support
Found a problem or missing field? Open an issue with the board, your non-sensitive input and the run ID. Never post API tokens or proxy passwords. If the scraper is useful, a review helps other users find it.
Built on the open-source python-jobspy library. Old API identifier groupoject~indeed-jobs-scraper has moved: use the Actor ID LzsIpToRTUZSnqjbS. See CHANGELOG.md.


