

Teamtailor Jobs Scraper - Career Page Jobs API & Alerts
Pricing
from $1.40 / 1,000 teamtailor jobs
Teamtailor Jobs Scraper - Career Page Jobs API & Alerts
Teamtailor jobs scraper for any public Teamtailor career site. Export titles, departments, locations, remote/hybrid type, full descriptions, apply links, posting and expiry dates for many companies per run, and schedule alerts that output only new jobs. No login or API key.
Pricing
from $1.40 / 1,000 teamtailor jobs
Rating
0.0
(0)
Developer
Group Oject
Maintained by CommunityActor stats
1
Bookmarked
4
Total users
0
Monthly active users
8 days ago
Last modified
Categories
Share
Scrape every open job from any public Teamtailor career site: title, company, department, locations, remote/hybrid type, employment type, full description, apply URL, posting and expiry dates. Run many companies at once and schedule alerts for new jobs. No login, browser or API key.
Teamtailor powers the career pages of thousands of startups, scale-ups and employers, especially in the Nordics and the rest of Europe. This Actor reads each site's public jobs.json feed, so results are fast, structured and current.
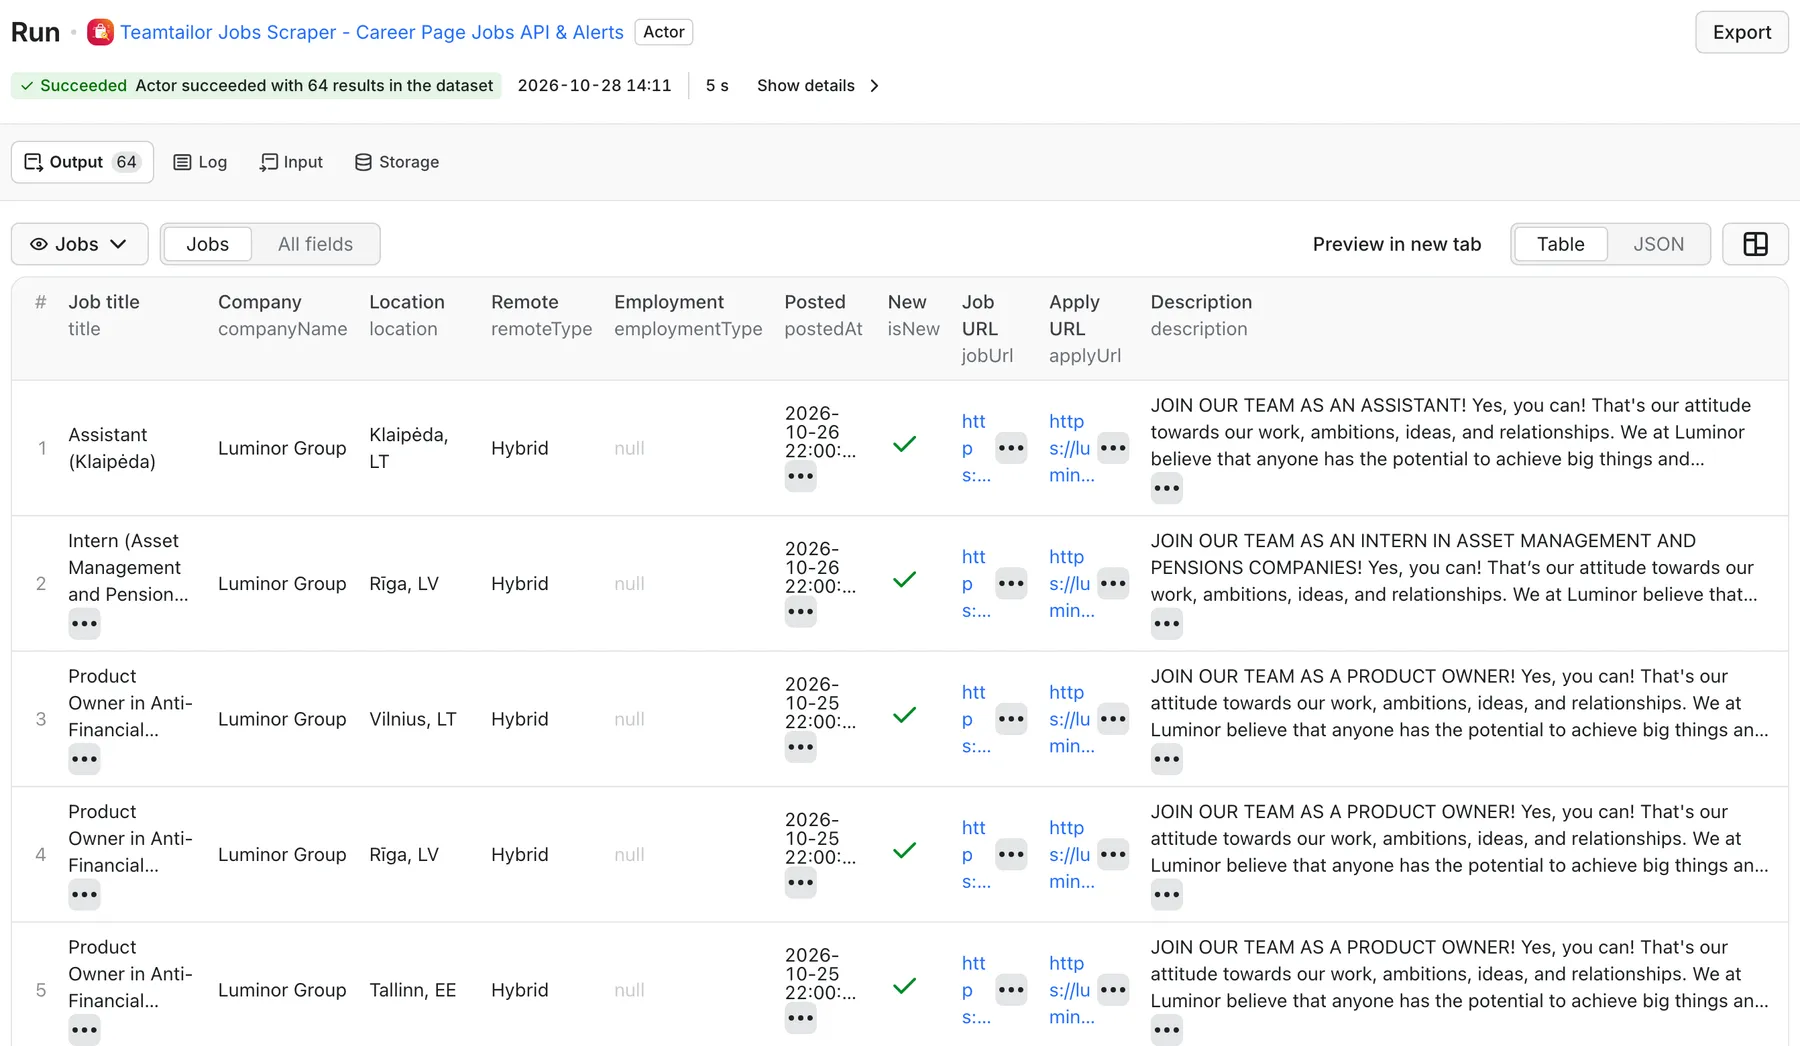
Real output from a default run of Teamtailor Jobs Scraper in Apify Console.
What can this Teamtailor scraper do?
- Any Teamtailor career site - paste
https://company.teamtailor.com/jobsURLs or just the slug (company). - Many companies per run - lists, slugs, or a pasted block with one entry per line.
- Full job descriptions - clean text by default, raw HTML optional.
- Filters - keywords, locations, departments and posted within N days.
- New job alerts -
monitorModeremembers job IDs;onlyNewJobsoutputs only jobs not seen before. - Per-source diagnostics -
SOURCESshows fetched / kept / new counts and errors per career site.
What data can I extract from Teamtailor?
| Field | Meaning |
|---|---|
title, jobId, department | Job title, Teamtailor job ID, department |
companyName, companySlug | Employer and Teamtailor subdomain |
location, locations, country | Locations from the job posting |
remoteType | Remote / Hybrid / On-site, from structured fields or job text |
employmentType | For example FULL_TIME |
description, descriptionHtml | Clean-text description, optional HTML |
jobUrl, applyUrl, sourceUrl, feedUrl | Posting, application and feed links |
postedAt, validThrough | Publish date and expiry date when set |
isNew, firstSeenAt, lastSeenAt | Monitoring fields |
How much does it cost?
$2.00 per 1,000 jobs saved ($0.002 per job), plus an Actor start charge of $0.00005 per GB of memory. 100 jobs = $0.20. Use maxJobsPerCompany (default 200) and maxTotalJobs (default 1,000) to control spend. The Pricing tab has current rates.
How to scrape Teamtailor jobs
- Open a company's careers page and check that it is hosted on Teamtailor (the address is
<company>.teamtailor.com). - Paste the URL or slug into Company URLs / Company slugs.
- Optionally add keywords, locations, departments or a freshness filter.
- Click Start, then export as CSV, Excel or JSON.
- For alerts: set
monitorMode: true,onlyNewJobs: trueand astateKey, save as a task and schedule it.
Input example
Output example
Monitor Teamtailor career pages for new jobs
Turn on monitorMode and keep the same stateKey across scheduled runs. Each job gets isNew; with onlyNewJobs: true the dataset contains only jobs that were not seen in earlier runs. Connect a webhook, Make, Zapier or n8n to send them to Slack, email or a spreadsheet. Use a different stateKey per saved task.
Use cases
- Export all jobs from one or many Teamtailor career pages.
- Startup and scale-up hiring trackers for recruiters and agencies.
- Sales signals: European companies hiring for roles related to your product.
- Niche job boards and newsletters fed from Teamtailor companies.
- Labor-market research across Nordic and European employers.
Use with AI agents (MCP)
Connect the Apify MCP server at https://mcp.apify.com?tools=groupoject/teamtailor-jobs-scraper in Claude Desktop, Cursor, VS Code or any MCP client, and your AI assistant can call this actor as a tool. Example prompt: "Get every open job from these Teamtailor career sites and group them by location."
FAQ
Do I need a Teamtailor account or API key? No. The public jobs.json feed of each career site is used.
Does it work with custom career domains? Only *.teamtailor.com addresses are accepted. If a company uses its own domain, look for its teamtailor.com subdomain (often visible in the apply link).
Why did a company return no jobs? It may have no open roles, a disabled feed or a moved career site. Check SOURCES for the error.
Is it legal? It reads publicly advertised jobs only, without login or candidate data. You are responsible for how you use the data.
Related job scrapers
- Greenhouse & Lever Jobs Scraper - jobs from Greenhouse and Lever career boards with hiring-signal scores.
- SmartRecruiters Jobs Scraper - jobs from SmartRecruiters company boards.
- Job Scraper - LinkedIn Jobs & Indeed - keyword job search across LinkedIn and Indeed with alerts.
See CHANGELOG.md.


