
Sitemap URL Extractor: Bulk XML Sitemap Parser
Pricing
$0.50 / 1,000 extracted urls
Sitemap URL Extractor: Bulk XML Sitemap Parser
Extract every URL from a website's XML sitemaps: robots.txt discovery, nested sitemap indexes and gzip. Returns url, lastmod, changefreq, priority and source sitemap. Include/exclude filters. Plain HTTP, no browser. $0.50 per 1,000 URLs, failures free.
Pricing
$0.50 / 1,000 extracted urls
Rating
0.0
(0)
Developer
Hill Country Bots
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
13 hours ago
Last modified
Categories
Features
Share
Extract every URL from a website's XML sitemaps in one run. This is a bulk sitemap URL extractor and XML sitemap parser. The Actor reads robots.txt, follows nested sitemap indexes, and decompresses gzip sitemaps. Each row comes back with the URL, lastmod, changefreq, priority and the source sitemap. Optional include and exclude filters. Plain HTTP, no browser, no login, no personal data. $0.50 per 1,000 extracted URLs. Failed fetches, invalid inputs and filtered URLs are free.
What does this sitemap URL extractor do?
You give it a website or a sitemap URL. It then:
- Discovers sitemap files from robots.txt (
Sitemap:lines) and, if you want, from common paths (/sitemap.xml,/sitemap_index.xml, and their.gzversions) - Follows sitemap indexes recursively, including gzip-compressed files
- Returns one row per unique URL:
url,lastmod,changefreq,priority,sourceSitemap - Applies optional include and exclude patterns (
*wildcards or/regex/) - Caps the run with
maxUrlsandmaxSitemaps - Refuses private, local and internal addresses
It does not crawl pages, render JavaScript, or fetch anything except robots.txt and sitemap files.
Who is it for?
- SEO agencies and consultants: export a site's URL list for audits, migrations or index coverage checks
- Developers: turn a sitemap into a clean CSV or JSON list as a first step before a PageSpeed run or a content crawl
- AI agents and automations: stable JSON through the Apify API or MCP, with a predictable price per extracted URL
Quick start
- Paste a website (for example
https://www.sitemaps.org/) or a direct sitemap URL. The form comes prefilled, so Start works right away. - Leave sitemap discovery on unless you already have the exact sitemap URL. Optionally add include or exclude patterns, or raise
maxUrlsfor a full site (the example starts at 25 so a one-click run finishes in seconds). - Click Start, then download the results as JSON, CSV or Excel, or read them through the API.
To refresh a site's URL list on a schedule, create a Schedule in Apify Console and send the dataset to Google Sheets, or feed the url column into the Bulk PageSpeed Insights Test.
Sample output
This table is the first five of 20 URLs from a real run on November 10, 2026, at 9:34 PM CT (America/Chicago), starting at sitemaps.org. You pay about $0.50 per 1,000 extracted URLs. Failed fetches and filtered URLs are free.
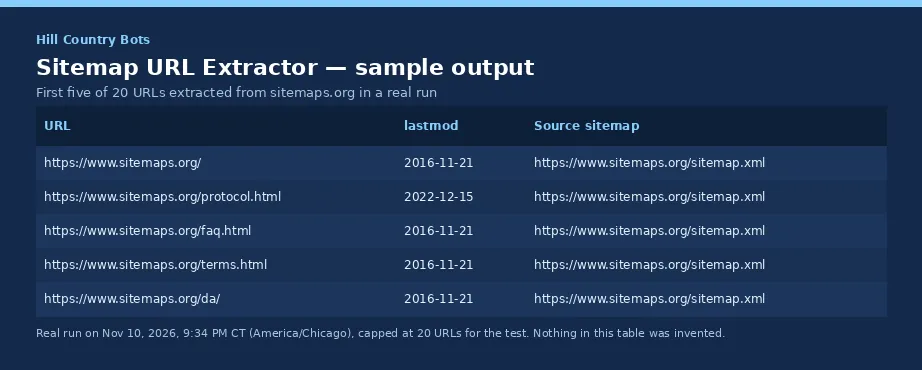
If no sitemap can be found or a start URL is invalid, the run writes a row with status: "error", errorCode and errorMessage instead of finishing as a silent success with empty data. Those rows are not charged.
Example inputs
Discover and parse XML sitemaps from a website homepage (robots.txt plus common paths):
Extract URLs from a direct sitemap.xml (no discovery):
Keep only matching paths with an include pattern:
Cap a large site at 100 URLs ($0.05 maximum):
Ready-to-run example tasks (pre-filled inputs on this Actor's Store page):
Input
| Field | Type | Default | What it does |
|---|---|---|---|
startUrls | array of strings | (required, prefilled) | Website home pages and/or direct sitemap URLs. Private, local and internal addresses are refused. |
discoverFromRobots | boolean | true | Fetch /robots.txt and collect every Sitemap: line. |
tryCommonPaths | boolean | true | Also try /sitemap.xml, /sitemap_index.xml and their .gz versions. Missing files are skipped, not charged. |
includePatterns | array | (none) | If set, only URLs matching at least one pattern are kept. * wildcards or /regex/. |
excludePatterns | array | (none) | URLs matching any of these patterns are dropped. |
maxUrls | integer | 10000 | Exact cap on unique URLs returned (and charged). Caps spend at maxUrls × $0.0005. |
maxSitemaps | integer | 200 | Exact cap on unique sitemap files to fetch (indexes and urlsets). |
maxConcurrency | integer 1-10 | 4 | Sitemap files fetched in parallel. |
requestTimeoutSecs | integer | 30 | Seconds to wait on one file, then retry (up to 3 attempts). |
Output example
A start URL or sitemap file that could not be used is not charged and looks like this:
The key-value store also gets a RUN_SUMMARY record with totals (extracted, failed, filtered, sitemapsFetched, indexesFollowed).
Output fields (for AI agents and integrations)
status:okmeans a URL was extracted from a sitemap.errormeans a start URL or sitemap file could not be used and is not charged.url: the page URL from<loc>, or the rejected start/sitemap URL on an error row.lastmod,changefreq,priority: sitemap fields, when present.priorityis kept as the original string (0.0-1.0).sourceSitemap: the sitemap file the URL was read from.errorCodeis one of:INVALID_URL,PRIVATE_URL,HTTP_<code>,TIMEOUT,NETWORK_ERROR,INVALID_SITEMAP,EMPTY_SITEMAP.
Use it from the API, MCP or an AI agent
- Actor ID:
hillcountrybots/sitemap-url-extractor - One API call returns the rows:
- MCP (Claude, Cursor, ChatGPT and other MCP clients): add
https://mcp.apify.com?tools=hillcountrybots/sitemap-url-extractor. - For agents: branch on
status. Eachokrow is one extracted URL. Error rows are free.
How much does it cost?
$0.50 per 1,000 extracted URLs, which is $0.0005 per url-extracted event (one unique URL kept after filters). You pay nothing for:
- invalid start URLs
- failed sitemap fetches
- URLs dropped by include/exclude filters
- the run summary
The Actor's compute is included, so there's no separate platform usage charge. For example, 2,000 URLs from a large sitemap index is $1.00. To cap spend, use maxUrls or the run's maximum charge setting.
Limits
- This tool reads sitemap files only. It does not crawl pages, check HTTP status of each URL, or render JavaScript.
- A URL appears in the output only if a sitemap lists it. Pages missing from the sitemap are not invented.
lastmodis whatever the sitemap published; some sites omit it or keep it stale.- Very large sites can have hundreds of sitemap files. Use
maxUrlsandmaxSitemapsto cap the run.
FAQ
Do I need a sitemap URL, or will a homepage do? A homepage is enough. The Actor reads robots.txt and also tries common sitemap paths.
Does it support gzip sitemaps and sitemap indexes? Yes. .gz files and nested indexes are followed, up to maxSitemaps.
Does it crawl the website? No. It only fetches robots.txt and sitemap XML.
Does it collect personal data? No. It returns URLs and sitemap metadata only.
Can I feed the URLs into the PageSpeed checker? Yes. Export the url column and paste it into Bulk PageSpeed Insights Test.
More tools from Hill Country Bots
- Bulk PageSpeed Insights Test: Lighthouse scores and Core Web Vitals for many URLs. $3 per 1,000 audits, failures free.
- Bulk Domain Availability Checker: Bulk available/taken checks from official registry RDAP, with registrar and expiry dates. $1 per 1,000 domains, invalid inputs and errors free.
- Tech Stack Detector: CMS, ecommerce, analytics, CDN and frameworks for many websites. $0.50 per 1,000 sites, failures free.
- SEO Audit Tool: 0-100 SEO score per page, top 5 fixes and a client-ready HTML report. $2 per 1,000 pages, failures free.
Support
Found a missed sitemap or need a field added? Open an issue on this Actor's Issues tab with the run ID and the website. We reply within 2 business days (US Central time). Built and maintained by Hill Country Bots.


