

LinkedIn Jobs Scraper
Pricing
from $2.10 / 1,000 jobs
LinkedIn Jobs Scraper
Scrape LinkedIn job listings worldwide without login: title, company, location, seniority, job function, industries, applicants, salary when posted, full description, apply link and recruiter emails from the posting.
Pricing
from $2.10 / 1,000 jobs
Rating
5.0
(1)
Developer

Matvey
Maintained by CommunityActor stats
0
Bookmarked
18
Total users
10
Monthly active users
a day ago
Last modified
Categories
Share
LinkedIn Jobs Scraper turns any LinkedIn job search into a clean table — without login, cookies or a LinkedIn account. Every row has the title, company, location, remote / hybrid / on-site, seniority, industries, number of applicants, Easy Apply or external apply, salary when the employer posts it, the full description, the job poster when LinkedIn shows them, recruiter emails and phones found in the posting — and company details at no extra cost: website and domain, industry, size, employees on LinkedIn, followers, headquarters, founded year, specialties and description. Worldwide, by any location LinkedIn understands.
Type job titles and a location and click Start. Export as JSON, CSV or Excel, run it on a schedule for fresh postings, or call it from the API and AI agents.
Tested head-to-head — 5 October 2026
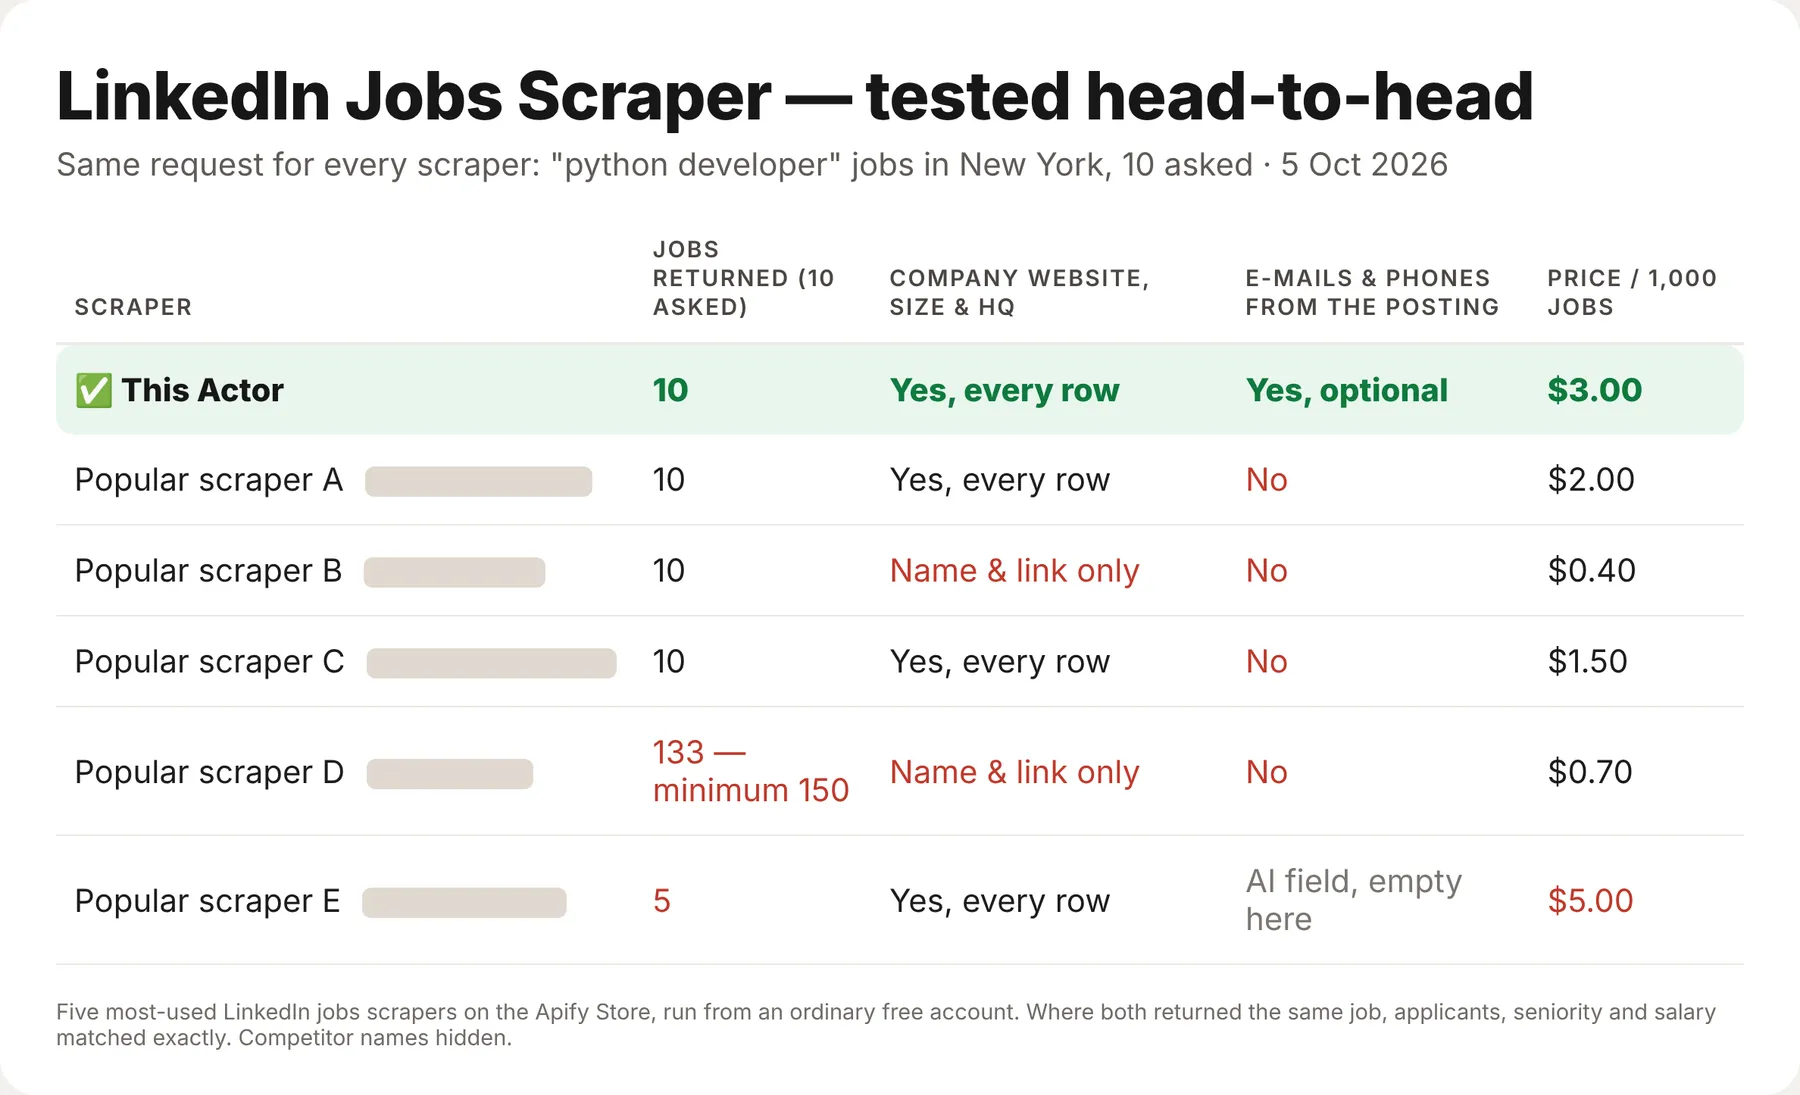
The same search — "python developer" jobs in New York, 10 asked — went to this Actor and to the five most-used LinkedIn jobs scrapers on the Apify Store, from an ordinary free account. Where both returned the same job, applicants, seniority and salary matched exactly; what differed was how much of the company came with each row.
| This Actor | The others | |
|---|---|---|
| Company website, size & HQ on every row | Yes | 3 of 5 |
| E-mails & phones from the posting text | Yes (optional) | none (1 has an AI field, empty in this test) |
| Jobs returned (10 asked) | 10 | 5 – 133 |
What is LinkedIn Jobs Scraper?
It is a LinkedIn jobs scraper and LinkedIn jobs API for recruiters, job boards, lead generation, labour-market research and AI agents. LinkedIn has no public job-search API; this Actor reads LinkedIn's public guest job pages — the ones anyone can open without signing in — so no account is ever at risk.
- No login, no cookies: nothing to connect, nothing to get banned.
- Full descriptions and LinkedIn's own fields:
seniority,industries,applicants,applyType(Easy Apply or an external site), and the job poster (posterName,posterTitle,posterProfileUrl) when LinkedIn shows the hiring team. - Company details, free: each hiring company's LinkedIn page is read once per run —
companyWebsite,companyDomain,companyIndustry,companySize,companyEmployeesOnLinkedIn,companyFollowers,companyHeadquarters,companyFoundedand more on every row. Turn off with Add company details. - Filters at the source: posted within, remote / hybrid / on-site filter, job type, experience level, radius, sort by date. Jobs found with the workplace filter carry it in
workplaceTypeandisRemote. - Contacts: emails and phones from the posting text; optional look-up of general contacts on the company website.
What data does it return?
| Field | Example |
|---|---|
id, url | 4466180813 · https://de.linkedin.com/jobs/view/senior-data-engineer-at-trust-in-soda-4466180813 |
title, company, companyUrl, companyLogo | Senior Data Engineer · Trust In SODA · https://uk.linkedin.com/company/trust-in-soda · … |
location, queryLocation | Berlin, Germany · Berlin, Germany |
seniority, industries, applyType | Mid-Senior level · Software Development · external |
applicants, applicantsText | 189 · "189 applicants" |
workplaceType, isRemote | remote · true (from the workplace filter; otherwise from the title and location, else null) |
employmentType, jobTypes | fulltime · ["fulltime"] |
salaryMin, salaryMax, salaryCurrency, salaryPeriod, salaryText | 85000 · 110000 · EUR · year (when the employer posts pay) |
postedAt, postedText, description, descriptionHtml | 2026-09-15T00:00:00.000Z · "1 week ago" · full text · HTML |
posterName, posterTitle, posterProfileUrl | Asif Shaikh · Delivery Manager at NTT DATA North America · linkedin.com/in/shaikh-asif (about 1 job in 5) |
companyWebsite, companyDomain | https://www.bankofamerica.com · bankofamerica.com |
companyIndustry, companyType, companyFounded | Banking · Public Company · null (the year when the page shows it, e.g. 2008) |
companySize, companySizeMin, companySizeMax | 10,001+ employees · 10001 · null |
companyEmployeesOnLinkedIn, companyFollowers | 227047 · 3488660 |
companyHeadquarters, companyCity, companyCountry | Charlotte, NC · Charlotte · US |
companySpecialties, companyDescription, companyTagline | ["Financial Services"] · about text · tagline |
emails, phones | from the posting text, when present |
LinkedIn no longer shows "Job function" to guests on most postings, so jobFunction is usually null. The external apply link is shown by LinkedIn to signed-in members only, so applyUrl is null unless LinkedIn shows it to guests: applyType tells whether the job's button is LinkedIn Easy Apply (easyApply) or an external site (external), and url opens the job. Company fields are null when LinkedIn did not open the company page this time — the job row is still delivered.
How much does it cost?
Pay per job row; error rows are free.
| Row | Price |
|---|---|
| Job | $0.003 — 1,000 LinkedIn jobs for $3 |
| Job that came with an email address | +$0.002 |
| Company details on the row | free |
No fee per run, per page or for proxies. Larger monthly plans get 10–30 % off.
How to scrape LinkedIn jobs
- Enter Job titles or keywords (one per line) and a Location (city, region, country or "Worldwide").
- Pick filters: posted within, workplace, job types, experience level, radius, sort.
- Keep Full descriptions on if you need the job text (one extra request per job). When LinkedIn refuses a job page on the first route, it is fetched again through a residential address and then a web unblocker — included in the price. A job whose page still does not open is delivered without the description fields. With your own proxy URLs in the proxy field, only your proxies are used.
- Click Start; export the dataset or read it through the API.
⬇️ Input
Remote jobs worldwide, newest first:
⬆️ Output
A search that cannot be read arrives as a type: "error" row with the reason, never as a silently empty run.
Use cases
- Recruiting and sourcing: who is hiring for a role, where, how many applicants already.
- Job boards and alerts: fresh LinkedIn postings on a schedule; dedupe on
id. - Lead generation: companies hiring for a function are buying tools for it — export
companyand contacts. - Market research: seniority and industries across thousands of postings.
- AI agents: typed rows an agent can filter.
Integrations
Run it from the Apify API, a schedule or a webhook, and push results to Google Sheets, Airtable, Slack or a CRM through n8n, Make or Zapier. The Apify MCP server exposes it to Claude, ChatGPT and other agents.
❓ FAQ
Do I need a LinkedIn account or cookies?
No. Only LinkedIn's public guest job pages are read.
How many jobs can I get?
Up to 1,000 per search — the same ceiling LinkedIn shows to any visitor. LinkedIn lists 10 jobs per page; the Actor reads page after page until your Jobs per keyword number, the last page or that ceiling. Split big searches by location or keyword.
I also need Indeed and company career sites.
Use Jobs API — Indeed, LinkedIn and Greenhouse / Lever / Ashby / Workable boards in one schema — or Indeed Jobs Scraper.
Is this legal?
It reads public job postings without logging in and returns factual listing data and public business contacts. Respect LinkedIn's terms and local law for outreach; this is not legal advice.
You might also like
- Jobs API — Indeed, LinkedIn and career sites in one table.
- Indeed Jobs Scraper — Indeed jobs from 60+ countries.
- Website Contacts API — emails and phones from any company website.
Use via API
Run this Actor from your own code or pipeline. Get your token in Apify Console → Settings → API & Integrations. Every input field below has the same name as in the JSON tab of the input form.
Python
JavaScript
cURL (runs the Actor and returns the results in one call)


