
TikTok Transcript Scraper — TikTok Video to Text
Pricing
from $2.50 / 1,000 videos
TikTok Transcript Scraper — TikTok Video to Text
Turn TikTok videos into text: transcript with timestamps, on-screen captions and the first-3-second hook. Give it links or a whole profile — no login, no cookies. Instagram Reels and YouTube Shorts links work in the same run. Run via API, schedule, or feed an AI workflow.
Pricing
from $2.50 / 1,000 videos
Rating
5.0
(3)
Developer

Matvey
Maintained by CommunityActor stats
0
Bookmarked
40
Total users
15
Monthly active users
11 days ago
Last modified
Categories
Share
TikTok Transcript Scraper turns public TikTok videos into text — transcript with timestamps,
the text burned into the picture, and the first-3-second hook — without a login, cookies or the
official API. Paste video links or a handle like @duolingo and get one clean row per video.
It also accepts Instagram Reels and YouTube Shorts links, so a mixed list of URLs works in one run.
Tested head-to-head — 26 September 2026
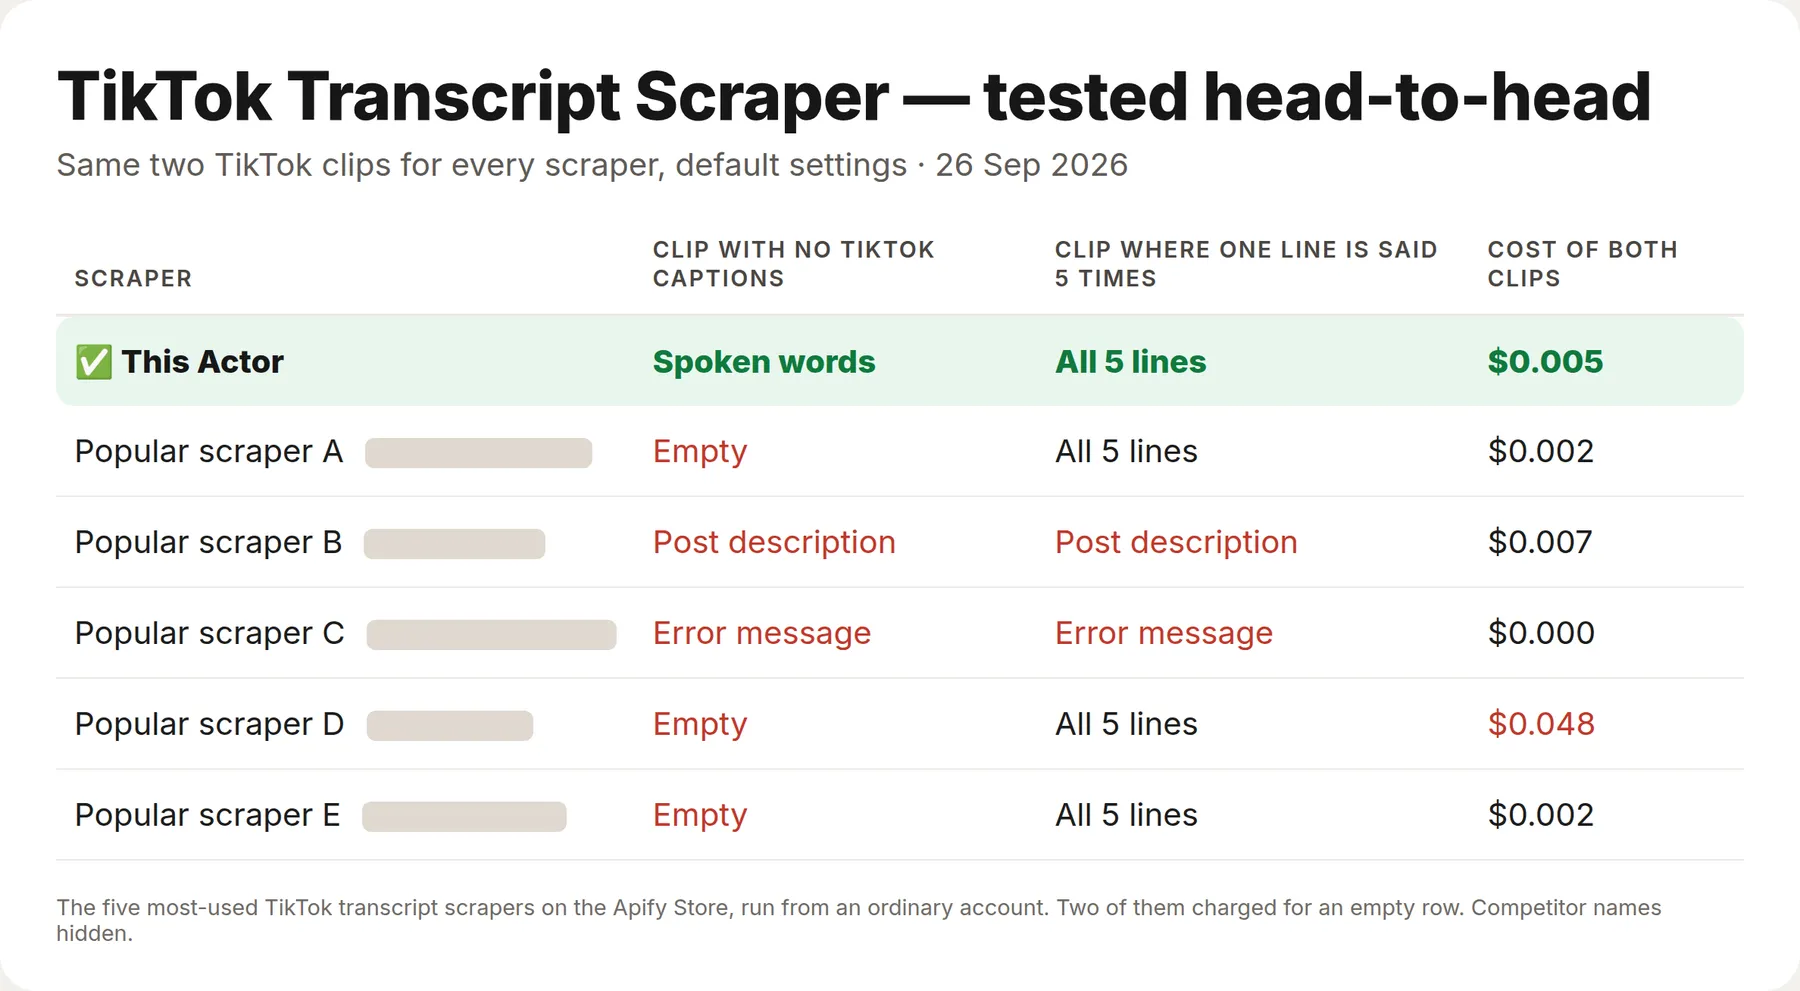
Two public TikTok clips, run through the five most-used TikTok transcript Actors on the Apify Store from an ordinary account, with every Actor on its default settings.
| This Actor | The five others | |
|---|---|---|
| Clip that has no TikTok captions (Duolingo, 9 s) | Spoken words returned | 0 of 5: an empty transcript, an error message or the post description instead |
| Clip with TikTok captions, one line said five times | All 5 lines | 3 of 5 returned all 5 lines |
| Time per run | 12–21 s | 2–13 s |
| Cost of both clips | $0.005 | $0.00–$0.048 (two charged for an empty row) |
How it works: when TikTok already has captions for a video, they become the transcript — they keep every repeated line and there is no audio charge. When a video has none, speech recognition fills the gap, which is why this Actor returned text on both clips.
What is TikTok Transcript Scraper?
TikTok Transcript Scraper turns a short vertical video into structured text: the spoken transcript, the text written on screen, and the first three seconds of both — the hook. It works on Instagram Reels, TikTok videos and YouTube Shorts, with no login, no cookies and no official API needed.
Most transcript scrapers stop at the audio. In short-form video the audio is often not where the message is: in our test set of 26 real videos, only 69% carried a narrated script, 19% had no usable speech at all, and 12% ran on someone else's trending sound. 81% had text on screen. An actor that reads only the audio returns noise or nothing on roughly a third of a real feed.
This one reads both, tells them apart, and says which kind of video you gave it.
What data can TikTok Transcript Scraper extract?
| Field | Example |
|---|---|
transcriptText | Today, I wanted to do a quick tips and tricks or best practices for posting reels… |
firstThreeSecondsSpeech | Today, I wanted to do a quick tips and tricks or best practices for |
onScreenText | Reels Tips & Tricks, No Watermarks, Under 3 Minutes, Add Music/Audio |
firstThreeSecondsOnScreen | Reels Tips & Tricks |
contentClass | narrated · borrowed_audio · silent · empty |
hookText, hookType | So what brought you here?, question |
ctaText, ctaType | 🔗 Link in bio to book, link_in_bio |
wordsPerMinute, beats | 150, [{startSeconds, endSeconds, label: hook/body/cta, text}] |
speechDetected, speechCoverage | true, 0.89 |
burnedInCaptionCount | 41 |
screenRecording | false |
language, durationSeconds, platform, videoId | en, 61.3, instagram, DFIWSVoy1UQ |
Why on-screen text is separated from subtitles
Half the videos we measured carry burned-in subtitles that simply repeat the speech. Dumping every recognised string into one field means the same sentence appears twice and the actual title cards drown in it.
This actor separates them by two signals: how closely a line matches what is being said at that exact moment, and which horizontal band of the frame it lives in. On a labelled video with 54 text tracks the split came out with no errors. onScreenText therefore contains what the author wrote for the viewer; burnedInCaptionCount tells you how many subtitle tracks were removed.
Why the content class matters
Speech recognition models do not stay silent over music — they invent. On a wordless branded clip the model returned "We'll be right back.", and its own confidence score for that invention was 0.00 false positive — the metric that is supposed to catch this says nothing. So the class is decided from word density and how much of the clip speech actually covers.
| Class | What it means | What you get |
|---|---|---|
narrated | The voice carries the script | Transcript + on-screen text |
borrowed_audio | A trending sound or a clip from someone else — not the author's words | On-screen text; the audio is labelled, not passed off as a script |
silent | No speech; the meaning is in the captions | On-screen text only |
empty | Neither speech nor on-screen text | An explicit refusal instead of blank fields |
A looping trending sound is caught by its own repetition: when one line comes back word for word three times or more, it is a sound, not a script.
Hook, call to action and beats: rules, not AI
Every video row also carries a short script breakdown. It is built by fixed rules from data the row already has (the timestamped transcript, the on-screen text and the caption). There is no language model and no extra charge, and the same video always gives the same answer.
| Field | What it holds |
|---|---|
hookText, hookSource | The opening line. Text written on screen in the first three seconds comes first, because it is a deliberate hook; the first spoken sentence wins only when the speech is the author's subtitled voice-over, or when there is no early on-screen text. Last resort: the caption's first sentence. hookSource says which one: speech, on-screen or caption. |
hookType | how_to, question, number, warning, curiosity, callout, story, or statement when no pattern matches |
hookEndSeconds | Where the hook ends on the timeline |
ctaText, ctaType, ctaSource | The line that asks the viewer to act. Types: link_in_bio, dm, book, shop, download, comment, subscribe, follow, save, share, like, visit, watch_more, or none |
wordsPerMinute | Speaking pace of the author's speech; empty when there is no own speech |
beats | The timeline split into hook, body and cta parts with start and end seconds. The text is the real words, not a summary |
The patterns cover English and basic Russian, Spanish, Portuguese, Indonesian, French and German. Being rules, they miss what they do not know. A hook phrased in an unusual way comes out as statement, and a call to action without a known phrase comes out as none. They never invent text that is not in the video or the caption. Real output for a silent Reel with an on-screen question:
AI script breakdown (paid add-on, from 6 Nov 2026)
Switch on 🤖 AI script breakdown (aiAnalysis: true) and every video row gets an ai object written by a language model (DeepSeek V4.1 Flash). How it works, honestly: we take one frame every 2 seconds (at most 12 per video; longer videos are sampled evenly), 360 px wide, and send them to the model together with our own transcript, the on-screen text (when you switch that on) and the caption. The model sees still frames, not the moving video and not the sound itself.
Field in ai | What it holds |
|---|---|
hook | text, source (speech, on-screen, visual, caption), type and whyItWorks |
beats | 2 to 8 consecutive parts with startSeconds, endSeconds, label (hook, setup, value, proof, twist, cta, outro), visual (what is on screen) and text (the words of that part) |
cta | text and type (link_in_bio, follow, comment, dm, book, shop, save, share, other, none) |
topic, format, audience, emotion | One line each |
scriptTemplate | The script as a fill-in template with [placeholders] you can reuse |
speechIsSong | True when the audio is song lyrics rather than the author talking |
onScreenText | Text the model reads on the frames |
Descriptions are in English; spoken and on-screen words are quoted in the video's own language. aiModel names the model and aiError says why a breakdown is missing. The rule-based fields above (hookText, ctaText, beats and the rest) stay as they are. A model can misread a frame, so treat the breakdown as a strong first draft. It costs $0.05 per video on the Free plan (less on paid Apify plans), charged as the ai-analysis event only when the breakdown comes back; a failed or skipped breakdown is free. Until 6 November 2026 the switch does nothing and costs nothing. Shortened real output for a 9-second Reel:
How much does it cost to extract Reel transcripts?
Pay-per-event, no subscription, and short clips are not billed as if they were long ones.
| Event | Until 7 Oct 2026 | From 7 Oct 2026 |
|---|---|---|
reel-processed — one video: transcript with timestamps, language, hook | $0.002 | $0.003 |
audio-10-seconds — each started 10 seconds of speech recognised | $0.001 | $0.0015 |
on-screen-text — one video read frame by frame for burned-in text | $0.06 | $0.06 |
From 7 October 2026 a 15-second TikTok costs $0.006, a 30-second Reel $0.0075 and a 60-second Short $0.012; a YouTube Short with its own captions costs $0.003. Apify plan discounts take up to a sixth off. Reading on-screen text is a separate switch and a separate charge, because it is a separate job: the video is downloaded and read frame by frame.
Failed URLs, videos above your duration limit and silent videos are never billed. A row you cannot use is a row you do not pay for.
AI script breakdown is a separate switch and a separate event: ai-analysis, $0.05 per video on the Free plan ($0.045 Bronze, $0.04 Silver, $0.035 Gold and above), from 6 November 2026. It is charged only when the breakdown comes back.
Bulk export
This Actor is built for bulk jobs — put hundreds of URLs into one run, or call it from the API on a schedule. Videos are processed three at a time, and there is no fee per run, no fee per page and no proxy charge. Speech is billed in 10-second steps, not rounded up to whole minutes, so a 9-second TikTok never costs what a 59-second one does. 50,000 clips of 30 seconds cost $375 from 7 October 2026; 50,000 YouTube Shorts with captions cost $150.
Two things most alternatives do not do: three platforms in one run — TikTok, Instagram Reels and YouTube Shorts, one integration instead of three — and on-screen text read and separated from speech, so caption cards and hard subtitles do not get mixed into what the author actually said.
How to extract TikTok, Reels and Shorts transcripts
- Click Try for free.
- Paste one or more video URLs into 🔗 Reel, TikTok or Shorts URLs. The field comes prefilled with a working example, so you can just press Start.
- Press Start. Results appear in the dataset, one row per video.
⬇️ Input
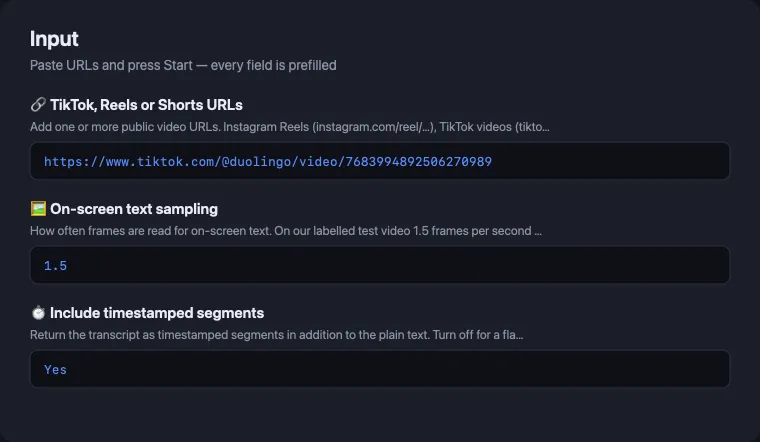
Video URLs
Public Instagram Reels, TikTok videos and YouTube Shorts. Private and deleted videos return an error row naming the reason.
On-screen text sampling
How many frames per second are read for on-screen text. On our labelled video, 1.5 frames per second found every caption card; 1 frame per second lost three of six. 1.5 is the default; raise it only for dense motion graphics.
Videos are read one at a time. If a video's on-screen text cannot be read before the run ends, you still get its transcript: the row carries onScreenTextError, and on-screen text is not charged for that video.
Whole profiles, not just links
Paste a TikTok handle (@duolingo), just the username (duolingo), a TikTok profile link or a YouTube channel into Whole
profiles, set how many of the newest videos you want, and the Actor collects the links itself.
Add a date in Only videos newer than to keep a weekly watch cheap: anything older is skipped
before it is downloaded, so it costs nothing.
Instagram profiles need a login, so they are not supported — paste Reel URLs instead. A profile link dropped into the URL field is understood too; you do not have to pick the right box.
YouTube Shorts cost less than the rest
For YouTube the Actor takes the caption track YouTube has already made, instead of downloading the video and recognising speech. That means Shorts are billed at the video price alone, with no per-audio charge at all, and they come back in seconds.
⬆️ Output
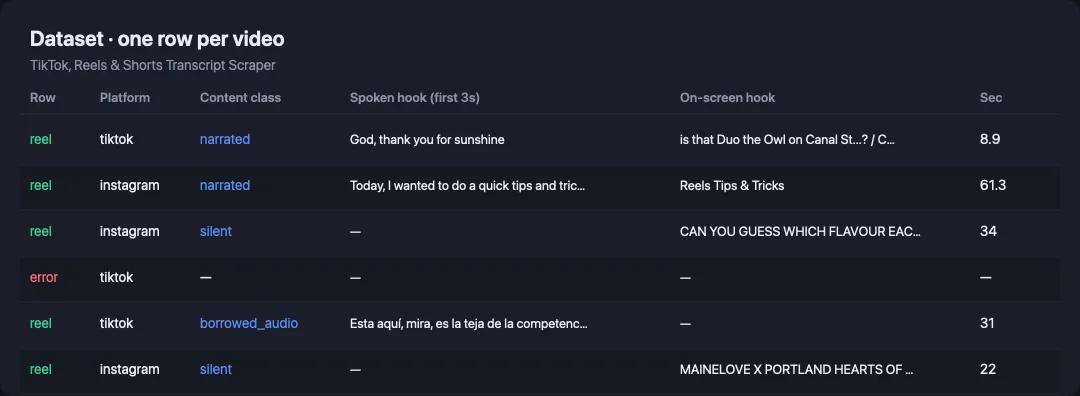
One row per video:
Error rows
A URL that cannot be processed returns a row of its own and is not billed:
Codes: download_failed, timeout, unsupported_url, audio_failed, transcription_failed, ocr_failed, processing_failed.
Use cases for Reel and TikTok transcript data
Competitive research
Feed a list of a competitor's videos and read their hooks side by side. firstThreeSecondsSpeech and firstThreeSecondsOnScreen are cut on the 3.0-second boundary, so the comparison is between what viewers actually received, not between opening sentences of different lengths.
Content repurposing
Turn a back catalogue into text for blog posts, newsletters and captions. onScreenTextJoined gives the written layer separately, which is what carries the message in silent videos.
Feeding an LLM or a RAG index
The output is flat, typed and one row per video. The content class tells your prompt when the transcript is not the author's words — which is what stops a summarising agent from confidently describing someone else's trending sound as this creator's message.
Accessibility and archiving
Transcripts and on-screen text for captioning, search and long-term storage of a feed that platforms may take down.
Integrations
- API: run it from any language with the Apify API, or the Python and JavaScript clients.
- MCP: callable by AI agents through the Apify MCP server, like any other Actor.
- No-code: Make, Zapier, n8n, Google Sheets, Slack through Apify's integrations.
- Webhooks: trigger a downstream run when a batch finishes.
❓ FAQ
Is it legal to scrape Instagram Reels and TikTok?
This Actor reads only public videos, the same ones any visitor can open without logging in, and it does not collect personal profiles. Laws differ by country and by intended use; consult a lawyer before building a commercial product on scraped data.
How much does it cost to transcribe 1,000 reels?
From 7 October 2026 about $7.50 for 30-second clips and about $6 for 15-second ones (until then $5 and $4) — one event per video plus the seconds of speech actually recognised. Failed URLs are free.
Can I use it with the Apify API?
Yes — it is a standard Actor. Start a run, poll it, read the dataset, or use a webhook.
Can I use it through an MCP server?
Yes. It is exposed through Apify's MCP server and its input schema is written so an agent can call it correctly without reading this page.
Does it return one row per video?
Yes. One row per video, plus a separate error row for any URL that failed. Nested arrays (transcript, onScreenText) are provided alongside flat string versions so spreadsheets stay readable.
What languages does it handle?
Speech recognition is multilingual. On-screen text has been verified on Latin and Cyrillic scripts; other scripts are not claimed.
Why is the transcript empty on some videos?
Because the video has no speech. On music-only or wordless videos, speech-recognition models do not stay silent: they invent text they learned from film subtitles and YouTube outros, such as "Subtitles by …", "Thanks for watching", "[Music]", a single word repeated ("The The") or a few words in a random language. The Actor drops such invented lines using a list of known phrases in 15+ languages, the recogniser's own confidence scores (standard Whisper thresholds), repeated-word checks, how many words fit in the time, and whether the script matches the caption. Real speech in the same video is kept. When nothing real is left, transcriptText is empty, transcript is [], speechDetected is false, transcriptSource is no-speech, language is null (we do not guess a language when nobody speaks; the caption's language is still in caption), and the audio of that video is not charged. This is intended behaviour, not a failure.
Does it need proxies?
No. It runs without residential proxies, which is why extraction is priced where it is.
You might also like
Part of our speech-and-text toolkit — the Store only recommends within a category, so here they are:
| Actor | What it does |
|---|---|
| Whisper Transcriber | Any audio or video file to text, 90+ languages |
| YouTube Transcript Scraper | Transcripts from YouTube videos and playlists |
| SRT Subtitle Generator | Ready-to-upload subtitle files from any video |
| Audio Transcriber | Podcasts, calls and meetings to text |
| OCR Text Extractor | Text out of images and screenshots |
| Instagram Reels Transcript Scraper | Instagram Reels, TikTok and Shorts to text with the 3-second hook |
Use this Actor for short vertical video, where the message is split between the voice and the screen; use the others when you already have a file or a long-form video.
Your feedback
Found a video it handles badly? Open an issue on the Actor's Issues tab with the URL — that is the fastest way to get it fixed, and every issue gets a reply.


