
Weibo Scraper
Pricing
from $1.50 / 1,000 weibo posts
Weibo Scraper
[from $3/1K posts] Scrape Weibo posts from accounts, keyword search and post links: full text, likes, comments, reposts, pictures, video, IP region, author. Add comments, profiles and the Weibo hot search list. No login, no cookies, no run fee.
Pricing
from $1.50 / 1,000 weibo posts
Rating
0.0
(0)
Developer

Matvey
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
9 hours ago
Last modified
Categories
Share
Weibo Scraper is an all-in-one Weibo API for posts, comments, profiles and the Weibo hot search list (微博热搜). Give it Weibo accounts (profile link, uid or screen name), search keywords or post links, and it returns one clean row per Weibo post with the full text, publish time, likes, comments, reposts, pictures, video, #topics#, @mentions, IP region and author — plus, if you want them, top-level comments, account profiles and the 50 trending topics of the moment.
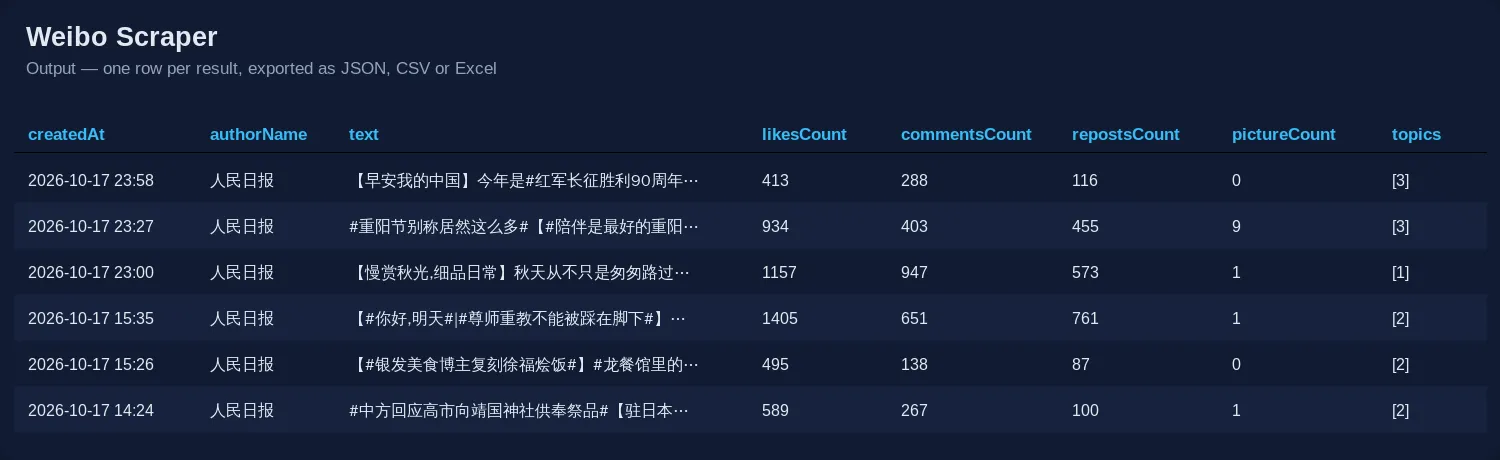
It works without a Weibo account, without login and without cookies. Chinese counters such as 1.58亿 or 100万+ arrive as plain numbers, long posts arrive as full text instead of the cut-off …全文 preview, and failed inputs are returned as free error rows. From $0.003 per post on paid plans ($0.012 on the Apify Free plan), no start fee.
What is Weibo Scraper?
Weibo (新浪微博, Sina Weibo) is China's largest public social network — the place where Chinese media, brands, celebrities, government bodies and hundreds of millions of users publish short posts, videos and comments, and where the national hot search list decides what China is talking about today. Weibo has no open public API for this data, and most of the site asks visitors to log in.
Weibo Scraper reads the public pages that Weibo shows to logged-out visitors on m.weibo.cn and weibo.com and turns them into structured rows you can download as JSON, CSV or Excel, or pull from the Apify API. It is built for:
- brand and competitor monitoring in China — what is said about a brand, a product or a person, every day;
- media and trend research — the Weibo hot search list, the newest posts of official accounts, reactions in the comments;
- influencer (KOL) discovery — who writes about your category, with follower counts and verification;
- AI and RAG pipelines — Chinese-language social media data as clean text, through the API or the Apify MCP server.
One Actor covers five jobs that usually need several tools: account posts, keyword search, post by link, comments and hot search.
What data can Weibo Scraper extract?
Every row has a type column first, so posts, comments, profiles and hot topics never get mixed up — even in one run.
📝 Weibo posts (type: post)
| Field | Example | Meaning |
|---|---|---|
id, bid, url | 5348998178410235, RkyFjzhSX, https://weibo.com/2803301701/RkyFjzhSX | Post id, short code and link |
createdAt | 2026-09-30T16:00:08.000Z | Publish time, ISO 8601 (UTC) |
text, textLength, isFullText | 【#家门口的海洋经济#】家门口的海鲜市场…, 145, true | Full post text; emoji kept as [name] |
topics, mentions | ["家门口的海洋经济"], [] | #Topics# and @accounts in the text |
likesCount, commentsCount, repostsCount | 14, 8, 4 | Engagement as numbers (万/亿 converted) |
engagementCount | 26 | Likes + comments + reposts, computed for you |
pictures, pictureCount | full-size image URLs, 3 | All pictures of the post |
videoUrl, videoTitle, videoPlayCount | MP4 link, title, 6825 | For video posts |
isRepost, repostOfUrl, repostOfAuthor, repostOfAuthorId, repostOfText, repostOfCreatedAt | true, link, name, uid, text, time | The original of a repost |
repostOfLikesCount, repostOfCommentsCount, repostOfRepostsCount | 51234, 812, 3020 | Engagement of the reposted original |
isPinned | false | Pinned to the top of the profile |
ipLocation | 四川 | IP region Weibo shows under the post (发布于…) |
client | iPhone客户端 | App or label the post was sent from |
authorId, authorName, authorUrl, authorVerified, authorVerifiedReason, authorFollowers, authorAvatar | 2803301701, 人民日报, …, true, 《人民日报》法人微博, 158000000 | Who posted it |
account / keyword / requestedUrl | the input this row came from | Lets you group rows by input |
💬 Weibo comments (type: comment)
id, postId, postUrl, createdAt, text, likesCount, replyCount, ipLocation (the commenter's IP region, 来自…), and the commenter: authorId, authorName, authorUrl, authorVerified, authorVerifiedReason, authorFollowers, authorAvatar. Top-level comments come hottest first, the way Weibo orders them.
👤 Weibo profiles (type: profile)
id, screenName, url, customDomain, description (bio), contactEmail (an e-mail written in the bio, if there is one), location, gender, followers, following, postsCount, verified, verifiedType, verifiedReason, company, accountCreatedAt, avatar, coverImage, memberRank.
🔥 Weibo hot search (type: hot-topic)
rank, topic, heat (numeric heat score), label (新 new, 热 hot, 沸 boiling, 爆 exploding), category, topicUrl. Advertising slots are removed, so ranks are the real trending topics.
💰 How much does it cost to scrape Weibo?
Weibo Scraper uses pay-per-event pricing: you pay for the rows you get, nothing else. There is no start fee, no fee per page and no proxy surcharge.
| Event | Free plan | Starter (Bronze) | Scale (Silver) | Business (Gold) |
|---|---|---|---|---|
| 📝 Post (from an account, a search or a link) | $0.012 ($12 / 1K) | $0.003 ($3 / 1K) | $0.00225 ($2.25 / 1K) | $0.0015 ($1.50 / 1K) |
| 💬 Comment | $0.0015 ($1.50 / 1K) | $0.00135 ($1.35 / 1K) | $0.0012 ($1.20 / 1K) | $0.00105 ($1.05 / 1K) |
| 👤 Profile | $0.075 ($75 / 1K) | $0.01875 ($18.75 / 1K) | $0.01641 ($16.41 / 1K) | $0.0140625 ($14.06 / 1K) |
| 🔥 Hot search topic | $0.0015 ($1.50 / 1K) | $0.00135 ($1.35 / 1K) | $0.0012 ($1.20 / 1K) | $0.00105 ($1.05 / 1K) |
Platinum and Diamond plans pay the Business price. A full 50-topic hot search snapshot costs about $0.075 on the Free plan and $0.0675 on Starter.
What is free: error rows (unknown account, deleted post, bad link), posts skipped by your date filter, duplicate posts, and anything above your maxItems cap.
What the demo run costs: the prefilled input returns 20 posts of 人民日报 (People's Daily) for $0.06 on the Starter plan ($0.24 on the Free plan). Apify's free plan includes $5 of monthly credit — roughly 400 Weibo posts or 3,300 comments a month at no cost to you.
Weibo Scraper vs. other Weibo actors
| Job | Weibo Scraper, Free plan | Weibo Scraper, Starter | Most-used Weibo actor, Free / Starter | Flat-rate alternative |
|---|---|---|---|---|
| 1,000 posts from keyword search | $12 | $3 | $12 / $4 + start fee | $35 |
| 1,000 posts by link | $12 | $3 | $75 / $25 | $35 |
| 1,000 account profiles | $75 | $18.75 | $75 / $25 | $35 |
| 1,000 comments | $1.50 | $1.35 | — | $35 |
Free plan: same as the leader; paid plans ~25% cheaper. Leader prices checked on the Apify Store on 15 October 2026: the actor with the most monthly users in this category charges $0.012 per search post on the Free plan and $0.004 on Starter, $0.075 / $0.025 per post detail and per profile, and a run start fee of $0.14 / $0.014. The flat-rate alternative charged $0.035 per row on 15 October 2026.
How to scrape Weibo with Weibo Scraper
- Open Weibo Scraper and press Try for free (an Apify account is free).
- Choose what to scrape — you can combine all of these in one run:
- 👤 Weibo accounts: profile links, uids or exact screen names, one per line;
- 🔍 Search keywords: words or #topics#, in Chinese for the best results;
- 🔗 Post links: links to individual posts;
- 🔥 Weibo hot search list: one switch.
- Optionally set 💬 Comments per post, 👤 Add the account profile and 📅 Only posts from the last N days.
- Press Start. The prefilled run finishes in about 10 seconds.
- Download the results as JSON, CSV, Excel or HTML, open them in Google Sheets, or fetch them through the Apify API.
⬇️ Input
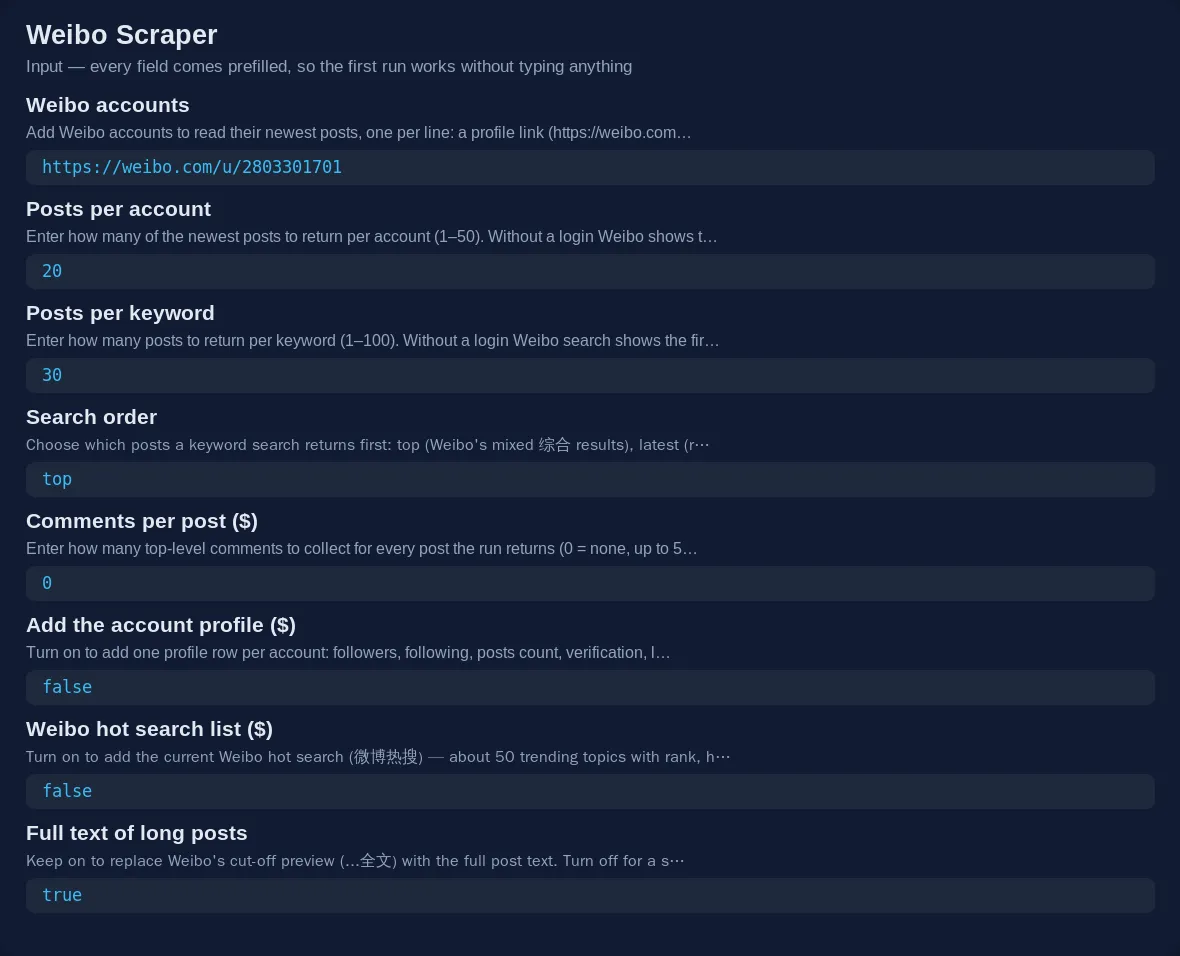
The prefilled input is the fastest working example — the newest 20 posts of 人民日报:
👤 Weibo account posts
Accounts accept a profile link (https://weibo.com/u/2803301701, https://weibo.com/rmrb, https://m.weibo.cn/u/2803301701), a numeric uid (2803301701) or the exact screen name (人民日报). The same account given twice is scraped once.
How many posts per account? Weibo shows logged-out visitors only the first screen of each profile tab. The Actor reads the All, Original, Video, Photo and Article tabs in turn and merges them, newest first — usually 20–35 recent posts per account (31 for 人民日报 in our tests). Older posts need a login and are not available.
🔍 Weibo keyword search
searchSort is top (Weibo's mixed 综合 results), latest (real-time 实时 posts, newest first) or hot (popular 热门 posts). Without a login Weibo search shows the first screen of each search tab; merged, that is typically 50–90 unique posts per keyword (89 for 比亚迪 in our tests).
🔗 Weibo posts by link, with comments
commentsPerPost works for every post the run returns — from accounts, searches or links. Comments are paged 20 at a time, hottest first. Posts with zero comments cost nothing extra.
🔥 Weibo hot search
Returns the current Weibo hot search list — about 50 trending topics. When you turn on hot topics, add keywords or post links, the prefilled demo account is skipped automatically, so you only get what you asked for.
All input fields
| Field | Default | What it does |
|---|---|---|
accounts | ["https://weibo.com/u/2803301701"] | Accounts to read |
postsPerAccount | 20 | Newest posts per account (1–50) |
keywords | — | Search keywords |
postsPerKeyword | 30 | Posts per keyword (1–100) |
searchSort | top | top, latest or hot |
postUrls | — | Post links or ids |
commentsPerPost | 0 | Top-level comments per post (0–500) |
includeProfile | false | Add a profile row per account |
hotTopics | false | Add the hot search list |
maxAgeDays | — | Skip posts older than N days |
expandLongText | true | Full text of long posts |
maxItems | — | Cap on billable rows per run |
proxyConfiguration | off | Direct connection; switches to Apify proxy by itself if Weibo throttles |
⬆️ Output
A post row:
A comment row:
A hot search row:
The dataset has five views: Posts, Comments, Profiles, Hot topics and Errors.
Error rows
If an account does not exist, a post was deleted or a link is not a Weibo link, you get a free row like this instead of a failed run:
An empty result is never silent: the run always says why.
Use cases for Weibo data
Brand and competitor monitoring in China
Search your brand, products and competitors every day with searchSort: latest and maxAgeDays: 1; every new post comes with likes, comments, reposts and the poster's IP region.
Weibo hot search tracking
Schedule the hot search list every hour and build a history of what trends in China, how hot it got and which category it belongs to. Feed a topic back into 🔍 Search keywords to read the posts behind it.
Media and official account monitoring
Follow the newest posts of media outlets, ministries, companies and celebrities in one run, with full text of long posts and video links.
Comment and sentiment analysis
Collect hundreds of top comments per post with likes, reply counts and IP regions — a ready dataset for sentiment analysis or regional breakdowns.
Influencer (KOL) research and lead generation
Profiles carry followers, verification, company, sign-up date and any contact e-mail written in the bio.
AI agents and RAG
Clean Chinese-language text with stable field names — easy to embed, summarise or translate.
Integrations
Weibo Scraper works with everything on the Apify platform: schedules, webhooks, Google Sheets, n8n, Make, Zapier, LangChain, Airbyte and the Apify MCP server.
Use the Weibo Scraper API from Python
Use the Weibo Scraper API from JavaScript
Run it with one HTTP request
🤖 For AI agents and LLM apps
Compact reference for agents calling lergassy/weibo-scraper through the Apify MCP server or the Apify API.
Purpose: Weibo (China) posts, comments, profiles and the hot search list, without login. One row = one post, comment, profile or trending topic; type tells which.
Minimal input: {"keywords": ["比亚迪"]} or {"accounts": ["人民日报"]} or {"hotTopics": true}.
Output fields (posts): type, id, bid, url, createdAt, text, textLength, isFullText, topics, mentions, repostsCount, commentsCount, likesCount, engagementCount, pictures, pictureCount, videoUrl, videoTitle, videoPlayCount, isRepost, repostOfUrl, repostOfAuthor, repostOfAuthorId, repostOfText, repostOfCreatedAt, repostOfLikesCount, repostOfCommentsCount, repostOfRepostsCount, isPinned, ipLocation, client, authorId, authorName, authorUrl, authorVerified, authorVerifiedReason, authorFollowers, authorAvatar, account / keyword / requestedUrl, scrapedAt. Comments add postId, postUrl, replyCount. Hot topics: rank, topic, heat, label, category, topicUrl.
Behaviours an agent should know:
- The default account (人民日报) is skipped when keywords, post links or hot topics are given.
- Without login Weibo shows only recent content: ~20–35 newest posts per account, ~50–90 posts per keyword. It is not a full archive.
- Use
maxAgeDaysandsearchSort: latestinstead of filtering afterwards; skipped posts are free. - Counts are numbers, dates are ISO 8601 UTC, text is plain (no HTML).
- Billed per post, comment, profile and hot topic; error rows are free.
❓ FAQ
Is it legal to scrape Weibo?
Weibo Scraper reads only public pages that Weibo shows to anyone without logging in, and does not access private messages, private accounts or anything behind a login. Scraping public data is generally lawful, but personal data (names, comments) is protected by laws such as GDPR and China's PIPL. Use the data for legitimate purposes, respect copyright when republishing text, and consult a lawyer if you are unsure.
Do I need a Weibo account, cookies or a Chinese phone number?
No. Nothing is logged in. The Actor uses the same anonymous visitor session a browser gets on its first visit.
Is there an official Weibo API?
Weibo's open platform (open.weibo.com) requires a registered developer app, a review and user authorisation before you get any data. Weibo Scraper is a ready Weibo API alternative: send JSON, get rows, no app review.
Can I use Weibo Scraper with the Apify API?
Yes. Every run can be started and read through the Apify API — see the Python, JavaScript and curl examples above. The run-sync-get-dataset-items endpoint returns the rows in the same HTTP response.
Can I use it through an MCP server?
Yes. Weibo Scraper is available to Claude, ChatGPT, Cursor and other AI agents through the Apify MCP server (https://mcp.apify.com). Ask your agent for "Weibo posts about 比亚迪" or "today's Weibo hot search" and it can call the Actor directly.
Can I integrate it with other apps?
Yes — Google Sheets, n8n, Make, Zapier, Slack, Airbyte, webhooks and schedules all work out of the box on Apify.
How much does it cost to scrape 1,000 Weibo posts?
$3 on the Starter plan, $2.25 on Scale and $1.50 on Business and above; $12 on the Free plan. On Starter, comments are $1.35 per 1,000, profiles $18.75 per 1,000 and hot topics $1.35 per 1,000 (on the Free plan $1.50, $75 and $1.50). No start fee.
Why do I get only 20–35 posts from an account?
Weibo shows deeper pages of a profile only to logged-in users. Weibo Scraper merges the first screen of five profile tabs to give you as many recent posts as a visitor can see. For longer histories, run it on a schedule — each run adds the newest posts.
Does it return one row per post?
Yes. A post found twice in one run (for example by two keywords) is returned and billed once.
Are the numbers exact?
Weibo itself rounds big counters for display (1.58亿 followers, 100万+ reposts). Where Weibo gives the exact number, you get it; where it shows a rounded one, you get the rounded value as a number.
How long do video and picture links work?
Picture and video files are hosted on Weibo's own servers. Video links carry an expiry time in the link itself (Expires=…), so download a video soon after the run if you need it.
Can I get followers lists, reposts lists or replies to comments?
Not in this version. Each comment row carries replyCount, so you can see which comments started a discussion.
Your feedback
Found a bug, need a field or a new mode? Open an issue on the Issues tab — we answer quickly and ship fixes fast. If Weibo Scraper saves you time, a short review on the Store helps other people find it.
You might also like
| Actor | What it does |
|---|---|
| WeChat Articles Scraper | WeChat Official Account articles by keyword — the other half of Chinese social media |
| Threads Scraper | Threads posts, profiles and search, no login |
| YouTube Comments Scraper | Comments and replies from any YouTube video |
| TikTok Comments Scraper | Comments from TikTok videos |
| Telegram Channel Analytics | Subscribers, reach and stats of Telegram channels |


